Initial project import
This commit is contained in:
 XM
@@ -0,0 +1,27 @@
|
||||
---
|
||||
name: chatgpt2api-search
|
||||
description: Use when current web search is needed through this chatgpt2api server. Call the configured HTTP search endpoint with a prompt and return the answer with source URLs.
|
||||
---
|
||||
|
||||
# ChatGPT2API Search
|
||||
|
||||
Use this skill when the user asks for current web search, online lookup, recent information, or source-backed answers.
|
||||
|
||||
## Endpoint
|
||||
|
||||
POST http://127.0.0.1:8000/v1/search
|
||||
|
||||
Headers:
|
||||
|
||||
Authorization: Bearer chatgpt2api
|
||||
Content-Type: application/json
|
||||
|
||||
Body:
|
||||
|
||||
{
|
||||
"prompt": "<search question>"
|
||||
}
|
||||
|
||||
## Response
|
||||
|
||||
Use `answer` as the main response. Include URLs from `sources` when available.
|
||||
@@ -0,0 +1,14 @@
|
||||
.git
|
||||
.gitignore
|
||||
.idea
|
||||
.venv
|
||||
__pycache__
|
||||
*.pyc
|
||||
*.pyo
|
||||
*.pyd
|
||||
|
||||
web/.next
|
||||
web/node_modules
|
||||
|
||||
assets
|
||||
README.md
|
||||
@@ -0,0 +1,82 @@
|
||||
# ============================================
|
||||
# ChatGPT2API 环境变量配置示例
|
||||
# ============================================
|
||||
|
||||
# 认证密钥(必填)
|
||||
CHATGPT2API_AUTH_KEY=your_secret_key_here
|
||||
|
||||
# 基础 URL(可选,用于生成图片 URL)
|
||||
# CHATGPT2API_BASE_URL=https://your-domain.com
|
||||
|
||||
# ============================================
|
||||
# 存储后端配置
|
||||
# ============================================
|
||||
|
||||
# 存储后端类型(可选值: json, sqlite, postgres, git)
|
||||
# 默认: json
|
||||
STORAGE_BACKEND=json
|
||||
|
||||
# ============================================
|
||||
# 数据库配置(当 STORAGE_BACKEND=sqlite/postgres 时使用)
|
||||
# ============================================
|
||||
|
||||
# PostgreSQL 示例
|
||||
# DATABASE_URL=postgresql://user:password@localhost:5432/chatgpt2api
|
||||
|
||||
# Supabase 示例
|
||||
# DATABASE_URL=postgresql://postgres.xxx:password@aws-1-us-west-1.pooler.supabase.com:5432/postgres
|
||||
|
||||
# SQLite 示例(不指定时自动使用 data/accounts.db)
|
||||
# DATABASE_URL=sqlite:///app/data/accounts.db
|
||||
|
||||
# ============================================
|
||||
# Git 仓库配置(当 STORAGE_BACKEND=git 时使用)
|
||||
# ============================================
|
||||
|
||||
# Git 仓库地址(必填)
|
||||
# GIT_REPO_URL=https://github.com/your-username/your-private-repo.git
|
||||
|
||||
# Git 访问令牌(必填)
|
||||
# GitHub: ghp_xxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxx
|
||||
# GitLab: glpat-xxxxxxxxxxxxxxxxxxxx
|
||||
# GIT_TOKEN=your_git_token_here
|
||||
|
||||
# Git 分支(可选,默认: main)
|
||||
# GIT_BRANCH=main
|
||||
|
||||
# Git 仓库中的文件路径(可选,默认: accounts.json)
|
||||
# GIT_FILE_PATH=accounts.json
|
||||
|
||||
# ============================================
|
||||
# WARP / FlareSolverr 稳定代理配置(可选)
|
||||
# ============================================
|
||||
|
||||
# docker-compose.warp.yml 暴露到宿主机的端口
|
||||
# WARP_SOCKS_PORT=40000
|
||||
# PRIVOXY_PORT=40080
|
||||
# FLARESOLVERR_PORT=8191
|
||||
|
||||
# FlareSolverr 日志与时区
|
||||
# FLARESOLVERR_LOG_LEVEL=info
|
||||
# TZ=Asia/Shanghai
|
||||
|
||||
# Cloudflare WARP+ License Key(可选)
|
||||
# WARP_LICENSE_KEY=
|
||||
|
||||
# 初始化 proxy_runtime 默认值
|
||||
# CHATGPT2API_PROXY_RUNTIME_ENABLED=true
|
||||
# CHATGPT2API_PROXY_RUNTIME_EGRESS_MODE=single_proxy
|
||||
# CHATGPT2API_PROXY_RUNTIME_PROXY_URL=http://privoxy:8118
|
||||
# CHATGPT2API_PROXY_RUNTIME_RESOURCE_PROXY_URL=
|
||||
# CHATGPT2API_PROXY_RUNTIME_SKIP_SSL_VERIFY=false
|
||||
# CHATGPT2API_PROXY_RUNTIME_RESET_STATUS_CODES=403
|
||||
|
||||
# Cloudflare clearance 刷新配置
|
||||
# CHATGPT2API_PROXY_RUNTIME_CLEARANCE_ENABLED=true
|
||||
# CHATGPT2API_PROXY_RUNTIME_CLEARANCE_MODE=flaresolverr
|
||||
# CHATGPT2API_FLARESOLVERR_URL=http://flaresolverr:8191
|
||||
# CHATGPT2API_PROXY_RUNTIME_CLEARANCE_TIMEOUT_SEC=60
|
||||
# CHATGPT2API_PROXY_RUNTIME_CLEARANCE_REFRESH_INTERVAL=3600
|
||||
# CHATGPT2API_PROXY_RUNTIME_WARM_UP_ON_START=false
|
||||
# CHATGPT2API_PROXY_RUNTIME_BROWSER=chrome
|
||||
# CHATGPT2API_PROXY_RUNTIME_USER_AGENT=
|
||||
@@ -0,0 +1,61 @@
|
||||
name: Publish Docker Image
|
||||
|
||||
on:
|
||||
push:
|
||||
tags:
|
||||
- "v*"
|
||||
workflow_dispatch:
|
||||
|
||||
env:
|
||||
IMAGE_NAME: chatgpt2api
|
||||
|
||||
jobs:
|
||||
docker:
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
contents: read
|
||||
packages: write
|
||||
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: Set up QEMU
|
||||
uses: docker/setup-qemu-action@v3
|
||||
with:
|
||||
platforms: arm64
|
||||
|
||||
- name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v3
|
||||
|
||||
- name: Log in to GHCR
|
||||
uses: docker/login-action@v3
|
||||
with:
|
||||
registry: ghcr.io
|
||||
username: ${{ github.actor }}
|
||||
password: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
||||
- name: Extract Docker metadata
|
||||
id: meta
|
||||
uses: docker/metadata-action@v5
|
||||
with:
|
||||
images: ghcr.io/${{ github.repository_owner }}/${{ env.IMAGE_NAME }}
|
||||
tags: |
|
||||
type=raw,value=latest,enable=${{ startsWith(github.ref, 'refs/tags/v') }}
|
||||
type=ref,event=tag
|
||||
type=sha
|
||||
type=semver,pattern={{version}}
|
||||
type=semver,pattern={{major}}.{{minor}}
|
||||
|
||||
- name: Build and push image
|
||||
uses: docker/build-push-action@v6
|
||||
with:
|
||||
context: .
|
||||
file: ./Dockerfile
|
||||
target: app
|
||||
platforms: linux/amd64,linux/arm64
|
||||
push: true
|
||||
tags: ${{ steps.meta.outputs.tags }}
|
||||
labels: ${{ steps.meta.outputs.labels }}
|
||||
cache-from: type=gha
|
||||
cache-to: type=gha,mode=max
|
||||
+41
@@ -0,0 +1,41 @@
|
||||
# Python-generated files
|
||||
__pycache__/
|
||||
*.py[oc]
|
||||
build/
|
||||
dist/
|
||||
wheels/
|
||||
*.egg-info
|
||||
web_dist
|
||||
# Virtual environments
|
||||
.venv
|
||||
.idea
|
||||
data
|
||||
config.json
|
||||
edit
|
||||
|
||||
docker-compose-local.yml
|
||||
|
||||
.claude/settings.local.json
|
||||
.codex/run/
|
||||
|
||||
# Environment variables
|
||||
.env
|
||||
.env.local
|
||||
|
||||
# Database files
|
||||
*.db
|
||||
*.sqlite
|
||||
*.sqlite3
|
||||
|
||||
# Git cache
|
||||
git_cache/
|
||||
|
||||
# Build and test output
|
||||
web/.next/
|
||||
web/out/
|
||||
.pytest_cache/
|
||||
|
||||
# 调试/测试输出目录
|
||||
loginwithpassword_*/
|
||||
logwithemailverifycode_*/
|
||||
test_batch_output/
|
||||
@@ -0,0 +1 @@
|
||||
3.13
|
||||
@@ -0,0 +1,80 @@
|
||||
# Changelog
|
||||
|
||||
## Unreleased
|
||||
|
||||
## 1.8.0 - 2026-07-28
|
||||
|
||||
+ [新增] 新增默认请求上游模型名称和默认思考强度配置,支持在设置页面修改,并可通过模型名的 `-standard`、`-extended`、`-max` 后缀覆盖思考强度。
|
||||
+ [修复] 新增没出图也移除本地对话的配置,支持在图片生成失败、超时或仅返回文本时异步隐藏对应对话记录。
|
||||
+ [修复] `/v1/models` 汇总各账号类型的官方模型列表,文本请求按模型权限选择账号。
|
||||
+ [修复] 过滤隐藏、非最终频道及发往内部工具的助手消息,避免搜索指令和推理内容泄漏到 API 输出。
|
||||
+ [修复] 修复输出清洗误删代码和命令中标点前空格的问题。
|
||||
+ [修复] 为图片生成 SSE 流增加可配置的硬超时上限,避免上游长连接长时间挂起。
|
||||
+ [优化] 数据库存储改为增量同步,仅新增、更新或删除发生变化的记录,保留未变记录的 ID。
|
||||
|
||||
## 1.7.0 - 2026-07-05
|
||||
|
||||
+ [移除] 移除注册功能、防滥用机制导致封禁GitHub账号。
|
||||
|
||||
## 1.6.0 - 2026-07-04
|
||||
|
||||
+ [修复] 修复sub2api导入问题。
|
||||
+ [修复] 修复前端404、405问题。
|
||||
+ [新增] 新增出图后删除对话记录功能。
|
||||
+ [调整] Pro号不再按无限额度处理、约每天1000张。
|
||||
|
||||
## 1.5.0 - 2026-06-13
|
||||
|
||||
+ [新增] 新增 WARP / Privoxy / FlareSolverr 清障方案,注册遇到 Cloudflare 拦截后可刷新 clearance 并重试。
|
||||
+ [新增] 新增 `outlook_token` 邮箱池,支持 Outlook/Hotmail 注册验证码读取。
|
||||
+ [新增] 新增网页搜索兼容接口、图片编辑 mask 和图片任务相关能力。
|
||||
+ [优化] 更新 sentinel/PoW 获取方式,提高上游请求兼容性。
|
||||
+ [优化] 调整代理优先级和注册请求重试逻辑。
|
||||
|
||||
## 1.4.1 - 2026-06-03
|
||||
|
||||
+ [新增] 账号刷新改为异步模式,支持前端轮询刷新/重新登录进度。
|
||||
+ [新增] 号池管理页面新增重新登录功能,支持密码登录恢复异常账号。
|
||||
+ [新增] 刷新后自动重新登录异常账号(可在设置页开启)。
|
||||
+ [新增] 图片生成支持并行模式,多张图片使用独立线程和账号同时生成。
|
||||
+ [新增] 图片轮询超时自动换账号重试(最多4次),连接超时同账号递增等待重试。
|
||||
+ [新增] 图片二次确认机制与先check再hit可配置化,关闭后可跳过等待直接返回结果。
|
||||
+ [新增] 图片任务进度追踪,显示当前生成步骤(上传/预热/获取token/生成中等)。
|
||||
+ [新增] 图片超时后续轮询功能,前端显示"继续等待"按钮。
|
||||
+ [新增] 设置页新增图片二次确认、超时等待时间、自动重新登录等配置项。
|
||||
+ [优化] 优化生图页面滚动加载性能,图片懒加载、会话切换滚动位置保存与恢复。
|
||||
|
||||
## 1.4.0 - 2026-05-31
|
||||
|
||||
+ [新增] 新增AI生成可编辑PSD文件逆向。
|
||||
+ [新增] 新增AI生成可编辑PPT文件逆向。
|
||||
|
||||
## 1.3.1 - 2026-05-30
|
||||
|
||||
+ [新增] 新增ChatGPT搜索调试、Skills。
|
||||
|
||||
## 1.3.0 - 2026-05-30
|
||||
|
||||
+ [新增] 新增ChatGPT搜索接口逆向。
|
||||
|
||||
## 1.2.4 - 2026-05-30
|
||||
|
||||
+ [新增] 添加聊天补全缓存与重复请求合并。
|
||||
+ [新增] 新增无限画布一键跳转功能
|
||||
|
||||
## 1.2.3 - 2026-05-29
|
||||
|
||||
+ [新增] 新增账号级代理。
|
||||
+ [修复] 修复503异常信息、前端邮箱换行问题。
|
||||
|
||||
## 1.2.2 - 2026-05-29
|
||||
|
||||
+ [新增] 新增Codex链路生图、支持2k,4k。
|
||||
+ [新增] 支持RT刷新账号信息。
|
||||
|
||||
## 1.2.0 - 2026-05-28
|
||||
|
||||
+ [新增] 当前版本基线,包含 Web 面板、画图、号池管理、注册机、图片管理、日志管理和设置能力。
|
||||
+ [新增] 前端版本号支持点击查看版本更新弹窗,展示当前版本、最新版本和更新日志。
|
||||
+ [优化] 优化注册机效率,成功率大幅提高。
|
||||
+ [优化] 优化生图页面配置选项。
|
||||
+56
@@ -0,0 +1,56 @@
|
||||
ARG BUILDPLATFORM
|
||||
ARG TARGETPLATFORM
|
||||
ARG TARGETARCH
|
||||
|
||||
FROM --platform=$BUILDPLATFORM node:22-alpine AS web-build
|
||||
|
||||
WORKDIR /app/web
|
||||
|
||||
COPY web/package.json web/bun.lock ./
|
||||
RUN npm install
|
||||
|
||||
COPY VERSION /app/VERSION
|
||||
COPY CHANGELOG.md /app/CHANGELOG.md
|
||||
COPY web ./
|
||||
RUN NEXT_PUBLIC_APP_VERSION="$(cat /app/VERSION)" npm run build
|
||||
|
||||
|
||||
FROM --platform=$TARGETPLATFORM python:3.13-slim AS app
|
||||
|
||||
ARG TARGETPLATFORM
|
||||
ARG TARGETARCH
|
||||
|
||||
ENV PYTHONDONTWRITEBYTECODE=1 \
|
||||
PYTHONUNBUFFERED=1 \
|
||||
UV_LINK_MODE=copy
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
# 安装系统依赖
|
||||
# - git: Git 存储后端需要
|
||||
# - libpq-dev: PostgreSQL 客户端库
|
||||
# - gcc: 编译 psycopg2-binary 需要
|
||||
RUN apt-get update && apt-get install -y --no-install-recommends \
|
||||
git \
|
||||
libpq-dev \
|
||||
gcc \
|
||||
openssl \
|
||||
&& rm -rf /var/lib/apt/lists/*
|
||||
|
||||
RUN pip install --no-cache-dir uv
|
||||
|
||||
COPY pyproject.toml uv.lock ./
|
||||
RUN uv sync --frozen --no-dev --no-install-project
|
||||
|
||||
COPY main.py ./
|
||||
COPY config.json ./
|
||||
COPY VERSION ./
|
||||
COPY api ./api
|
||||
COPY services ./services
|
||||
COPY utils ./utils
|
||||
COPY scripts ./scripts
|
||||
COPY --from=web-build /app/web/out ./web_dist
|
||||
|
||||
EXPOSE 80
|
||||
|
||||
CMD ["uv", "run", "uvicorn", "main:app", "--host", "0.0.0.0", "--port", "80", "--access-log"]
|
||||
@@ -0,0 +1,21 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2026 kunkun
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
@@ -0,0 +1,375 @@
|
||||
<h1 align="center">ChatGPT2API</h1>
|
||||
|
||||
|
||||
<p align="center">ChatGPT2API 主要是对 ChatGPT 官网相关能力进行逆向整理与封装,提供面向 ChatGPT 图片生成、图片编辑、多图组图编辑场景的 OpenAI 兼容图片 API / 代理,并集成在线画图、号池管理、多种账号导入方式与 Docker 自托管部署能力。</p>
|
||||
|
||||
> [!WARNING]
|
||||
> 免责声明:
|
||||
>
|
||||
> 本项目涉及对 ChatGPT 官网文本生成、图片生成与图片编辑等相关接口的逆向研究,仅供个人学习、技术研究与非商业性技术交流使用。
|
||||
>
|
||||
> - 严禁将本项目用于任何商业用途、盈利性使用、批量操作、自动化滥用或规模化调用。
|
||||
> - 严禁将本项目用于破坏市场秩序、恶意竞争、套利倒卖、二次售卖相关服务,以及任何违反 OpenAI 服务条款或当地法律法规的行为。
|
||||
> - 严禁将本项目用于生成、传播或协助生成违法、暴力、色情、未成年人相关内容,或用于诈骗、欺诈、骚扰等非法或不当用途。
|
||||
> - 使用者应自行承担全部风险,包括但不限于账号被限制、临时封禁或永久封禁以及因违规使用等所导致的法律责任。
|
||||
> - 使用本项目即视为你已充分理解并同意本免责声明全部内容;如因滥用、违规或违法使用造成任何后果,均由使用者自行承担。
|
||||
> - 本项目基于对 ChatGPT 官网相关能力的逆向研究实现,存在账号受限、临时封禁或永久封禁的风险。请勿使用你自己的重要账号、常用账号或高价值账号进行测试。
|
||||
|
||||
|
||||
## 赞助商
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td width="190" align="center">
|
||||
<a href="https://www.atlascloud.ai/zh?utm_source=github&utm_medium=link&utm_campaign=chatgpt2api"><img src="assets/atlascloud.svg" width="163" alt="Atlas Cloud"></a>
|
||||
</td>
|
||||
<td>
|
||||
<a href="https://www.atlascloud.ai/zh?utm_source=github&utm_medium=link&utm_campaign=chatgpt2api">Atlas Cloud</a> is a full-modal AI inference platform that gives developers a single AI API to access video generation, image generation, and LLM APIs. Instead of managing multiple vendor integrations, you connect once and get unified access to 300+ curated models across all modalities. Check out <a href="https://www.atlascloud.ai/console/coding-plan">Atlas Cloud's new coding plan promotion</a> for more budget-friendly API access.
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## 快速开始
|
||||
|
||||
### Docker 运行
|
||||
|
||||
```bash
|
||||
git clone git@github.com:basketikun/chatgpt2api.git
|
||||
cd chatgpt2api
|
||||
docker compose up -d
|
||||
```
|
||||
|
||||
启动前请先在 `config.json` 中设置 `auth-key`,也可以在 `docker-compose.yml` 中通过 `CHATGPT2API_AUTH_KEY` 覆盖。
|
||||
|
||||
- Web 面板:`http://localhost:3000`
|
||||
- API 地址:`http://localhost:3000/v1`
|
||||
- 数据目录:`./data`
|
||||
|
||||
### WARP / FlareSolverr 稳定代理部署
|
||||
|
||||
如果图片链路经常遇到 Cloudflare 拦截,可以启用附带的 WARP + Privoxy + FlareSolverr 方案:
|
||||
|
||||
```bash
|
||||
cp .env.example .env
|
||||
docker compose -f docker-compose.warp.yml up -d --build
|
||||
```
|
||||
|
||||
该 compose 会启动:
|
||||
|
||||
- `warp-proxy`:提供 WARP SOCKS5 出口。
|
||||
- `privoxy`:把 WARP SOCKS5 转成 HTTP 代理。
|
||||
- `flaresolverr`:刷新 Cloudflare clearance。
|
||||
- `init-config`:幂等写入 `proxy_runtime` 默认配置。
|
||||
- `app`:启动 ChatGPT2API 主服务。
|
||||
|
||||
默认只让上游 OpenAI / ChatGPT 请求走稳定代理,账号邮箱、CPA 等辅助链路不会被强制接管。账号自身配置的代理优先级最高,其次是稳定代理运行时,再其次是显式代理和旧版全局代理。
|
||||
|
||||
可在 `.env` 中调整端口和代理运行时参数,也可在后台设置页的「稳定代理运行时」面板手动保存、测试代理和测试 clearance。
|
||||
|
||||
### 本地开发
|
||||
|
||||
启动后端:
|
||||
|
||||
```bash
|
||||
git clone git@github.com:basketikun/chatgpt2api.git
|
||||
cd chatgpt2api
|
||||
uv sync
|
||||
uv run main.py
|
||||
```
|
||||
|
||||
启动前端:
|
||||
|
||||
```bash
|
||||
cd chatgpt2api/web
|
||||
bun install
|
||||
bun run dev
|
||||
```
|
||||
|
||||
后续更新新版本:
|
||||
|
||||
```bash
|
||||
docker pull ghcr.io/basketikun/chatgpt2api:latest
|
||||
docker-compose down
|
||||
docker-compose up -d
|
||||
|
||||
```
|
||||
|
||||
### 存储后端配置
|
||||
|
||||
支持通过环境变量 `STORAGE_BACKEND` 切换存储方式:
|
||||
|
||||
- `json` - 本地 JSON 文件(默认)
|
||||
- `sqlite` - 本地 SQLite 数据库
|
||||
- `postgres` - 外部 PostgreSQL(需配置 `DATABASE_URL`)
|
||||
- `git` - Git 私有仓库(需配置 `GIT_REPO_URL` 和 `GIT_TOKEN`)
|
||||
|
||||
示例:使用 PostgreSQL
|
||||
|
||||
```yaml
|
||||
environment:
|
||||
- STORAGE_BACKEND=postgres
|
||||
- DATABASE_URL=postgresql://user:password@host:5432/dbname
|
||||
```
|
||||
|
||||
## 功能
|
||||
|
||||
### API 兼容能力
|
||||
|
||||
- 兼容 `POST /v1/images/generations` 图片生成接口
|
||||
- 兼容 `POST /v1/images/edits` 图片编辑接口
|
||||
- 兼容面向图片场景的 `POST /v1/chat/completions`
|
||||
- 兼容面向图片场景的 `POST /v1/responses`
|
||||
- `GET /v1/models` 返回 `gpt-image-2`、`codex-gpt-image-2`、`auto`、`gpt-5`、`gpt-5-1`、`gpt-5-2`、`gpt-5-3`、`gpt-5-3-mini`、
|
||||
`gpt-5-mini`
|
||||
- 支持通过 `n` 返回多张生成结果
|
||||
- 支持生成可编辑 PPT 文件
|
||||
- 支持生成可编辑 PSD 文件
|
||||
- 支持 Codex 中的画图接口逆向,仅 `Plus` / `Team` / `Pro` 订阅可用,模型别名为 `codex-gpt-image-2`,如有需要可自行在其他场景映射回
|
||||
`gpt-image-2`,用于和官网画图区分;也就意味着同一账号会同时有官网和 Codex 两份生图额度
|
||||
|
||||
### 在线画图功能
|
||||
|
||||
- 内置在线画图工作台,支持生成、图片编辑与多图组图编辑
|
||||
- 支持 `gpt-image-2`、`codex-gpt-image-2`、`auto`、`gpt-5`、`gpt-5-1`、`gpt-5-2`、`gpt-5-3`、`gpt-5-3-mini`、`gpt-5-mini` 模型选择
|
||||
- 编辑模式支持参考图上传
|
||||
- 前端支持多图生成交互
|
||||
- 本地保存图片会话历史,支持回看、删除和清空
|
||||
- 支持服务端缓存图片URL
|
||||
- 图片生成进度追踪,超时后可继续等待
|
||||
- 图片懒加载与滚动位置记忆,优化大量图片场景性能
|
||||
|
||||
### 号池管理功能
|
||||
|
||||
- 自动刷新账号邮箱、类型、额度和恢复时间(异步进度追踪)
|
||||
- 轮询可用账号执行图片生成与图片编辑
|
||||
- 遇到 Token 失效类错误时自动剔除无效 Token
|
||||
- 定时检查限流账号并自动刷新
|
||||
- 支持密码重新登录恢复异常账号,刷新后可自动重登
|
||||
- 支持网页端配置全局 HTTP / HTTPS / SOCKS5 / SOCKS5H 代理
|
||||
- 支持 WARP / FlareSolverr 稳定代理运行时
|
||||
- 支持搜索、筛选、批量刷新、导出、手动编辑和清理账号
|
||||
- 支持四种导入方式:本地 CPA JSON 文件导入、远程 CPA 服务器导入、`sub2api` 服务器导入、`access_token` 导入
|
||||
- 支持在设置页配置 `sub2api` 服务器,筛选并批量导入其中的 OpenAI OAuth 账号
|
||||
|
||||
### 实验性 / 规划中
|
||||
|
||||
- 详细状态说明见:[功能清单](./docs/feature-status.en.md)
|
||||
|
||||
## 效果展示
|
||||
|
||||
<table width="100%">
|
||||
<tr>
|
||||
<td width="50%"><img src="https://i.ibb.co/Jj8nfwwP/image.png" alt="image" border="0"></td>
|
||||
<td width="50%"><img src="https://i.ibb.co/pqf235v/image-edit.png" alt="image edit" border="0"></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td width="50%"><img src="https://i.ibb.co/tPcqtVfd/chery-studio.png" alt="chery studio" border="0"></td>
|
||||
<td width="50%"><img src="https://i.ibb.co/PsT9YHBV/account-pool.png" alt="account pool" border="0"></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td width="50%"><img src="https://i.ibb.co/rRWLG08q/new-api.png" alt="new api" border="0"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## API
|
||||
|
||||
所有 AI 接口都需要请求头:
|
||||
|
||||
```http
|
||||
Authorization: Bearer <auth-key>
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary><code>GET /v1/models</code></summary>
|
||||
<br>
|
||||
|
||||
返回当前暴露的图片模型列表。
|
||||
|
||||
```bash
|
||||
curl http://localhost:8000/v1/models \
|
||||
-H "Authorization: Bearer <auth-key>"
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>说明</summary>
|
||||
<br>
|
||||
|
||||
| 字段 | 说明 |
|
||||
|:-----|:-----------------------------------------------------------------------------------------------------------|
|
||||
| 返回模型 | `gpt-image-2`、`codex-gpt-image-2`、`auto`、`gpt-5`、`gpt-5-1`、`gpt-5-2`、`gpt-5-3`、`gpt-5-3-mini`、`gpt-5-mini` |
|
||||
| 接入场景 | 可接入 Cherry Studio、New API 等上游或客户端 |
|
||||
|
||||
<br>
|
||||
</details>
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><code>POST /v1/images/generations</code></summary>
|
||||
<br>
|
||||
|
||||
OpenAI 兼容图片生成接口,用于文生图。
|
||||
|
||||
```bash
|
||||
curl http://localhost:8000/v1/images/generations \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer <auth-key>" \
|
||||
-d '{
|
||||
"model": "gpt-image-2",
|
||||
"prompt": "一只漂浮在太空里的猫",
|
||||
"n": 1,
|
||||
"response_format": "b64_json"
|
||||
}'
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>字段说明</summary>
|
||||
<br>
|
||||
|
||||
| 字段 | 说明 |
|
||||
|:------------------|:---------------------------------------------------|
|
||||
| `model` | 图片模型,当前可用值以 `/v1/models` 返回结果为准,推荐使用 `gpt-image-2` |
|
||||
| `prompt` | 图片生成提示词 |
|
||||
| `n` | 生成数量,当前后端限制为 `1-4` |
|
||||
| `response_format` | 当前请求模型中包含该字段,默认值为 `b64_json` |
|
||||
|
||||
<br>
|
||||
</details>
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><code>POST /v1/images/edits</code></summary>
|
||||
<br>
|
||||
|
||||
OpenAI 兼容图片编辑接口,可上传图片文件,也可按官方 JSON 格式传入图片链接并生成编辑结果。
|
||||
|
||||
```bash
|
||||
curl http://localhost:8000/v1/images/edits \
|
||||
-H "Authorization: Bearer <auth-key>" \
|
||||
-F "model=gpt-image-2" \
|
||||
-F "prompt=把这张图改成赛博朋克夜景风格" \
|
||||
-F "n=1" \
|
||||
-F "image=@./input.png"
|
||||
```
|
||||
|
||||
也可以直接传图片 URL:
|
||||
|
||||
```bash
|
||||
curl http://localhost:8000/v1/images/edits \
|
||||
-H "Authorization: Bearer <auth-key>" \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"model": "gpt-image-2",
|
||||
"prompt": "把这张图改成赛博朋克夜景风格",
|
||||
"images": [
|
||||
{"image_url": "https://example.com/input.png"}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>字段说明</summary>
|
||||
<br>
|
||||
|
||||
| 字段 | 说明 |
|
||||
|:------------|:----------------------------------------------|
|
||||
| `model` | 图片模型, `gpt-image-2` |
|
||||
| `prompt` | 图片编辑提示词 |
|
||||
| `n` | 生成数量,当前后端限制为 `1-4` |
|
||||
| `image` | 需要编辑的图片文件,使用 multipart/form-data 上传 |
|
||||
| `images` | JSON 图片引用数组,支持 `{"image_url": "https://..."}` |
|
||||
| `image_url` | 表单模式下也可直接传图片链接,支持重复字段传多张图 |
|
||||
|
||||
<br>
|
||||
</details>
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><code>POST /v1/chat/completions</code></summary>
|
||||
<br>
|
||||
|
||||
面向文本、网页搜索与图片场景的 Chat Completions 兼容接口,不是完整通用聊天代理。
|
||||
|
||||
```bash
|
||||
curl http://localhost:8000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer <auth-key>" \
|
||||
-d '{
|
||||
"model": "gpt-image-2",
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": "生成一张雨夜东京街头的赛博朋克猫"
|
||||
}
|
||||
],
|
||||
"n": 1
|
||||
}'
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>字段说明</summary>
|
||||
<br>
|
||||
|
||||
| 字段 | 说明 |
|
||||
|:---------------------|:-----------------------------------------------------------------------------|
|
||||
| `model` | 文本、搜索或图片模型;搜索模型会触发网页搜索兼容逻辑 |
|
||||
| `messages` | 消息数组,支持文本、搜索和图片请求内容 |
|
||||
| `n` | 图片生成数量,按当前实现解析为图片数量 |
|
||||
| `stream` | 文本、搜索和图片场景均支持,仍在测试 |
|
||||
| `tools` | 文本场景支持 `web_search` / `web_search_preview` / `web_search_preview_2025_03_11` |
|
||||
| `web_search_options` | 传入时会触发网页搜索兼容逻辑 |
|
||||
|
||||
<br>
|
||||
</details>
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><code>POST /v1/responses</code></summary>
|
||||
<br>
|
||||
|
||||
面向文本、网页搜索和图片生成工具调用的 Responses API 兼容接口,不是完整通用 Responses API 代理。
|
||||
|
||||
```bash
|
||||
curl http://localhost:8000/v1/responses \
|
||||
-H "Content-Type: application/json" \
|
||||
-H "Authorization: Bearer <auth-key>" \
|
||||
-d '{
|
||||
"model": "gpt-5",
|
||||
"input": "生成一张未来感城市天际线图片",
|
||||
"tools": [
|
||||
{
|
||||
"type": "image_generation"
|
||||
}
|
||||
]
|
||||
}'
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>字段说明</summary>
|
||||
<br>
|
||||
|
||||
| 字段 | 说明 |
|
||||
|:---------|:----------------------------------------------------------------------------------------|
|
||||
| `model` | 响应中会回显该模型字段,搜索和图片生成会走对应兼容逻辑 |
|
||||
| `input` | 输入内容;搜索使用最后一条用户文本,图片生成需能解析出提示词 |
|
||||
| `tools` | 支持 `image_generation`、`web_search`、`web_search_preview`、`web_search_preview_2025_03_11` |
|
||||
| `stream` | 已实现,但仍在测试 |
|
||||
|
||||
<br>
|
||||
</details>
|
||||
</details>
|
||||
|
||||
## 社区支持
|
||||
|
||||
学 AI , 上 L 站:[LinuxDO](https://linux.do)
|
||||
|
||||
## Contributors
|
||||
|
||||
感谢所有为本项目做出贡献的开发者:
|
||||
|
||||
<a href="https://github.com/basketikun/chatgpt2api/graphs/contributors">
|
||||
<img alt="Contributors" src="https://contrib.rocks/image?repo=basketikun/chatgpt2api" />
|
||||
</a>
|
||||
|
||||
## Star History
|
||||
|
||||
[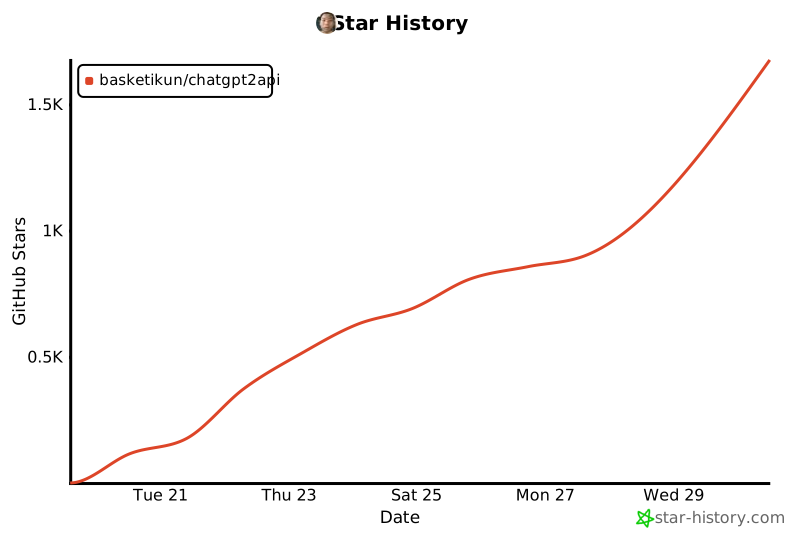](https://www.star-history.com/?repos=basketikun%2Fchatgpt2api&type=date&legend=top-left)
|
||||
@@ -0,0 +1,2 @@
|
||||
from api.app import create_app
|
||||
|
||||
+537
@@ -0,0 +1,537 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import asyncio
|
||||
import io
|
||||
import json
|
||||
import re
|
||||
import uuid
|
||||
import zipfile
|
||||
from datetime import datetime
|
||||
from typing import Any, Literal
|
||||
|
||||
from fastapi import APIRouter, Header, HTTPException
|
||||
from fastapi.concurrency import run_in_threadpool
|
||||
from fastapi.responses import Response
|
||||
from pydantic import BaseModel, Field
|
||||
|
||||
from services.auth_service import auth_service
|
||||
|
||||
from api.support import (
|
||||
require_admin,
|
||||
sanitize_cpa_pool,
|
||||
sanitize_cpa_pools,
|
||||
sanitize_sub2api_server,
|
||||
sanitize_sub2api_servers,
|
||||
)
|
||||
from services.account_service import account_service
|
||||
from services.cpa_service import cpa_config, cpa_import_service, list_remote_files
|
||||
from services.oauth_login_service import OAuthLoginError, oauth_login_service
|
||||
from services.sub2api_service import (
|
||||
list_remote_accounts as sub2api_list_remote_accounts,
|
||||
list_remote_groups as sub2api_list_remote_groups,
|
||||
sub2api_config,
|
||||
sub2api_import_service,
|
||||
)
|
||||
|
||||
|
||||
|
||||
class UserKeyCreateRequest(BaseModel):
|
||||
name: str = ""
|
||||
|
||||
|
||||
class UserKeyUpdateRequest(BaseModel):
|
||||
name: str | None = None
|
||||
enabled: bool | None = None
|
||||
key: str | None = None
|
||||
|
||||
|
||||
class AccountCreateRequest(BaseModel):
|
||||
tokens: list[str] = Field(default_factory=list)
|
||||
accounts: list[dict[str, Any]] = Field(default_factory=list)
|
||||
|
||||
|
||||
class AccountDeleteRequest(BaseModel):
|
||||
tokens: list[str] = Field(default_factory=list)
|
||||
|
||||
|
||||
class AccountRefreshRequest(BaseModel):
|
||||
access_tokens: list[str] = Field(default_factory=list)
|
||||
|
||||
|
||||
class AccountExportRequest(BaseModel):
|
||||
access_tokens: list[str] = Field(default_factory=list)
|
||||
format: Literal["json", "zip"] = "json"
|
||||
|
||||
|
||||
class AccountUpdateRequest(BaseModel):
|
||||
access_token: str = ""
|
||||
type: str | None = None
|
||||
status: str | None = None
|
||||
quota: int | None = None
|
||||
proxy: str | None = None
|
||||
|
||||
|
||||
class CPAPoolCreateRequest(BaseModel):
|
||||
name: str = ""
|
||||
base_url: str = ""
|
||||
secret_key: str = ""
|
||||
|
||||
|
||||
class CPAPoolUpdateRequest(BaseModel):
|
||||
name: str | None = None
|
||||
base_url: str | None = None
|
||||
secret_key: str | None = None
|
||||
|
||||
|
||||
class CPAImportRequest(BaseModel):
|
||||
names: list[str] = Field(default_factory=list)
|
||||
|
||||
|
||||
class Sub2APIServerCreateRequest(BaseModel):
|
||||
name: str = ""
|
||||
base_url: str = ""
|
||||
email: str = ""
|
||||
password: str = ""
|
||||
api_key: str = ""
|
||||
group_id: str = ""
|
||||
|
||||
|
||||
class Sub2APIServerUpdateRequest(BaseModel):
|
||||
name: str | None = None
|
||||
base_url: str | None = None
|
||||
email: str | None = None
|
||||
password: str | None = None
|
||||
api_key: str | None = None
|
||||
group_id: str | None = None
|
||||
|
||||
|
||||
class Sub2APIImportRequest(BaseModel):
|
||||
account_ids: list[str] = Field(default_factory=list)
|
||||
|
||||
|
||||
class OAuthLoginStartRequest(BaseModel):
|
||||
"""起始 OAuth 桥。email_hint 可选,仅用于让 OpenAI 登录页预填邮箱。"""
|
||||
email_hint: str = ""
|
||||
|
||||
|
||||
class OAuthLoginFinishRequest(BaseModel):
|
||||
"""提交 callback。callback 既可以是完整 URL 也可以只填 code。"""
|
||||
session_id: str = ""
|
||||
callback: str = ""
|
||||
|
||||
|
||||
def _account_payload_token(item: dict[str, Any]) -> str:
|
||||
return str(item.get("access_token") or item.get("accessToken") or "").strip()
|
||||
|
||||
|
||||
def _unique_tokens(tokens: list[str]) -> list[str]:
|
||||
return list(dict.fromkeys(str(token or "").strip() for token in tokens if str(token or "").strip()))
|
||||
|
||||
|
||||
def _download_timestamp() -> str:
|
||||
return datetime.now().strftime("%Y%m%d-%H%M%S")
|
||||
|
||||
|
||||
def _safe_export_name(value: str, fallback: str) -> str:
|
||||
clean = re.sub(r"[^A-Za-z0-9._-]+", "-", value.strip()).strip("-._")
|
||||
return (clean or fallback)[:80]
|
||||
|
||||
|
||||
def _account_zip_bytes(items: list[dict[str, str]]) -> bytes:
|
||||
buf = io.BytesIO()
|
||||
used_names: set[str] = set()
|
||||
with zipfile.ZipFile(buf, "w", zipfile.ZIP_DEFLATED) as archive:
|
||||
for index, item in enumerate(items, start=1):
|
||||
raw_name = item.get("email") or item.get("account_id") or f"account-{index:03d}"
|
||||
base_name = _safe_export_name(raw_name, f"account-{index:03d}")
|
||||
name = base_name
|
||||
suffix = 2
|
||||
while name in used_names:
|
||||
name = f"{base_name}-{suffix}"
|
||||
suffix += 1
|
||||
used_names.add(name)
|
||||
archive.writestr(
|
||||
f"{name}.json",
|
||||
json.dumps(item, ensure_ascii=False, indent=2) + "\n",
|
||||
)
|
||||
return buf.getvalue()
|
||||
|
||||
|
||||
def create_router() -> APIRouter:
|
||||
router = APIRouter()
|
||||
|
||||
@router.get("/api/auth/users")
|
||||
async def list_user_keys(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {"items": auth_service.list_keys(role="user")}
|
||||
|
||||
@router.post("/api/auth/users")
|
||||
async def create_user_key(body: UserKeyCreateRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
try:
|
||||
item, raw_key = auth_service.create_key(role="user", name=body.name)
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
return {"item": item, "key": raw_key, "items": auth_service.list_keys(role="user")}
|
||||
|
||||
@router.post("/api/auth/users/{key_id}")
|
||||
async def update_user_key(
|
||||
key_id: str,
|
||||
body: UserKeyUpdateRequest,
|
||||
authorization: str | None = Header(default=None),
|
||||
):
|
||||
require_admin(authorization)
|
||||
updates = {
|
||||
key: value
|
||||
for key, value in {
|
||||
"name": body.name,
|
||||
"enabled": body.enabled,
|
||||
"key": body.key,
|
||||
}.items()
|
||||
if value is not None
|
||||
}
|
||||
if not updates:
|
||||
raise HTTPException(status_code=400, detail={"error": "还没有检测到改动,请修改后再保存"})
|
||||
try:
|
||||
item = auth_service.update_key(key_id, updates, role="user")
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
if item is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "这条用户密钥不存在,可能已经被删除"})
|
||||
return {"item": item, "items": auth_service.list_keys(role="user")}
|
||||
|
||||
@router.delete("/api/auth/users/{key_id}")
|
||||
async def delete_user_key(key_id: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
if not auth_service.delete_key(key_id, role="user"):
|
||||
raise HTTPException(status_code=404, detail={"error": "这条用户密钥不存在,可能已经被删除"})
|
||||
return {"items": auth_service.list_keys(role="user")}
|
||||
|
||||
@router.get("/api/accounts")
|
||||
async def get_accounts(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {"items": account_service.list_accounts()}
|
||||
|
||||
@router.post("/api/accounts")
|
||||
async def create_accounts(body: AccountCreateRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
account_payloads = [item for item in body.accounts if isinstance(item, dict)]
|
||||
payload_tokens = [_account_payload_token(item) for item in account_payloads]
|
||||
tokens = _unique_tokens([*body.tokens, *payload_tokens])
|
||||
if not tokens:
|
||||
raise HTTPException(status_code=400, detail={"error": "tokens is required"})
|
||||
if account_payloads:
|
||||
result = account_service.add_account_items(account_payloads)
|
||||
payload_token_set = set(_unique_tokens(payload_tokens))
|
||||
extra_tokens = [token for token in tokens if token not in payload_token_set]
|
||||
if extra_tokens:
|
||||
extra_result = account_service.add_accounts(extra_tokens)
|
||||
result["added"] = int(result.get("added") or 0) + int(extra_result.get("added") or 0)
|
||||
result["skipped"] = int(result.get("skipped") or 0) + int(extra_result.get("skipped") or 0)
|
||||
else:
|
||||
result = account_service.add_accounts(tokens)
|
||||
refresh_result = account_service.refresh_accounts(tokens)
|
||||
return {
|
||||
**result,
|
||||
"refreshed": refresh_result.get("refreshed", 0),
|
||||
"errors": refresh_result.get("errors", []),
|
||||
"items": refresh_result.get("items", result.get("items", [])),
|
||||
}
|
||||
|
||||
@router.delete("/api/accounts")
|
||||
async def delete_accounts(body: AccountDeleteRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
tokens = [str(token or "").strip() for token in body.tokens if str(token or "").strip()]
|
||||
if not tokens:
|
||||
raise HTTPException(status_code=400, detail={"error": "tokens is required"})
|
||||
return account_service.delete_accounts(tokens)
|
||||
|
||||
@router.post("/api/accounts/refresh")
|
||||
async def refresh_accounts(body: AccountRefreshRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
access_tokens = [str(token or "").strip() for token in body.access_tokens if str(token or "").strip()]
|
||||
if not access_tokens:
|
||||
access_tokens = account_service.list_tokens()
|
||||
if not access_tokens:
|
||||
raise HTTPException(status_code=400, detail={"error": "access_tokens is required"})
|
||||
|
||||
progress_id = str(uuid.uuid4())
|
||||
|
||||
async def _do_refresh():
|
||||
try:
|
||||
await run_in_threadpool(account_service.refresh_accounts, access_tokens, progress_id, False)
|
||||
except Exception as e:
|
||||
account_service.finish_refresh_progress(progress_id, error=str(e))
|
||||
|
||||
asyncio.create_task(_do_refresh())
|
||||
|
||||
return {"progress_id": progress_id}
|
||||
|
||||
@router.get("/api/accounts/refresh/progress/{progress_id}")
|
||||
async def get_refresh_progress(progress_id: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
progress = account_service.get_refresh_progress(progress_id)
|
||||
if progress is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "progress not found"})
|
||||
return progress
|
||||
|
||||
@router.post("/api/accounts/re-login")
|
||||
async def re_login_accounts(body: AccountRefreshRequest, authorization: str | None = Header(default=None)):
|
||||
"""对选中账号执行密码重新登录流程(密码登录→验证码登录→刷新token)。"""
|
||||
require_admin(authorization)
|
||||
access_tokens = [str(token or "").strip() for token in body.access_tokens if str(token or "").strip()]
|
||||
if not access_tokens:
|
||||
raise HTTPException(status_code=400, detail={"error": "access_tokens is required"})
|
||||
|
||||
progress_id = str(uuid.uuid4())
|
||||
|
||||
async def _do_relogin():
|
||||
try:
|
||||
await run_in_threadpool(account_service.re_login_accounts, access_tokens, progress_id)
|
||||
except Exception as e:
|
||||
account_service.finish_relogin_progress(progress_id, error=str(e))
|
||||
|
||||
asyncio.create_task(_do_relogin())
|
||||
|
||||
return {"progress_id": progress_id}
|
||||
|
||||
@router.get("/api/accounts/re-login/progress/{progress_id}")
|
||||
async def get_relogin_progress(progress_id: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
progress = account_service.get_relogin_progress(progress_id)
|
||||
if progress is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "progress not found"})
|
||||
return progress
|
||||
|
||||
@router.post("/api/accounts/export")
|
||||
async def export_accounts(body: AccountExportRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
access_tokens = _unique_tokens(body.access_tokens)
|
||||
items = account_service.build_export_items(access_tokens)
|
||||
if not items:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail={"error": "没有可导出的完整账号,需要同时有 access_token、refresh_token 和 id_token"},
|
||||
)
|
||||
|
||||
timestamp = _download_timestamp()
|
||||
if body.format == "zip":
|
||||
content = _account_zip_bytes(items)
|
||||
return Response(
|
||||
content,
|
||||
media_type="application/zip",
|
||||
headers={"Content-Disposition": f'attachment; filename="codex-accounts-{timestamp}.zip"'},
|
||||
)
|
||||
|
||||
payload: dict[str, str] | list[dict[str, str]] = items[0] if len(items) == 1 else items
|
||||
return Response(
|
||||
json.dumps(payload, ensure_ascii=False, indent=2) + "\n",
|
||||
media_type="application/json",
|
||||
headers={"Content-Disposition": f'attachment; filename="codex-accounts-{timestamp}.json"'},
|
||||
)
|
||||
|
||||
@router.post("/api/accounts/update")
|
||||
async def update_account(body: AccountUpdateRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
access_token = str(body.access_token or "").strip()
|
||||
if not access_token:
|
||||
raise HTTPException(status_code=400, detail={"error": "access_token is required"})
|
||||
updates = {key: value for key, value in {"type": body.type, "status": body.status, "quota": body.quota, "proxy": body.proxy}.items() if value is not None}
|
||||
if not updates:
|
||||
raise HTTPException(status_code=400, detail={"error": "还没有检测到改动,请修改后再保存"})
|
||||
account = account_service.update_account(access_token, updates, manual=True)
|
||||
if account is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "account not found"})
|
||||
return {"item": account, "items": account_service.list_accounts()}
|
||||
|
||||
@router.post("/api/accounts/oauth/start")
|
||||
async def start_oauth_login(
|
||||
body: OAuthLoginStartRequest,
|
||||
authorization: str | None = Header(default=None),
|
||||
):
|
||||
"""登记一次 PKCE 会话,返回可让用户浏览器打开的 authorize URL。"""
|
||||
require_admin(authorization)
|
||||
try:
|
||||
return await run_in_threadpool(oauth_login_service.start, body.email_hint)
|
||||
except OAuthLoginError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.post("/api/accounts/oauth/finish")
|
||||
async def finish_oauth_login(
|
||||
body: OAuthLoginFinishRequest,
|
||||
authorization: str | None = Header(default=None),
|
||||
):
|
||||
"""收用户从浏览器抓回的 callback URL / code,换出 token 三件套并落盘。"""
|
||||
require_admin(authorization)
|
||||
# 入参日志:截断敏感字段,仅保留前几位,方便排错而不泄密
|
||||
cb_preview = (body.callback or "")[:80]
|
||||
sid_preview = (body.session_id or "")[:8]
|
||||
print(
|
||||
f"[oauth-login] finish called: session_id={sid_preview}..., callback_preview={cb_preview!r}",
|
||||
flush=True,
|
||||
)
|
||||
try:
|
||||
tokens = await run_in_threadpool(oauth_login_service.finish, body.session_id, body.callback)
|
||||
except OAuthLoginError as exc:
|
||||
print(f"[oauth-login] finish rejected: {exc}", flush=True)
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
payload = {
|
||||
"access_token": tokens["access_token"],
|
||||
"refresh_token": tokens["refresh_token"],
|
||||
"id_token": tokens["id_token"],
|
||||
"source_type": "oauth_login",
|
||||
}
|
||||
add_result = await run_in_threadpool(account_service.add_account_items, [payload])
|
||||
refresh_result = await run_in_threadpool(
|
||||
account_service.refresh_accounts, [tokens["access_token"]]
|
||||
)
|
||||
return {
|
||||
**add_result,
|
||||
"refreshed": refresh_result.get("refreshed", 0),
|
||||
"errors": refresh_result.get("errors", []),
|
||||
"items": refresh_result.get("items", add_result.get("items", [])),
|
||||
}
|
||||
|
||||
@router.get("/api/cpa/pools")
|
||||
async def list_cpa_pools(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {"pools": sanitize_cpa_pools(cpa_config.list_pools())}
|
||||
|
||||
@router.post("/api/cpa/pools")
|
||||
async def create_cpa_pool(body: CPAPoolCreateRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
if not body.base_url.strip():
|
||||
raise HTTPException(status_code=400, detail={"error": "base_url is required"})
|
||||
if not body.secret_key.strip():
|
||||
raise HTTPException(status_code=400, detail={"error": "secret_key is required"})
|
||||
pool = cpa_config.add_pool(name=body.name, base_url=body.base_url, secret_key=body.secret_key)
|
||||
return {"pool": sanitize_cpa_pool(pool), "pools": sanitize_cpa_pools(cpa_config.list_pools())}
|
||||
|
||||
@router.post("/api/cpa/pools/{pool_id}")
|
||||
async def update_cpa_pool(pool_id: str, body: CPAPoolUpdateRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
pool = cpa_config.update_pool(pool_id, body.model_dump(exclude_none=True))
|
||||
if pool is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "pool not found"})
|
||||
return {"pool": sanitize_cpa_pool(pool), "pools": sanitize_cpa_pools(cpa_config.list_pools())}
|
||||
|
||||
@router.delete("/api/cpa/pools/{pool_id}")
|
||||
async def delete_cpa_pool(pool_id: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
if not cpa_config.delete_pool(pool_id):
|
||||
raise HTTPException(status_code=404, detail={"error": "pool not found"})
|
||||
return {"pools": sanitize_cpa_pools(cpa_config.list_pools())}
|
||||
|
||||
@router.get("/api/cpa/pools/{pool_id}/files")
|
||||
async def cpa_pool_files(pool_id: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
pool = cpa_config.get_pool(pool_id)
|
||||
if pool is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "pool not found"})
|
||||
return {"pool_id": pool_id, "files": await run_in_threadpool(list_remote_files, pool)}
|
||||
|
||||
@router.post("/api/cpa/pools/{pool_id}/import")
|
||||
async def cpa_pool_import(pool_id: str, body: CPAImportRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
pool = cpa_config.get_pool(pool_id)
|
||||
if pool is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "pool not found"})
|
||||
try:
|
||||
job = cpa_import_service.start_import(pool, body.names)
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
return {"import_job": job}
|
||||
|
||||
@router.get("/api/cpa/pools/{pool_id}/import")
|
||||
async def cpa_pool_import_progress(pool_id: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
pool = cpa_config.get_pool(pool_id)
|
||||
if pool is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "pool not found"})
|
||||
return {"import_job": pool.get("import_job")}
|
||||
|
||||
@router.get("/api/sub2api/servers")
|
||||
async def list_sub2api_servers(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {"servers": sanitize_sub2api_servers(sub2api_config.list_servers())}
|
||||
|
||||
@router.post("/api/sub2api/servers")
|
||||
async def create_sub2api_server(body: Sub2APIServerCreateRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
if not body.base_url.strip():
|
||||
raise HTTPException(status_code=400, detail={"error": "base_url is required"})
|
||||
has_login = body.email.strip() and body.password.strip()
|
||||
has_api_key = bool(body.api_key.strip())
|
||||
if not has_login and not has_api_key:
|
||||
raise HTTPException(status_code=400, detail={"error": "email+password or api_key is required"})
|
||||
server = sub2api_config.add_server(
|
||||
name=body.name,
|
||||
base_url=body.base_url,
|
||||
email=body.email,
|
||||
password=body.password,
|
||||
api_key=body.api_key,
|
||||
group_id=body.group_id,
|
||||
)
|
||||
return {"server": sanitize_sub2api_server(server), "servers": sanitize_sub2api_servers(sub2api_config.list_servers())}
|
||||
|
||||
@router.post("/api/sub2api/servers/{server_id}")
|
||||
async def update_sub2api_server(server_id: str, body: Sub2APIServerUpdateRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
server = sub2api_config.update_server(server_id, body.model_dump(exclude_none=True))
|
||||
if server is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "server not found"})
|
||||
return {"server": sanitize_sub2api_server(server), "servers": sanitize_sub2api_servers(sub2api_config.list_servers())}
|
||||
|
||||
@router.delete("/api/sub2api/servers/{server_id}")
|
||||
async def delete_sub2api_server(server_id: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
if not sub2api_config.delete_server(server_id):
|
||||
raise HTTPException(status_code=404, detail={"error": "server not found"})
|
||||
return {"servers": sanitize_sub2api_servers(sub2api_config.list_servers())}
|
||||
|
||||
@router.get("/api/sub2api/servers/{server_id}/groups")
|
||||
async def sub2api_server_groups(server_id: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
server = sub2api_config.get_server(server_id)
|
||||
if server is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "server not found"})
|
||||
try:
|
||||
groups = await run_in_threadpool(sub2api_list_remote_groups, server)
|
||||
except Exception as exc:
|
||||
raise HTTPException(status_code=502, detail={"error": str(exc)}) from exc
|
||||
return {"server_id": server_id, "groups": groups}
|
||||
|
||||
@router.get("/api/sub2api/servers/{server_id}/accounts")
|
||||
async def sub2api_server_accounts(server_id: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
server = sub2api_config.get_server(server_id)
|
||||
if server is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "server not found"})
|
||||
try:
|
||||
accounts = await run_in_threadpool(sub2api_list_remote_accounts, server)
|
||||
except Exception as exc:
|
||||
raise HTTPException(status_code=502, detail={"error": str(exc)}) from exc
|
||||
return {"server_id": server_id, "accounts": accounts}
|
||||
|
||||
@router.post("/api/sub2api/servers/{server_id}/import")
|
||||
async def sub2api_server_import(server_id: str, body: Sub2APIImportRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
server = sub2api_config.get_server(server_id)
|
||||
if server is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "server not found"})
|
||||
try:
|
||||
job = sub2api_import_service.start_import(server, body.account_ids)
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
return {"import_job": job}
|
||||
|
||||
@router.get("/api/sub2api/servers/{server_id}/import")
|
||||
async def sub2api_server_import_progress(server_id: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
server = sub2api_config.get_server(server_id)
|
||||
if server is None:
|
||||
raise HTTPException(status_code=404, detail={"error": "server not found"})
|
||||
return {"import_job": server.get("import_job")}
|
||||
|
||||
return router
|
||||
@@ -0,0 +1,217 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from fastapi import APIRouter, Header, HTTPException, Request
|
||||
from fastapi.concurrency import run_in_threadpool
|
||||
from fastapi.responses import FileResponse
|
||||
from pydantic import BaseModel, ConfigDict, Field
|
||||
|
||||
from api.image_inputs import parse_image_edit_request, read_image_sources
|
||||
from api.support import require_identity, resolve_image_base_url
|
||||
from services.content_filter import check_request, request_shape, request_text
|
||||
from services.editable_file_task_service import editable_file_task_service
|
||||
from services.log_service import LoggedCall
|
||||
from services.protocol import (
|
||||
anthropic_v1_messages,
|
||||
openai_v1_chat_complete,
|
||||
openai_v1_image_edit,
|
||||
openai_v1_image_generations,
|
||||
openai_v1_models,
|
||||
openai_v1_response,
|
||||
openai_search,
|
||||
)
|
||||
|
||||
|
||||
class ImageGenerationRequest(BaseModel):
|
||||
prompt: str = Field(..., min_length=1)
|
||||
model: str = "gpt-image-2"
|
||||
n: int = Field(default=1, ge=1, le=4)
|
||||
size: str | None = None
|
||||
quality: str = "auto"
|
||||
response_format: str = "b64_json"
|
||||
history_disabled: bool = True
|
||||
stream: bool | None = None
|
||||
|
||||
|
||||
class ChatCompletionRequest(BaseModel):
|
||||
model_config = ConfigDict(extra="allow")
|
||||
model: str | None = None
|
||||
prompt: str | None = None
|
||||
n: int | None = None
|
||||
stream: bool | None = None
|
||||
modalities: list[str] | None = None
|
||||
messages: list[dict[str, object]] | None = None
|
||||
|
||||
|
||||
class ResponseCreateRequest(BaseModel):
|
||||
model_config = ConfigDict(extra="allow")
|
||||
model: str | None = None
|
||||
input: object | None = None
|
||||
tools: list[dict[str, object]] | None = None
|
||||
tool_choice: object | None = None
|
||||
stream: bool | None = None
|
||||
|
||||
|
||||
class AnthropicMessageRequest(BaseModel):
|
||||
model_config = ConfigDict(extra="allow")
|
||||
model: str | None = None
|
||||
messages: list[dict[str, object]] | None = None
|
||||
system: object | None = None
|
||||
stream: bool | None = None
|
||||
|
||||
|
||||
class SearchRequest(BaseModel):
|
||||
prompt: str = Field(..., min_length=1)
|
||||
|
||||
|
||||
class EditableFileTaskRequest(BaseModel):
|
||||
prompt: str = ""
|
||||
base64_images: list[str] = Field(default_factory=list)
|
||||
client_task_id: str | None = None
|
||||
|
||||
|
||||
async def filter_or_log(call: LoggedCall, text: str) -> None:
|
||||
try:
|
||||
await run_in_threadpool(check_request, text)
|
||||
except HTTPException as exc:
|
||||
call.log("调用失败", status="failed", error=str(exc.detail))
|
||||
raise
|
||||
|
||||
|
||||
def create_router() -> APIRouter:
|
||||
router = APIRouter()
|
||||
|
||||
@router.get("/v1/models")
|
||||
async def list_models(authorization: str | None = Header(default=None)):
|
||||
require_identity(authorization)
|
||||
try:
|
||||
return await run_in_threadpool(openai_v1_models.list_models)
|
||||
except Exception as exc:
|
||||
raise HTTPException(status_code=502, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.post("/v1/images/generations")
|
||||
async def generate_images(
|
||||
body: ImageGenerationRequest,
|
||||
request: Request,
|
||||
authorization: str | None = Header(default=None),
|
||||
):
|
||||
identity = require_identity(authorization)
|
||||
payload = body.model_dump(mode="python")
|
||||
payload["base_url"] = resolve_image_base_url(request)
|
||||
call = LoggedCall(identity, "/v1/images/generations", body.model, "文生图", request_text=body.prompt)
|
||||
await filter_or_log(call, body.prompt)
|
||||
return await call.run(openai_v1_image_generations.handle, payload)
|
||||
|
||||
@router.post("/v1/images/edits")
|
||||
async def edit_images(
|
||||
request: Request,
|
||||
authorization: str | None = Header(default=None),
|
||||
):
|
||||
identity = require_identity(authorization)
|
||||
payload, image_sources, mask_sources = await parse_image_edit_request(request)
|
||||
prompt = str(payload["prompt"])
|
||||
model = str(payload["model"])
|
||||
call = LoggedCall(identity, "/v1/images/edits", model, "图生图", request_text=prompt)
|
||||
await filter_or_log(call, prompt)
|
||||
payload["images"] = await read_image_sources(image_sources)
|
||||
if mask_sources:
|
||||
payload["mask"] = await read_image_sources(mask_sources)
|
||||
payload["base_url"] = resolve_image_base_url(request)
|
||||
return await call.run(openai_v1_image_edit.handle, payload)
|
||||
|
||||
@router.post("/v1/chat/completions")
|
||||
async def create_chat_completion(body: ChatCompletionRequest, authorization: str | None = Header(default=None)):
|
||||
identity = require_identity(authorization)
|
||||
payload = body.model_dump(mode="python")
|
||||
model = str(payload.get("model") or "auto")
|
||||
request_preview = request_text(payload.get("prompt"), payload.get("messages"))
|
||||
call = LoggedCall(
|
||||
identity,
|
||||
"/v1/chat/completions",
|
||||
model,
|
||||
"文本生成",
|
||||
request_text=request_preview,
|
||||
request_shape=request_shape(payload.get("messages")),
|
||||
)
|
||||
await filter_or_log(call, request_preview)
|
||||
return await call.run(openai_v1_chat_complete.handle, payload)
|
||||
|
||||
@router.post("/v1/responses")
|
||||
async def create_response(body: ResponseCreateRequest, authorization: str | None = Header(default=None)):
|
||||
identity = require_identity(authorization)
|
||||
payload = body.model_dump(mode="python")
|
||||
model = str(payload.get("model") or "auto")
|
||||
request_preview = request_text(payload.get("input"), payload.get("instructions"))
|
||||
call = LoggedCall(
|
||||
identity,
|
||||
"/v1/responses",
|
||||
model,
|
||||
"Responses",
|
||||
request_text=request_preview,
|
||||
request_shape=request_shape(payload.get("input")),
|
||||
)
|
||||
await filter_or_log(call, request_preview)
|
||||
return await call.run(openai_v1_response.handle, payload)
|
||||
|
||||
@router.post("/v1/messages")
|
||||
async def create_message(
|
||||
body: AnthropicMessageRequest,
|
||||
authorization: str | None = Header(default=None),
|
||||
x_api_key: str | None = Header(default=None, alias="x-api-key"),
|
||||
anthropic_version: str | None = Header(default=None, alias="anthropic-version"),
|
||||
):
|
||||
identity = require_identity(authorization or (f"Bearer {x_api_key}" if x_api_key else None))
|
||||
payload = body.model_dump(mode="python")
|
||||
model = str(payload.get("model") or "auto")
|
||||
request_preview = request_text(payload.get("system"), payload.get("messages"), payload.get("tools"))
|
||||
call = LoggedCall(identity, "/v1/messages", model, "Messages", request_text=request_preview)
|
||||
await filter_or_log(call, request_preview)
|
||||
return await call.run(anthropic_v1_messages.handle, payload, sse="anthropic")
|
||||
|
||||
@router.post("/v1/search")
|
||||
async def search(body: SearchRequest, authorization: str | None = Header(default=None)):
|
||||
identity = require_identity(authorization)
|
||||
call = LoggedCall(identity, "/v1/search", openai_search.MODEL, "搜索", request_text=body.prompt)
|
||||
await filter_or_log(call, body.prompt)
|
||||
return await call.run(openai_search.handle, body.model_dump(mode="python"))
|
||||
|
||||
@router.get("/v1/editable-file-tasks")
|
||||
async def list_editable_file_tasks(ids: str = "", authorization: str | None = Header(default=None)):
|
||||
identity = require_identity(authorization)
|
||||
task_ids = [item.strip() for item in ids.split(",") if item.strip()]
|
||||
return await run_in_threadpool(editable_file_task_service.list_tasks, identity, task_ids)
|
||||
|
||||
@router.get("/files/{file_path:path}")
|
||||
async def download_editable_file(file_path: str):
|
||||
try:
|
||||
path = await run_in_threadpool(editable_file_task_service.public_file_path, file_path)
|
||||
except Exception as exc:
|
||||
raise HTTPException(status_code=404, detail={"error": "file not found"}) from exc
|
||||
return FileResponse(path, filename=path.name)
|
||||
|
||||
@router.post("/v1/ppt/generations")
|
||||
async def create_ppt_task(body: EditableFileTaskRequest, request: Request, authorization: str | None = Header(default=None)):
|
||||
identity = require_identity(authorization)
|
||||
await filter_or_log(LoggedCall(identity, "/v1/ppt/generations", "gpt-5-5-thinking", "PPT生成任务", request_text=body.prompt), body.prompt)
|
||||
return await run_in_threadpool(
|
||||
editable_file_task_service.submit_ppt,
|
||||
identity,
|
||||
client_task_id=body.client_task_id or "",
|
||||
prompt=body.prompt,
|
||||
base64_images=body.base64_images,
|
||||
base_url=resolve_image_base_url(request),
|
||||
)
|
||||
|
||||
@router.post("/v1/psd/generations")
|
||||
async def create_psd_task(body: EditableFileTaskRequest, request: Request, authorization: str | None = Header(default=None)):
|
||||
identity = require_identity(authorization)
|
||||
await filter_or_log(LoggedCall(identity, "/v1/psd/generations", "gpt-5-5-thinking", "PSD生成任务", request_text=body.prompt), body.prompt)
|
||||
return await run_in_threadpool(
|
||||
editable_file_task_service.submit_psd,
|
||||
identity,
|
||||
client_task_id=body.client_task_id or "",
|
||||
prompt=body.prompt,
|
||||
base64_images=body.base64_images,
|
||||
base_url=resolve_image_base_url(request),
|
||||
)
|
||||
|
||||
return router
|
||||
+62
@@ -0,0 +1,62 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from contextlib import asynccontextmanager
|
||||
from threading import Event
|
||||
|
||||
from fastapi import FastAPI, HTTPException
|
||||
from fastapi.middleware.cors import CORSMiddleware
|
||||
from fastapi.responses import FileResponse
|
||||
|
||||
from api import accounts, ai, image_tasks, system
|
||||
from api.errors import install_exception_handlers
|
||||
from api.support import resolve_web_asset, start_limited_account_watcher
|
||||
from services.backup_service import backup_service
|
||||
from services.config import config
|
||||
from services.image_service import start_image_cleanup_scheduler
|
||||
|
||||
|
||||
def create_app() -> FastAPI:
|
||||
app_version = config.app_version
|
||||
|
||||
@asynccontextmanager
|
||||
async def lifespan(_: FastAPI):
|
||||
stop_event = Event()
|
||||
thread = start_limited_account_watcher(stop_event)
|
||||
cleanup_thread = start_image_cleanup_scheduler(stop_event)
|
||||
backup_service.start()
|
||||
config.cleanup_old_images()
|
||||
try:
|
||||
yield
|
||||
finally:
|
||||
stop_event.set()
|
||||
thread.join(timeout=1)
|
||||
cleanup_thread.join(timeout=1)
|
||||
backup_service.stop()
|
||||
|
||||
app = FastAPI(title="chatgpt2api", version=app_version, lifespan=lifespan)
|
||||
install_exception_handlers(app)
|
||||
app.add_middleware(
|
||||
CORSMiddleware,
|
||||
allow_origins=["*"],
|
||||
allow_credentials=False,
|
||||
allow_methods=["*"],
|
||||
allow_headers=["*"],
|
||||
)
|
||||
app.include_router(ai.create_router())
|
||||
app.include_router(accounts.create_router())
|
||||
app.include_router(image_tasks.create_router())
|
||||
app.include_router(system.create_router(app_version))
|
||||
|
||||
@app.api_route("/{full_path:path}", methods=["GET", "HEAD"], include_in_schema=False)
|
||||
async def serve_web(full_path: str):
|
||||
asset = resolve_web_asset(full_path)
|
||||
if asset is not None:
|
||||
return FileResponse(asset)
|
||||
if full_path.strip("/").startswith("_next/"):
|
||||
raise HTTPException(status_code=404, detail="Not Found")
|
||||
fallback = resolve_web_asset("")
|
||||
if fallback is None:
|
||||
raise HTTPException(status_code=404, detail="Not Found")
|
||||
return FileResponse(fallback)
|
||||
|
||||
return app
|
||||
@@ -0,0 +1,46 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from fastapi import FastAPI, Request
|
||||
from fastapi.encoders import jsonable_encoder
|
||||
from fastapi.exceptions import RequestValidationError
|
||||
from fastapi.responses import JSONResponse
|
||||
from starlette.exceptions import HTTPException as StarletteHTTPException
|
||||
|
||||
from services.protocol.error_response import anthropic_error_response, openai_error_response
|
||||
|
||||
|
||||
def _is_openai_compatible_path(path: str) -> bool:
|
||||
return path == "/v1" or path.startswith("/v1/")
|
||||
|
||||
|
||||
def _is_anthropic_messages_path(path: str) -> bool:
|
||||
return path == "/v1/messages"
|
||||
|
||||
|
||||
def _compatible_error_response(
|
||||
request: Request,
|
||||
detail: object,
|
||||
status_code: int,
|
||||
headers: dict[str, str] | None = None,
|
||||
) -> JSONResponse:
|
||||
if _is_anthropic_messages_path(request.url.path):
|
||||
return anthropic_error_response(detail, status_code, headers=headers)
|
||||
return openai_error_response(detail, status_code, headers=headers)
|
||||
|
||||
|
||||
def install_exception_handlers(app: FastAPI) -> None:
|
||||
@app.exception_handler(StarletteHTTPException)
|
||||
async def http_exception_handler(request: Request, exc: StarletteHTTPException) -> JSONResponse:
|
||||
if _is_openai_compatible_path(request.url.path):
|
||||
return _compatible_error_response(request, exc.detail, exc.status_code, exc.headers)
|
||||
return JSONResponse(
|
||||
status_code=exc.status_code,
|
||||
content={"detail": jsonable_encoder(exc.detail)},
|
||||
headers=exc.headers,
|
||||
)
|
||||
|
||||
@app.exception_handler(RequestValidationError)
|
||||
async def validation_exception_handler(request: Request, exc: RequestValidationError) -> JSONResponse:
|
||||
if _is_openai_compatible_path(request.url.path):
|
||||
return _compatible_error_response(request, exc.errors(), 422)
|
||||
return JSONResponse(status_code=422, content={"detail": jsonable_encoder(exc.errors())})
|
||||
@@ -0,0 +1,309 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import base64
|
||||
import binascii
|
||||
import json
|
||||
import mimetypes
|
||||
import re
|
||||
from pathlib import PurePosixPath
|
||||
from typing import Any, TypeGuard
|
||||
from urllib.parse import unquote, unquote_to_bytes, urlparse
|
||||
|
||||
from curl_cffi import requests
|
||||
from fastapi import HTTPException, Request
|
||||
from fastapi.concurrency import run_in_threadpool
|
||||
from starlette.datastructures import UploadFile
|
||||
|
||||
from services.proxy_service import proxy_settings
|
||||
|
||||
ImageInput = tuple[bytes, str, str]
|
||||
ImageSource = str | UploadFile | ImageInput
|
||||
|
||||
MAX_IMAGE_REFERENCE_BYTES = 50 * 1024 * 1024
|
||||
IMAGE_REFERENCE_FIELDS = {"image", "image[]", "images", "images[]", "image_url", "image_url[]"}
|
||||
MASK_REFERENCE_FIELDS = {"mask", "mask[]"}
|
||||
|
||||
|
||||
def _clean(value: object, default: str = "") -> str:
|
||||
"""清理字符串:转换为字符串并去掉首尾空白。"""
|
||||
text = str(value if value is not None else default).strip()
|
||||
return text or default
|
||||
|
||||
|
||||
def _is_upload(value: object) -> TypeGuard[UploadFile]:
|
||||
"""识别上传文件:兼容 Starlette 表单返回的 UploadFile。"""
|
||||
return isinstance(value, UploadFile)
|
||||
|
||||
|
||||
def _parse_bool(value: object) -> bool | None:
|
||||
"""解析布尔字段:兼容 JSON 布尔值和表单字符串。"""
|
||||
if value is None or value == "":
|
||||
return None
|
||||
if isinstance(value, bool):
|
||||
return value
|
||||
text = _clean(value).lower()
|
||||
if text in {"true", "1", "yes", "y", "on"}:
|
||||
return True
|
||||
if text in {"false", "0", "no", "n", "off"}:
|
||||
return False
|
||||
raise HTTPException(status_code=400, detail={"error": "stream must be a boolean"})
|
||||
|
||||
|
||||
def _parse_count(value: object) -> int:
|
||||
"""解析生成数量:保持图片接口的 1 到 4 限制。"""
|
||||
try:
|
||||
count = int(value or 1)
|
||||
except (TypeError, ValueError) as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": "n must be an integer"}) from exc
|
||||
if count < 1 or count > 4:
|
||||
raise HTTPException(status_code=400, detail={"error": "n must be between 1 and 4"})
|
||||
return count
|
||||
|
||||
|
||||
def _payload_from_fields(fields: dict[str, Any]) -> dict[str, Any]:
|
||||
"""构造图片编辑载荷:从表单或 JSON 字段提取通用参数。"""
|
||||
prompt = _clean(fields.get("prompt"))
|
||||
if not prompt:
|
||||
raise HTTPException(status_code=400, detail={"error": "prompt is required"})
|
||||
payload = {
|
||||
"prompt": prompt,
|
||||
"model": _clean(fields.get("model"), "gpt-image-2"),
|
||||
"n": _parse_count(fields.get("n")),
|
||||
"size": _clean(fields.get("size")) or None,
|
||||
"quality": _clean(fields.get("quality"), "auto"),
|
||||
"response_format": _clean(fields.get("response_format"), "b64_json"),
|
||||
"stream": _parse_bool(fields.get("stream")),
|
||||
}
|
||||
if "client_task_id" in fields:
|
||||
payload["client_task_id"] = _clean(fields.get("client_task_id"))
|
||||
return payload
|
||||
|
||||
|
||||
def _json_reference_value(value: object) -> object:
|
||||
"""解析表单图片引用:支持把 images 字段写成 JSON 字符串。"""
|
||||
if not isinstance(value, str):
|
||||
return value
|
||||
text = value.strip()
|
||||
if not text or text[0] not in "[{":
|
||||
return value
|
||||
try:
|
||||
return json.loads(text)
|
||||
except json.JSONDecodeError:
|
||||
return value
|
||||
|
||||
|
||||
def _decode_base64_image(value: object, filename: str, mime_type: str) -> ImageInput:
|
||||
try:
|
||||
data = base64.b64decode(str(value).strip(), validate=True)
|
||||
except (binascii.Error, ValueError) as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": "invalid base64 image data"}) from exc
|
||||
if not data:
|
||||
raise HTTPException(status_code=400, detail={"error": "image file is empty"})
|
||||
if len(data) > MAX_IMAGE_REFERENCE_BYTES:
|
||||
raise HTTPException(status_code=400, detail={"error": "image URL exceeds 50MB limit"})
|
||||
return data, filename, mime_type
|
||||
|
||||
|
||||
def _source_from_object(value: dict[str, Any]) -> list[ImageSource]:
|
||||
"""提取图片引用对象:支持 image_url 或 url,明确拒绝 file_id。"""
|
||||
has_url = "image_url" in value or "url" in value
|
||||
if value.get("file_id"):
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail={"error": "file_id image references are not supported; use image_url instead"},
|
||||
)
|
||||
inline = value.get("b64_json") or value.get("base64")
|
||||
if inline:
|
||||
filename = _clean(value.get("filename") or value.get("file_name"), "image.png")
|
||||
mime_type = _clean(value.get("mime_type") or value.get("mimeType"), "image/png")
|
||||
return [_decode_base64_image(inline, filename, mime_type)]
|
||||
if not has_url:
|
||||
raise HTTPException(status_code=400, detail={"error": "image reference must include image_url"})
|
||||
image_url = value.get("image_url", value.get("url"))
|
||||
if isinstance(image_url, dict):
|
||||
image_url = image_url.get("url")
|
||||
return _sources_from_value(image_url)
|
||||
|
||||
|
||||
def _sources_from_value(value: object) -> list[ImageSource]:
|
||||
"""展开图片引用:把字符串、数组和对象统一成图片来源列表。"""
|
||||
value = _json_reference_value(value)
|
||||
if _is_upload(value):
|
||||
return [value]
|
||||
if isinstance(value, str):
|
||||
text = value.strip()
|
||||
if not text:
|
||||
return []
|
||||
if text.lower().startswith(("data:", "http://", "https://")):
|
||||
return [text]
|
||||
return [_decode_base64_image(text, "image.png", "image/png")]
|
||||
if isinstance(value, list):
|
||||
sources: list[ImageSource] = []
|
||||
for item in value:
|
||||
sources.extend(_sources_from_value(item))
|
||||
return sources
|
||||
if isinstance(value, dict):
|
||||
return _source_from_object(value)
|
||||
if value is None:
|
||||
return []
|
||||
raise HTTPException(status_code=400, detail={"error": "invalid image reference"})
|
||||
|
||||
|
||||
def _json_image_sources(body: dict[str, Any]) -> list[ImageSource]:
|
||||
"""读取 JSON 图片引用:优先支持官方 images 数组字段。"""
|
||||
sources: list[ImageSource] = []
|
||||
for key in ("images", "image", "image_url"):
|
||||
if key in body:
|
||||
sources.extend(_sources_from_value(body.get(key)))
|
||||
return sources
|
||||
|
||||
|
||||
def _json_mask_sources(body: dict[str, Any]) -> list[ImageSource]:
|
||||
"""读取 JSON mask 引用。"""
|
||||
mask = body.get("mask")
|
||||
if mask is not None:
|
||||
return _sources_from_value(mask)
|
||||
return []
|
||||
|
||||
|
||||
async def parse_image_edit_request(request: Request) -> tuple[dict[str, Any], list[ImageSource], list[ImageSource]]:
|
||||
"""解析图片编辑请求:同时支持 multipart 上传和官方 JSON 图片 URL。
|
||||
|
||||
返回 (payload, image_sources, mask_sources)
|
||||
"""
|
||||
content_type = request.headers.get("content-type", "").split(";", 1)[0].strip().lower()
|
||||
if content_type == "application/json":
|
||||
try:
|
||||
body = await request.json()
|
||||
except json.JSONDecodeError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": "invalid JSON body"}) from exc
|
||||
if not isinstance(body, dict):
|
||||
raise HTTPException(status_code=400, detail={"error": "JSON body must be an object"})
|
||||
return _payload_from_fields(body), _json_image_sources(body), _json_mask_sources(body)
|
||||
|
||||
form = await request.form()
|
||||
fields: dict[str, Any] = {}
|
||||
for key in ("client_task_id", "prompt", "model", "n", "size", "quality", "response_format", "stream"):
|
||||
value = form.get(key)
|
||||
if isinstance(value, str):
|
||||
fields[key] = value
|
||||
sources: list[ImageSource] = []
|
||||
mask_sources: list[ImageSource] = []
|
||||
for key, value in form.multi_items():
|
||||
if key in IMAGE_REFERENCE_FIELDS:
|
||||
sources.extend(_sources_from_value(value))
|
||||
elif key in MASK_REFERENCE_FIELDS:
|
||||
mask_sources.extend(_sources_from_value(value))
|
||||
return _payload_from_fields(fields), sources, mask_sources
|
||||
|
||||
|
||||
def _extension_from_mime(mime_type: str) -> str:
|
||||
"""推导图片扩展名:把 MIME 类型转换为常见文件后缀。"""
|
||||
subtype = mime_type.split("/", 1)[1].split("+", 1)[0] if "/" in mime_type else "png"
|
||||
if subtype == "jpeg":
|
||||
return "jpg"
|
||||
return re.sub(r"[^a-z0-9]+", "", subtype.lower()) or "png"
|
||||
|
||||
|
||||
def _safe_filename(name: str, mime_type: str, fallback: str) -> str:
|
||||
"""生成安全文件名:清理 URL 文件名并补齐扩展名。"""
|
||||
cleaned = re.sub(r"[^A-Za-z0-9._-]+", "_", name).strip("._")
|
||||
if not cleaned:
|
||||
cleaned = fallback
|
||||
if "." not in cleaned:
|
||||
cleaned = f"{cleaned}.{_extension_from_mime(mime_type)}"
|
||||
return cleaned
|
||||
|
||||
|
||||
def _decode_data_url(url: str) -> ImageInput:
|
||||
"""解码 data URL:把内联图片转成标准图片输入元组。"""
|
||||
header, separator, payload = url.partition(",")
|
||||
if not separator:
|
||||
raise HTTPException(status_code=400, detail={"error": "invalid data image URL"})
|
||||
mime_type = header.split(";", 1)[0].removeprefix("data:") or "image/png"
|
||||
if not mime_type.startswith("image/"):
|
||||
raise HTTPException(status_code=400, detail={"error": "image_url must point to an image"})
|
||||
try:
|
||||
data = base64.b64decode(payload, validate=True) if ";base64" in header else unquote_to_bytes(payload)
|
||||
except (binascii.Error, ValueError) as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": "invalid data image URL"}) from exc
|
||||
if not data:
|
||||
raise HTTPException(status_code=400, detail={"error": "image URL is empty"})
|
||||
if len(data) > MAX_IMAGE_REFERENCE_BYTES:
|
||||
raise HTTPException(status_code=400, detail={"error": "image URL exceeds 50MB limit"})
|
||||
return data, f"image_url.{_extension_from_mime(mime_type)}", mime_type
|
||||
|
||||
|
||||
def _response_mime_type(response: requests.Response, parsed_path: str) -> str:
|
||||
"""识别下载图片类型:优先响应头,必要时按 URL 后缀推断。"""
|
||||
header_type = str(response.headers.get("content-type") or "").split(";", 1)[0].strip().lower()
|
||||
guessed_type = mimetypes.guess_type(parsed_path)[0] or ""
|
||||
if header_type.startswith("image/"):
|
||||
return header_type
|
||||
if header_type and header_type not in {"application/octet-stream", "binary/octet-stream"}:
|
||||
raise HTTPException(status_code=400, detail={"error": "image_url must point to an image"})
|
||||
if guessed_type.startswith("image/"):
|
||||
return guessed_type
|
||||
if not header_type or header_type in {"application/octet-stream", "binary/octet-stream"}:
|
||||
return "image/png"
|
||||
raise HTTPException(status_code=400, detail={"error": "image_url must point to an image"})
|
||||
|
||||
|
||||
def _filename_from_url(parsed_path: str, mime_type: str) -> str:
|
||||
"""生成 URL 图片文件名:从链接路径提取名称并做安全化。"""
|
||||
raw_name = PurePosixPath(unquote(parsed_path)).name
|
||||
return _safe_filename(raw_name, mime_type, "image_url")
|
||||
|
||||
|
||||
def _download_image_url(url: str) -> ImageInput:
|
||||
"""下载远程图片:把 http/https 图片链接转成标准图片输入元组。"""
|
||||
source = _clean(url)
|
||||
if source.startswith("data:"):
|
||||
return _decode_data_url(source)
|
||||
parsed = urlparse(source)
|
||||
if parsed.scheme not in {"http", "https"} or not parsed.netloc:
|
||||
raise HTTPException(status_code=400, detail={"error": "image_url must be an http or https URL"})
|
||||
try:
|
||||
response = requests.get(
|
||||
source,
|
||||
headers={"Accept": "image/*,*/*;q=0.8", "User-Agent": "chatgpt2api image fetcher"},
|
||||
timeout=60,
|
||||
allow_redirects=True,
|
||||
**proxy_settings.build_session_kwargs(),
|
||||
)
|
||||
except Exception as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": f"image_url fetch failed: {exc}"}) from exc
|
||||
if not 200 <= response.status_code < 300:
|
||||
raise HTTPException(status_code=400, detail={"error": f"image_url fetch failed: HTTP {response.status_code}"})
|
||||
content_length = _clean(response.headers.get("content-length"))
|
||||
if content_length and content_length.isdigit() and int(content_length) > MAX_IMAGE_REFERENCE_BYTES:
|
||||
raise HTTPException(status_code=400, detail={"error": "image_url exceeds 50MB limit"})
|
||||
data = response.content
|
||||
if not data:
|
||||
raise HTTPException(status_code=400, detail={"error": "image_url returned empty content"})
|
||||
if len(data) > MAX_IMAGE_REFERENCE_BYTES:
|
||||
raise HTTPException(status_code=400, detail={"error": "image_url exceeds 50MB limit"})
|
||||
mime_type = _response_mime_type(response, parsed.path)
|
||||
return data, _filename_from_url(parsed.path, mime_type), mime_type
|
||||
|
||||
|
||||
async def read_image_sources(sources: list[ImageSource]) -> list[ImageInput]:
|
||||
"""读取图片来源:上传文件直接读取,URL 下载后统一返回图片元组。"""
|
||||
images: list[ImageInput] = []
|
||||
for source in sources:
|
||||
if isinstance(source, tuple):
|
||||
images.append(source)
|
||||
continue
|
||||
if _is_upload(source):
|
||||
try:
|
||||
image_data = await source.read()
|
||||
finally:
|
||||
await source.close()
|
||||
if not image_data:
|
||||
raise HTTPException(status_code=400, detail={"error": "image file is empty"})
|
||||
images.append((image_data, source.filename or "image.png", source.content_type or "image/png"))
|
||||
continue
|
||||
images.append(await run_in_threadpool(_download_image_url, source))
|
||||
if not images:
|
||||
raise HTTPException(status_code=400, detail={"error": "image file or image_url is required"})
|
||||
return images
|
||||
@@ -0,0 +1,120 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from fastapi import APIRouter, Header, HTTPException, Query, Request
|
||||
from fastapi.concurrency import run_in_threadpool
|
||||
from pydantic import BaseModel, Field
|
||||
|
||||
from api.image_inputs import parse_image_edit_request, read_image_sources
|
||||
from api.support import require_identity, resolve_image_base_url
|
||||
from services.content_filter import check_request
|
||||
from services.image_task_service import image_task_service
|
||||
from services.log_service import LoggedCall
|
||||
|
||||
|
||||
class ImageGenerationTaskRequest(BaseModel):
|
||||
client_task_id: str = Field(..., min_length=1)
|
||||
prompt: str = Field(..., min_length=1)
|
||||
model: str = "gpt-image-2"
|
||||
size: str | None = None
|
||||
quality: str = "auto"
|
||||
|
||||
|
||||
class ResumePollRequest(BaseModel):
|
||||
extra_timeout_secs: float = Field(default=30.0, ge=5.0, le=120.0)
|
||||
|
||||
|
||||
def _parse_task_ids(value: str) -> list[str]:
|
||||
return [item.strip() for item in value.split(",") if item.strip()]
|
||||
|
||||
|
||||
async def filter_or_log(call: LoggedCall, text: str) -> None:
|
||||
try:
|
||||
await run_in_threadpool(check_request, text)
|
||||
except HTTPException as exc:
|
||||
call.log("调用失败", status="failed", error=str(exc.detail))
|
||||
raise
|
||||
|
||||
|
||||
def create_router() -> APIRouter:
|
||||
router = APIRouter()
|
||||
|
||||
@router.get("/api/image-tasks")
|
||||
async def list_image_tasks(
|
||||
ids: str = Query(default=""),
|
||||
authorization: str | None = Header(default=None),
|
||||
):
|
||||
identity = require_identity(authorization)
|
||||
return await run_in_threadpool(image_task_service.list_tasks, identity, _parse_task_ids(ids))
|
||||
|
||||
@router.post("/api/image-tasks/generations")
|
||||
async def create_generation_task(
|
||||
body: ImageGenerationTaskRequest,
|
||||
request: Request,
|
||||
authorization: str | None = Header(default=None),
|
||||
):
|
||||
identity = require_identity(authorization)
|
||||
await filter_or_log(LoggedCall(identity, "/api/image-tasks/generations", body.model, "文生图任务", request_text=body.prompt), body.prompt)
|
||||
try:
|
||||
return await run_in_threadpool(
|
||||
image_task_service.submit_generation,
|
||||
identity,
|
||||
client_task_id=body.client_task_id,
|
||||
prompt=body.prompt,
|
||||
model=body.model,
|
||||
size=body.size,
|
||||
quality=body.quality,
|
||||
base_url=resolve_image_base_url(request),
|
||||
)
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.post("/api/image-tasks/edits")
|
||||
async def create_edit_task(
|
||||
request: Request,
|
||||
authorization: str | None = Header(default=None),
|
||||
):
|
||||
identity = require_identity(authorization)
|
||||
payload, image_sources, mask_sources = await parse_image_edit_request(request)
|
||||
client_task_id = str(payload.get("client_task_id") or "").strip()
|
||||
if not client_task_id:
|
||||
raise HTTPException(status_code=400, detail={"error": "client_task_id is required"})
|
||||
prompt = str(payload["prompt"])
|
||||
model = str(payload["model"])
|
||||
await filter_or_log(LoggedCall(identity, "/api/image-tasks/edits", model, "图生图任务", request_text=prompt), prompt)
|
||||
images = await read_image_sources(image_sources)
|
||||
masks = await read_image_sources(mask_sources) if mask_sources else None
|
||||
try:
|
||||
return await run_in_threadpool(
|
||||
image_task_service.submit_edit,
|
||||
identity,
|
||||
client_task_id=client_task_id,
|
||||
prompt=prompt,
|
||||
model=model,
|
||||
size=payload["size"],
|
||||
quality=payload["quality"],
|
||||
base_url=resolve_image_base_url(request),
|
||||
images=images,
|
||||
masks=masks,
|
||||
)
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.post("/api/image-tasks/{task_id}/resume-poll")
|
||||
async def resume_image_poll(
|
||||
task_id: str,
|
||||
body: ResumePollRequest,
|
||||
request: Request,
|
||||
authorization: str | None = Header(default=None),
|
||||
):
|
||||
identity = require_identity(authorization)
|
||||
try:
|
||||
return await run_in_threadpool(
|
||||
image_task_service.resume_poll,
|
||||
identity,
|
||||
task_id,
|
||||
body.extra_timeout_secs,
|
||||
)
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
return router
|
||||
+134
@@ -0,0 +1,134 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
from threading import Event, Thread
|
||||
|
||||
from fastapi import HTTPException, Request
|
||||
|
||||
from services.account_service import account_service
|
||||
from services.auth_service import auth_service
|
||||
from services.config import config
|
||||
|
||||
BASE_DIR = Path(__file__).resolve().parents[1]
|
||||
WEB_DIST_DIR = BASE_DIR / "web_dist"
|
||||
|
||||
|
||||
def extract_bearer_token(authorization: str | None) -> str:
|
||||
scheme, _, value = str(authorization or "").partition(" ")
|
||||
if scheme.lower() != "bearer" or not value.strip():
|
||||
return ""
|
||||
return value.strip()
|
||||
|
||||
|
||||
def _legacy_admin_identity(token: str) -> dict[str, object] | None:
|
||||
auth_key = str(config.auth_key or "").strip()
|
||||
if auth_key and token == auth_key:
|
||||
return {"id": "admin", "name": "管理员", "role": "admin"}
|
||||
return None
|
||||
|
||||
|
||||
def require_identity(authorization: str | None) -> dict[str, object]:
|
||||
token = extract_bearer_token(authorization)
|
||||
identity = _legacy_admin_identity(token) or auth_service.authenticate(token)
|
||||
if identity is None:
|
||||
raise HTTPException(status_code=401, detail={"error": "密钥无效或已失效,请重新登录"})
|
||||
return identity
|
||||
|
||||
|
||||
def require_auth_key(authorization: str | None) -> None:
|
||||
require_identity(authorization)
|
||||
|
||||
|
||||
def require_admin(authorization: str | None) -> dict[str, object]:
|
||||
identity = require_identity(authorization)
|
||||
if identity.get("role") != "admin":
|
||||
raise HTTPException(status_code=403, detail={"error": "需要管理员权限才能执行这个操作"})
|
||||
return identity
|
||||
|
||||
|
||||
def resolve_image_base_url(request: Request) -> str:
|
||||
return config.base_url or f"{request.url.scheme}://{request.headers.get('host', request.url.netloc)}"
|
||||
|
||||
|
||||
def raise_image_quota_error(exc: Exception) -> None:
|
||||
message = str(exc)
|
||||
if "no available image quota" in message.lower():
|
||||
raise HTTPException(status_code=429, detail={"error": "no available image quota"}) from exc
|
||||
raise HTTPException(status_code=502, detail={"error": message}) from exc
|
||||
|
||||
|
||||
def sanitize_cpa_pool(pool: dict | None) -> dict | None:
|
||||
if not isinstance(pool, dict):
|
||||
return None
|
||||
return {key: value for key, value in pool.items() if key != "secret_key"}
|
||||
|
||||
|
||||
def sanitize_cpa_pools(pools: list[dict]) -> list[dict]:
|
||||
return [sanitized for pool in pools if (sanitized := sanitize_cpa_pool(pool)) is not None]
|
||||
|
||||
|
||||
def sanitize_sub2api_server(server: dict | None) -> dict | None:
|
||||
if not isinstance(server, dict):
|
||||
return None
|
||||
sanitized = {key: value for key, value in server.items() if key not in {"password", "api_key"}}
|
||||
sanitized["has_api_key"] = bool(str(server.get("api_key") or "").strip())
|
||||
return sanitized
|
||||
|
||||
|
||||
def sanitize_sub2api_servers(servers: list[dict]) -> list[dict]:
|
||||
return [sanitized for server in servers if (sanitized := sanitize_sub2api_server(server)) is not None]
|
||||
|
||||
|
||||
def start_limited_account_watcher(stop_event: Event) -> Thread:
|
||||
interval_seconds = config.refresh_account_interval_minute * 60
|
||||
|
||||
def worker() -> None:
|
||||
while not stop_event.is_set():
|
||||
try:
|
||||
limited_tokens = account_service.list_limited_tokens()
|
||||
normal_tokens = account_service.list_normal_tokens()
|
||||
expiring_tokens = account_service.list_expiring_access_tokens()
|
||||
keepalive_tokens = account_service.list_refresh_token_keepalive_tokens()
|
||||
tokens = list(dict.fromkeys([*limited_tokens, *normal_tokens, *expiring_tokens]))
|
||||
expiring_token_set = set(expiring_tokens)
|
||||
keepalive_tokens = [token for token in keepalive_tokens if token not in expiring_token_set]
|
||||
if tokens:
|
||||
print(
|
||||
"[account-watcher] checking "
|
||||
f"{len(limited_tokens)} limited accounts, "
|
||||
f"{len(normal_tokens)} normal accounts, "
|
||||
f"{len(expiring_tokens)} expiring access tokens"
|
||||
)
|
||||
account_service.refresh_accounts(tokens)
|
||||
if keepalive_tokens:
|
||||
print(f"[account-watcher] keepalive {len(keepalive_tokens)} refresh tokens")
|
||||
result = account_service.keepalive_refresh_tokens(keepalive_tokens)
|
||||
if result.get("errors"):
|
||||
print(f"[account-watcher] keepalive errors: {result['errors']}")
|
||||
except Exception as exc:
|
||||
print(f"[account-watcher] fail {exc}")
|
||||
stop_event.wait(interval_seconds)
|
||||
|
||||
thread = Thread(target=worker, name="account-watcher", daemon=True)
|
||||
thread.start()
|
||||
return thread
|
||||
|
||||
|
||||
def resolve_web_asset(requested_path: str) -> Path | None:
|
||||
if not WEB_DIST_DIR.exists():
|
||||
return None
|
||||
clean_path = requested_path.strip("/")
|
||||
base_dir = WEB_DIST_DIR.resolve()
|
||||
candidates = [base_dir / "index.html"] if not clean_path else [
|
||||
base_dir / Path(clean_path),
|
||||
base_dir / clean_path / "index.html",
|
||||
base_dir / f"{clean_path}.html",
|
||||
]
|
||||
for candidate in candidates:
|
||||
try:
|
||||
candidate.resolve().relative_to(base_dir)
|
||||
except ValueError:
|
||||
continue
|
||||
if candidate.is_file():
|
||||
return candidate
|
||||
return None
|
||||
+365
@@ -0,0 +1,365 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from urllib.parse import quote
|
||||
|
||||
from fastapi import APIRouter, Header, HTTPException, Query, Request
|
||||
from fastapi.concurrency import run_in_threadpool
|
||||
from fastapi.responses import HTMLResponse, Response, StreamingResponse
|
||||
from pydantic import BaseModel, ConfigDict
|
||||
|
||||
from api.support import require_admin, require_identity, resolve_image_base_url
|
||||
from services.backup_service import BackupError, backup_service
|
||||
from services.config import config
|
||||
from services.image_service import (
|
||||
compress_images,
|
||||
delete_images,
|
||||
delete_to_target,
|
||||
download_images_zip,
|
||||
get_image_download_response,
|
||||
get_image_response,
|
||||
get_thumbnail_response,
|
||||
list_images,
|
||||
storage_stats,
|
||||
)
|
||||
from services.image_storage_service import ImageStorageError, image_storage_service
|
||||
from services.image_tags_service import delete_tag, get_all_tags, set_tags
|
||||
from services.log_service import log_service
|
||||
from services.proxy_service import proxy_settings, test_clearance, test_proxy
|
||||
|
||||
|
||||
class SettingsUpdateRequest(BaseModel):
|
||||
model_config = ConfigDict(extra="allow")
|
||||
|
||||
|
||||
class ProxyTestRequest(BaseModel):
|
||||
url: str = ""
|
||||
|
||||
|
||||
class ClearanceTestRequest(BaseModel):
|
||||
target_url: str = "https://chatgpt.com"
|
||||
|
||||
|
||||
class ImageDeleteRequest(BaseModel):
|
||||
paths: list[str] = []
|
||||
start_date: str = ""
|
||||
end_date: str = ""
|
||||
all_matching: bool = False
|
||||
|
||||
class ImageDownloadRequest(BaseModel):
|
||||
paths: list[str]
|
||||
|
||||
class ImageTagsRequest(BaseModel):
|
||||
path: str
|
||||
tags: list[str]
|
||||
|
||||
class LogDeleteRequest(BaseModel):
|
||||
ids: list[str] = []
|
||||
class BackupDeleteRequest(BaseModel):
|
||||
key: str = ""
|
||||
|
||||
|
||||
def create_router(app_version: str) -> APIRouter:
|
||||
router = APIRouter()
|
||||
|
||||
@router.post("/auth/login")
|
||||
async def login(authorization: str | None = Header(default=None)):
|
||||
identity = require_identity(authorization)
|
||||
return {
|
||||
"ok": True,
|
||||
"version": app_version,
|
||||
"role": identity.get("role"),
|
||||
"subject_id": identity.get("id"),
|
||||
"name": identity.get("name"),
|
||||
}
|
||||
|
||||
@router.get("/version")
|
||||
async def get_version():
|
||||
return {"version": app_version}
|
||||
|
||||
@router.get("/api/settings")
|
||||
async def get_settings(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {"config": config.get()}
|
||||
|
||||
@router.get("/api/third-party-apps")
|
||||
async def get_third_party_apps(authorization: str | None = Header(default=None)):
|
||||
require_identity(authorization)
|
||||
return {"third_party_apps": config.get_third_party_apps_settings()}
|
||||
|
||||
@router.post("/api/settings")
|
||||
async def save_settings(body: SettingsUpdateRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
try:
|
||||
return {"config": config.update(body.model_dump(mode="python"))}
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.get("/api/images")
|
||||
async def get_images(request: Request, start_date: str = "", end_date: str = "", authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return list_images(resolve_image_base_url(request), start_date=start_date.strip(), end_date=end_date.strip())
|
||||
|
||||
@router.get("/images/{image_path:path}", include_in_schema=False)
|
||||
async def get_image(image_path: str):
|
||||
return get_image_response(image_path)
|
||||
|
||||
@router.get("/image-thumbnails/{image_path:path}", include_in_schema=False)
|
||||
async def get_image_thumbnail(image_path: str):
|
||||
return get_thumbnail_response(image_path)
|
||||
|
||||
@router.post("/api/images/delete")
|
||||
async def delete_images_endpoint(body: ImageDeleteRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return delete_images(body.paths, start_date=body.start_date.strip(), end_date=body.end_date.strip(), all_matching=body.all_matching)
|
||||
|
||||
@router.post("/api/images/download")
|
||||
async def download_images_endpoint(body: ImageDownloadRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
buf = download_images_zip(body.paths)
|
||||
return StreamingResponse(
|
||||
buf,
|
||||
media_type="application/zip",
|
||||
headers={"Content-Disposition": 'attachment; filename="images.zip"'},
|
||||
)
|
||||
|
||||
@router.get("/api/images/download/{image_path:path}")
|
||||
async def download_single_image_endpoint(image_path: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return get_image_download_response(image_path)
|
||||
|
||||
@router.get("/api/logs")
|
||||
async def get_logs(type: str = "", start_date: str = "", end_date: str = "", authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {"items": log_service.list(type=type.strip(), start_date=start_date.strip(), end_date=end_date.strip())}
|
||||
|
||||
@router.post("/api/logs/delete")
|
||||
async def delete_logs(body: LogDeleteRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return log_service.delete(body.ids)
|
||||
|
||||
@router.post("/api/proxy/test")
|
||||
async def test_proxy_endpoint(body: ProxyTestRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {"result": await run_in_threadpool(test_proxy, (body.url or "").strip())}
|
||||
|
||||
@router.get("/api/proxy/runtime")
|
||||
async def get_proxy_runtime_endpoint(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {
|
||||
"runtime": config.get_public_proxy_runtime_settings(),
|
||||
"status": proxy_settings.get_runtime_status(),
|
||||
}
|
||||
|
||||
@router.post("/api/proxy/runtime")
|
||||
async def save_proxy_runtime_endpoint(body: SettingsUpdateRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
try:
|
||||
config.update({"proxy_runtime": body.model_dump(mode="python")})
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
return {
|
||||
"runtime": config.get_public_proxy_runtime_settings(),
|
||||
"status": proxy_settings.get_runtime_status(),
|
||||
}
|
||||
|
||||
@router.post("/api/proxy/clearance/test")
|
||||
async def test_proxy_clearance_endpoint(body: ClearanceTestRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {"result": await run_in_threadpool(test_clearance, body.target_url)}
|
||||
|
||||
@router.get("/api/storage/info")
|
||||
async def get_storage_info(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
storage = config.get_storage_backend()
|
||||
return {
|
||||
"backend": storage.get_backend_info(),
|
||||
"health": storage.health_check(),
|
||||
}
|
||||
|
||||
@router.post("/api/backup/test")
|
||||
async def test_backup_connection(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
try:
|
||||
return {"result": await run_in_threadpool(backup_service.test_connection)}
|
||||
except BackupError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.post("/api/image-storage/test")
|
||||
async def test_image_storage_endpoint(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {"result": await run_in_threadpool(image_storage_service.test_webdav)}
|
||||
|
||||
@router.post("/api/image-storage/sync")
|
||||
async def sync_image_storage_endpoint(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
try:
|
||||
return {"result": await run_in_threadpool(image_storage_service.sync_all)}
|
||||
except ImageStorageError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.get("/api/backups")
|
||||
async def get_backups(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
try:
|
||||
return {
|
||||
"items": await run_in_threadpool(backup_service.list_backups),
|
||||
"state": backup_service.get_status(),
|
||||
"settings": backup_service.get_settings(),
|
||||
}
|
||||
except BackupError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.post("/api/backups/run")
|
||||
async def run_backup_endpoint(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
try:
|
||||
return {"result": await run_in_threadpool(backup_service.run_backup)}
|
||||
except BackupError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.post("/api/backups/delete")
|
||||
async def delete_backup_endpoint(body: BackupDeleteRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
try:
|
||||
await run_in_threadpool(backup_service.delete_backup, body.key)
|
||||
return {"ok": True}
|
||||
except BackupError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.get("/api/backups/detail")
|
||||
async def get_backup_detail(key: str = "", authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
try:
|
||||
return {"item": await run_in_threadpool(backup_service.get_backup_detail, key)}
|
||||
except BackupError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
|
||||
@router.get("/api/backups/download")
|
||||
async def download_backup_endpoint(key: str = "", authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
try:
|
||||
item = await run_in_threadpool(backup_service.download_backup, key)
|
||||
except BackupError as exc:
|
||||
raise HTTPException(status_code=400, detail={"error": str(exc)}) from exc
|
||||
filename = str(item.get("name") or "backup.bin")
|
||||
quoted = quote(filename)
|
||||
headers = {
|
||||
"Content-Disposition": f"attachment; filename*=UTF-8''{quoted}",
|
||||
"Content-Length": str(int(item.get("size") or 0)),
|
||||
}
|
||||
return Response(
|
||||
content=bytes(item.get("payload") or b""),
|
||||
media_type=str(item.get("content_type") or "application/octet-stream"),
|
||||
headers=headers,
|
||||
)
|
||||
|
||||
|
||||
@router.get("/api/images/tags")
|
||||
async def list_image_tags(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return {"tags": get_all_tags()}
|
||||
|
||||
@router.post("/api/images/tags")
|
||||
async def update_image_tags(body: ImageTagsRequest, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
rel = body.path.strip().lstrip("/")
|
||||
if not rel:
|
||||
raise HTTPException(status_code=400, detail={"error": "path is required"})
|
||||
tags = set_tags(rel, body.tags)
|
||||
return {"ok": True, "tags": tags}
|
||||
|
||||
@router.delete("/api/images/tags/{tag}")
|
||||
async def delete_image_tag(tag: str, authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
count = delete_tag(tag)
|
||||
return {"ok": True, "removed_from": count}
|
||||
|
||||
@router.get("/api/images/storage")
|
||||
async def get_image_storage(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return storage_stats()
|
||||
|
||||
@router.post("/api/images/storage/compress")
|
||||
async def compress_all_images(authorization: str | None = Header(default=None)):
|
||||
require_admin(authorization)
|
||||
return await run_in_threadpool(compress_images)
|
||||
|
||||
@router.post("/api/images/storage/cleanup-to-target")
|
||||
async def cleanup_to_target(
|
||||
target_free_mb: int = 500,
|
||||
dry_run: bool = False,
|
||||
authorization: str | None = Header(default=None),
|
||||
):
|
||||
require_admin(authorization)
|
||||
return await run_in_threadpool(delete_to_target, target_free_mb, dry_run)
|
||||
|
||||
@router.get("/health", response_model=None)
|
||||
async def health_dashboard(format: str = Query(default="html")):
|
||||
from services.account_service import account_service as acct_svc
|
||||
stats = acct_svc.get_stats()
|
||||
storage = config.get_storage_backend()
|
||||
storage_health = storage.health_check()
|
||||
healthy = stats["active"] > 0
|
||||
|
||||
stats_json = {
|
||||
"status": "ok" if healthy else "degraded",
|
||||
"healthy": healthy,
|
||||
"version": app_version,
|
||||
"storage": {"backend": storage.get_backend_info(), "health": storage_health},
|
||||
"proxy_runtime": proxy_settings.get_runtime_status(),
|
||||
"accounts": stats,
|
||||
}
|
||||
if format == "json":
|
||||
return stats_json
|
||||
return HTMLResponse(f"""<!DOCTYPE html>
|
||||
<html lang="zh">
|
||||
<head><meta charset="UTF-8"><meta name="viewport" content="width=device-width,initial-scale=1">
|
||||
<title>号池健康监控 - chatgpt2api</title>
|
||||
<style>
|
||||
*{{margin:0;padding:0;box-sizing:border-box}}
|
||||
body{{font-family:system-ui,-apple-system,sans-serif;background:#0f1117;color:#e2e8f0;min-height:100vh}}
|
||||
.header{{background:#1a1d27;border-bottom:1px solid #2a2d3a;padding:16px 24px;display:flex;justify-content:space-between;align-items:center}}
|
||||
.header h1{{font-size:20px}}
|
||||
.status-dot{{display:inline-block;width:10px;height:10px;border-radius:50%;margin-right:8px}}
|
||||
.status-ok{{background:#22c55e;box-shadow:0 0 8px #22c55e88}}
|
||||
.status-degraded{{background:#f59e0b;box-shadow:0 0 8px #f59e0b88}}
|
||||
.container{{max-width:960px;margin:0 auto;padding:24px}}
|
||||
.cards{{display:grid;grid-template-columns:repeat(auto-fit,minmax(140px,1fr));gap:12px;margin-bottom:24px}}
|
||||
.card{{background:#1a1d27;border:1px solid #2a2d3a;border-radius:10px;padding:16px}}
|
||||
.card .value{{font-size:28px;font-weight:700;margin:4px 0}}
|
||||
.card .label{{font-size:13px;color:#94a3b8}}
|
||||
.green{{color:#22c55e}}.yellow{{color:#f59e0b}}.red{{color:#ef4444}}.blue{{color:#6c63ff}}
|
||||
table{{width:100%;border-collapse:collapse;background:#1a1d27;border:1px solid #2a2d3a;border-radius:10px;overflow:hidden}}
|
||||
th{{background:#242836;font-weight:600;text-align:left;padding:10px 12px;font-size:12px;color:#94a3b8;text-transform:uppercase}}
|
||||
td{{padding:8px 12px;border-top:1px solid #2a2d3a;font-size:14px}}tr:hover td{{background:rgba(108,99,255,.05)}}
|
||||
.api-url{{font-family:monospace;font-size:12px;color:#6c63ff}}
|
||||
.refresh{{font-size:12px;color:#64748b;text-align:center;margin-top:24px}}
|
||||
</style>
|
||||
<meta http-equiv="refresh" content="30">
|
||||
</head>
|
||||
<body>
|
||||
<div class="header">
|
||||
<h1><span class="status-dot {'status-ok' if healthy else 'status-degraded'}"></span>号池健康监控</h1>
|
||||
<div style="font-size:13px;color:#94a3b8">v{app_version} · 30s 自动刷新</div>
|
||||
</div>
|
||||
<div class="container">
|
||||
<div class="cards">
|
||||
<div class="card"><div class="label">号池状态</div><div class="value {'green' if healthy else 'yellow'}">{'正常' if healthy else '异常'}</div></div>
|
||||
<div class="card"><div class="label">当前账号</div><div class="value blue">{stats['total']}</div></div>
|
||||
<div class="card"><div class="label">累计入库</div><div class="value">{stats['cumulative_total']}</div></div>
|
||||
<div class="card"><div class="label">可用账号</div><div class="value green">{stats['active']}</div></div>
|
||||
<div class="card"><div class="label">剩余额度</div><div class="value">{stats['total_quota']}</div></div>
|
||||
<div class="card"><div class="label">限流</div><div class="value yellow">{stats['limited']}</div></div>
|
||||
<div class="card"><div class="label">异常</div><div class="value red">{stats['abnormal']}</div></div>
|
||||
<div class="card"><div class="label">禁用</div><div class="value">{stats['disabled']}</div></div>
|
||||
<div class="card"><div class="label">成功/失败</div><div class="value">{stats['total_success']}<span style="font-size:18px;color:#94a3b8">/</span><span class="red">{stats['total_fail']}</span></div></div>
|
||||
</div>
|
||||
<h2 style="margin-bottom:12px;font-size:16px">账号类型分布</h2>
|
||||
<table>
|
||||
<tr><th>类型</th><th>数量</th></tr>
|
||||
{''.join(f'<tr><td>{t}</td><td>{c}</td></tr>' for t,c in sorted(stats['by_type'].items()))}
|
||||
</table>
|
||||
<div class="refresh">JSON: <span class="api-url">/health?format=json</span></div>
|
||||
</div></body></html>""")
|
||||
|
||||
return router
|
||||

File diff suppressed because one or more lines are too long
|
After Width: | Height: | Size: 8.3 KiB |
@@ -0,0 +1,34 @@
|
||||
services:
|
||||
app:
|
||||
build:
|
||||
context: .
|
||||
dockerfile: Dockerfile
|
||||
image: chatgpt2api:local
|
||||
container_name: chatgpt2api-local
|
||||
ports:
|
||||
- "8000:80"
|
||||
volumes:
|
||||
- ./data:/app/data
|
||||
- ./config.json:/app/config.json
|
||||
environment:
|
||||
STORAGE_BACKEND: sqlite
|
||||
DATABASE_URL: sqlite:////app/data/accounts.db
|
||||
# 存储后端配置 (可选值: json, sqlite, postgres, git)
|
||||
# environment:
|
||||
# STORAGE_BACKEND: json
|
||||
|
||||
# 数据库配置 (当 STORAGE_BACKEND=sqlite/postgres 时使用)
|
||||
# DATABASE_URL: postgresql://user:password@host:5432/dbname
|
||||
# DATABASE_URL: sqlite:////app/data/accounts.db
|
||||
|
||||
# Git 仓库配置 (当 STORAGE_BACKEND=git 时使用)
|
||||
# GIT_REPO_URL: https://github.com/user/repo.git
|
||||
# GIT_TOKEN: ghp_xxxxxxxxxxxx
|
||||
# GIT_BRANCH: main
|
||||
# GIT_FILE_PATH: accounts.json
|
||||
|
||||
# 认证密钥 (可选,覆盖 config.json)
|
||||
# CHATGPT2API_AUTH_KEY: your_secret_key
|
||||
|
||||
# 基础 URL (可选)
|
||||
# CHATGPT2API_BASE_URL: https://your-domain.com
|
||||
@@ -0,0 +1,108 @@
|
||||
services:
|
||||
init-config:
|
||||
image: python:3.13-alpine
|
||||
container_name: chatgpt2api-warp-init
|
||||
working_dir: /app
|
||||
volumes:
|
||||
- ./config.json:/app/config.json
|
||||
- ./scripts:/app/scripts:ro
|
||||
environment:
|
||||
CHATGPT2API_CONFIG_FILE: /app/config.json
|
||||
CHATGPT2API_PROXY_RUNTIME_ENABLED: ${CHATGPT2API_PROXY_RUNTIME_ENABLED:-true}
|
||||
CHATGPT2API_PROXY_RUNTIME_EGRESS_MODE: ${CHATGPT2API_PROXY_RUNTIME_EGRESS_MODE:-single_proxy}
|
||||
CHATGPT2API_PROXY_RUNTIME_PROXY_URL: ${CHATGPT2API_PROXY_RUNTIME_PROXY_URL:-http://privoxy:8118}
|
||||
CHATGPT2API_PROXY_RUNTIME_RESOURCE_PROXY_URL: ${CHATGPT2API_PROXY_RUNTIME_RESOURCE_PROXY_URL:-}
|
||||
CHATGPT2API_PROXY_RUNTIME_SKIP_SSL_VERIFY: ${CHATGPT2API_PROXY_RUNTIME_SKIP_SSL_VERIFY:-false}
|
||||
CHATGPT2API_PROXY_RUNTIME_RESET_STATUS_CODES: ${CHATGPT2API_PROXY_RUNTIME_RESET_STATUS_CODES:-403}
|
||||
CHATGPT2API_PROXY_RUNTIME_CLEARANCE_ENABLED: ${CHATGPT2API_PROXY_RUNTIME_CLEARANCE_ENABLED:-true}
|
||||
CHATGPT2API_PROXY_RUNTIME_CLEARANCE_MODE: ${CHATGPT2API_PROXY_RUNTIME_CLEARANCE_MODE:-flaresolverr}
|
||||
CHATGPT2API_PROXY_RUNTIME_CLEARANCE_TIMEOUT_SEC: ${CHATGPT2API_PROXY_RUNTIME_CLEARANCE_TIMEOUT_SEC:-60}
|
||||
CHATGPT2API_PROXY_RUNTIME_CLEARANCE_REFRESH_INTERVAL: ${CHATGPT2API_PROXY_RUNTIME_CLEARANCE_REFRESH_INTERVAL:-3600}
|
||||
CHATGPT2API_PROXY_RUNTIME_WARM_UP_ON_START: ${CHATGPT2API_PROXY_RUNTIME_WARM_UP_ON_START:-false}
|
||||
CHATGPT2API_PROXY_RUNTIME_BROWSER: ${CHATGPT2API_PROXY_RUNTIME_BROWSER:-chrome}
|
||||
CHATGPT2API_PROXY_RUNTIME_USER_AGENT: ${CHATGPT2API_PROXY_RUNTIME_USER_AGENT:-}
|
||||
CHATGPT2API_FLARESOLVERR_URL: ${CHATGPT2API_FLARESOLVERR_URL:-http://flaresolverr:8191}
|
||||
command: ["python3", "/app/scripts/init_proxy_config.py"]
|
||||
restart: "no"
|
||||
|
||||
warp-proxy:
|
||||
image: caomingjun/warp:latest
|
||||
container_name: chatgpt2api-warp-proxy
|
||||
restart: unless-stopped
|
||||
environment:
|
||||
WARP_SLEEP: "2"
|
||||
# 可选:填写 Cloudflare WARP+ License Key
|
||||
# WARP_LICENSE_KEY: ${WARP_LICENSE_KEY:-}
|
||||
cap_add:
|
||||
- NET_ADMIN
|
||||
- SYS_MODULE
|
||||
sysctls:
|
||||
net.ipv6.conf.all.disable_ipv6: 0
|
||||
net.ipv4.conf.all.src_valid_mark: 1
|
||||
ports:
|
||||
- "127.0.0.1:${WARP_SOCKS_PORT:-40000}:1080"
|
||||
healthcheck:
|
||||
test: ["CMD-SHELL", "python3 -c \"import socket; s=socket.create_connection(('127.0.0.1', 1080), 5); s.close()\""]
|
||||
interval: 30s
|
||||
timeout: 5s
|
||||
retries: 5
|
||||
start_period: 30s
|
||||
|
||||
privoxy:
|
||||
image: vimagick/privoxy:latest
|
||||
container_name: chatgpt2api-privoxy
|
||||
restart: unless-stopped
|
||||
depends_on:
|
||||
warp-proxy:
|
||||
condition: service_started
|
||||
volumes:
|
||||
- ./scripts/privoxy-warp.conf:/etc/privoxy/config:ro
|
||||
ports:
|
||||
- "127.0.0.1:${PRIVOXY_PORT:-40080}:8118"
|
||||
healthcheck:
|
||||
test: ["CMD-SHELL", "nc -z 127.0.0.1 8118 || exit 1"]
|
||||
interval: 30s
|
||||
timeout: 5s
|
||||
retries: 5
|
||||
start_period: 10s
|
||||
|
||||
flaresolverr:
|
||||
image: ghcr.io/flaresolverr/flaresolverr:latest
|
||||
container_name: chatgpt2api-flaresolverr
|
||||
restart: unless-stopped
|
||||
environment:
|
||||
LOG_LEVEL: ${FLARESOLVERR_LOG_LEVEL:-info}
|
||||
TZ: ${TZ:-Asia/Shanghai}
|
||||
ports:
|
||||
- "127.0.0.1:${FLARESOLVERR_PORT:-8191}:8191"
|
||||
healthcheck:
|
||||
test: ["CMD-SHELL", "curl -fsS http://127.0.0.1:8191/ >/dev/null"]
|
||||
interval: 30s
|
||||
timeout: 10s
|
||||
retries: 5
|
||||
start_period: 30s
|
||||
|
||||
app:
|
||||
build:
|
||||
context: .
|
||||
dockerfile: Dockerfile
|
||||
image: chatgpt2api:warp
|
||||
container_name: chatgpt2api-warp
|
||||
restart: unless-stopped
|
||||
depends_on:
|
||||
init-config:
|
||||
condition: service_completed_successfully
|
||||
privoxy:
|
||||
condition: service_started
|
||||
flaresolverr:
|
||||
condition: service_started
|
||||
ports:
|
||||
- "${CHATGPT2API_PORT:-3000}:80"
|
||||
volumes:
|
||||
- ./data:/app/data
|
||||
- ./config.json:/app/config.json
|
||||
environment:
|
||||
STORAGE_BACKEND: ${STORAGE_BACKEND:-json}
|
||||
DATABASE_URL: ${DATABASE_URL:-}
|
||||
CHATGPT2API_AUTH_KEY: ${CHATGPT2API_AUTH_KEY:-}
|
||||
CHATGPT2API_BASE_URL: ${CHATGPT2API_BASE_URL:-}
|
||||
@@ -0,0 +1,29 @@
|
||||
services:
|
||||
app:
|
||||
image: ghcr.io/basketikun/chatgpt2api:latest
|
||||
container_name: chatgpt2api
|
||||
restart: unless-stopped
|
||||
ports:
|
||||
- "3000:80"
|
||||
volumes:
|
||||
- ./data:/app/data
|
||||
- ./config.json:/app/config.json
|
||||
environment:
|
||||
# 存储后端配置 (可选值: json, sqlite, postgres, git)
|
||||
- STORAGE_BACKEND=json
|
||||
|
||||
# 数据库配置 (当 STORAGE_BACKEND=sqlite/postgres 时使用)
|
||||
# - DATABASE_URL=postgresql://user:password@host:5432/dbname
|
||||
# - DATABASE_URL=sqlite:///app/data/accounts.db
|
||||
|
||||
# Git 仓库配置 (当 STORAGE_BACKEND=git 时使用)
|
||||
# - GIT_REPO_URL=https://github.com/user/repo.git
|
||||
# - GIT_TOKEN=ghp_xxxxxxxxxxxx
|
||||
# - GIT_BRANCH=main
|
||||
# - GIT_FILE_PATH=accounts.json
|
||||
|
||||
# 认证密钥 (可选,覆盖 config.json)
|
||||
# - CHATGPT2API_AUTH_KEY=your_secret_key
|
||||
|
||||
# 基础 URL (可选)
|
||||
# - CHATGPT2API_BASE_URL=https://your-domain.com
|
||||
@@ -0,0 +1,359 @@
|
||||
# 部署与升级指南
|
||||
|
||||
本文介绍 ChatGPT2API 的常见部署方式,以及后续升级项目时需要保留的数据和执行步骤。
|
||||
|
||||
## 部署前准备
|
||||
|
||||
服务器需要安装:
|
||||
|
||||
- Docker
|
||||
- Docker Compose v2
|
||||
- Git
|
||||
|
||||
首次部署前建议确认:
|
||||
|
||||
```bash
|
||||
docker version
|
||||
docker compose version
|
||||
git --version
|
||||
```
|
||||
|
||||
项目核心持久化文件:
|
||||
|
||||
| 路径 | 作用 |
|
||||
| --- | --- |
|
||||
| `config.json` | 主配置、后台密钥、代理、图片、备份等配置 |
|
||||
| `.env` | Docker compose 环境变量 |
|
||||
| `data/` | 账号、日志、图片、任务记录等运行数据 |
|
||||
|
||||
升级和迁移时重点保留以上内容。
|
||||
|
||||
## 方式一:普通 Docker 部署
|
||||
|
||||
适合不需要 WARP / FlareSolverr 清障的场景。
|
||||
|
||||
```bash
|
||||
git clone git@github.com:basketikun/chatgpt2api.git
|
||||
cd chatgpt2api
|
||||
```
|
||||
|
||||
设置 `config.json` 中的 `auth-key`,或在 `docker-compose.yml` 中配置:
|
||||
|
||||
```yaml
|
||||
environment:
|
||||
- CHATGPT2API_AUTH_KEY=your_secret_key
|
||||
```
|
||||
|
||||
启动:
|
||||
|
||||
```bash
|
||||
docker compose up -d
|
||||
```
|
||||
|
||||
访问:
|
||||
|
||||
```text
|
||||
http://localhost:3000
|
||||
```
|
||||
|
||||
API 基础地址:
|
||||
|
||||
```text
|
||||
http://localhost:3000/v1
|
||||
```
|
||||
|
||||
查看日志:
|
||||
|
||||
```bash
|
||||
docker logs -f chatgpt2api
|
||||
```
|
||||
|
||||
停止:
|
||||
|
||||
```bash
|
||||
docker compose down
|
||||
```
|
||||
|
||||
## 方式二:WARP / FlareSolverr 部署
|
||||
|
||||
适合上游请求经常遇到 Cloudflare 拦截的场景。该方式会启动:
|
||||
|
||||
- `warp-proxy`
|
||||
- `privoxy`
|
||||
- `flaresolverr`
|
||||
- `init-config`
|
||||
- `app`
|
||||
|
||||
复制环境变量模板:
|
||||
|
||||
```bash
|
||||
cp .env.example .env
|
||||
```
|
||||
|
||||
至少修改 `.env` 中的:
|
||||
|
||||
```text
|
||||
CHATGPT2API_AUTH_KEY=your_secret_key_here
|
||||
```
|
||||
|
||||
启动:
|
||||
|
||||
```bash
|
||||
docker compose -f docker-compose.warp.yml up -d --build
|
||||
```
|
||||
|
||||
访问:
|
||||
|
||||
```text
|
||||
http://localhost:3000
|
||||
```
|
||||
|
||||
FlareSolverr 相关配置可以在后台设置页的 `FlareSolverr` tab 中查看和测试。
|
||||
|
||||
查看容器状态:
|
||||
|
||||
```bash
|
||||
docker compose -f docker-compose.warp.yml ps
|
||||
```
|
||||
|
||||
查看日志:
|
||||
|
||||
```bash
|
||||
docker logs -f chatgpt2api-warp
|
||||
docker logs -f chatgpt2api-flaresolverr
|
||||
```
|
||||
|
||||
停止:
|
||||
|
||||
```bash
|
||||
docker compose -f docker-compose.warp.yml down
|
||||
```
|
||||
|
||||
## 方式三:源码运行
|
||||
|
||||
适合本地开发或临时调试。
|
||||
|
||||
后端:
|
||||
|
||||
```bash
|
||||
git clone git@github.com:basketikun/chatgpt2api.git
|
||||
cd chatgpt2api
|
||||
uv sync
|
||||
uv run main.py
|
||||
```
|
||||
|
||||
前端开发服务:
|
||||
|
||||
```bash
|
||||
cd web
|
||||
bun install
|
||||
bun run dev
|
||||
```
|
||||
|
||||
源码方式运行时,后端默认读取项目根目录的 `config.json` 和 `data/`。
|
||||
|
||||
## 存储后端
|
||||
|
||||
默认使用本地 JSON 文件:
|
||||
|
||||
```text
|
||||
STORAGE_BACKEND=json
|
||||
```
|
||||
|
||||
可选值:
|
||||
|
||||
| 值 | 说明 |
|
||||
| --- | --- |
|
||||
| `json` | 本地 JSON 文件,默认方式 |
|
||||
| `sqlite` | 本地 SQLite,通常存放在 `data/accounts.db` |
|
||||
| `postgres` | 外部 PostgreSQL |
|
||||
| `git` | Git 私有仓库存储账号数据 |
|
||||
|
||||
PostgreSQL 示例:
|
||||
|
||||
```yaml
|
||||
environment:
|
||||
- STORAGE_BACKEND=postgres
|
||||
- DATABASE_URL=postgresql://user:password@host:5432/dbname
|
||||
```
|
||||
|
||||
SQLite 示例:
|
||||
|
||||
```yaml
|
||||
environment:
|
||||
- STORAGE_BACKEND=sqlite
|
||||
- DATABASE_URL=sqlite:////app/data/accounts.db
|
||||
```
|
||||
|
||||
## 升级前备份
|
||||
|
||||
升级前建议备份:
|
||||
|
||||
```bash
|
||||
mkdir -p backups
|
||||
tar -czf backups/chatgpt2api-$(date +%Y%m%d-%H%M%S).tgz config.json .env data
|
||||
```
|
||||
|
||||
如果没有 `.env`,可以去掉:
|
||||
|
||||
```bash
|
||||
tar -czf backups/chatgpt2api-$(date +%Y%m%d-%H%M%S).tgz config.json data
|
||||
```
|
||||
|
||||
也可以在后台设置页配置 Cloudflare R2 备份,用于定时备份关键数据。
|
||||
|
||||
## 升级:普通 Docker 部署
|
||||
|
||||
进入项目目录:
|
||||
|
||||
```bash
|
||||
cd chatgpt2api
|
||||
```
|
||||
|
||||
备份:
|
||||
|
||||
```bash
|
||||
mkdir -p backups
|
||||
tar -czf backups/chatgpt2api-$(date +%Y%m%d-%H%M%S).tgz config.json .env data
|
||||
```
|
||||
|
||||
拉取最新代码和镜像:
|
||||
|
||||
```bash
|
||||
git pull
|
||||
docker compose pull
|
||||
docker compose up -d
|
||||
```
|
||||
|
||||
查看状态:
|
||||
|
||||
```bash
|
||||
docker compose ps
|
||||
docker logs -f chatgpt2api
|
||||
```
|
||||
|
||||
## 升级:WARP / FlareSolverr 部署
|
||||
|
||||
进入项目目录:
|
||||
|
||||
```bash
|
||||
cd chatgpt2api
|
||||
```
|
||||
|
||||
备份:
|
||||
|
||||
```bash
|
||||
mkdir -p backups
|
||||
tar -czf backups/chatgpt2api-$(date +%Y%m%d-%H%M%S).tgz config.json .env data
|
||||
```
|
||||
|
||||
拉取最新代码并重新构建:
|
||||
|
||||
```bash
|
||||
git pull
|
||||
docker compose -f docker-compose.warp.yml up -d --build
|
||||
```
|
||||
|
||||
查看状态:
|
||||
|
||||
```bash
|
||||
docker compose -f docker-compose.warp.yml ps
|
||||
docker logs -f chatgpt2api-warp
|
||||
```
|
||||
|
||||
## 升级:源码运行
|
||||
|
||||
```bash
|
||||
cd chatgpt2api
|
||||
git pull
|
||||
uv sync
|
||||
```
|
||||
|
||||
如果需要重新构建前端静态产物:
|
||||
|
||||
```bash
|
||||
cd web
|
||||
bun install
|
||||
bun run build
|
||||
```
|
||||
|
||||
然后按你的进程管理方式重启后端服务。
|
||||
|
||||
## 回滚
|
||||
|
||||
如果升级后需要回滚代码:
|
||||
|
||||
```bash
|
||||
git log --oneline -n 20
|
||||
git checkout <旧版本commit>
|
||||
```
|
||||
|
||||
普通 Docker 部署:
|
||||
|
||||
```bash
|
||||
docker compose up -d
|
||||
```
|
||||
|
||||
WARP / FlareSolverr 部署:
|
||||
|
||||
```bash
|
||||
docker compose -f docker-compose.warp.yml up -d --build
|
||||
```
|
||||
|
||||
如果需要恢复数据:
|
||||
|
||||
```bash
|
||||
tar -xzf backups/你的备份文件.tgz
|
||||
```
|
||||
|
||||
恢复数据前建议先停止容器,避免运行中写入覆盖:
|
||||
|
||||
```bash
|
||||
docker compose down
|
||||
```
|
||||
|
||||
或:
|
||||
|
||||
```bash
|
||||
docker compose -f docker-compose.warp.yml down
|
||||
```
|
||||
|
||||
## 常用维护命令
|
||||
|
||||
查看容器:
|
||||
|
||||
```bash
|
||||
docker compose ps
|
||||
```
|
||||
|
||||
查看主服务日志:
|
||||
|
||||
```bash
|
||||
docker logs -f chatgpt2api
|
||||
```
|
||||
|
||||
查看 WARP 部署主服务日志:
|
||||
|
||||
```bash
|
||||
docker logs -f chatgpt2api-warp
|
||||
```
|
||||
|
||||
重启普通部署:
|
||||
|
||||
```bash
|
||||
docker compose restart
|
||||
```
|
||||
|
||||
重启 WARP 部署:
|
||||
|
||||
```bash
|
||||
docker compose -f docker-compose.warp.yml restart
|
||||
```
|
||||
|
||||
清理未使用镜像:
|
||||
|
||||
```bash
|
||||
docker image prune
|
||||
```
|
||||
|
||||
不要直接删除 `data/`、`config.json`、`.env`,除非已经确认有可用备份。
|
||||
@@ -0,0 +1,45 @@
|
||||
# 功能状态
|
||||
|
||||
本文基于当前仓库当前实现整理,用于帮助用户快速了解哪些功能已经可用、哪些仍在完善、哪些待实现。
|
||||
|
||||
| 功能 | 状态 | 说明 |
|
||||
|:----------------------------------------|:--:|:--------------------------------------------------------------|
|
||||
| OpenAI 兼容 `POST /v1/images/generations` | ✅ | 已支持,用于图片生成,并可通过 `n` 返回多张图片。 |
|
||||
| OpenAI 兼容 `POST /v1/images/edits` | ✅ | 已支持,可上传图片进行编辑。 |
|
||||
| 面向图片工作流的 `POST /v1/chat/completions` | ✅ | 已支持图片相关请求。 |
|
||||
| 面向图片工作流的 `POST /v1/responses` | ✅ | 已支持图片生成工具调用。 |
|
||||
| `GET /v1/models` 接口 | ✅ | 当前返回 `gpt-image-2`、`codex-gpt-image-2`、`auto`、`gpt-5`、`gpt-5-1`、`gpt-5-2`、`gpt-5-3`、`gpt-5-3-mini`、`gpt-5-mini`。 |
|
||||
| 同时生成多张图片 | ✅ | 已支持,后端与前端都可进行多图生成。 |
|
||||
| 图片并行生成 | ✅ | 多张图片使用独立线程和账号同时生成,可通过 `image_parallel_generation` 配置关闭。 |
|
||||
| 图片生成进度追踪 | ✅ | 任务显示当前步骤(上传/预热/获取token/生成中等),支持耗时统计。 |
|
||||
| 图片超时续轮询 | ✅ | 超时任务可继续等待,前端显示"继续等待"按钮,后端 resume-poll API。 |
|
||||
| 图片二次确认与先check再hit | ✅ | 可通过 `image_settle_enabled` 和 `image_check_before_hit_enabled` 配置,关闭后跳过等待直接返回。 |
|
||||
| 前端图片工作台 | ✅ | 已支持图片生成、图片编辑、模型选择、历史记录与查看大图。 |
|
||||
| 前端图片懒加载与滚动优化 | ✅ | LazyImage 懒加载、会话切换滚动位置保存与恢复、bfcache 页面恢复同步。 |
|
||||
| 前端图片输入 / 参考图交互 | ✅ | 已支持参考图上传、预览、移除和编辑模式工作流。 |
|
||||
| Codex 画图接口逆向 | ✅ | 已支持,仅 `Plus` / `Team` / `Pro` 订阅可用,模型别名为 `codex-gpt-image-2`;如有需要可自行在其他场景映射回 `gpt-image-2`。这是 Codex 逆向链路,用于和官网画图区分,同一账号通常会同时支持官网和 Codex 两份生图额度。 |
|
||||
| Cherry Studio 接入 | ✅ | 已支持作为绘图接口接入 Cherry Studio。 |
|
||||
| New API 接入 | ✅ | 已支持接入 New API。 |
|
||||
| 账号池管理 | ✅ | 已支持列表、筛选、批量操作、导出、手动编辑、刷新和删除。 |
|
||||
| 手动账号状态保护 | ✅ | 手动设置“禁用”或“限流”后,账号刷新、令牌轮换和生图结束不会覆盖状态,也不会自动清理该账号;手动改回“正常”可恢复自动状态管理。旧数据中的“禁用”自动保留,旧“限流”因无法判断来源,需要重新手动保存一次。 |
|
||||
| 账号刷新异步进度追踪 | ✅ | 刷新和重新登录改为异步模式,前端轮询显示进度。 |
|
||||
| 密码重新登录恢复异常账号 | ✅ | 号池管理页面支持重新登录,刷新后可自动重登异常账号。 |
|
||||
| 账号额度刷新与恢复时间同步 | ✅ | 已支持账号信息刷新,限流账号也会自动继续检查。 |
|
||||
| 失效 Token 自动清理 | ✅ | 已支持自动移除失效 Token。 |
|
||||
| CPA 连接管理 | ✅ | 已支持 CPA 连接的新增、修改、查询和删除。 |
|
||||
| CPA 文件浏览与按需导入 | ✅ | 已支持读取远程文件列表、筛选、勾选并导入到本地号池。 |
|
||||
| CPA 导入进度跟踪 | ✅ | 已支持导入进度展示与轮询更新。 |
|
||||
| `sub2api` 连接管理与账号浏览 | ✅ | 已支持 `sub2api` 服务器的新增、修改、删除、分组查询和 OpenAI OAuth 账号列表读取。 |
|
||||
| `sub2api` 导入 | ✅ | 已支持勾选 `sub2api` 中的 OpenAI OAuth 账号,批量拉取 `access_token` 导入本地号池,并展示导入进度。 |
|
||||
| Docker 自托管部署 | ✅ | 已支持 Docker Compose 部署,并提供多架构镜像。 |
|
||||
| 兼容接口中的多参考图能力 | ✅ | 已实现,支持在兼容接口中传入多参考图。 |
|
||||
| 更高级的 Token 调度策略 | ⚠️ | 当前已有基础轮询与限流刷新机制,更复杂的调度策略仍在完善中。 |
|
||||
| Render / Vercel 等部署表述 | ⚠️ | 当前主要以 Docker 部署为主,其他平台部署方式暂未重点说明。 |
|
||||
| `/v1/complete` 文本补全与流式输出 | ✅ | 已实现。 |
|
||||
| 流式输出支持 | ✅ | 已实现。 |
|
||||
| 文本补全缓存与重复请求合并 | ✅ | `/v1/chat/completions` 文本链路默认启用 60 秒短缓存、流式结果回放、in-flight 请求合并和相邻重复消息清理;可通过 `chat_completion_cache` 配置关闭或调整。 |
|
||||
| 图片尺寸参数 | ❌ | 待实现。 |
|
||||
| 服务端图片 URL 缓存 | ✅ | 已实现。 |
|
||||
| `rt_token` 刷新 | ❌ | 待实现。 |
|
||||
| 代理配置功能 | ✅ | 已支持网页端配置全局 HTTP / HTTPS / SOCKS5 / SOCKS5H 代理,并应用到出站请求。 |
|
||||
| Anthropic 协议支持 | ❌ | 待实现。 |
|
||||
@@ -0,0 +1,271 @@
|
||||
# 上游 Conversation SSE 协议说明
|
||||
|
||||
Conversation SSE 是上游对话链路的流式返回协议。每条 SSE `data:` 通常是一段 JSON payload,也可能是协议标记或结束标记。客户端需要按顺序消费这些 payload,维护当前会话状态、文本内容、工具调用状态和图片结果指针。
|
||||
|
||||
## 基本形态
|
||||
|
||||
常见 payload 示例:
|
||||
|
||||
```text
|
||||
"v1"
|
||||
{"type":"resume_conversation_token",...}
|
||||
{"p":"","o":"add","v":{...}}
|
||||
{"v":{...}}
|
||||
{"p":"/message/content/parts/0","o":"append","v":"..."}
|
||||
{"type":"server_ste_metadata","metadata":{...}}
|
||||
[DONE]
|
||||
```
|
||||
|
||||
处理建议:
|
||||
|
||||
| payload | 含义 | 处理方式 |
|
||||
|:--|:--|:--|
|
||||
| `"v1"` | 协议版本标记 | 可记录,通常不影响业务 |
|
||||
| `[DONE]` | 当前 SSE 流结束 | 停止继续读取 |
|
||||
| JSON object | 事件、消息或 patch | 按字段更新会话状态 |
|
||||
| JSON string | 短文本 patch 或协议标记 | 结合上下文处理 |
|
||||
| 非 JSON 内容 | 原始内容 | 保留为 raw 事件,避免中断流 |
|
||||
|
||||
## 常用字段
|
||||
|
||||
| 字段 | 说明 |
|
||||
|:--|:--|
|
||||
| `type` | 上游事件类型,如 `resume_conversation_token`、`input_message`、`message_marker`、`title_generation`、`server_ste_metadata` |
|
||||
| `conversation_id` | 当前会话 ID,可从多个事件中获得 |
|
||||
| `p` | patch 路径,例如 `/message/content/parts/0` |
|
||||
| `o` | patch 操作,例如 `add`、`append`、`replace`、`patch` |
|
||||
| `v` | patch 值,可能是字符串、数组,也可能包含完整 message |
|
||||
| `c` | 消息序号或游标,常见于 add 类事件 |
|
||||
| `message.id` | 消息 ID |
|
||||
| `message.author.role` | 消息角色,常见 `system`、`user`、`assistant`、`tool` |
|
||||
| `message.content.content_type` | 内容类型,如 `text`、`multimodal_text`、`model_editable_context` |
|
||||
| `message.content.parts` | 内容片段,可能包含文本、图片指针或多模态对象 |
|
||||
| `message.status` | 消息状态,如 `in_progress`、`finished_successfully` |
|
||||
| `message.end_turn` | 是否结束当前轮次 |
|
||||
| `metadata.tool_invoked` | 本轮是否调用工具 |
|
||||
| `metadata.turn_use_case` | 本轮用途,如 `text`、`multimodal` |
|
||||
| `metadata.async_task_type` | 异步工具任务类型,图片生成通常为 `image_gen` |
|
||||
|
||||
## 会话启动事件
|
||||
|
||||
上游通常会先返回恢复令牌或会话令牌:
|
||||
|
||||
```json
|
||||
{
|
||||
"type": "resume_conversation_token",
|
||||
"kind": "topic",
|
||||
"token": "...",
|
||||
"conversation_id": "..."
|
||||
}
|
||||
```
|
||||
|
||||
这个事件主要用于标识会话和恢复上下文。业务层通常只需要保存 `conversation_id`,`token` 不应该暴露给下游用户。
|
||||
|
||||
## 消息 add 场景
|
||||
|
||||
完整消息可能通过 `add` 或带 `v.message` 的事件出现:
|
||||
|
||||
```json
|
||||
{
|
||||
"p": "",
|
||||
"o": "add",
|
||||
"v": {
|
||||
"message": {
|
||||
"author": {"role": "assistant"},
|
||||
"content": {"content_type": "text", "parts": [""]},
|
||||
"status": "in_progress"
|
||||
},
|
||||
"conversation_id": "..."
|
||||
},
|
||||
"c": 3
|
||||
}
|
||||
```
|
||||
|
||||
此类事件常用于创建一条新消息。若消息角色为 `assistant`,后续文本通常会通过 patch 继续追加。
|
||||
|
||||
## 文本增量场景
|
||||
|
||||
文本输出通常由多条 patch 组成:
|
||||
|
||||
```json
|
||||
{"p":"/message/content/parts/0","o":"append","v":"Hello"}
|
||||
{"v":" world"}
|
||||
{"p":"","o":"patch","v":[
|
||||
{"p":"/message/content/parts/0","o":"append","v":"!"},
|
||||
{"p":"/message/status","o":"replace","v":"finished_successfully"},
|
||||
{"p":"/message/end_turn","o":"replace","v":true}
|
||||
]}
|
||||
```
|
||||
|
||||
处理要点:
|
||||
|
||||
| 形态 | 含义 |
|
||||
|:--|:--|
|
||||
| `p == "/message/content/parts/0"` 且 `o == "append"` | 向当前文本追加内容 |
|
||||
| `o == "replace"` | 用新值替换目标字段 |
|
||||
| `o == "patch"` 且 `v` 是数组 | 批量 patch,需要按数组顺序处理 |
|
||||
| 只有 `v` 且 `v` 是字符串 | 可能是省略路径的文本增量,应结合当前文本流处理 |
|
||||
|
||||
## 输入消息场景
|
||||
|
||||
用户输入会以 `input_message` 或普通 `user` message 出现。图片编辑请求会包含用户上传的参考图:
|
||||
|
||||
```json
|
||||
{
|
||||
"type": "input_message",
|
||||
"input_message": {
|
||||
"author": {"role": "user"},
|
||||
"content": {
|
||||
"content_type": "multimodal_text",
|
||||
"parts": [
|
||||
{"asset_pointer": "sediment://file_input"},
|
||||
"编辑提示词"
|
||||
]
|
||||
}
|
||||
},
|
||||
"conversation_id": "..."
|
||||
}
|
||||
```
|
||||
|
||||
这类 `sediment://...` 表示输入附件,不是生成结果。即使它可以被下载,也不能当作输出图片返回。
|
||||
|
||||
## 图片工具成功场景
|
||||
|
||||
图片生成或图片编辑成功时,上游一般会出现工具消息:
|
||||
|
||||
```json
|
||||
{
|
||||
"v": {
|
||||
"message": {
|
||||
"author": {"role": "tool"},
|
||||
"content": {
|
||||
"content_type": "multimodal_text",
|
||||
"parts": [
|
||||
{"asset_pointer": "file-service://file_result"},
|
||||
{"asset_pointer": "sediment://file_result"}
|
||||
]
|
||||
},
|
||||
"metadata": {"async_task_type": "image_gen"}
|
||||
}
|
||||
},
|
||||
"conversation_id": "..."
|
||||
}
|
||||
```
|
||||
|
||||
只有同时满足以下条件的图片指针,才应该视为输出结果:
|
||||
|
||||
| 条件 | 说明 |
|
||||
|:--|:--|
|
||||
| `message.author.role == "tool"` | 来源是工具消息 |
|
||||
| `metadata.async_task_type == "image_gen"` | 工具任务是图片生成 |
|
||||
| `asset_pointer` 为 `file-service://...` 或 `sediment://...` | 指向可解析图片资源 |
|
||||
|
||||
## 图片指针类型
|
||||
|
||||
| 指针 | 常见来源 | 说明 |
|
||||
|:--|:--|:--|
|
||||
| `file-service://file_xxx` | 图片工具输出 | 可通过文件下载接口解析 |
|
||||
| `sediment://file_xxx` | 输入附件或图片工具输出 | 需要结合消息角色判断来源 |
|
||||
| `file_upload` | 上传过程占位 | 通常不应作为输出 |
|
||||
|
||||
不要只凭字符串里出现 `file_` 或 `sediment://` 就判定为输出图。必须结合消息角色和任务类型。
|
||||
|
||||
## 策略拒绝场景
|
||||
|
||||
当上游拒绝请求时,通常不会产生图片工具消息,而是返回普通 assistant 文本:
|
||||
|
||||
```text
|
||||
I can't assist with that request. If you have another type of modification...
|
||||
```
|
||||
|
||||
常见伴随事件:
|
||||
|
||||
```json
|
||||
{"type":"title_generation","title":"Request Denied","conversation_id":"..."}
|
||||
```
|
||||
|
||||
```json
|
||||
{
|
||||
"type": "server_ste_metadata",
|
||||
"metadata": {
|
||||
"tool_invoked": false,
|
||||
"turn_use_case": "multimodal",
|
||||
"did_prompt_contain_image": true
|
||||
},
|
||||
"conversation_id": "..."
|
||||
}
|
||||
```
|
||||
|
||||
处理要点:
|
||||
|
||||
| 条件 | 行为 |
|
||||
|:--|:--|
|
||||
| 有 assistant 拒绝文本 | 应返回文本消息 |
|
||||
| `tool_invoked == false` | 说明没有实际工具结果 |
|
||||
| 没有 `role=tool` 且 `async_task_type=image_gen` 的消息 | 不应收集输出图片 |
|
||||
| 用户输入消息里有图片指针 | 仍然只视为输入附件 |
|
||||
|
||||
## moderation 场景
|
||||
|
||||
部分请求可能返回 moderation 事件:
|
||||
|
||||
```json
|
||||
{
|
||||
"type": "moderation",
|
||||
"moderation_response": {
|
||||
"blocked": true
|
||||
},
|
||||
"conversation_id": "..."
|
||||
}
|
||||
```
|
||||
|
||||
若 `blocked == true`,应认为本轮被策略拦截。后续如有 assistant 文本,应优先返回该文本;若没有文本,可返回合适的错误信息。
|
||||
|
||||
## marker 和 title 事件
|
||||
|
||||
上游会返回一些辅助事件:
|
||||
|
||||
```json
|
||||
{"type":"message_marker","marker":"user_visible_token","event":"first"}
|
||||
{"type":"message_marker","marker":"last_token","event":"last"}
|
||||
{"type":"title_generation","title":"...","conversation_id":"..."}
|
||||
```
|
||||
|
||||
这些事件通常用于前端展示、标题生成或流式状态标记,不代表实际文本内容或图片结果。
|
||||
|
||||
## metadata 事件
|
||||
|
||||
`server_ste_metadata` 用于描述本轮调度和工具状态:
|
||||
|
||||
```json
|
||||
{
|
||||
"type": "server_ste_metadata",
|
||||
"metadata": {
|
||||
"tool_invoked": true,
|
||||
"turn_use_case": "multimodal",
|
||||
"model_slug": "i-mini-m",
|
||||
"did_prompt_contain_image": true
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
常用判断:
|
||||
|
||||
| 字段 | 说明 |
|
||||
|:--|:--|
|
||||
| `tool_invoked == true` | 上游认为本轮调用过工具 |
|
||||
| `tool_invoked == false` | 上游未调用工具,常见于拒绝或纯文本响应 |
|
||||
| `turn_use_case == "text"` | 按文本响应处理 |
|
||||
| `turn_use_case == "multimodal"` | 多模态请求,不代表一定有图片输出 |
|
||||
| `did_prompt_contain_image == true` | 输入包含图片,不代表输出包含图片 |
|
||||
|
||||
## 结束后的结果判断
|
||||
|
||||
SSE 结束后可按以下顺序判断结果:
|
||||
|
||||
1. 如果已经收集到图片工具输出指针,解析并下载输出图片。
|
||||
2. 如果没有输出图片指针,但有 assistant 文本,并且本轮被拦截或未调用工具,返回文本消息。
|
||||
3. 如果没有输出图片指针,但有 `conversation_id`,可查询完整会话明细,继续寻找图片工具输出。
|
||||
4. 查询完整会话时,仍然只读取 `role=tool` 且 `async_task_type=image_gen` 的消息。
|
||||
5. 如果没有图片结果也没有文本,返回上游异常或空结果错误。
|
||||
|
||||
@@ -0,0 +1,9 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import uvicorn
|
||||
from api import create_app
|
||||
|
||||
app = create_app()
|
||||
|
||||
if __name__ == "__main__":
|
||||
uvicorn.run(app, access_log=False, log_level="info")
|
||||
@@ -0,0 +1,27 @@
|
||||
[project]
|
||||
name = "chatgpt2api"
|
||||
version = "0.1.0"
|
||||
description = "Add your description here"
|
||||
readme = "README.md"
|
||||
requires-python = ">=3.13"
|
||||
dependencies = [
|
||||
"curl-cffi>=0.15.0",
|
||||
"fastapi>=0.136.0",
|
||||
"pillow>=12.2.0",
|
||||
"pybase64>=1.4.3",
|
||||
"python-multipart>=0.0.26",
|
||||
"tiktoken>=0.12.0",
|
||||
"uvicorn>=0.44.0",
|
||||
"sqlalchemy>=2.0.0",
|
||||
"psycopg2-binary>=2.9.0",
|
||||
"gitpython>=3.1.0",
|
||||
]
|
||||
|
||||
[dependency-groups]
|
||||
dev = [
|
||||
"httpx>=0.28.1",
|
||||
]
|
||||
|
||||
[[tool.uv.index]]
|
||||
url = "https://mirrors.aliyun.com/pypi/simple"
|
||||
default = true
|
||||
@@ -0,0 +1,186 @@
|
||||
#!/usr/bin/env python3
|
||||
"""Idempotently merge WARP/FlareSolverr proxy_runtime defaults into config.json."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import copy
|
||||
import json
|
||||
import os
|
||||
import re
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
DEFAULT_USER_AGENT = (
|
||||
"Mozilla/5.0 (Windows NT 10.0; Win64; x64) "
|
||||
"AppleWebKit/537.36 (KHTML, like Gecko) "
|
||||
"Chrome/145.0.0.0 Safari/537.36"
|
||||
)
|
||||
|
||||
DEFAULT_PROXY_RUNTIME: dict[str, Any] = {
|
||||
"enabled": False,
|
||||
"egress_mode": "direct",
|
||||
"proxy_url": "",
|
||||
"resource_proxy_url": "",
|
||||
"skip_ssl_verify": False,
|
||||
"reset_session_status_codes": [403],
|
||||
"clearance": {
|
||||
"enabled": False,
|
||||
"mode": "none",
|
||||
"cf_cookies": "",
|
||||
"cf_clearance": "",
|
||||
"user_agent": DEFAULT_USER_AGENT,
|
||||
"browser": "chrome",
|
||||
"flaresolverr_url": "",
|
||||
"timeout_sec": 60,
|
||||
"refresh_interval": 3600,
|
||||
"warm_up_on_start": False,
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def _env_bool(name: str, default: bool) -> bool:
|
||||
value = os.getenv(name)
|
||||
if value is None:
|
||||
return default
|
||||
lowered = value.strip().lower()
|
||||
if lowered in {"1", "true", "yes", "on"}:
|
||||
return True
|
||||
if lowered in {"0", "false", "no", "off"}:
|
||||
return False
|
||||
return default
|
||||
|
||||
|
||||
def _env_int(name: str, default: int, minimum: int = 0) -> int:
|
||||
try:
|
||||
return max(minimum, int(os.getenv(name, str(default))))
|
||||
except (TypeError, ValueError, OverflowError):
|
||||
return default
|
||||
|
||||
|
||||
def _warp_runtime_defaults() -> dict[str, Any]:
|
||||
clearance_enabled = _env_bool("CHATGPT2API_PROXY_RUNTIME_CLEARANCE_ENABLED", True)
|
||||
clearance_mode = os.getenv("CHATGPT2API_PROXY_RUNTIME_CLEARANCE_MODE", "flaresolverr").strip().lower()
|
||||
if clearance_mode not in {"none", "manual", "flaresolverr"}:
|
||||
clearance_mode = "flaresolverr" if clearance_enabled else "none"
|
||||
if not clearance_enabled:
|
||||
clearance_mode = "none"
|
||||
|
||||
egress_mode = os.getenv("CHATGPT2API_PROXY_RUNTIME_EGRESS_MODE", "single_proxy").strip().lower()
|
||||
if egress_mode not in {"direct", "single_proxy"}:
|
||||
egress_mode = "single_proxy"
|
||||
|
||||
runtime = copy.deepcopy(DEFAULT_PROXY_RUNTIME)
|
||||
runtime.update(
|
||||
{
|
||||
"enabled": _env_bool("CHATGPT2API_PROXY_RUNTIME_ENABLED", True),
|
||||
"egress_mode": egress_mode,
|
||||
"proxy_url": os.getenv("CHATGPT2API_PROXY_RUNTIME_PROXY_URL", "http://privoxy:8118").strip(),
|
||||
"resource_proxy_url": os.getenv("CHATGPT2API_PROXY_RUNTIME_RESOURCE_PROXY_URL", "").strip(),
|
||||
"skip_ssl_verify": _env_bool("CHATGPT2API_PROXY_RUNTIME_SKIP_SSL_VERIFY", False),
|
||||
"reset_session_status_codes": [
|
||||
int(part.strip())
|
||||
for part in os.getenv("CHATGPT2API_PROXY_RUNTIME_RESET_STATUS_CODES", "403").split(",")
|
||||
if part.strip().isdigit() and 100 <= int(part.strip()) <= 599
|
||||
] or [403],
|
||||
}
|
||||
)
|
||||
runtime["clearance"].update(
|
||||
{
|
||||
"enabled": clearance_enabled,
|
||||
"mode": clearance_mode,
|
||||
"user_agent": os.getenv("CHATGPT2API_PROXY_RUNTIME_USER_AGENT", DEFAULT_USER_AGENT).strip() or DEFAULT_USER_AGENT,
|
||||
"browser": os.getenv("CHATGPT2API_PROXY_RUNTIME_BROWSER", "chrome").strip() or "chrome",
|
||||
"flaresolverr_url": os.getenv("CHATGPT2API_FLARESOLVERR_URL", "http://flaresolverr:8191").strip(),
|
||||
"timeout_sec": _env_int("CHATGPT2API_PROXY_RUNTIME_CLEARANCE_TIMEOUT_SEC", 60, 1),
|
||||
"refresh_interval": _env_int("CHATGPT2API_PROXY_RUNTIME_CLEARANCE_REFRESH_INTERVAL", 3600, 60),
|
||||
"warm_up_on_start": _env_bool("CHATGPT2API_PROXY_RUNTIME_WARM_UP_ON_START", False),
|
||||
}
|
||||
)
|
||||
return runtime
|
||||
|
||||
|
||||
def _deep_fill_missing(target: dict[str, Any], defaults: dict[str, Any]) -> bool:
|
||||
changed = False
|
||||
for key, value in defaults.items():
|
||||
if key not in target:
|
||||
target[key] = copy.deepcopy(value)
|
||||
changed = True
|
||||
continue
|
||||
if isinstance(target[key], dict) and isinstance(value, dict):
|
||||
changed = _deep_fill_missing(target[key], value) or changed
|
||||
return changed
|
||||
|
||||
|
||||
def _looks_like_repository_default(runtime: Any) -> bool:
|
||||
if not isinstance(runtime, dict):
|
||||
return True
|
||||
candidate = copy.deepcopy(runtime)
|
||||
_deep_fill_missing(candidate, DEFAULT_PROXY_RUNTIME)
|
||||
return candidate == DEFAULT_PROXY_RUNTIME
|
||||
|
||||
|
||||
def _mask_url(value: str) -> str:
|
||||
return re.sub(r"(https?://)([^\s/@:]+):([^\s/@]+)@", r"\1[REDACTED]@", value or "", flags=re.I)
|
||||
|
||||
|
||||
def main() -> int:
|
||||
config_path = Path(os.getenv("CHATGPT2API_CONFIG_FILE", "/app/config.json"))
|
||||
if not config_path.exists():
|
||||
print(f"Config file not found, creating {config_path}")
|
||||
data: dict[str, Any] = {}
|
||||
else:
|
||||
try:
|
||||
data = json.loads(config_path.read_text(encoding="utf-8"))
|
||||
except json.JSONDecodeError as exc:
|
||||
print(f"Invalid JSON in {config_path}: {exc}", file=sys.stderr)
|
||||
return 1
|
||||
if not isinstance(data, dict):
|
||||
print(f"Config root must be an object: {config_path}", file=sys.stderr)
|
||||
return 1
|
||||
|
||||
desired = _warp_runtime_defaults()
|
||||
existing = data.get("proxy_runtime")
|
||||
changed = False
|
||||
|
||||
if _looks_like_repository_default(existing) or _env_bool("CHATGPT2API_PROXY_RUNTIME_FORCE", False):
|
||||
data["proxy_runtime"] = desired
|
||||
changed = True
|
||||
print("Created proxy_runtime defaults")
|
||||
else:
|
||||
runtime = existing if isinstance(existing, dict) else {}
|
||||
changed = _deep_fill_missing(runtime, DEFAULT_PROXY_RUNTIME)
|
||||
data["proxy_runtime"] = runtime
|
||||
print("Proxy runtime already configured")
|
||||
|
||||
if changed:
|
||||
config_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
payload = json.dumps(data, ensure_ascii=False, indent=2) + "\n"
|
||||
tmp_path = config_path.with_suffix(config_path.suffix + ".tmp")
|
||||
try:
|
||||
tmp_path.write_text(payload, encoding="utf-8")
|
||||
tmp_path.replace(config_path)
|
||||
except OSError as exc:
|
||||
# Docker bind-mounted single files can reject atomic rename with EBUSY.
|
||||
# Fall back to in-place write so the init job works with both file and
|
||||
# directory mounts.
|
||||
if getattr(exc, "errno", None) != 16:
|
||||
raise
|
||||
config_path.write_text(payload, encoding="utf-8")
|
||||
tmp_path.unlink(missing_ok=True)
|
||||
|
||||
runtime = data.get("proxy_runtime") if isinstance(data.get("proxy_runtime"), dict) else {}
|
||||
clearance = runtime.get("clearance") if isinstance(runtime.get("clearance"), dict) else {}
|
||||
print(
|
||||
"Proxy runtime summary: "
|
||||
f"enabled={bool(runtime.get('enabled'))}, "
|
||||
f"egress_mode={runtime.get('egress_mode')}, "
|
||||
f"proxy_url={_mask_url(str(runtime.get('proxy_url') or ''))}, "
|
||||
f"clearance_mode={clearance.get('mode')}, "
|
||||
f"flaresolverr_url={_mask_url(str(clearance.get('flaresolverr_url') or ''))}"
|
||||
)
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,163 @@
|
||||
#!/usr/bin/env python3
|
||||
"""
|
||||
存储后端数据迁移脚本
|
||||
|
||||
用法:
|
||||
python scripts/migrate_storage.py --from json --to postgres
|
||||
python scripts/migrate_storage.py --from postgres --to git
|
||||
python scripts/migrate_storage.py --export accounts.json
|
||||
python scripts/migrate_storage.py --import accounts.json
|
||||
"""
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
# 添加项目根目录到 Python 路径
|
||||
sys.path.insert(0, str(Path(__file__).resolve().parents[1]))
|
||||
|
||||
DATA_DIR = Path(__file__).resolve().parents[1] / "data"
|
||||
|
||||
from services.storage.factory import create_storage_backend
|
||||
|
||||
|
||||
def export_to_json(output_file: str):
|
||||
"""导出当前存储后端的数据到 JSON 文件"""
|
||||
print(f"[migrate] Exporting data to {output_file}")
|
||||
DATA_DIR.mkdir(parents=True, exist_ok=True)
|
||||
storage = create_storage_backend(DATA_DIR)
|
||||
accounts = storage.load_accounts()
|
||||
|
||||
output_path = Path(output_file)
|
||||
output_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
output_path.write_text(
|
||||
json.dumps(accounts, ensure_ascii=False, indent=2) + "\n",
|
||||
encoding="utf-8",
|
||||
)
|
||||
|
||||
print(f"[migrate] Exported {len(accounts)} accounts to {output_file}")
|
||||
|
||||
|
||||
def import_from_json(input_file: str):
|
||||
"""从 JSON 文件导入数据到当前存储后端"""
|
||||
print(f"[migrate] Importing data from {input_file}")
|
||||
DATA_DIR.mkdir(parents=True, exist_ok=True)
|
||||
input_path = Path(input_file)
|
||||
if not input_path.exists():
|
||||
print(f"[migrate] Error: File not found: {input_file}")
|
||||
sys.exit(1)
|
||||
|
||||
try:
|
||||
accounts = json.loads(input_path.read_text(encoding="utf-8"))
|
||||
if not isinstance(accounts, list):
|
||||
print(f"[migrate] Error: Invalid JSON format, expected array")
|
||||
sys.exit(1)
|
||||
except json.JSONDecodeError as e:
|
||||
print(f"[migrate] Error: Invalid JSON: {e}")
|
||||
sys.exit(1)
|
||||
|
||||
storage = create_storage_backend(DATA_DIR)
|
||||
storage.save_accounts(accounts)
|
||||
|
||||
print(f"[migrate] Imported {len(accounts)} accounts")
|
||||
|
||||
|
||||
def migrate_data(from_backend: str, to_backend: str):
|
||||
"""从一个存储后端迁移到另一个"""
|
||||
print(f"[migrate] Migrating from {from_backend} to {to_backend}")
|
||||
DATA_DIR.mkdir(parents=True, exist_ok=True)
|
||||
# 保存原始环境变量
|
||||
original_backend = os.environ.get("STORAGE_BACKEND")
|
||||
|
||||
try:
|
||||
# 从源后端读取数据
|
||||
os.environ["STORAGE_BACKEND"] = from_backend
|
||||
from_storage = create_storage_backend(DATA_DIR)
|
||||
accounts = from_storage.load_accounts()
|
||||
print(f"[migrate] Loaded {len(accounts)} accounts from {from_backend}")
|
||||
|
||||
# 写入目标后端
|
||||
os.environ["STORAGE_BACKEND"] = to_backend
|
||||
to_storage = create_storage_backend(DATA_DIR)
|
||||
to_storage.save_accounts(accounts)
|
||||
print(f"[migrate] Saved {len(accounts)} accounts to {to_backend}")
|
||||
|
||||
print(f"[migrate] Migration completed successfully!")
|
||||
|
||||
finally:
|
||||
# 恢复原始环境变量
|
||||
if original_backend:
|
||||
os.environ["STORAGE_BACKEND"] = original_backend
|
||||
elif "STORAGE_BACKEND" in os.environ:
|
||||
del os.environ["STORAGE_BACKEND"]
|
||||
|
||||
|
||||
def main():
|
||||
parser = argparse.ArgumentParser(
|
||||
description="ChatGPT2API 存储后端数据迁移工具",
|
||||
formatter_class=argparse.RawDescriptionHelpFormatter,
|
||||
epilog="""
|
||||
示例:
|
||||
# 从 JSON 迁移到 PostgreSQL
|
||||
python scripts/migrate_storage.py --from json --to postgres
|
||||
|
||||
# 从 PostgreSQL 迁移到 Git
|
||||
python scripts/migrate_storage.py --from postgres --to git
|
||||
|
||||
# 导出当前数据到 JSON 文件
|
||||
python scripts/migrate_storage.py --export backup.json
|
||||
|
||||
# 从 JSON 文件导入数据
|
||||
python scripts/migrate_storage.py --import backup.json
|
||||
|
||||
环境变量:
|
||||
STORAGE_BACKEND - 存储后端类型 (json, sqlite, postgres, git)
|
||||
DATABASE_URL - 数据库连接字符串
|
||||
GIT_REPO_URL - Git 仓库地址
|
||||
GIT_TOKEN - Git 访问令牌
|
||||
"""
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--from",
|
||||
dest="from_backend",
|
||||
choices=["json", "sqlite", "postgres", "git"],
|
||||
help="源存储后端",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--to",
|
||||
dest="to_backend",
|
||||
choices=["json", "sqlite", "postgres", "git"],
|
||||
help="目标存储后端",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
dest="export_file",
|
||||
metavar="FILE",
|
||||
help="导出数据到 JSON 文件",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--import",
|
||||
dest="import_file",
|
||||
metavar="FILE",
|
||||
help="从 JSON 文件导入数据",
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
# 检查参数
|
||||
if args.from_backend and args.to_backend:
|
||||
migrate_data(args.from_backend, args.to_backend)
|
||||
elif args.export_file:
|
||||
export_to_json(args.export_file)
|
||||
elif args.import_file:
|
||||
import_from_json(args.import_file)
|
||||
else:
|
||||
parser.print_help()
|
||||
sys.exit(1)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,13 @@
|
||||
listen-address 0.0.0.0:8118
|
||||
toggle 1
|
||||
enable-remote-toggle 0
|
||||
enable-remote-http-toggle 0
|
||||
enable-edit-actions 0
|
||||
enforce-blocks 0
|
||||
buffer-limit 4096
|
||||
keep-alive-timeout 300
|
||||
socket-timeout 300
|
||||
|
||||
# Forward every HTTP/HTTPS request through the WARP SOCKS5 proxy.
|
||||
# The trailing dot is required by Privoxy syntax.
|
||||
forward-socks5t / warp-proxy:1080 .
|
||||
@@ -0,0 +1,385 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import imaplib
|
||||
import json
|
||||
import re
|
||||
import sys
|
||||
import urllib.error
|
||||
import urllib.parse
|
||||
import urllib.request
|
||||
from dataclasses import dataclass
|
||||
from email import message_from_bytes, policy
|
||||
from email.header import decode_header, make_header
|
||||
from email.message import Message
|
||||
from email.utils import parsedate_to_datetime
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
|
||||
TOKEN_URL = "https://login.microsoftonline.com/common/oauth2/v2.0/token"
|
||||
GRAPH_MESSAGES_URL = "https://graph.microsoft.com/v1.0/me/messages"
|
||||
GRAPH_SCOPE = "offline_access https://graph.microsoft.com/Mail.Read"
|
||||
IMAP_SCOPE = "offline_access https://outlook.office.com/IMAP.AccessAsUser.All"
|
||||
DEFAULT_IMAP_HOST = "outlook.office365.com"
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class OutlookCredential:
|
||||
email: str
|
||||
password: str
|
||||
client_id: str
|
||||
refresh_token: str
|
||||
line_number: int
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class HttpResponse:
|
||||
status_code: int
|
||||
text: str
|
||||
|
||||
def json(self) -> Any:
|
||||
return json.loads(self.text)
|
||||
|
||||
|
||||
def _clean(value: str) -> str:
|
||||
return value.replace("\ufeff", "").replace("\u00a0", " ").strip()
|
||||
|
||||
|
||||
def _redact_email(email: str) -> str:
|
||||
local, sep, domain = email.partition("@")
|
||||
if not sep:
|
||||
return "***"
|
||||
if len(local) <= 2:
|
||||
masked = local[:1] + "***"
|
||||
else:
|
||||
masked = local[:2] + "***" + local[-1:]
|
||||
return f"{masked}@{domain}"
|
||||
|
||||
|
||||
def parse_credentials(path: Path) -> list[OutlookCredential]:
|
||||
credentials: list[OutlookCredential] = []
|
||||
for line_number, raw_line in enumerate(path.read_text(encoding="utf-8-sig").splitlines(), start=1):
|
||||
line = _clean(raw_line)
|
||||
if not line or "----" not in line:
|
||||
continue
|
||||
parts = [_clean(part) for part in line.split("----", 3)]
|
||||
if len(parts) != 4:
|
||||
continue
|
||||
email, password, client_id, refresh_token = parts
|
||||
if "@" not in email or not client_id or not refresh_token:
|
||||
continue
|
||||
credentials.append(
|
||||
OutlookCredential(
|
||||
email=email,
|
||||
password=password,
|
||||
client_id=client_id,
|
||||
refresh_token=refresh_token,
|
||||
line_number=line_number,
|
||||
)
|
||||
)
|
||||
return credentials
|
||||
|
||||
|
||||
def _http_request(
|
||||
method: str,
|
||||
url: str,
|
||||
*,
|
||||
headers: dict[str, str] | None = None,
|
||||
data: dict[str, str] | None = None,
|
||||
params: dict[str, Any] | None = None,
|
||||
timeout: float = 30,
|
||||
) -> HttpResponse:
|
||||
target = url
|
||||
if params:
|
||||
query = urllib.parse.urlencode(params)
|
||||
target = f"{url}?{query}"
|
||||
|
||||
body: bytes | None = None
|
||||
request_headers = dict(headers or {})
|
||||
if data is not None:
|
||||
body = urllib.parse.urlencode(data).encode("utf-8")
|
||||
request_headers.setdefault("Content-Type", "application/x-www-form-urlencoded")
|
||||
|
||||
request = urllib.request.Request(target, data=body, headers=request_headers, method=method.upper())
|
||||
try:
|
||||
with urllib.request.urlopen(request, timeout=timeout) as response:
|
||||
return HttpResponse(
|
||||
status_code=int(response.status),
|
||||
text=response.read().decode("utf-8", errors="replace"),
|
||||
)
|
||||
except urllib.error.HTTPError as error:
|
||||
return HttpResponse(
|
||||
status_code=int(error.code),
|
||||
text=error.read().decode("utf-8", errors="replace"),
|
||||
)
|
||||
|
||||
|
||||
def exchange_refresh_token(credential: OutlookCredential, scope: str, timeout: float) -> str:
|
||||
response = _http_request(
|
||||
"POST",
|
||||
TOKEN_URL,
|
||||
data={
|
||||
"client_id": credential.client_id,
|
||||
"grant_type": "refresh_token",
|
||||
"refresh_token": credential.refresh_token,
|
||||
"scope": scope,
|
||||
},
|
||||
timeout=timeout,
|
||||
)
|
||||
try:
|
||||
data = response.json()
|
||||
except Exception:
|
||||
data = {}
|
||||
if response.status_code != 200:
|
||||
detail = data.get("error_description") or data.get("error") or response.text[:300]
|
||||
raise RuntimeError(f"token refresh failed: HTTP {response.status_code}, {detail}")
|
||||
access_token = str(data.get("access_token") or "").strip()
|
||||
if not access_token:
|
||||
raise RuntimeError("token refresh response did not include access_token")
|
||||
return access_token
|
||||
|
||||
|
||||
def _graph_sender(message: dict[str, Any]) -> str:
|
||||
sender = message.get("from") or {}
|
||||
if isinstance(sender, dict):
|
||||
address = sender.get("emailAddress") or {}
|
||||
if isinstance(address, dict):
|
||||
return str(address.get("address") or address.get("name") or "")
|
||||
return ""
|
||||
|
||||
|
||||
def read_graph_messages(access_token: str, limit: int, timeout: float) -> list[dict[str, str]]:
|
||||
response = _http_request(
|
||||
"GET",
|
||||
GRAPH_MESSAGES_URL,
|
||||
headers={"Authorization": f"Bearer {access_token}", "Accept": "application/json"},
|
||||
params={
|
||||
"$top": max(1, min(limit, 50)),
|
||||
"$orderby": "receivedDateTime desc",
|
||||
"$select": "subject,receivedDateTime,from,bodyPreview",
|
||||
},
|
||||
timeout=timeout,
|
||||
)
|
||||
try:
|
||||
data = response.json()
|
||||
except Exception:
|
||||
data = {}
|
||||
if response.status_code != 200:
|
||||
detail = data.get("error", {}).get("message") if isinstance(data.get("error"), dict) else response.text[:300]
|
||||
raise RuntimeError(f"graph messages failed: HTTP {response.status_code}, {detail}")
|
||||
items = data.get("value") if isinstance(data, dict) else None
|
||||
if not isinstance(items, list):
|
||||
raise RuntimeError("graph messages response did not include value[]")
|
||||
return [
|
||||
{
|
||||
"received": str(item.get("receivedDateTime") or ""),
|
||||
"from": _graph_sender(item),
|
||||
"subject": str(item.get("subject") or ""),
|
||||
"preview": str(item.get("bodyPreview") or ""),
|
||||
}
|
||||
for item in items
|
||||
if isinstance(item, dict)
|
||||
]
|
||||
|
||||
|
||||
def _decode_header(value: str | None) -> str:
|
||||
if not value:
|
||||
return ""
|
||||
try:
|
||||
return str(make_header(decode_header(value)))
|
||||
except Exception:
|
||||
return value
|
||||
|
||||
|
||||
def _message_text_preview(message: Message, limit: int = 240) -> str:
|
||||
text_parts: list[str] = []
|
||||
parts = message.walk() if message.is_multipart() else [message]
|
||||
for part in parts:
|
||||
if part.get_content_maintype() == "multipart":
|
||||
continue
|
||||
content_type = part.get_content_type()
|
||||
if content_type not in {"text/plain", "text/html"}:
|
||||
continue
|
||||
try:
|
||||
payload = part.get_content()
|
||||
except Exception:
|
||||
continue
|
||||
if payload:
|
||||
text_parts.append(str(payload))
|
||||
if content_type == "text/plain" and text_parts:
|
||||
break
|
||||
text = "\n".join(text_parts)
|
||||
text = re.sub(r"<[^>]+>", " ", text)
|
||||
text = re.sub(r"\s+", " ", text).strip()
|
||||
return text[:limit]
|
||||
|
||||
|
||||
def _parse_imap_message(raw: bytes, include_preview: bool) -> dict[str, str]:
|
||||
message = message_from_bytes(raw, policy=policy.default)
|
||||
received = ""
|
||||
try:
|
||||
parsed = parsedate_to_datetime(str(message.get("Date") or ""))
|
||||
received = parsed.isoformat()
|
||||
except Exception:
|
||||
received = str(message.get("Date") or "")
|
||||
return {
|
||||
"received": received,
|
||||
"from": _decode_header(str(message.get("From") or "")),
|
||||
"subject": _decode_header(str(message.get("Subject") or "")),
|
||||
"preview": _message_text_preview(message) if include_preview else "",
|
||||
}
|
||||
|
||||
|
||||
def read_imap_messages(access_token: str, email: str, host: str, limit: int, include_preview: bool) -> list[dict[str, str]]:
|
||||
auth_string = f"user={email}\x01auth=Bearer {access_token}\x01\x01"
|
||||
mailbox = imaplib.IMAP4_SSL(host)
|
||||
try:
|
||||
mailbox.authenticate("XOAUTH2", lambda _: auth_string.encode("utf-8"))
|
||||
status, _ = mailbox.select("INBOX", readonly=True)
|
||||
if status != "OK":
|
||||
raise RuntimeError("imap select INBOX failed")
|
||||
status, data = mailbox.uid("search", None, "ALL")
|
||||
if status != "OK" or not data or not data[0]:
|
||||
return []
|
||||
uids = data[0].split()[-max(1, limit) :]
|
||||
messages: list[dict[str, str]] = []
|
||||
for uid in reversed(uids):
|
||||
status, fetched = mailbox.uid("fetch", uid, "(RFC822)")
|
||||
if status != "OK":
|
||||
continue
|
||||
raw_payload = next((item[1] for item in fetched if isinstance(item, tuple) and isinstance(item[1], bytes)), b"")
|
||||
if raw_payload:
|
||||
messages.append(_parse_imap_message(raw_payload, include_preview))
|
||||
return messages
|
||||
finally:
|
||||
try:
|
||||
mailbox.logout()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
|
||||
def print_messages(messages: list[dict[str, str]], include_preview: bool) -> None:
|
||||
if not messages:
|
||||
print(" no recent messages")
|
||||
return
|
||||
for index, message in enumerate(messages, start=1):
|
||||
print(f" {index}. {message['received']} | {message['from']} | {message['subject']}")
|
||||
if include_preview and message.get("preview"):
|
||||
print(f" preview: {message['preview']}")
|
||||
|
||||
|
||||
def test_credential(
|
||||
credential: OutlookCredential,
|
||||
mode: str,
|
||||
limit: int,
|
||||
timeout: float,
|
||||
imap_host: str,
|
||||
include_preview: bool,
|
||||
show_email: bool,
|
||||
) -> bool:
|
||||
label = credential.email if show_email else _redact_email(credential.email)
|
||||
print(f"[line {credential.line_number}] {label}")
|
||||
errors: list[str] = []
|
||||
|
||||
if mode in {"graph", "auto"}:
|
||||
try:
|
||||
access_token = exchange_refresh_token(credential, GRAPH_SCOPE, timeout)
|
||||
messages = read_graph_messages(access_token, limit, timeout)
|
||||
print(" graph: ok")
|
||||
print_messages(messages, include_preview)
|
||||
return True
|
||||
except Exception as error:
|
||||
errors.append(f"graph: {error}")
|
||||
if mode == "graph":
|
||||
print(f" graph: failed - {error}")
|
||||
return False
|
||||
|
||||
if mode in {"imap", "auto"}:
|
||||
try:
|
||||
access_token = exchange_refresh_token(credential, IMAP_SCOPE, timeout)
|
||||
messages = read_imap_messages(access_token, credential.email, imap_host, limit, include_preview)
|
||||
print(" imap: ok")
|
||||
print_messages(messages, include_preview)
|
||||
return True
|
||||
except Exception as error:
|
||||
errors.append(f"imap: {error}")
|
||||
if mode == "imap":
|
||||
print(f" imap: failed - {error}")
|
||||
return False
|
||||
|
||||
print(" failed")
|
||||
for error in errors:
|
||||
print(f" - {error}")
|
||||
return False
|
||||
|
||||
|
||||
def build_parser() -> argparse.ArgumentParser:
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Test Outlook/Hotmail mailbox access from lines formatted as email----password----client_id----refresh_token.",
|
||||
)
|
||||
parser.add_argument("--file", default=r"D:\Desktop\yx.txt", help="Credential text file path.")
|
||||
parser.add_argument("--mode", choices=("auto", "graph", "imap"), default="auto", help="Mailbox read method.")
|
||||
parser.add_argument("--limit-accounts", type=int, default=1, help="How many accounts to test.")
|
||||
parser.add_argument("--message-limit", type=int, default=5, help="How many recent messages to list per account.")
|
||||
parser.add_argument("--timeout", type=float, default=30, help="HTTP request timeout in seconds.")
|
||||
parser.add_argument("--imap-host", default=DEFAULT_IMAP_HOST, help="IMAP host for XOAUTH2 mode.")
|
||||
parser.add_argument("--preview", action="store_true", help="Print body preview/snippet. Disabled by default.")
|
||||
parser.add_argument("--show-email", action="store_true", help="Print full email address. Secrets are never printed.")
|
||||
parser.add_argument("--json", action="store_true", help="Only parse the file and print non-secret account metadata as JSON.")
|
||||
return parser
|
||||
|
||||
|
||||
def main() -> int:
|
||||
args = build_parser().parse_args()
|
||||
path = Path(args.file)
|
||||
if not path.exists():
|
||||
print(f"file not found: {path}", file=sys.stderr)
|
||||
return 2
|
||||
|
||||
credentials = parse_credentials(path)
|
||||
if not credentials:
|
||||
print(f"no valid credentials parsed from: {path}", file=sys.stderr)
|
||||
return 2
|
||||
|
||||
limit_accounts = max(1, int(args.limit_accounts or 1))
|
||||
selected = credentials[:limit_accounts]
|
||||
|
||||
if args.json:
|
||||
print(
|
||||
json.dumps(
|
||||
[
|
||||
{
|
||||
"line": item.line_number,
|
||||
"email": item.email if args.show_email else _redact_email(item.email),
|
||||
"client_id": item.client_id,
|
||||
"has_password": bool(item.password),
|
||||
"has_refresh_token": bool(item.refresh_token),
|
||||
}
|
||||
for item in selected
|
||||
],
|
||||
ensure_ascii=False,
|
||||
indent=2,
|
||||
)
|
||||
)
|
||||
return 0
|
||||
|
||||
print(f"parsed {len(credentials)} credential(s), testing {len(selected)}")
|
||||
success = 0
|
||||
for credential in selected:
|
||||
if test_credential(
|
||||
credential=credential,
|
||||
mode=str(args.mode),
|
||||
limit=max(1, int(args.message_limit or 1)),
|
||||
timeout=max(1.0, float(args.timeout or 30)),
|
||||
imap_host=str(args.imap_host),
|
||||
include_preview=bool(args.preview),
|
||||
show_email=bool(args.show_email),
|
||||
):
|
||||
success += 1
|
||||
print(f"summary: {success}/{len(selected)} account(s) readable")
|
||||
return 0 if success == len(selected) else 1
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,129 @@
|
||||
#!/usr/bin/env python3
|
||||
"""
|
||||
存储后端测试脚本
|
||||
|
||||
用法:
|
||||
python scripts/test_storage.py
|
||||
"""
|
||||
|
||||
import os
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
# 添加项目根目录到 Python 路径
|
||||
sys.path.insert(0, str(Path(__file__).resolve().parents[1]))
|
||||
|
||||
DATA_DIR = Path(__file__).resolve().parents[1] / "data"
|
||||
|
||||
from services.storage.factory import create_storage_backend
|
||||
|
||||
|
||||
def test_storage():
|
||||
"""测试当前配置的存储后端"""
|
||||
DATA_DIR.mkdir(parents=True, exist_ok=True)
|
||||
print("=" * 60)
|
||||
print("ChatGPT2API 存储后端测试")
|
||||
print("=" * 60)
|
||||
|
||||
# 显示当前配置
|
||||
backend_type = os.getenv("STORAGE_BACKEND", "json")
|
||||
print(f"\n当前存储后端: {backend_type}")
|
||||
|
||||
if backend_type in ("sqlite", "postgres", "postgresql", "mysql", "database"):
|
||||
database_url = os.getenv("DATABASE_URL", "")
|
||||
if database_url:
|
||||
# 隐藏密码
|
||||
if "://" in database_url and "@" in database_url:
|
||||
protocol, rest = database_url.split("://", 1)
|
||||
if "@" in rest:
|
||||
credentials, host = rest.split("@", 1)
|
||||
if ":" in credentials:
|
||||
username, _ = credentials.split(":", 1)
|
||||
database_url = f"{protocol}://{username}:****@{host}"
|
||||
print(f"数据库连接: {database_url}")
|
||||
else:
|
||||
print(f"数据库连接: 本地 SQLite (data/accounts.db)")
|
||||
|
||||
elif backend_type == "git":
|
||||
repo_url = os.getenv("GIT_REPO_URL", "")
|
||||
branch = os.getenv("GIT_BRANCH", "main")
|
||||
file_path = os.getenv("GIT_FILE_PATH", "accounts.json")
|
||||
print(f"Git 仓库: {repo_url}")
|
||||
print(f"Git 分支: {branch}")
|
||||
print(f"文件路径: {file_path}")
|
||||
|
||||
print("\n" + "=" * 60)
|
||||
|
||||
try:
|
||||
# 创建存储后端
|
||||
print("\n[1/5] 创建存储后端...")
|
||||
storage = create_storage_backend(DATA_DIR)
|
||||
print("✅ 存储后端创建成功")
|
||||
|
||||
# 获取后端信息
|
||||
print("\n[2/5] 获取后端信息...")
|
||||
info = storage.get_backend_info()
|
||||
print(f"✅ 后端类型: {info.get('type')}")
|
||||
print(f" 描述: {info.get('description')}")
|
||||
for key, value in info.items():
|
||||
if key not in ('type', 'description'):
|
||||
print(f" {key}: {value}")
|
||||
|
||||
# 健康检查
|
||||
print("\n[3/5] 执行健康检查...")
|
||||
health = storage.health_check()
|
||||
status = health.get("status")
|
||||
if status == "healthy":
|
||||
print(f"✅ 健康状态: {status}")
|
||||
else:
|
||||
print(f"❌ 健康状态: {status}")
|
||||
print(f" 错误: {health.get('error')}")
|
||||
return False
|
||||
|
||||
# 读取数据
|
||||
print("\n[4/5] 读取账号数据...")
|
||||
accounts = storage.load_accounts()
|
||||
print(f"✅ 成功读取 {len(accounts)} 个账号")
|
||||
|
||||
# 写入测试(可选)
|
||||
print("\n[5/5] 测试写入功能...")
|
||||
test_account = {
|
||||
"access_token": "test_token_" + str(os.getpid()),
|
||||
"type": "Free",
|
||||
"status": "测试",
|
||||
"quota": 0,
|
||||
"email": "test@example.com",
|
||||
}
|
||||
|
||||
# 添加测试账号
|
||||
test_accounts = accounts + [test_account]
|
||||
storage.save_accounts(test_accounts)
|
||||
print("✅ 写入测试账号成功")
|
||||
|
||||
# 验证写入
|
||||
reloaded = storage.load_accounts()
|
||||
if len(reloaded) == len(test_accounts):
|
||||
print("✅ 验证写入成功")
|
||||
else:
|
||||
print(f"❌ 验证失败: 期望 {len(test_accounts)} 个账号,实际 {len(reloaded)} 个")
|
||||
return False
|
||||
|
||||
# 恢复原始数据
|
||||
storage.save_accounts(accounts)
|
||||
print("✅ 恢复原始数据")
|
||||
|
||||
print("\n" + "=" * 60)
|
||||
print("✅ 所有测试通过!")
|
||||
print("=" * 60)
|
||||
return True
|
||||
|
||||
except Exception as e:
|
||||
print(f"\n❌ 测试失败: {e}")
|
||||
import traceback
|
||||
traceback.print_exc()
|
||||
return False
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
success = test_storage()
|
||||
sys.exit(0 if success else 1)
|
||||
@@ -0,0 +1,92 @@
|
||||
"""验证 OAuth 账号的自动刷新是否生效。
|
||||
|
||||
用法(在容器内,工作目录 /app):
|
||||
uv run python scripts/verify_oauth_refresh.py # 只读诊断,安全
|
||||
uv run python scripts/verify_oauth_refresh.py --force # 真正触发一次刷新
|
||||
|
||||
只读模式:列出每个账号的 access_token 剩余有效期、是否带 refresh_token、
|
||||
上次刷新时间与上次刷新错误,判断"有没有料可刷"。
|
||||
--force :对每个带 refresh_token 的账号强制走一次 refresh_access_token(force=True),
|
||||
直接验证 refresh_token + 本项目 client_id 能否从 OpenAI 换出新 access_token。
|
||||
这会真实轮换 access_token(新 token 有效,不损坏账号)。
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import sys
|
||||
|
||||
from services.account_service import account_service
|
||||
|
||||
|
||||
def _fmt_remaining(seconds: int | None) -> str:
|
||||
if seconds is None:
|
||||
return "无法解析 exp"
|
||||
if seconds <= 0:
|
||||
return f"已过期 {(-seconds) // 3600}h"
|
||||
return f"{seconds // 3600}h{(seconds % 3600) // 60}m 后过期"
|
||||
|
||||
|
||||
def diagnose() -> list[str]:
|
||||
"""只读:打印每个账号的刷新就绪状态,返回带 refresh_token 的 token 列表。"""
|
||||
tokens = account_service.list_tokens()
|
||||
print(f"账号总数: {len(tokens)}\n")
|
||||
refreshable: list[str] = []
|
||||
for token in tokens:
|
||||
account = account_service.get_account(token) or {}
|
||||
remaining = account_service._token_expires_in(token)
|
||||
has_rt = bool(str(account.get("refresh_token") or "").strip())
|
||||
if has_rt:
|
||||
refreshable.append(token)
|
||||
print(f"- email={account.get('email') or '(未知)'}")
|
||||
print(f" access_token[:20] = {token[:20]}...")
|
||||
print(f" 距过期 = {_fmt_remaining(remaining)}")
|
||||
print(f" refresh_token = {'有 ✅' if has_rt else '无 ❌(无法自动刷新)'}")
|
||||
print(f" last_token_refresh_at = {account.get('last_token_refresh_at')}")
|
||||
print(f" last_token_refresh_error = {account.get('last_token_refresh_error')}")
|
||||
print()
|
||||
return refreshable
|
||||
|
||||
|
||||
def force_refresh(tokens: list[str]) -> None:
|
||||
"""对每个账号 force 刷新一次,并对比前后状态判断成败。"""
|
||||
if not tokens:
|
||||
print("没有带 refresh_token 的账号,无法验证刷新。")
|
||||
return
|
||||
print("=" * 60)
|
||||
print(f"开始对 {len(tokens)} 个账号 force 刷新(真实调用 OpenAI)...\n")
|
||||
ok = 0
|
||||
for token in tokens:
|
||||
before = account_service.get_account(token) or {}
|
||||
new_token = account_service.refresh_access_token(token, force=True, event="manual_verify")
|
||||
after = account_service.get_account(new_token) or {}
|
||||
err = str(after.get("last_token_refresh_error") or "").strip()
|
||||
rotated = new_token != token
|
||||
success = bool(new_token) and not err
|
||||
if success:
|
||||
ok += 1
|
||||
print(f"- email={before.get('email') or '(未知)'}")
|
||||
print(f" 旧 access_token[:20] = {token[:20]}...")
|
||||
print(f" 新 access_token[:20] = {new_token[:20]}...")
|
||||
print(f" token 是否轮换 = {'是' if rotated else '否(exp 未到刷新窗口时可能返回原值)'}")
|
||||
print(f" last_token_refresh_at = {after.get('last_token_refresh_at')}")
|
||||
print(f" last_token_refresh_error = {after.get('last_token_refresh_error') or '无'}")
|
||||
print(f" >>> 刷新结果 = {'成功 ✅' if success else '失败 ❌'}")
|
||||
print()
|
||||
print("=" * 60)
|
||||
print(f"汇总: {ok}/{len(tokens)} 个账号刷新成功")
|
||||
if ok == len(tokens):
|
||||
print("✅ 自动刷新机制对这些账号完全可用——refresh_token 与 client_id 匹配。")
|
||||
else:
|
||||
print("❌ 有账号刷新失败,看上面的 last_token_refresh_error,或 docker logs 里的 [oauth-login]/refresh 日志。")
|
||||
|
||||
|
||||
def main() -> None:
|
||||
do_force = "--force" in sys.argv[1:]
|
||||
refreshable = diagnose()
|
||||
if do_force:
|
||||
force_refresh(refreshable)
|
||||
else:
|
||||
print("提示: 加 --force 参数可真正触发一次刷新以验证能否成功。")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,253 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import hashlib
|
||||
import hmac
|
||||
import secrets
|
||||
import uuid
|
||||
from datetime import datetime, timezone
|
||||
from threading import Lock
|
||||
from typing import Literal
|
||||
|
||||
from services.config import config
|
||||
from services.storage.base import StorageBackend
|
||||
|
||||
AuthRole = Literal["admin", "user"]
|
||||
|
||||
|
||||
def _now_iso() -> str:
|
||||
return datetime.now(timezone.utc).isoformat()
|
||||
|
||||
|
||||
def _hash_key(value: str) -> str:
|
||||
return hashlib.sha256(value.encode("utf-8")).hexdigest()
|
||||
|
||||
|
||||
class AuthService:
|
||||
def __init__(self, storage: StorageBackend):
|
||||
self.storage = storage
|
||||
self._lock = Lock()
|
||||
self._items = self._load()
|
||||
self._last_used_flush_at: dict[str, datetime] = {}
|
||||
|
||||
@staticmethod
|
||||
def _clean(value: object) -> str:
|
||||
return str(value or "").strip()
|
||||
|
||||
@staticmethod
|
||||
def _default_name(role: object) -> str:
|
||||
return "管理员密钥" if str(role or "").strip().lower() == "admin" else "普通用户"
|
||||
|
||||
def _normalize_item(self, raw: object) -> dict[str, object] | None:
|
||||
if not isinstance(raw, dict):
|
||||
return None
|
||||
role = self._clean(raw.get("role")).lower()
|
||||
if role not in {"admin", "user"}:
|
||||
return None
|
||||
key_hash = self._clean(raw.get("key_hash"))
|
||||
if not key_hash:
|
||||
return None
|
||||
item_id = self._clean(raw.get("id")) or uuid.uuid4().hex[:12]
|
||||
name = self._clean(raw.get("name")) or self._default_name(role)
|
||||
created_at = self._clean(raw.get("created_at")) or _now_iso()
|
||||
last_used_at = self._clean(raw.get("last_used_at")) or None
|
||||
return {
|
||||
"id": item_id,
|
||||
"name": name,
|
||||
"role": role,
|
||||
"key_hash": key_hash,
|
||||
"enabled": bool(raw.get("enabled", True)),
|
||||
"created_at": created_at,
|
||||
"last_used_at": last_used_at,
|
||||
}
|
||||
|
||||
def _load(self) -> list[dict[str, object]]:
|
||||
try:
|
||||
items = self.storage.load_auth_keys()
|
||||
except Exception:
|
||||
return []
|
||||
if not isinstance(items, list):
|
||||
return []
|
||||
return [normalized for item in items if (normalized := self._normalize_item(item)) is not None]
|
||||
|
||||
def _save(self) -> None:
|
||||
self.storage.save_auth_keys(self._items)
|
||||
|
||||
def _reload_locked(self) -> None:
|
||||
self._items = self._load()
|
||||
|
||||
@staticmethod
|
||||
def _public_item(item: dict[str, object]) -> dict[str, object]:
|
||||
return {
|
||||
"id": item.get("id"),
|
||||
"name": item.get("name"),
|
||||
"role": item.get("role"),
|
||||
"enabled": bool(item.get("enabled", True)),
|
||||
"created_at": item.get("created_at"),
|
||||
"last_used_at": item.get("last_used_at"),
|
||||
}
|
||||
|
||||
def list_keys(self, role: AuthRole | None = None) -> list[dict[str, object]]:
|
||||
with self._lock:
|
||||
self._reload_locked()
|
||||
items = [item for item in self._items if role is None or item.get("role") == role]
|
||||
return [self._public_item(item) for item in items]
|
||||
|
||||
def _has_key_hash_locked(self, key_hash: str, *, exclude_id: str = "") -> bool:
|
||||
for item in self._items:
|
||||
item_id = self._clean(item.get("id"))
|
||||
if exclude_id and item_id == exclude_id:
|
||||
continue
|
||||
stored_hash = self._clean(item.get("key_hash"))
|
||||
if stored_hash and hmac.compare_digest(stored_hash, key_hash):
|
||||
return True
|
||||
return False
|
||||
|
||||
def _build_key_hash_locked(self, raw_key: str, *, exclude_id: str = "") -> str:
|
||||
candidate = self._clean(raw_key)
|
||||
if not candidate:
|
||||
raise ValueError("请输入新的专用密钥")
|
||||
admin_key = self._clean(config.auth_key)
|
||||
if admin_key and hmac.compare_digest(candidate, admin_key):
|
||||
raise ValueError("这个密钥和管理员密钥冲突了,请换一个新的密钥")
|
||||
key_hash = _hash_key(candidate)
|
||||
if self._has_key_hash_locked(key_hash, exclude_id=exclude_id):
|
||||
raise ValueError("这个专用密钥已经存在,请换一个新的密钥")
|
||||
return key_hash
|
||||
|
||||
def _has_name_locked(self, name: str, *, role: AuthRole | None = None, exclude_id: str = "") -> bool:
|
||||
candidate = self._clean(name)
|
||||
if not candidate:
|
||||
return False
|
||||
for item in self._items:
|
||||
item_id = self._clean(item.get("id"))
|
||||
if exclude_id and item_id == exclude_id:
|
||||
continue
|
||||
if role is not None and item.get("role") != role:
|
||||
continue
|
||||
if self._clean(item.get("name")) == candidate:
|
||||
return True
|
||||
return False
|
||||
|
||||
def _build_default_name_locked(self, role: AuthRole, *, exclude_id: str = "") -> str:
|
||||
base_name = self._default_name(role)
|
||||
if not self._has_name_locked(base_name, role=role, exclude_id=exclude_id):
|
||||
return base_name
|
||||
suffix = 2
|
||||
while True:
|
||||
candidate = f"{base_name} {suffix}"
|
||||
if not self._has_name_locked(candidate, role=role, exclude_id=exclude_id):
|
||||
return candidate
|
||||
suffix += 1
|
||||
|
||||
def _build_name_locked(self, name: str, *, role: AuthRole, exclude_id: str = "") -> str:
|
||||
candidate = self._clean(name)
|
||||
if not candidate:
|
||||
return self._build_default_name_locked(role, exclude_id=exclude_id)
|
||||
if self._has_name_locked(candidate, role=role, exclude_id=exclude_id):
|
||||
raise ValueError("这个名称已经在使用中了,换一个更容易区分的名称吧")
|
||||
return candidate
|
||||
|
||||
def create_key(self, *, role: AuthRole, name: str = "") -> tuple[dict[str, object], str]:
|
||||
with self._lock:
|
||||
self._reload_locked()
|
||||
normalized_name = self._build_name_locked(name, role=role)
|
||||
while True:
|
||||
raw_key = f"sk-{secrets.token_urlsafe(24)}"
|
||||
try:
|
||||
key_hash = self._build_key_hash_locked(raw_key)
|
||||
break
|
||||
except ValueError:
|
||||
continue
|
||||
item = {
|
||||
"id": uuid.uuid4().hex[:12],
|
||||
"name": normalized_name,
|
||||
"role": role,
|
||||
"key_hash": key_hash,
|
||||
"enabled": True,
|
||||
"created_at": _now_iso(),
|
||||
"last_used_at": None,
|
||||
}
|
||||
self._items.append(item)
|
||||
self._save()
|
||||
return self._public_item(item), raw_key
|
||||
|
||||
def update_key(
|
||||
self,
|
||||
key_id: str,
|
||||
updates: dict[str, object],
|
||||
*,
|
||||
role: AuthRole | None = None,
|
||||
) -> dict[str, object] | None:
|
||||
normalized_id = self._clean(key_id)
|
||||
if not normalized_id:
|
||||
return None
|
||||
with self._lock:
|
||||
self._reload_locked()
|
||||
for index, item in enumerate(self._items):
|
||||
if item.get("id") != normalized_id:
|
||||
continue
|
||||
if role is not None and item.get("role") != role:
|
||||
return None
|
||||
next_item = dict(item)
|
||||
next_role = "admin" if str(next_item.get("role") or "").strip().lower() == "admin" else "user"
|
||||
if "name" in updates and updates.get("name") is not None:
|
||||
next_item["name"] = self._build_name_locked(
|
||||
str(updates.get("name") or ""),
|
||||
role=next_role,
|
||||
exclude_id=normalized_id,
|
||||
)
|
||||
if "enabled" in updates and updates.get("enabled") is not None:
|
||||
next_item["enabled"] = bool(updates.get("enabled"))
|
||||
if "key" in updates and updates.get("key") is not None:
|
||||
next_item["key_hash"] = self._build_key_hash_locked(str(updates.get("key") or ""), exclude_id=normalized_id)
|
||||
self._items[index] = next_item
|
||||
self._save()
|
||||
return self._public_item(next_item)
|
||||
return None
|
||||
|
||||
def delete_key(self, key_id: str, *, role: AuthRole | None = None) -> bool:
|
||||
normalized_id = self._clean(key_id)
|
||||
if not normalized_id:
|
||||
return False
|
||||
with self._lock:
|
||||
self._reload_locked()
|
||||
before = len(self._items)
|
||||
self._items = [
|
||||
item
|
||||
for item in self._items
|
||||
if not (item.get("id") == normalized_id and (role is None or item.get("role") == role))
|
||||
]
|
||||
if len(self._items) == before:
|
||||
return False
|
||||
self._save()
|
||||
return True
|
||||
|
||||
def authenticate(self, raw_key: str) -> dict[str, object] | None:
|
||||
candidate = self._clean(raw_key)
|
||||
if not candidate:
|
||||
return None
|
||||
candidate_hash = _hash_key(candidate)
|
||||
with self._lock:
|
||||
for index, item in enumerate(self._items):
|
||||
if not bool(item.get("enabled", True)):
|
||||
continue
|
||||
stored_hash = self._clean(item.get("key_hash"))
|
||||
if not stored_hash or not hmac.compare_digest(stored_hash, candidate_hash):
|
||||
continue
|
||||
next_item = dict(item)
|
||||
now = datetime.now(timezone.utc)
|
||||
next_item["last_used_at"] = now.isoformat()
|
||||
self._items[index] = next_item
|
||||
item_id = self._clean(next_item.get("id"))
|
||||
last_flush_at = self._last_used_flush_at.get(item_id)
|
||||
if last_flush_at is None or (now - last_flush_at).total_seconds() >= 60:
|
||||
try:
|
||||
self._save()
|
||||
self._last_used_flush_at[item_id] = now
|
||||
except Exception:
|
||||
pass
|
||||
return self._public_item(next_item)
|
||||
return None
|
||||
|
||||
|
||||
auth_service = AuthService(config.get_storage_backend())
|
||||
@@ -0,0 +1,671 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import hashlib
|
||||
import hmac
|
||||
import io
|
||||
import json
|
||||
import os
|
||||
import random
|
||||
import subprocess
|
||||
import tarfile
|
||||
import threading
|
||||
from datetime import UTC, datetime
|
||||
from pathlib import Path
|
||||
from urllib.parse import quote, urlencode
|
||||
|
||||
from curl_cffi import requests
|
||||
|
||||
from services.config import BASE_DIR, CONFIG_FILE, DATA_DIR, config, load_backup_state, save_backup_state
|
||||
from services.image_storage_service import IMAGE_INDEX_FILE
|
||||
from services.image_tags_service import TAGS_FILE
|
||||
|
||||
|
||||
def _utc_now() -> datetime:
|
||||
return datetime.now(UTC)
|
||||
|
||||
|
||||
def _iso_now() -> str:
|
||||
return _utc_now().replace(microsecond=0).isoformat().replace("+00:00", "Z")
|
||||
|
||||
|
||||
def _clean(value: object) -> str:
|
||||
return str(value or "").strip()
|
||||
|
||||
|
||||
def _sha256_hex(value: bytes) -> str:
|
||||
return hashlib.sha256(value).hexdigest()
|
||||
|
||||
|
||||
def _is_backup_object(key: object) -> bool:
|
||||
name = _clean(key).rsplit("/", 1)[-1]
|
||||
return name.startswith("backup-") and (name.endswith(".tar.gz") or name.endswith(".tar.gz.enc"))
|
||||
|
||||
|
||||
def _hmac_sha256(key: bytes, message: str) -> bytes:
|
||||
return hmac.new(key, message.encode("utf-8"), hashlib.sha256).digest()
|
||||
|
||||
|
||||
def _openssl_encrypt(data: bytes, passphrase: str) -> bytes:
|
||||
env = dict(os.environ)
|
||||
env["CHATGPT2API_BACKUP_PASSPHRASE"] = passphrase
|
||||
try:
|
||||
result = subprocess.run(
|
||||
[
|
||||
"openssl",
|
||||
"enc",
|
||||
"-aes-256-cbc",
|
||||
"-pbkdf2",
|
||||
"-salt",
|
||||
"-md",
|
||||
"sha256",
|
||||
"-pass",
|
||||
"env:CHATGPT2API_BACKUP_PASSPHRASE",
|
||||
],
|
||||
input=data,
|
||||
stdout=subprocess.PIPE,
|
||||
stderr=subprocess.PIPE,
|
||||
check=True,
|
||||
env=env,
|
||||
)
|
||||
except FileNotFoundError as exc:
|
||||
raise BackupError("当前环境缺少 openssl,无法执行加密备份") from exc
|
||||
except subprocess.CalledProcessError as exc:
|
||||
detail = (exc.stderr or b"").decode("utf-8", errors="replace").strip()
|
||||
raise BackupError(f"加密备份失败:{detail or 'openssl 执行失败'}") from exc
|
||||
return result.stdout
|
||||
|
||||
|
||||
def _openssl_decrypt(data: bytes, passphrase: str) -> bytes:
|
||||
env = dict(os.environ)
|
||||
env["CHATGPT2API_BACKUP_PASSPHRASE"] = passphrase
|
||||
try:
|
||||
result = subprocess.run(
|
||||
[
|
||||
"openssl",
|
||||
"enc",
|
||||
"-d",
|
||||
"-aes-256-cbc",
|
||||
"-pbkdf2",
|
||||
"-md",
|
||||
"sha256",
|
||||
"-pass",
|
||||
"env:CHATGPT2API_BACKUP_PASSPHRASE",
|
||||
],
|
||||
input=data,
|
||||
stdout=subprocess.PIPE,
|
||||
stderr=subprocess.PIPE,
|
||||
check=True,
|
||||
env=env,
|
||||
)
|
||||
except FileNotFoundError as exc:
|
||||
raise BackupError("当前环境缺少 openssl,无法解密备份内容") from exc
|
||||
except subprocess.CalledProcessError as exc:
|
||||
detail = (exc.stderr or b"").decode("utf-8", errors="replace").strip()
|
||||
raise BackupError(f"解密备份失败:{detail or 'openssl 执行失败'}") from exc
|
||||
return result.stdout
|
||||
|
||||
|
||||
def _guess_content_type(name: str) -> str:
|
||||
if name.endswith(".json"):
|
||||
return "application/json"
|
||||
if name.endswith(".jsonl"):
|
||||
return "application/x-ndjson"
|
||||
if name.endswith(".tar.gz"):
|
||||
return "application/gzip"
|
||||
if name.endswith(".gz"):
|
||||
return "application/gzip"
|
||||
return "application/octet-stream"
|
||||
|
||||
|
||||
def _json_bytes(value: object) -> bytes:
|
||||
return json.dumps(value, ensure_ascii=False, indent=2).encode("utf-8")
|
||||
|
||||
|
||||
def _count_items(value: object) -> int:
|
||||
if isinstance(value, list):
|
||||
return len(value)
|
||||
if isinstance(value, dict):
|
||||
return len(value)
|
||||
return 0
|
||||
|
||||
|
||||
class BackupError(RuntimeError):
|
||||
pass
|
||||
|
||||
|
||||
class CloudflareR2Client:
|
||||
def __init__(self, settings: dict[str, object]) -> None:
|
||||
self.account_id = _clean(settings.get("account_id"))
|
||||
self.access_key_id = _clean(settings.get("access_key_id"))
|
||||
self.secret_access_key = _clean(settings.get("secret_access_key"))
|
||||
self.bucket = _clean(settings.get("bucket"))
|
||||
self.prefix = _clean(settings.get("prefix")) or "backups"
|
||||
self.session = requests.Session(impersonate="chrome", verify=True)
|
||||
|
||||
def validate(self) -> None:
|
||||
missing = []
|
||||
if not self.account_id:
|
||||
missing.append("Account ID")
|
||||
if not self.access_key_id:
|
||||
missing.append("Access Key ID")
|
||||
if not self.secret_access_key:
|
||||
missing.append("Secret Access Key")
|
||||
if not self.bucket:
|
||||
missing.append("Bucket")
|
||||
if missing:
|
||||
raise BackupError(f"R2 配置不完整:缺少 {'、'.join(missing)}")
|
||||
|
||||
@property
|
||||
def endpoint(self) -> str:
|
||||
return f"https://{self.account_id}.r2.cloudflarestorage.com"
|
||||
|
||||
def _aws_v4_headers(
|
||||
self,
|
||||
method: str,
|
||||
path: str,
|
||||
*,
|
||||
query: dict[str, str] | None = None,
|
||||
body: bytes = b"",
|
||||
extra_headers: dict[str, str] | None = None,
|
||||
) -> tuple[str, dict[str, str]]:
|
||||
now = _utc_now()
|
||||
amz_date = now.strftime("%Y%m%dT%H%M%SZ")
|
||||
date_stamp = now.strftime("%Y%m%d")
|
||||
encoded_query = urlencode(sorted((query or {}).items()))
|
||||
payload_hash = _sha256_hex(body)
|
||||
host = f"{self.account_id}.r2.cloudflarestorage.com"
|
||||
headers = {
|
||||
"host": host,
|
||||
"x-amz-content-sha256": payload_hash,
|
||||
"x-amz-date": amz_date,
|
||||
}
|
||||
if extra_headers:
|
||||
for key, value in extra_headers.items():
|
||||
headers[key.lower()] = value.strip()
|
||||
sorted_items = sorted((key.lower(), " ".join(str(value).strip().split())) for key, value in headers.items())
|
||||
canonical_headers = "".join(f"{key}:{value}\n" for key, value in sorted_items)
|
||||
signed_headers = ";".join(key for key, _ in sorted_items)
|
||||
canonical_request = "\n".join([
|
||||
method.upper(),
|
||||
path,
|
||||
encoded_query,
|
||||
canonical_headers,
|
||||
signed_headers,
|
||||
payload_hash,
|
||||
])
|
||||
credential_scope = f"{date_stamp}/auto/s3/aws4_request"
|
||||
string_to_sign = "\n".join([
|
||||
"AWS4-HMAC-SHA256",
|
||||
amz_date,
|
||||
credential_scope,
|
||||
_sha256_hex(canonical_request.encode("utf-8")),
|
||||
])
|
||||
k_date = _hmac_sha256(("AWS4" + self.secret_access_key).encode("utf-8"), date_stamp)
|
||||
k_region = hmac.new(k_date, b"auto", hashlib.sha256).digest()
|
||||
k_service = hmac.new(k_region, b"s3", hashlib.sha256).digest()
|
||||
k_signing = hmac.new(k_service, b"aws4_request", hashlib.sha256).digest()
|
||||
signature = hmac.new(k_signing, string_to_sign.encode("utf-8"), hashlib.sha256).hexdigest()
|
||||
authorization = (
|
||||
"AWS4-HMAC-SHA256 "
|
||||
f"Credential={self.access_key_id}/{credential_scope}, "
|
||||
f"SignedHeaders={signed_headers}, "
|
||||
f"Signature={signature}"
|
||||
)
|
||||
request_headers = {key: value for key, value in headers.items()}
|
||||
request_headers["authorization"] = authorization
|
||||
return encoded_query, request_headers
|
||||
|
||||
def _request(
|
||||
self,
|
||||
method: str,
|
||||
key: str = "",
|
||||
*,
|
||||
query: dict[str, str] | None = None,
|
||||
body: bytes = b"",
|
||||
extra_headers: dict[str, str] | None = None,
|
||||
timeout: float = 60.0,
|
||||
):
|
||||
object_path = f"/{self.bucket}"
|
||||
if key:
|
||||
object_path += f"/{quote(key.lstrip('/'), safe='/')}"
|
||||
encoded_query, headers = self._aws_v4_headers(method, object_path, query=query, body=body, extra_headers=extra_headers)
|
||||
url = f"{self.endpoint}{object_path}"
|
||||
if encoded_query:
|
||||
url += f"?{encoded_query}"
|
||||
response = self.session.request(method.upper(), url, headers=headers, data=body, timeout=timeout)
|
||||
return response
|
||||
|
||||
def test_connection(self) -> dict[str, object]:
|
||||
self.validate()
|
||||
response = self._request("GET", query={"list-type": "2", "max-keys": "1"}, timeout=30.0)
|
||||
if response.status_code >= 400:
|
||||
raise BackupError(f"连接 R2 失败:HTTP {response.status_code}")
|
||||
return {"ok": True, "status": int(response.status_code)}
|
||||
|
||||
def upload_bytes(self, key: str, payload: bytes, *, content_type: str, metadata: dict[str, str] | None = None) -> dict[str, object]:
|
||||
headers = {"content-type": content_type}
|
||||
if metadata:
|
||||
for item_key, item_value in metadata.items():
|
||||
headers[f"x-amz-meta-{item_key}"] = str(item_value)
|
||||
response = self._request("PUT", key, body=payload, extra_headers=headers)
|
||||
if response.status_code >= 400:
|
||||
raise BackupError(f"上传备份失败:HTTP {response.status_code}")
|
||||
return {"key": key, "etag": str(response.headers.get("etag") or "").strip('"')}
|
||||
|
||||
def delete_object(self, key: str) -> None:
|
||||
response = self._request("DELETE", key, timeout=30.0)
|
||||
if response.status_code >= 400 and response.status_code != 404:
|
||||
raise BackupError(f"删除备份失败:HTTP {response.status_code}")
|
||||
|
||||
def download_bytes(self, key: str) -> bytes:
|
||||
response = self._request("GET", key, timeout=60.0)
|
||||
if response.status_code >= 400:
|
||||
raise BackupError(f"读取备份失败:HTTP {response.status_code}")
|
||||
return bytes(response.content or b"")
|
||||
|
||||
def list_objects(self) -> list[dict[str, object]]:
|
||||
items: list[dict[str, object]] = []
|
||||
continuation = ""
|
||||
while True:
|
||||
query = {"list-type": "2", "prefix": f"{self.prefix.rstrip('/')}/", "max-keys": "1000"}
|
||||
if continuation:
|
||||
query["continuation-token"] = continuation
|
||||
response = self._request("GET", query=query, timeout=30.0)
|
||||
if response.status_code >= 400:
|
||||
raise BackupError(f"获取备份列表失败:HTTP {response.status_code}")
|
||||
text = response.text
|
||||
for block in text.split("<Contents>")[1:]:
|
||||
key = _clean(block.split("<Key>", 1)[1].split("</Key>", 1)[0]) if "<Key>" in block else ""
|
||||
if not key:
|
||||
continue
|
||||
size_text = _clean(block.split("<Size>", 1)[1].split("</Size>", 1)[0]) if "<Size>" in block else "0"
|
||||
updated = _clean(block.split("<LastModified>", 1)[1].split("</LastModified>", 1)[0]) if "<LastModified>" in block else ""
|
||||
items.append({
|
||||
"key": key,
|
||||
"size": int(size_text or 0),
|
||||
"updated_at": updated,
|
||||
})
|
||||
truncated = "<IsTruncated>true</IsTruncated>" in text
|
||||
if not truncated:
|
||||
break
|
||||
if "<NextContinuationToken>" not in text:
|
||||
break
|
||||
continuation = _clean(text.split("<NextContinuationToken>", 1)[1].split("</NextContinuationToken>", 1)[0])
|
||||
if not continuation:
|
||||
break
|
||||
items.sort(key=lambda item: str(item.get("updated_at") or ""), reverse=True)
|
||||
return items
|
||||
|
||||
def close(self) -> None:
|
||||
self.session.close()
|
||||
|
||||
|
||||
class BackupService:
|
||||
def __init__(self) -> None:
|
||||
self._lock = threading.RLock()
|
||||
self._stop_event = threading.Event()
|
||||
self._thread: threading.Thread | None = None
|
||||
self._running = False
|
||||
|
||||
def start(self) -> None:
|
||||
with self._lock:
|
||||
if self._thread and self._thread.is_alive():
|
||||
return
|
||||
self._stop_event.clear()
|
||||
self._thread = threading.Thread(target=self._run, daemon=True, name="r2-backup-scheduler")
|
||||
self._thread.start()
|
||||
|
||||
def stop(self) -> None:
|
||||
with self._lock:
|
||||
self._stop_event.set()
|
||||
thread = self._thread
|
||||
self._thread = None
|
||||
if thread and thread.is_alive():
|
||||
thread.join(timeout=2)
|
||||
|
||||
def _run(self) -> None:
|
||||
while not self._stop_event.is_set():
|
||||
try:
|
||||
self.run_scheduled_backup_if_needed()
|
||||
except Exception:
|
||||
pass
|
||||
self._stop_event.wait(30)
|
||||
|
||||
def run_scheduled_backup_if_needed(self) -> None:
|
||||
settings = config.get_backup_settings()
|
||||
if not settings.get("enabled"):
|
||||
return
|
||||
state = self.get_status()
|
||||
if state.get("running"):
|
||||
return
|
||||
interval_minutes = int(settings.get("interval_minutes") or 360)
|
||||
last_finished_raw = _clean(state.get("last_finished_at"))
|
||||
if last_finished_raw:
|
||||
try:
|
||||
last_finished = datetime.fromisoformat(last_finished_raw.replace("Z", "+00:00"))
|
||||
elapsed = (_utc_now() - last_finished.astimezone(UTC)).total_seconds()
|
||||
if elapsed < interval_minutes * 60:
|
||||
return
|
||||
except Exception:
|
||||
pass
|
||||
self.run_backup(trigger="schedule")
|
||||
|
||||
def get_status(self) -> dict[str, object]:
|
||||
return {
|
||||
**load_backup_state(),
|
||||
"running": self._running,
|
||||
}
|
||||
|
||||
def is_configured(self) -> bool:
|
||||
settings = config.get_backup_settings()
|
||||
return all([
|
||||
_clean(settings.get("account_id")),
|
||||
_clean(settings.get("access_key_id")),
|
||||
_clean(settings.get("secret_access_key")),
|
||||
_clean(settings.get("bucket")),
|
||||
])
|
||||
|
||||
def get_settings(self) -> dict[str, object]:
|
||||
settings = dict(config.get_backup_settings())
|
||||
settings["secret_access_key"] = "********" if _clean(settings.get("secret_access_key")) else ""
|
||||
settings["passphrase"] = "********" if _clean(settings.get("passphrase")) else ""
|
||||
return settings
|
||||
|
||||
def update_settings(self, payload: dict[str, object]) -> dict[str, object]:
|
||||
current = config.get_backup_settings()
|
||||
merged = dict(current)
|
||||
merged.update(dict(payload or {}))
|
||||
if "include" in payload and isinstance(payload.get("include"), dict):
|
||||
include = dict(current.get("include") or {})
|
||||
include.update(payload.get("include") or {})
|
||||
merged["include"] = include
|
||||
if payload.get("secret_access_key") == "********":
|
||||
merged["secret_access_key"] = current.get("secret_access_key")
|
||||
if payload.get("passphrase") == "********":
|
||||
merged["passphrase"] = current.get("passphrase")
|
||||
updated = config.update({"backup": merged})
|
||||
return dict(updated.get("backup") or {})
|
||||
|
||||
def test_connection(self) -> dict[str, object]:
|
||||
client = CloudflareR2Client(config.get_backup_settings())
|
||||
try:
|
||||
return client.test_connection()
|
||||
finally:
|
||||
client.close()
|
||||
|
||||
def list_backups(self) -> list[dict[str, object]]:
|
||||
if not self.is_configured():
|
||||
return []
|
||||
client = CloudflareR2Client(config.get_backup_settings())
|
||||
try:
|
||||
items = client.list_objects()
|
||||
finally:
|
||||
client.close()
|
||||
parsed: list[dict[str, object]] = []
|
||||
for item in items:
|
||||
key = _clean(item.get("key"))
|
||||
name = key.rsplit("/", 1)[-1]
|
||||
encrypted = name.endswith(".enc")
|
||||
parsed.append({
|
||||
"key": key,
|
||||
"name": name,
|
||||
"size": int(item.get("size") or 0),
|
||||
"updated_at": item.get("updated_at"),
|
||||
"encrypted": encrypted,
|
||||
})
|
||||
return parsed
|
||||
|
||||
def delete_backup(self, key: str) -> None:
|
||||
candidate = _clean(key)
|
||||
if not candidate:
|
||||
raise BackupError("备份对象 key 不能为空")
|
||||
client = CloudflareR2Client(config.get_backup_settings())
|
||||
try:
|
||||
client.delete_object(candidate)
|
||||
finally:
|
||||
client.close()
|
||||
|
||||
def download_backup(self, key: str) -> dict[str, object]:
|
||||
candidate = _clean(key)
|
||||
if not candidate:
|
||||
raise BackupError("备份对象 key 不能为空")
|
||||
client = CloudflareR2Client(config.get_backup_settings())
|
||||
try:
|
||||
payload = client.download_bytes(candidate)
|
||||
finally:
|
||||
client.close()
|
||||
name = candidate.rsplit("/", 1)[-1] or "backup.bin"
|
||||
if candidate.endswith(".enc"):
|
||||
passphrase = _clean(config.get_backup_settings().get("passphrase"))
|
||||
if not passphrase:
|
||||
raise BackupError("当前未配置加密口令,无法下载并解密已加密备份")
|
||||
payload = _openssl_decrypt(payload, passphrase)
|
||||
if name.endswith(".enc"):
|
||||
name = name[:-4] or "backup.tar.gz"
|
||||
return {
|
||||
"key": candidate,
|
||||
"name": name,
|
||||
"content_type": _guess_content_type(name),
|
||||
"payload": payload,
|
||||
"size": len(payload),
|
||||
}
|
||||
|
||||
def get_backup_detail(self, key: str) -> dict[str, object]:
|
||||
candidate = _clean(key)
|
||||
if not candidate:
|
||||
raise BackupError("备份对象 key 不能为空")
|
||||
client = CloudflareR2Client(config.get_backup_settings())
|
||||
try:
|
||||
payload = client.download_bytes(candidate)
|
||||
finally:
|
||||
client.close()
|
||||
detail = self._decode_backup_payload(candidate, payload)
|
||||
detail["key"] = candidate
|
||||
detail["name"] = candidate.rsplit("/", 1)[-1]
|
||||
detail["encrypted"] = candidate.endswith(".enc")
|
||||
return detail
|
||||
|
||||
def run_backup(self, *, trigger: str = "manual") -> dict[str, object]:
|
||||
with self._lock:
|
||||
current = self.get_status()
|
||||
if self._running:
|
||||
raise BackupError("当前已有备份任务正在执行")
|
||||
started_at = _iso_now()
|
||||
self._running = True
|
||||
save_backup_state({
|
||||
"last_started_at": started_at,
|
||||
"last_finished_at": current.get("last_finished_at"),
|
||||
"last_status": "idle",
|
||||
"last_error": None,
|
||||
"last_object_key": current.get("last_object_key"),
|
||||
})
|
||||
try:
|
||||
result = self._run_backup_once(trigger=trigger)
|
||||
save_backup_state({
|
||||
"last_started_at": started_at,
|
||||
"last_finished_at": _iso_now(),
|
||||
"last_status": "success",
|
||||
"last_error": None,
|
||||
"last_object_key": result["key"],
|
||||
})
|
||||
return result
|
||||
except Exception as exc:
|
||||
save_backup_state({
|
||||
"last_started_at": started_at,
|
||||
"last_finished_at": _iso_now(),
|
||||
"last_status": "error",
|
||||
"last_error": str(exc) or exc.__class__.__name__,
|
||||
"last_object_key": current.get("last_object_key"),
|
||||
})
|
||||
raise
|
||||
finally:
|
||||
self._running = False
|
||||
|
||||
def _run_backup_once(self, *, trigger: str) -> dict[str, object]:
|
||||
settings = config.get_backup_settings()
|
||||
client = CloudflareR2Client(settings)
|
||||
client.validate()
|
||||
payload_raw = self._build_backup_archive(settings, trigger=trigger)
|
||||
encrypted = bool(settings.get("encrypt"))
|
||||
if encrypted:
|
||||
passphrase = _clean(settings.get("passphrase"))
|
||||
if not passphrase:
|
||||
raise BackupError("已启用备份加密,但未设置加密口令")
|
||||
payload = _openssl_encrypt(payload_raw, passphrase)
|
||||
suffix = ".tar.gz.enc"
|
||||
else:
|
||||
payload = payload_raw
|
||||
suffix = ".tar.gz"
|
||||
timestamp = _utc_now().strftime("%Y%m%dT%H%M%SZ")
|
||||
random_tag = f"{random.randint(0, 0xFFFF):04x}"
|
||||
object_key = f"{client.prefix.rstrip('/')}/backup-{timestamp}-{random_tag}{suffix}"
|
||||
metadata = {
|
||||
"created-at": _iso_now(),
|
||||
"encrypted": "true" if encrypted else "false",
|
||||
"trigger": trigger,
|
||||
}
|
||||
try:
|
||||
result = client.upload_bytes(object_key, payload, content_type="application/octet-stream", metadata=metadata)
|
||||
self._apply_rotation(client, int(settings.get("rotation_keep") or 0))
|
||||
return {
|
||||
"key": result["key"],
|
||||
"size": len(payload),
|
||||
"encrypted": encrypted,
|
||||
}
|
||||
finally:
|
||||
client.close()
|
||||
|
||||
def _decode_backup_payload(self, key: str, payload: bytes) -> dict[str, object]:
|
||||
decoded = payload
|
||||
if key.endswith(".enc"):
|
||||
passphrase = _clean(config.get_backup_settings().get("passphrase"))
|
||||
if not passphrase:
|
||||
raise BackupError("当前未配置加密口令,无法查看已加密备份")
|
||||
decoded = _openssl_decrypt(decoded, passphrase)
|
||||
return self._decode_archive_detail(decoded)
|
||||
|
||||
def _apply_rotation(self, client: CloudflareR2Client, keep: int) -> None:
|
||||
if keep <= 0:
|
||||
return
|
||||
items = [item for item in client.list_objects() if _is_backup_object(item.get("key"))]
|
||||
if len(items) <= keep:
|
||||
return
|
||||
for item in items[keep:]:
|
||||
key = _clean(item.get("key"))
|
||||
if key:
|
||||
client.delete_object(key)
|
||||
|
||||
def _decode_archive_detail(self, payload: bytes) -> dict[str, object]:
|
||||
files: list[dict[str, object]] = []
|
||||
snapshots: list[dict[str, object]] = []
|
||||
metadata: dict[str, object] = {}
|
||||
try:
|
||||
with tarfile.open(fileobj=io.BytesIO(payload), mode="r:gz") as archive:
|
||||
members = [member for member in archive.getmembers() if member.isfile()]
|
||||
for member in members:
|
||||
extracted = archive.extractfile(member)
|
||||
if extracted is None:
|
||||
continue
|
||||
raw = extracted.read()
|
||||
name = member.name
|
||||
if name == "backup-metadata.json":
|
||||
try:
|
||||
parsed = json.loads(raw.decode("utf-8"))
|
||||
if isinstance(parsed, dict):
|
||||
metadata = parsed
|
||||
except Exception:
|
||||
metadata = {}
|
||||
continue
|
||||
if name.startswith("snapshots/") and name.endswith(".json"):
|
||||
count = 0
|
||||
try:
|
||||
parsed_snapshot = json.loads(raw.decode("utf-8"))
|
||||
count = _count_items(parsed_snapshot)
|
||||
except Exception:
|
||||
count = 0
|
||||
snapshots.append({
|
||||
"name": name.removeprefix("snapshots/").removesuffix(".json"),
|
||||
"count": count,
|
||||
})
|
||||
continue
|
||||
files.append({
|
||||
"name": name,
|
||||
"exists": True,
|
||||
"content_type": _guess_content_type(name),
|
||||
"size": len(raw),
|
||||
"sha256": _sha256_hex(raw),
|
||||
})
|
||||
except tarfile.TarError as exc:
|
||||
raise BackupError("解析备份压缩包失败,备份可能已损坏") from exc
|
||||
files.sort(key=lambda item: str(item.get("name") or ""))
|
||||
snapshots.sort(key=lambda item: str(item.get("name") or ""))
|
||||
return {
|
||||
"created_at": metadata.get("created_at"),
|
||||
"trigger": metadata.get("trigger"),
|
||||
"app_version": metadata.get("app_version"),
|
||||
"storage_backend": metadata.get("storage_backend"),
|
||||
"files": files,
|
||||
"snapshots": snapshots,
|
||||
}
|
||||
|
||||
def _build_backup_archive(self, settings: dict[str, object], *, trigger: str) -> bytes:
|
||||
include = settings.get("include") if isinstance(settings.get("include"), dict) else {}
|
||||
metadata = {
|
||||
"version": 2,
|
||||
"created_at": _iso_now(),
|
||||
"trigger": trigger,
|
||||
"app_version": config.app_version,
|
||||
"storage_backend": config.get_storage_backend().get_backend_info(),
|
||||
}
|
||||
buffer = io.BytesIO()
|
||||
with tarfile.open(fileobj=buffer, mode="w:gz") as archive:
|
||||
self._add_bytes_to_archive(archive, "backup-metadata.json", _json_bytes(metadata))
|
||||
if include.get("config"):
|
||||
self._add_file_to_archive(archive, CONFIG_FILE, "config.json")
|
||||
if include.get("cpa"):
|
||||
self._add_file_to_archive(archive, DATA_DIR / "cpa_config.json", "data/cpa_config.json")
|
||||
if include.get("sub2api"):
|
||||
self._add_file_to_archive(archive, DATA_DIR / "sub2api_config.json", "data/sub2api_config.json")
|
||||
if include.get("logs"):
|
||||
self._add_file_to_archive(archive, DATA_DIR / "logs.jsonl", "data/logs.jsonl")
|
||||
if include.get("image_tasks"):
|
||||
self._add_file_to_archive(archive, DATA_DIR / "image_tasks.json", "data/image_tasks.json")
|
||||
self._add_file_to_archive(archive, IMAGE_INDEX_FILE, "data/image_index.json")
|
||||
if include.get("accounts_snapshot"):
|
||||
self._add_bytes_to_archive(
|
||||
archive,
|
||||
"snapshots/accounts.json",
|
||||
_json_bytes(config.get_storage_backend().load_accounts()),
|
||||
)
|
||||
if include.get("auth_keys_snapshot"):
|
||||
self._add_bytes_to_archive(
|
||||
archive,
|
||||
"snapshots/auth_keys.json",
|
||||
_json_bytes(config.get_storage_backend().load_auth_keys()),
|
||||
)
|
||||
if include.get("images"):
|
||||
self._add_file_to_archive(archive, TAGS_FILE, "data/image_tags.json")
|
||||
self._add_directory_to_archive(archive, config.images_dir, "data/images")
|
||||
return buffer.getvalue()
|
||||
|
||||
def _add_bytes_to_archive(self, archive: tarfile.TarFile, name: str, payload: bytes) -> None:
|
||||
info = tarfile.TarInfo(name=name)
|
||||
info.size = len(payload)
|
||||
info.mtime = int(_utc_now().timestamp())
|
||||
archive.addfile(info, io.BytesIO(payload))
|
||||
|
||||
def _add_file_to_archive(self, archive: tarfile.TarFile, source: Path, arcname: str) -> None:
|
||||
if not source.exists() or not source.is_file():
|
||||
return
|
||||
archive.add(source, arcname=arcname)
|
||||
|
||||
def _add_directory_to_archive(self, archive: tarfile.TarFile, source_dir: Path, arcname_root: str) -> None:
|
||||
if not source_dir.exists() or not source_dir.is_dir():
|
||||
return
|
||||
for path in sorted(source_dir.rglob("*")):
|
||||
if path.is_file():
|
||||
relative = path.relative_to(source_dir).as_posix()
|
||||
archive.add(path, arcname=f"{arcname_root}/{relative}")
|
||||
|
||||
|
||||
backup_service = BackupService()
|
||||
@@ -0,0 +1,667 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import copy
|
||||
from dataclasses import dataclass
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
from pathlib import Path
|
||||
import time
|
||||
|
||||
from services.storage.base import StorageBackend
|
||||
|
||||
BASE_DIR = Path(__file__).resolve().parents[1]
|
||||
DATA_DIR = BASE_DIR / "data"
|
||||
CONFIG_FILE = BASE_DIR / "config.json"
|
||||
VERSION_FILE = BASE_DIR / "VERSION"
|
||||
BACKUP_STATE_FILE = DATA_DIR / "backup_state.json"
|
||||
|
||||
DEFAULT_BACKUP_INCLUDE = {
|
||||
"config": True,
|
||||
"cpa": True,
|
||||
"sub2api": True,
|
||||
"logs": True,
|
||||
"image_tasks": True,
|
||||
"accounts_snapshot": True,
|
||||
"auth_keys_snapshot": True,
|
||||
"images": False,
|
||||
}
|
||||
|
||||
DEFAULT_IMAGE_STORAGE = {
|
||||
"enabled": False,
|
||||
"mode": "local",
|
||||
"webdav_url": "",
|
||||
"webdav_username": "",
|
||||
"webdav_password": "",
|
||||
"webdav_root_path": "chatgpt2api/images",
|
||||
"public_base_url": "",
|
||||
}
|
||||
|
||||
DEFAULT_CHAT_COMPLETION_CACHE = {
|
||||
"enabled": True,
|
||||
"ttl_seconds": 60,
|
||||
"max_entries": 256,
|
||||
"dedupe_inflight": True,
|
||||
"stream_cache": True,
|
||||
"normalize_messages": True,
|
||||
"drop_adjacent_duplicates": True,
|
||||
"drop_assistant_history": False,
|
||||
}
|
||||
|
||||
DEFAULT_PROXY_RUNTIME_USER_AGENT = (
|
||||
"Mozilla/5.0 (Windows NT 10.0; Win64; x64) "
|
||||
"AppleWebKit/537.36 (KHTML, like Gecko) "
|
||||
"Chrome/145.0.0.0 Safari/537.36"
|
||||
)
|
||||
|
||||
DEFAULT_PROXY_RUNTIME = {
|
||||
"enabled": False,
|
||||
"egress_mode": "direct",
|
||||
"proxy_url": "",
|
||||
"resource_proxy_url": "",
|
||||
"skip_ssl_verify": False,
|
||||
"reset_session_status_codes": [403],
|
||||
"clearance": {
|
||||
"enabled": False,
|
||||
"mode": "none",
|
||||
"cf_cookies": "",
|
||||
"cf_clearance": "",
|
||||
"user_agent": DEFAULT_PROXY_RUNTIME_USER_AGENT,
|
||||
"browser": "chrome",
|
||||
"flaresolverr_url": "",
|
||||
"timeout_sec": 60,
|
||||
"refresh_interval": 3600,
|
||||
"warm_up_on_start": False,
|
||||
},
|
||||
}
|
||||
|
||||
DEFAULT_THIRD_PARTY_APPS = {
|
||||
"infinite_canvas": {
|
||||
"enabled": False,
|
||||
"url": "https://canvas.best",
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def _normalize_bool(value: object, default: bool = False) -> bool:
|
||||
if isinstance(value, str):
|
||||
lowered = value.strip().lower()
|
||||
if lowered in {"1", "true", "yes", "on"}:
|
||||
return True
|
||||
if lowered in {"0", "false", "no", "off"}:
|
||||
return False
|
||||
return default
|
||||
if value is None:
|
||||
return default
|
||||
return bool(value)
|
||||
|
||||
|
||||
def _normalize_positive_int(value: object, default: int, minimum: int = 0) -> int:
|
||||
try:
|
||||
normalized = int(value)
|
||||
except (OverflowError, TypeError, ValueError):
|
||||
normalized = default
|
||||
return max(minimum, normalized)
|
||||
|
||||
|
||||
def _normalize_backup_include(value: object) -> dict[str, bool]:
|
||||
source = value if isinstance(value, dict) else {}
|
||||
normalized = dict(DEFAULT_BACKUP_INCLUDE)
|
||||
for key in normalized:
|
||||
normalized[key] = _normalize_bool(source.get(key), normalized[key])
|
||||
return normalized
|
||||
|
||||
|
||||
def _normalize_backup_settings(value: object) -> dict[str, object]:
|
||||
source = value if isinstance(value, dict) else {}
|
||||
return {
|
||||
"enabled": _normalize_bool(source.get("enabled"), False),
|
||||
"provider": "cloudflare_r2",
|
||||
"account_id": str(source.get("account_id") or "").strip(),
|
||||
"access_key_id": str(source.get("access_key_id") or "").strip(),
|
||||
"secret_access_key": str(source.get("secret_access_key") or "").strip(),
|
||||
"bucket": str(source.get("bucket") or "").strip(),
|
||||
"prefix": str(source.get("prefix") or "backups").strip().strip("/") or "backups",
|
||||
"interval_minutes": _normalize_positive_int(source.get("interval_minutes"), 360, 1),
|
||||
"rotation_keep": _normalize_positive_int(source.get("rotation_keep"), 10, 0),
|
||||
"encrypt": _normalize_bool(source.get("encrypt"), False),
|
||||
"passphrase": str(source.get("passphrase") or "").strip(),
|
||||
"include": _normalize_backup_include(source.get("include")),
|
||||
}
|
||||
|
||||
|
||||
def _normalize_backup_state(value: object) -> dict[str, object]:
|
||||
source = value if isinstance(value, dict) else {}
|
||||
return {
|
||||
"last_started_at": str(source.get("last_started_at") or "").strip() or None,
|
||||
"last_finished_at": str(source.get("last_finished_at") or "").strip() or None,
|
||||
"last_status": str(source.get("last_status") or "idle").strip() or "idle",
|
||||
"last_error": str(source.get("last_error") or "").strip() or None,
|
||||
"last_object_key": str(source.get("last_object_key") or "").strip() or None,
|
||||
}
|
||||
|
||||
|
||||
def _normalize_image_storage_settings(value: object) -> dict[str, object]:
|
||||
source = value if isinstance(value, dict) else {}
|
||||
mode = str(source.get("mode") or "local").strip().lower()
|
||||
if mode not in {"local", "webdav", "both"}:
|
||||
mode = "local"
|
||||
enabled = _normalize_bool(source.get("enabled"), False)
|
||||
if not enabled:
|
||||
mode = "local"
|
||||
root_path = str(source.get("webdav_root_path") or DEFAULT_IMAGE_STORAGE["webdav_root_path"]).strip().strip("/")
|
||||
return {
|
||||
"enabled": enabled,
|
||||
"mode": mode,
|
||||
"webdav_url": str(source.get("webdav_url") or "").strip().rstrip("/"),
|
||||
"webdav_username": str(source.get("webdav_username") or "").strip(),
|
||||
"webdav_password": str(source.get("webdav_password") or "").strip(),
|
||||
"webdav_root_path": root_path or str(DEFAULT_IMAGE_STORAGE["webdav_root_path"]),
|
||||
"public_base_url": str(source.get("public_base_url") or "").strip().rstrip("/"),
|
||||
}
|
||||
|
||||
|
||||
def _normalize_chat_completion_cache_settings(value: object) -> dict[str, object]:
|
||||
source = value if isinstance(value, dict) else {}
|
||||
return {
|
||||
"enabled": _normalize_bool(source.get("enabled"), DEFAULT_CHAT_COMPLETION_CACHE["enabled"]),
|
||||
"ttl_seconds": _normalize_positive_int(
|
||||
source.get("ttl_seconds"),
|
||||
int(DEFAULT_CHAT_COMPLETION_CACHE["ttl_seconds"]),
|
||||
0,
|
||||
),
|
||||
"max_entries": _normalize_positive_int(
|
||||
source.get("max_entries"),
|
||||
int(DEFAULT_CHAT_COMPLETION_CACHE["max_entries"]),
|
||||
1,
|
||||
),
|
||||
"dedupe_inflight": _normalize_bool(
|
||||
source.get("dedupe_inflight"),
|
||||
bool(DEFAULT_CHAT_COMPLETION_CACHE["dedupe_inflight"]),
|
||||
),
|
||||
"stream_cache": _normalize_bool(
|
||||
source.get("stream_cache"),
|
||||
bool(DEFAULT_CHAT_COMPLETION_CACHE["stream_cache"]),
|
||||
),
|
||||
"normalize_messages": _normalize_bool(
|
||||
source.get("normalize_messages"),
|
||||
bool(DEFAULT_CHAT_COMPLETION_CACHE["normalize_messages"]),
|
||||
),
|
||||
"drop_adjacent_duplicates": _normalize_bool(
|
||||
source.get("drop_adjacent_duplicates"),
|
||||
bool(DEFAULT_CHAT_COMPLETION_CACHE["drop_adjacent_duplicates"]),
|
||||
),
|
||||
"drop_assistant_history": _normalize_bool(
|
||||
source.get("drop_assistant_history"),
|
||||
bool(DEFAULT_CHAT_COMPLETION_CACHE["drop_assistant_history"]),
|
||||
),
|
||||
}
|
||||
|
||||
|
||||
def _normalize_status_codes(value: object) -> list[int]:
|
||||
items = value if isinstance(value, list) else DEFAULT_PROXY_RUNTIME["reset_session_status_codes"]
|
||||
normalized: list[int] = []
|
||||
for item in items:
|
||||
if isinstance(item, bool):
|
||||
continue
|
||||
try:
|
||||
status = int(item)
|
||||
except (OverflowError, TypeError, ValueError):
|
||||
continue
|
||||
if 100 <= status <= 599 and status not in normalized:
|
||||
normalized.append(status)
|
||||
if not normalized:
|
||||
return list(DEFAULT_PROXY_RUNTIME["reset_session_status_codes"])
|
||||
return normalized
|
||||
|
||||
|
||||
def _normalize_proxy_runtime_settings(value: object) -> dict[str, object]:
|
||||
source = value if isinstance(value, dict) else {}
|
||||
default_clearance = DEFAULT_PROXY_RUNTIME["clearance"]
|
||||
clearance_source = source.get("clearance") if isinstance(source.get("clearance"), dict) else {}
|
||||
|
||||
egress_mode = str(source.get("egress_mode") or DEFAULT_PROXY_RUNTIME["egress_mode"]).strip().lower()
|
||||
if egress_mode not in {"direct", "single_proxy"}:
|
||||
egress_mode = str(DEFAULT_PROXY_RUNTIME["egress_mode"])
|
||||
|
||||
clearance_mode = str(clearance_source.get("mode") or default_clearance["mode"]).strip().lower()
|
||||
if clearance_mode not in {"none", "manual", "flaresolverr"}:
|
||||
clearance_mode = str(default_clearance["mode"])
|
||||
|
||||
user_agent = str(clearance_source.get("user_agent") or default_clearance["user_agent"]).strip()
|
||||
browser = str(clearance_source.get("browser") or default_clearance["browser"]).strip()
|
||||
|
||||
existing_clearance_cookies = str(source.get("_existing_cf_cookies") or "").strip()
|
||||
existing_cf_clearance = str(source.get("_existing_cf_clearance") or "").strip()
|
||||
cf_cookies = str(clearance_source.get("cf_cookies") or "").strip()
|
||||
cf_clearance = str(clearance_source.get("cf_clearance") or "").strip()
|
||||
if not cf_cookies and _normalize_bool(clearance_source.get("has_cf_cookies"), False):
|
||||
cf_cookies = existing_clearance_cookies
|
||||
if not cf_clearance and _normalize_bool(clearance_source.get("has_cf_clearance"), False):
|
||||
cf_clearance = existing_cf_clearance
|
||||
|
||||
return {
|
||||
"enabled": _normalize_bool(source.get("enabled"), bool(DEFAULT_PROXY_RUNTIME["enabled"])),
|
||||
"egress_mode": egress_mode,
|
||||
"proxy_url": str(source.get("proxy_url") or "").strip(),
|
||||
"resource_proxy_url": str(source.get("resource_proxy_url") or "").strip(),
|
||||
"skip_ssl_verify": _normalize_bool(
|
||||
source.get("skip_ssl_verify"),
|
||||
bool(DEFAULT_PROXY_RUNTIME["skip_ssl_verify"]),
|
||||
),
|
||||
"reset_session_status_codes": _normalize_status_codes(source.get("reset_session_status_codes")),
|
||||
"clearance": {
|
||||
"enabled": _normalize_bool(clearance_source.get("enabled"), bool(default_clearance["enabled"])),
|
||||
"mode": clearance_mode,
|
||||
"cf_cookies": cf_cookies,
|
||||
"cf_clearance": cf_clearance,
|
||||
"user_agent": user_agent or str(default_clearance["user_agent"]),
|
||||
"browser": browser or str(default_clearance["browser"]),
|
||||
"flaresolverr_url": str(clearance_source.get("flaresolverr_url") or "").strip(),
|
||||
"timeout_sec": _normalize_positive_int(
|
||||
clearance_source.get("timeout_sec"),
|
||||
int(default_clearance["timeout_sec"]),
|
||||
1,
|
||||
),
|
||||
"refresh_interval": _normalize_positive_int(
|
||||
clearance_source.get("refresh_interval"),
|
||||
int(default_clearance["refresh_interval"]),
|
||||
60,
|
||||
),
|
||||
"warm_up_on_start": _normalize_bool(
|
||||
clearance_source.get("warm_up_on_start"),
|
||||
bool(default_clearance["warm_up_on_start"]),
|
||||
),
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def _normalize_third_party_apps_settings(value: object) -> dict[str, object]:
|
||||
source = value if isinstance(value, dict) else {}
|
||||
canvas_source = source.get("infinite_canvas") if isinstance(source.get("infinite_canvas"), dict) else {}
|
||||
return {
|
||||
"infinite_canvas": {
|
||||
"enabled": _normalize_bool(canvas_source.get("enabled"), False),
|
||||
"url": str(canvas_source.get("url") or DEFAULT_THIRD_PARTY_APPS["infinite_canvas"]["url"]).strip(),
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def _validate_image_storage_settings(settings: dict[str, object]) -> None:
|
||||
if not _normalize_bool(settings.get("enabled"), False):
|
||||
return
|
||||
if not str(settings.get("webdav_url") or "").strip():
|
||||
raise ValueError("启用 WebDAV 图片存储后必须填写 WebDAV URL")
|
||||
if not str(settings.get("webdav_password") or "").strip():
|
||||
raise ValueError("启用 WebDAV 图片存储后必须填写 WebDAV 密码")
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class LoadedSettings:
|
||||
auth_key: str
|
||||
refresh_account_interval_minute: int
|
||||
|
||||
|
||||
def _normalize_auth_key(value: object) -> str:
|
||||
return str(value or "").strip()
|
||||
|
||||
|
||||
def _is_invalid_auth_key(value: object) -> bool:
|
||||
return _normalize_auth_key(value) == ""
|
||||
|
||||
|
||||
def _read_json_object(path: Path, *, name: str) -> dict[str, object]:
|
||||
if not path.exists():
|
||||
return {}
|
||||
if path.is_dir():
|
||||
print(
|
||||
f"Warning: {name} at '{path}' is a directory, ignoring it and falling back to other configuration sources.",
|
||||
file=sys.stderr,
|
||||
)
|
||||
return {}
|
||||
try:
|
||||
data = json.loads(path.read_text(encoding="utf-8"))
|
||||
except Exception:
|
||||
return {}
|
||||
return data if isinstance(data, dict) else {}
|
||||
|
||||
|
||||
def _load_settings() -> LoadedSettings:
|
||||
DATA_DIR.mkdir(parents=True, exist_ok=True)
|
||||
raw_config = _read_json_object(CONFIG_FILE, name="config.json")
|
||||
auth_key = _normalize_auth_key(os.getenv("CHATGPT2API_AUTH_KEY") or raw_config.get("auth-key"))
|
||||
if _is_invalid_auth_key(auth_key):
|
||||
raise ValueError(
|
||||
"❌ auth-key 未设置!\n"
|
||||
"请在环境变量 CHATGPT2API_AUTH_KEY 中设置,或者在 config.json 中填写 auth-key。"
|
||||
)
|
||||
|
||||
try:
|
||||
refresh_interval = int(raw_config.get("refresh_account_interval_minute", 5))
|
||||
except (TypeError, ValueError):
|
||||
refresh_interval = 5
|
||||
|
||||
return LoadedSettings(
|
||||
auth_key=auth_key,
|
||||
refresh_account_interval_minute=refresh_interval,
|
||||
)
|
||||
|
||||
|
||||
class ConfigStore:
|
||||
def __init__(self, path: Path):
|
||||
self.path = path
|
||||
DATA_DIR.mkdir(parents=True, exist_ok=True)
|
||||
self.data = self._load()
|
||||
self._storage_backend: StorageBackend | None = None
|
||||
if _is_invalid_auth_key(self.auth_key):
|
||||
raise ValueError(
|
||||
"❌ auth-key 未设置!\n"
|
||||
"请按以下任意一种方式解决:\n"
|
||||
"1. 在 Render 的 Environment 变量中添加:\n"
|
||||
" CHATGPT2API_AUTH_KEY = your_real_auth_key\n"
|
||||
"2. 或者在 config.json 中填写:\n"
|
||||
' "auth-key": "your_real_auth_key"'
|
||||
)
|
||||
|
||||
def _load(self) -> dict[str, object]:
|
||||
return _read_json_object(self.path, name="config.json")
|
||||
|
||||
def _save(self) -> None:
|
||||
self.path.write_text(json.dumps(self.data, ensure_ascii=False, indent=2) + "\n", encoding="utf-8")
|
||||
|
||||
@property
|
||||
def auth_key(self) -> str:
|
||||
return _normalize_auth_key(os.getenv("CHATGPT2API_AUTH_KEY") or self.data.get("auth-key"))
|
||||
|
||||
@property
|
||||
def accounts_file(self) -> Path:
|
||||
return DATA_DIR / "accounts.json"
|
||||
|
||||
@property
|
||||
def refresh_account_interval_minute(self) -> int:
|
||||
try:
|
||||
return int(self.data.get("refresh_account_interval_minute", 5))
|
||||
except (TypeError, ValueError):
|
||||
return 5
|
||||
|
||||
@property
|
||||
def image_retention_days(self) -> int:
|
||||
try:
|
||||
return max(1, int(self.data.get("image_retention_days", 30)))
|
||||
except (TypeError, ValueError):
|
||||
return 30
|
||||
|
||||
@property
|
||||
def image_poll_timeout_secs(self) -> int:
|
||||
try:
|
||||
return max(1, int(self.data.get("image_poll_timeout_secs", 120)))
|
||||
except (TypeError, ValueError):
|
||||
return 120
|
||||
|
||||
@property
|
||||
def image_poll_interval_secs(self) -> float:
|
||||
try:
|
||||
return max(0.5, float(self.data.get("image_poll_interval_secs", 10.0)))
|
||||
except (TypeError, ValueError):
|
||||
return 10.0
|
||||
|
||||
@property
|
||||
def image_poll_initial_wait_secs(self) -> float:
|
||||
"""Image generation upstream takes ~30s; polling immediately wastes requests
|
||||
and trips a transient 429. Default 10s gives the conversation document time
|
||||
to commit before the first poll."""
|
||||
try:
|
||||
return max(0.0, float(self.data.get("image_poll_initial_wait_secs", 10.0)))
|
||||
except (TypeError, ValueError):
|
||||
return 10.0
|
||||
|
||||
@property
|
||||
def image_account_concurrency(self) -> int:
|
||||
try:
|
||||
return max(1, int(self.data.get("image_account_concurrency", 3)))
|
||||
except (TypeError, ValueError):
|
||||
return 3
|
||||
|
||||
@property
|
||||
def image_parallel_generation(self) -> bool:
|
||||
value = self.data.get("image_parallel_generation", True)
|
||||
if isinstance(value, str):
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
return bool(value)
|
||||
|
||||
@property
|
||||
def image_settle_enabled(self) -> bool:
|
||||
"""图片二次确认机制:找到 file_ids 后等待一段时间再次确认。"""
|
||||
value = self.data.get("image_settle_enabled", True)
|
||||
if isinstance(value, str):
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
return bool(value)
|
||||
|
||||
@property
|
||||
def image_check_before_hit_enabled(self) -> bool:
|
||||
"""先check再hit:通过轮询确认 file_ids 存在后再返回,而非仅依赖 SSE 事件。"""
|
||||
value = self.data.get("image_check_before_hit_enabled", True)
|
||||
if isinstance(value, str):
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
return bool(value)
|
||||
|
||||
@property
|
||||
def image_remove_conversation_after_result(self) -> bool:
|
||||
"""出图成功后异步隐藏 ChatGPT 本地对话记录。"""
|
||||
value = self.data.get("image_remove_conversation_after_result", False)
|
||||
if isinstance(value, str):
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
return bool(value)
|
||||
|
||||
@property
|
||||
def image_remove_conversation_always(self) -> bool:
|
||||
"""无论是否出图,画图请求结束后都异步隐藏 ChatGPT 本地对话记录。"""
|
||||
return _normalize_bool(self.data.get("image_remove_conversation_always"), False)
|
||||
|
||||
@property
|
||||
def image_settle_secs(self) -> float:
|
||||
"""二次确认等待时间(秒)。"""
|
||||
try:
|
||||
return max(0.5, float(self.data.get("image_settle_secs", 2.0)))
|
||||
except (TypeError, ValueError):
|
||||
return 2.0
|
||||
|
||||
@property
|
||||
def auto_remove_invalid_accounts(self) -> bool:
|
||||
value = self.data.get("auto_remove_invalid_accounts", False)
|
||||
if isinstance(value, str):
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
return bool(value)
|
||||
|
||||
@property
|
||||
def auto_remove_rate_limited_accounts(self) -> bool:
|
||||
value = self.data.get("auto_remove_rate_limited_accounts", False)
|
||||
if isinstance(value, str):
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
return bool(value)
|
||||
|
||||
@property
|
||||
def auto_relogin_after_refresh(self) -> bool:
|
||||
value = self.data.get("auto_relogin_after_refresh", False)
|
||||
if isinstance(value, str):
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
return bool(value)
|
||||
|
||||
@property
|
||||
def log_levels(self) -> list[str]:
|
||||
levels = self.data.get("log_levels")
|
||||
if not isinstance(levels, list):
|
||||
return []
|
||||
allowed = {"debug", "info", "warning", "error"}
|
||||
return [level for item in levels if (level := str(item or "").strip().lower()) in allowed]
|
||||
|
||||
@property
|
||||
def sensitive_words(self) -> list[str]:
|
||||
words = self.data.get("sensitive_words")
|
||||
return [word for item in words if (word := str(item or "").strip())] if isinstance(words, list) else []
|
||||
|
||||
@property
|
||||
def ai_review(self) -> dict[str, object]:
|
||||
value = self.data.get("ai_review")
|
||||
return value if isinstance(value, dict) else {}
|
||||
|
||||
@property
|
||||
def global_system_prompt(self) -> str:
|
||||
return str(self.data.get("global_system_prompt") or "").strip()
|
||||
|
||||
@property
|
||||
def default_upstream_model_name(self) -> str:
|
||||
return str(self.data.get("default_upstream_model_name") or "gpt-5-5").strip()
|
||||
|
||||
@property
|
||||
def default_thinking_effort(self) -> str:
|
||||
value = str(self.data.get("default_thinking_effort") or "auto").strip().lower()
|
||||
return value if value in {"auto", "standard", "extended", "max"} else "auto"
|
||||
|
||||
@property
|
||||
def images_dir(self) -> Path:
|
||||
path = DATA_DIR / "images"
|
||||
path.mkdir(parents=True, exist_ok=True)
|
||||
return path
|
||||
|
||||
@property
|
||||
def image_thumbnails_dir(self) -> Path:
|
||||
path = DATA_DIR / "image_thumbnails"
|
||||
path.mkdir(parents=True, exist_ok=True)
|
||||
return path
|
||||
|
||||
def cleanup_old_images(self) -> int:
|
||||
cutoff = time.time() - self.image_retention_days * 86400
|
||||
removed = 0
|
||||
for path in self.images_dir.rglob("*"):
|
||||
if path.is_file() and path.stat().st_mtime < cutoff:
|
||||
path.unlink()
|
||||
removed += 1
|
||||
for path in sorted((p for p in self.images_dir.rglob("*") if p.is_dir()), key=lambda p: len(p.parts), reverse=True):
|
||||
try:
|
||||
path.rmdir()
|
||||
except OSError:
|
||||
pass
|
||||
return removed
|
||||
|
||||
@property
|
||||
def base_url(self) -> str:
|
||||
return str(
|
||||
os.getenv("CHATGPT2API_BASE_URL")
|
||||
or self.data.get("base_url")
|
||||
or ""
|
||||
).strip().rstrip("/")
|
||||
|
||||
@property
|
||||
def app_version(self) -> str:
|
||||
try:
|
||||
value = VERSION_FILE.read_text(encoding="utf-8").strip()
|
||||
except FileNotFoundError:
|
||||
return "0.0.0"
|
||||
return value or "0.0.0"
|
||||
|
||||
def get(self) -> dict[str, object]:
|
||||
data = dict(self.data)
|
||||
data["refresh_account_interval_minute"] = self.refresh_account_interval_minute
|
||||
data["image_retention_days"] = self.image_retention_days
|
||||
data["image_poll_timeout_secs"] = self.image_poll_timeout_secs
|
||||
data["image_poll_interval_secs"] = self.image_poll_interval_secs
|
||||
data["image_poll_initial_wait_secs"] = self.image_poll_initial_wait_secs
|
||||
data["image_account_concurrency"] = self.image_account_concurrency
|
||||
data["image_parallel_generation"] = self.image_parallel_generation
|
||||
data["image_remove_conversation_after_result"] = self.image_remove_conversation_after_result
|
||||
data["image_remove_conversation_always"] = self.image_remove_conversation_always
|
||||
data["auto_remove_invalid_accounts"] = self.auto_remove_invalid_accounts
|
||||
data["auto_remove_rate_limited_accounts"] = self.auto_remove_rate_limited_accounts
|
||||
data["auto_relogin_after_refresh"] = self.auto_relogin_after_refresh
|
||||
data["log_levels"] = self.log_levels
|
||||
data["sensitive_words"] = self.sensitive_words
|
||||
data["ai_review"] = self.ai_review
|
||||
data["global_system_prompt"] = self.global_system_prompt
|
||||
data["default_upstream_model_name"] = self.default_upstream_model_name
|
||||
data["default_thinking_effort"] = self.default_thinking_effort
|
||||
data["backup"] = self.get_backup_settings()
|
||||
data["image_storage"] = self.get_image_storage_settings()
|
||||
data["chat_completion_cache"] = self.get_chat_completion_cache_settings()
|
||||
data["proxy_runtime"] = self.get_public_proxy_runtime_settings()
|
||||
data["third_party_apps"] = self.get_third_party_apps_settings()
|
||||
data.pop("auth-key", None)
|
||||
return data
|
||||
|
||||
def get_proxy_settings(self) -> str:
|
||||
return str(self.data.get("proxy") or "").strip()
|
||||
|
||||
def get_proxy_runtime_settings(self) -> dict[str, object]:
|
||||
return _normalize_proxy_runtime_settings(self.data.get("proxy_runtime"))
|
||||
|
||||
def get_public_proxy_runtime_settings(self) -> dict[str, object]:
|
||||
runtime = copy.deepcopy(self.get_proxy_runtime_settings())
|
||||
clearance = runtime.get("clearance") if isinstance(runtime.get("clearance"), dict) else {}
|
||||
if isinstance(clearance, dict):
|
||||
cf_cookies = str(clearance.get("cf_cookies") or "").strip()
|
||||
cf_clearance = str(clearance.get("cf_clearance") or "").strip()
|
||||
clearance["cf_cookies"] = ""
|
||||
clearance["cf_clearance"] = ""
|
||||
clearance["has_cf_cookies"] = bool(cf_cookies)
|
||||
clearance["has_cf_clearance"] = bool(cf_clearance)
|
||||
return runtime
|
||||
|
||||
def get_third_party_apps_settings(self) -> dict[str, object]:
|
||||
return _normalize_third_party_apps_settings(self.data.get("third_party_apps"))
|
||||
|
||||
def update(self, data: dict[str, object]) -> dict[str, object]:
|
||||
next_data = dict(self.data)
|
||||
next_data.update(dict(data or {}))
|
||||
if "backup" in next_data:
|
||||
next_data["backup"] = _normalize_backup_settings(next_data.get("backup"))
|
||||
if "image_storage" in next_data:
|
||||
next_data["image_storage"] = _normalize_image_storage_settings(next_data.get("image_storage"))
|
||||
_validate_image_storage_settings(next_data["image_storage"])
|
||||
if "chat_completion_cache" in next_data:
|
||||
next_data["chat_completion_cache"] = _normalize_chat_completion_cache_settings(
|
||||
next_data.get("chat_completion_cache")
|
||||
)
|
||||
if "third_party_apps" in next_data:
|
||||
next_data["third_party_apps"] = _normalize_third_party_apps_settings(next_data.get("third_party_apps"))
|
||||
if "proxy_runtime" in next_data:
|
||||
incoming_runtime = next_data.get("proxy_runtime")
|
||||
if isinstance(incoming_runtime, dict):
|
||||
previous_clearance = self.get_proxy_runtime_settings().get("clearance")
|
||||
if isinstance(previous_clearance, dict):
|
||||
incoming_runtime = dict(incoming_runtime)
|
||||
incoming_runtime["_existing_cf_cookies"] = previous_clearance.get("cf_cookies")
|
||||
incoming_runtime["_existing_cf_clearance"] = previous_clearance.get("cf_clearance")
|
||||
next_data["proxy_runtime"] = _normalize_proxy_runtime_settings(incoming_runtime)
|
||||
next_data.pop("backup_state", None)
|
||||
self.data = next_data
|
||||
self._save()
|
||||
return self.get()
|
||||
|
||||
def get_backup_settings(self) -> dict[str, object]:
|
||||
return _normalize_backup_settings(self.data.get("backup"))
|
||||
|
||||
def get_image_storage_settings(self) -> dict[str, object]:
|
||||
return _normalize_image_storage_settings(self.data.get("image_storage"))
|
||||
|
||||
def get_chat_completion_cache_settings(self) -> dict[str, object]:
|
||||
return _normalize_chat_completion_cache_settings(self.data.get("chat_completion_cache"))
|
||||
|
||||
def get_storage_backend(self) -> StorageBackend:
|
||||
"""获取存储后端实例(单例)"""
|
||||
if self._storage_backend is None:
|
||||
from services.storage.factory import create_storage_backend
|
||||
self._storage_backend = create_storage_backend(DATA_DIR)
|
||||
return self._storage_backend
|
||||
|
||||
|
||||
def load_backup_state() -> dict[str, object]:
|
||||
return _normalize_backup_state(_read_json_object(BACKUP_STATE_FILE, name="backup_state.json"))
|
||||
|
||||
|
||||
def save_backup_state(state: dict[str, object]) -> dict[str, object]:
|
||||
normalized = _normalize_backup_state(state)
|
||||
BACKUP_STATE_FILE.write_text(json.dumps(normalized, ensure_ascii=False, indent=2) + "\n", encoding="utf-8")
|
||||
return normalized
|
||||
|
||||
|
||||
config = ConfigStore(CONFIG_FILE)
|
||||
@@ -0,0 +1,242 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
|
||||
from curl_cffi import requests
|
||||
from fastapi import HTTPException
|
||||
|
||||
from services.config import config
|
||||
from services.proxy_service import proxy_settings
|
||||
from utils.log import logger
|
||||
|
||||
DEFAULT_REVIEW_PROMPT = "判断用户请求是否允许。只回答 ALLOW 或 REJECT。"
|
||||
|
||||
# Strip base64 image data URIs before review: a text-only review model can't
|
||||
# analyze image bytes, and a single inlined image easily blows past the token
|
||||
# budget of the upstream review service.
|
||||
_BASE64_DATA_URI = re.compile(r"data:[\w/.+;-]+;base64,[A-Za-z0-9+/=]+")
|
||||
|
||||
# Cap aligned to the upstream review service's max context. If text still
|
||||
# exceeds the cap after base64 stripping, keep equal head/tail halves so both
|
||||
# the system prompt and the most recent user message survive.
|
||||
_MAX_REVIEW_TEXT_LEN = 100_000
|
||||
_TRUNCATION_MARKER = "\n…[truncated]…\n"
|
||||
|
||||
|
||||
def _text(value: object) -> str:
|
||||
if isinstance(value, str):
|
||||
return value
|
||||
if isinstance(value, list):
|
||||
return "\n".join(_text(item) for item in value)
|
||||
if isinstance(value, dict):
|
||||
return "\n".join(_text(value.get(key)) for key in ("text", "input_text", "content", "input", "instructions", "system", "prompt"))
|
||||
return ""
|
||||
|
||||
|
||||
def request_text(*values: object) -> str:
|
||||
return "\n".join(part for value in values if (part := _text(value).strip()))
|
||||
|
||||
|
||||
def request_shape(*values: object) -> dict[str, int]:
|
||||
"""Return a safe structural summary without logging prompts or image bytes."""
|
||||
stats = {
|
||||
"response_message_items": 0,
|
||||
"input_image_parts": 0,
|
||||
"image_url_parts": 0,
|
||||
"image_parts": 0,
|
||||
"data_url_images": 0,
|
||||
"remote_image_urls": 0,
|
||||
"literal_image_placeholders": 0,
|
||||
}
|
||||
|
||||
def walk(value: object, key: str = "") -> None:
|
||||
if isinstance(value, str):
|
||||
text = value.strip()
|
||||
lower = text.lower()
|
||||
if "<image>" in lower:
|
||||
stats["literal_image_placeholders"] += 1
|
||||
if lower.startswith("data:image/"):
|
||||
stats["data_url_images"] += 1
|
||||
elif key in {"image_url", "url"} and lower.startswith(("http://", "https://")):
|
||||
stats["remote_image_urls"] += 1
|
||||
return
|
||||
if isinstance(value, list):
|
||||
for item in value:
|
||||
walk(item, key)
|
||||
return
|
||||
if not isinstance(value, dict):
|
||||
return
|
||||
item_type = str(value.get("type") or "").strip()
|
||||
if item_type == "message":
|
||||
stats["response_message_items"] += 1
|
||||
elif item_type == "input_image":
|
||||
stats["input_image_parts"] += 1
|
||||
elif item_type == "image_url":
|
||||
stats["image_url_parts"] += 1
|
||||
elif item_type == "image":
|
||||
stats["image_parts"] += 1
|
||||
for child_key, child in value.items():
|
||||
walk(child, str(child_key))
|
||||
|
||||
for value in values:
|
||||
walk(value)
|
||||
return {key: value for key, value in stats.items() if value}
|
||||
|
||||
|
||||
def _sanitize_for_review(text: str) -> tuple[str, dict[str, int]]:
|
||||
"""Strip base64 data URIs and truncate to the review-service context limit.
|
||||
|
||||
Returns (sanitized_text, stats) where stats carries base64_blocks_stripped
|
||||
and truncated_chars so callers can emit structured logs.
|
||||
"""
|
||||
sanitized, base64_blocks_stripped = _BASE64_DATA_URI.subn("[image]", text)
|
||||
truncated_chars = 0
|
||||
if len(sanitized) > _MAX_REVIEW_TEXT_LEN:
|
||||
# Reserve marker space so the result stays within the cap.
|
||||
half = (_MAX_REVIEW_TEXT_LEN - len(_TRUNCATION_MARKER)) // 2
|
||||
truncated_chars = len(sanitized) - 2 * half
|
||||
sanitized = sanitized[:half] + _TRUNCATION_MARKER + sanitized[-half:]
|
||||
stats = {
|
||||
"base64_blocks_stripped": base64_blocks_stripped,
|
||||
"truncated_chars": truncated_chars,
|
||||
}
|
||||
return sanitized, stats
|
||||
|
||||
|
||||
def _extract_review_decision(data: object) -> str | None:
|
||||
"""Defensively pull the decision text out of the review service response.
|
||||
|
||||
Returns None when the response shape doesn't match the OpenAI chat-completion
|
||||
contract (e.g. {"error": ...} with no choices). The caller treats None as
|
||||
"undecided" and applies the configured fail-open policy.
|
||||
"""
|
||||
if not isinstance(data, dict):
|
||||
return None
|
||||
choices = data.get("choices")
|
||||
if not isinstance(choices, list) or not choices:
|
||||
return None
|
||||
first = choices[0]
|
||||
if not isinstance(first, dict):
|
||||
return None
|
||||
message = first.get("message")
|
||||
if not isinstance(message, dict):
|
||||
return None
|
||||
content = message.get("content")
|
||||
if content is None:
|
||||
return None
|
||||
return str(content).strip().lower()
|
||||
|
||||
|
||||
def _is_allow_decision(decision: str) -> bool:
|
||||
return decision.startswith(("allow", "pass", "true", "yes", "通过", "允许", "安全"))
|
||||
|
||||
|
||||
def _is_reject_decision(decision: str) -> bool:
|
||||
return decision.startswith(("reject", "deny", "block", "false", "no", "拒绝", "不允许", "违规", "禁止"))
|
||||
|
||||
|
||||
def _resolve_fail_open(review: dict) -> bool:
|
||||
"""Resolve fail_open from review config. Defaults to True."""
|
||||
value = review.get("fail_open")
|
||||
if value is None:
|
||||
return True
|
||||
if isinstance(value, bool):
|
||||
return value
|
||||
if isinstance(value, str):
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
return bool(value)
|
||||
|
||||
|
||||
def check_request(text: str) -> None:
|
||||
text = str(text or "")
|
||||
if not text.strip():
|
||||
return
|
||||
# Local sensitive-word match runs on the raw text (cheap, no network).
|
||||
for word in config.sensitive_words:
|
||||
if word in text:
|
||||
raise HTTPException(status_code=400, detail={"error": "检测到敏感词,拒绝本次任务"})
|
||||
review = config.ai_review
|
||||
if not review.get("enabled"):
|
||||
return
|
||||
base_url = str(review.get("base_url") or "").strip().rstrip("/")
|
||||
api_key = str(review.get("api_key") or "").strip()
|
||||
model = str(review.get("model") or "").strip()
|
||||
if not base_url or not api_key or not model:
|
||||
raise HTTPException(status_code=400, detail={"error": "ai review config is incomplete"})
|
||||
|
||||
fail_open = _resolve_fail_open(review)
|
||||
|
||||
review_text, sanitize_stats = _sanitize_for_review(text)
|
||||
if sanitize_stats["base64_blocks_stripped"] or sanitize_stats["truncated_chars"]:
|
||||
logger.info({
|
||||
"event": "ai_review_text_sanitized",
|
||||
"original_text_len": len(text),
|
||||
"review_text_len": len(review_text),
|
||||
**sanitize_stats,
|
||||
})
|
||||
prompt = str(review.get("prompt") or DEFAULT_REVIEW_PROMPT).strip()
|
||||
content = f"{prompt}\n\n用户请求:\n{review_text}\n\n只回答 ALLOW 或 REJECT。"
|
||||
|
||||
# fail_open=True (default): on upstream failure or ambiguous reply, let the
|
||||
# request through. The review is a soft safety net; one missed review is
|
||||
# preferable to a 5xx storm when the review service is flaky. Set
|
||||
# config.ai_review.fail_open=false for strict-compliance deployments.
|
||||
def _on_failure(event_payload: dict) -> None:
|
||||
logger.warning(event_payload)
|
||||
if not fail_open:
|
||||
raise HTTPException(
|
||||
status_code=503,
|
||||
detail={"error": "AI 审核服务暂时不可用,请稍后重试"},
|
||||
)
|
||||
|
||||
try:
|
||||
response = requests.post(
|
||||
f"{base_url}/v1/chat/completions",
|
||||
headers={"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"},
|
||||
json={"model": model, "messages": [{"role": "user", "content": content}], "temperature": 0},
|
||||
timeout=60,
|
||||
**proxy_settings.build_session_kwargs(),
|
||||
)
|
||||
except Exception as exc:
|
||||
_on_failure({
|
||||
"event": "ai_review_request_failed",
|
||||
"error": str(exc),
|
||||
"error_type": exc.__class__.__name__,
|
||||
"review_text_len": len(review_text),
|
||||
"original_text_len": len(text),
|
||||
})
|
||||
return
|
||||
|
||||
try:
|
||||
data = response.json()
|
||||
except Exception as exc:
|
||||
_on_failure({
|
||||
"event": "ai_review_response_not_json",
|
||||
"status_code": response.status_code,
|
||||
"body_preview": str(response.text or "")[:200],
|
||||
"error": str(exc),
|
||||
})
|
||||
return
|
||||
|
||||
decision = _extract_review_decision(data)
|
||||
if decision is None:
|
||||
_on_failure({
|
||||
"event": "ai_review_malformed_response",
|
||||
"status_code": response.status_code,
|
||||
"body_preview": str(data)[:300],
|
||||
"review_text_len": len(review_text),
|
||||
"original_text_len": len(text),
|
||||
})
|
||||
return
|
||||
|
||||
if _is_allow_decision(decision):
|
||||
return
|
||||
if _is_reject_decision(decision):
|
||||
raise HTTPException(status_code=400, detail={"error": "AI 审核未通过,拒绝本次任务"})
|
||||
# Ambiguous decisions (e.g. "MAYBE", empty content) fall back to fail-open policy.
|
||||
_on_failure({
|
||||
"event": "ai_review_ambiguous_decision",
|
||||
"decision": decision[:100],
|
||||
"review_text_len": len(review_text),
|
||||
})
|
||||
return
|
||||
@@ -0,0 +1,315 @@
|
||||
"""CLIProxyAPI integration for browsing remote auth files and importing selected tokens."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import threading
|
||||
import uuid
|
||||
from concurrent.futures import ThreadPoolExecutor, as_completed
|
||||
from datetime import datetime, timezone
|
||||
from pathlib import Path
|
||||
from threading import Lock
|
||||
|
||||
from curl_cffi.requests import Session
|
||||
|
||||
from services.account_service import account_service
|
||||
from services.config import DATA_DIR
|
||||
from services.proxy_service import proxy_settings
|
||||
|
||||
|
||||
CPA_CONFIG_FILE = DATA_DIR / "cpa_config.json"
|
||||
|
||||
|
||||
def _new_id() -> str:
|
||||
return uuid.uuid4().hex[:12]
|
||||
|
||||
|
||||
def _now_iso() -> str:
|
||||
return datetime.now(timezone.utc).isoformat()
|
||||
|
||||
|
||||
def _normalize_import_job(raw: object, *, fail_unfinished: bool) -> dict | None:
|
||||
if not isinstance(raw, dict):
|
||||
return None
|
||||
status = str(raw.get("status") or "failed").strip() or "failed"
|
||||
if fail_unfinished and status in {"pending", "running"}:
|
||||
status = "failed"
|
||||
return {
|
||||
"job_id": str(raw.get("job_id") or uuid.uuid4().hex).strip(),
|
||||
"status": status,
|
||||
"created_at": str(raw.get("created_at") or _now_iso()).strip() or _now_iso(),
|
||||
"updated_at": str(raw.get("updated_at") or raw.get("created_at") or _now_iso()).strip() or _now_iso(),
|
||||
"total": int(raw.get("total") or 0),
|
||||
"completed": int(raw.get("completed") or 0),
|
||||
"added": int(raw.get("added") or 0),
|
||||
"skipped": int(raw.get("skipped") or 0),
|
||||
"refreshed": int(raw.get("refreshed") or 0),
|
||||
"failed": int(raw.get("failed") or 0),
|
||||
"errors": raw.get("errors") if isinstance(raw.get("errors"), list) else [],
|
||||
}
|
||||
|
||||
|
||||
def _normalize_pool(raw: dict) -> dict:
|
||||
return {
|
||||
"id": str(raw.get("id") or _new_id()).strip(),
|
||||
"name": str(raw.get("name") or "").strip(),
|
||||
"base_url": str(raw.get("base_url") or "").strip(),
|
||||
"secret_key": str(raw.get("secret_key") or "").strip(),
|
||||
"import_job": _normalize_import_job(raw.get("import_job"), fail_unfinished=True),
|
||||
}
|
||||
|
||||
|
||||
def _management_headers(secret_key: str) -> dict[str, str]:
|
||||
return {
|
||||
"Authorization": f"Bearer {secret_key}",
|
||||
"Accept": "application/json",
|
||||
}
|
||||
|
||||
|
||||
class CPAConfig:
|
||||
def __init__(self, store_file: Path):
|
||||
self._store_file = store_file
|
||||
self._lock = Lock()
|
||||
self._pools: list[dict] = self._load()
|
||||
|
||||
def _load(self) -> list[dict]:
|
||||
if not self._store_file.exists():
|
||||
return []
|
||||
try:
|
||||
raw = json.loads(self._store_file.read_text(encoding="utf-8"))
|
||||
if isinstance(raw, dict) and "base_url" in raw:
|
||||
pool = _normalize_pool(raw)
|
||||
return [pool] if pool["base_url"] else []
|
||||
if isinstance(raw, list):
|
||||
return [_normalize_pool(item) for item in raw if isinstance(item, dict)]
|
||||
except Exception:
|
||||
pass
|
||||
return []
|
||||
|
||||
def _save(self) -> None:
|
||||
self._store_file.parent.mkdir(parents=True, exist_ok=True)
|
||||
self._store_file.write_text(json.dumps(self._pools, ensure_ascii=False, indent=2) + "\n", encoding="utf-8")
|
||||
|
||||
def list_pools(self) -> list[dict]:
|
||||
with self._lock:
|
||||
return [dict(pool) for pool in self._pools]
|
||||
|
||||
def get_pool(self, pool_id: str) -> dict | None:
|
||||
with self._lock:
|
||||
for pool in self._pools:
|
||||
if pool["id"] == pool_id:
|
||||
return dict(pool)
|
||||
return None
|
||||
|
||||
def add_pool(self, name: str, base_url: str, secret_key: str) -> dict:
|
||||
pool = _normalize_pool({"id": _new_id(), "name": name, "base_url": base_url, "secret_key": secret_key})
|
||||
with self._lock:
|
||||
self._pools.append(pool)
|
||||
self._save()
|
||||
return dict(pool)
|
||||
|
||||
def update_pool(self, pool_id: str, updates: dict) -> dict | None:
|
||||
with self._lock:
|
||||
for index, pool in enumerate(self._pools):
|
||||
if pool["id"] != pool_id:
|
||||
continue
|
||||
merged = {**pool, **{key: value for key, value in updates.items() if value is not None}, "id": pool_id}
|
||||
self._pools[index] = _normalize_pool(merged)
|
||||
self._save()
|
||||
return dict(self._pools[index])
|
||||
return None
|
||||
|
||||
def delete_pool(self, pool_id: str) -> bool:
|
||||
with self._lock:
|
||||
before = len(self._pools)
|
||||
self._pools = [pool for pool in self._pools if pool["id"] != pool_id]
|
||||
if len(self._pools) < before:
|
||||
self._save()
|
||||
return True
|
||||
return False
|
||||
|
||||
def set_import_job(self, pool_id: str, import_job: dict | None) -> dict | None:
|
||||
with self._lock:
|
||||
for index, pool in enumerate(self._pools):
|
||||
if pool["id"] != pool_id:
|
||||
continue
|
||||
next_pool = dict(pool)
|
||||
next_pool["import_job"] = _normalize_import_job(import_job, fail_unfinished=False)
|
||||
self._pools[index] = next_pool
|
||||
self._save()
|
||||
return dict(next_pool)
|
||||
return None
|
||||
|
||||
def get_import_job(self, pool_id: str) -> dict | None:
|
||||
with self._lock:
|
||||
for pool in self._pools:
|
||||
if pool["id"] == pool_id:
|
||||
job = pool.get("import_job")
|
||||
return dict(job) if isinstance(job, dict) else None
|
||||
return None
|
||||
|
||||
|
||||
def list_remote_files(pool: dict) -> list[dict]:
|
||||
base_url = str(pool.get("base_url") or "").strip()
|
||||
secret_key = str(pool.get("secret_key") or "").strip()
|
||||
if not base_url or not secret_key:
|
||||
return []
|
||||
|
||||
url = f"{base_url.rstrip('/')}/v0/management/auth-files"
|
||||
session = Session(**proxy_settings.build_session_kwargs(verify=True))
|
||||
try:
|
||||
response = session.get(url, headers=_management_headers(secret_key), timeout=30)
|
||||
if not response.ok:
|
||||
raise RuntimeError(f"remote list failed: HTTP {response.status_code}")
|
||||
payload = response.json()
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
files = payload.get("files") if isinstance(payload, dict) else None
|
||||
if not isinstance(files, list):
|
||||
raise RuntimeError("remote list payload is invalid")
|
||||
|
||||
items: list[dict] = []
|
||||
for item in files:
|
||||
if not isinstance(item, dict):
|
||||
continue
|
||||
name = str(item.get("name") or "").strip()
|
||||
email = str(item.get("email") or item.get("account") or "").strip()
|
||||
if not name:
|
||||
continue
|
||||
items.append({"name": name, "email": email})
|
||||
return items
|
||||
|
||||
|
||||
def fetch_remote_access_token(pool: dict, file_name: str) -> tuple[str | None, str | None]:
|
||||
base_url = str(pool.get("base_url") or "").strip()
|
||||
secret_key = str(pool.get("secret_key") or "").strip()
|
||||
file_name = str(file_name or "").strip()
|
||||
if not base_url or not secret_key or not file_name:
|
||||
return None, "invalid request"
|
||||
|
||||
url = f"{base_url.rstrip('/')}/v0/management/auth-files/download"
|
||||
session = Session(**proxy_settings.build_session_kwargs(verify=True))
|
||||
try:
|
||||
response = session.get(url, headers=_management_headers(secret_key), params={"name": file_name}, timeout=30)
|
||||
if not response.ok:
|
||||
return None, f"HTTP {response.status_code}"
|
||||
payload = response.json()
|
||||
except Exception as exc:
|
||||
return None, str(exc)
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
if not isinstance(payload, dict):
|
||||
return None, "invalid payload"
|
||||
|
||||
access_token = str(payload.get("access_token") or "").strip()
|
||||
if not access_token:
|
||||
return None, "missing access_token"
|
||||
return access_token, None
|
||||
|
||||
|
||||
class CPAImportService:
|
||||
def __init__(self, cpa_config: CPAConfig):
|
||||
self._config = cpa_config
|
||||
|
||||
def start_import(self, pool: dict, selected_files: list[str]) -> dict:
|
||||
names = [str(name or "").strip() for name in selected_files if str(name or "").strip()]
|
||||
if not names:
|
||||
raise ValueError("selected files is required")
|
||||
|
||||
pool_id = str(pool.get("id") or "").strip()
|
||||
job = {
|
||||
"job_id": uuid.uuid4().hex,
|
||||
"status": "pending",
|
||||
"created_at": _now_iso(),
|
||||
"updated_at": _now_iso(),
|
||||
"total": len(names),
|
||||
"completed": 0,
|
||||
"added": 0,
|
||||
"skipped": 0,
|
||||
"refreshed": 0,
|
||||
"failed": 0,
|
||||
"errors": [],
|
||||
}
|
||||
saved_pool = self._config.set_import_job(pool_id, job)
|
||||
if saved_pool is None:
|
||||
raise ValueError("pool not found")
|
||||
|
||||
thread = threading.Thread(
|
||||
target=self._run_import,
|
||||
args=(pool_id, pool, names),
|
||||
name=f"cpa-import-{pool_id}",
|
||||
daemon=True,
|
||||
)
|
||||
thread.start()
|
||||
return dict(saved_pool.get("import_job") or job)
|
||||
|
||||
def _update_job(self, pool_id: str, **updates) -> dict | None:
|
||||
current = self._config.get_import_job(pool_id)
|
||||
if current is None:
|
||||
return None
|
||||
next_job = {**current, **updates, "updated_at": _now_iso()}
|
||||
pool = self._config.set_import_job(pool_id, next_job)
|
||||
if pool is None:
|
||||
return None
|
||||
job = pool.get("import_job")
|
||||
return dict(job) if isinstance(job, dict) else None
|
||||
|
||||
def _append_error(self, pool_id: str, file_name: str, message: str) -> None:
|
||||
current = self._config.get_import_job(pool_id)
|
||||
if current is None:
|
||||
return
|
||||
errors = list(current.get("errors") or [])
|
||||
errors.append({"name": file_name, "error": message})
|
||||
self._update_job(pool_id, errors=errors, failed=len(errors))
|
||||
|
||||
def _run_import(self, pool_id: str, pool: dict, names: list[str]) -> None:
|
||||
self._update_job(pool_id, status="running")
|
||||
|
||||
tokens: list[str] = []
|
||||
max_workers = min(16, max(1, len(names)))
|
||||
with ThreadPoolExecutor(max_workers=max_workers) as executor:
|
||||
future_map = {executor.submit(fetch_remote_access_token, pool, name): name for name in names}
|
||||
for future in as_completed(future_map):
|
||||
file_name = future_map[future]
|
||||
try:
|
||||
token, error = future.result()
|
||||
except Exception as exc:
|
||||
token, error = None, str(exc)
|
||||
|
||||
if token:
|
||||
tokens.append(token)
|
||||
else:
|
||||
self._append_error(pool_id, file_name, error or "unknown error")
|
||||
|
||||
current = self._config.get_import_job(pool_id) or {}
|
||||
failed = len(current.get("errors") or [])
|
||||
self._update_job(pool_id, completed=int(current.get("completed") or 0) + 1, failed=failed)
|
||||
|
||||
if not tokens:
|
||||
current = self._config.get_import_job(pool_id) or {}
|
||||
self._update_job(
|
||||
pool_id,
|
||||
status="failed",
|
||||
completed=int(current.get("total") or 0),
|
||||
failed=len(current.get("errors") or []),
|
||||
)
|
||||
return
|
||||
|
||||
add_result = account_service.add_accounts(tokens, source_type="codex")
|
||||
refresh_result = account_service.refresh_accounts(tokens)
|
||||
current = self._config.get_import_job(pool_id) or {}
|
||||
self._update_job(
|
||||
pool_id,
|
||||
status="completed",
|
||||
completed=len(names),
|
||||
added=int(add_result.get("added") or 0),
|
||||
skipped=int(add_result.get("skipped") or 0),
|
||||
refreshed=int(refresh_result.get("refreshed") or 0),
|
||||
failed=len(current.get("errors") or []),
|
||||
)
|
||||
|
||||
|
||||
cpa_config = CPAConfig(CPA_CONFIG_FILE)
|
||||
cpa_import_service = CPAImportService(cpa_config)
|
||||
@@ -0,0 +1,260 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import threading
|
||||
import time
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
from urllib.parse import quote
|
||||
|
||||
from services.account_service import account_service
|
||||
from services.config import DATA_DIR
|
||||
from services.content_filter import request_text
|
||||
from services.log_service import LOG_TYPE_CALL, log_service
|
||||
from services.openai_backend_api import EDITABLE_FILE_MODEL, OpenAIBackendAPI
|
||||
from utils.helper import new_uuid
|
||||
|
||||
TASK_STATUS_QUEUED = "queued"
|
||||
TASK_STATUS_RUNNING = "running"
|
||||
TASK_STATUS_SUCCESS = "success"
|
||||
TASK_STATUS_ERROR = "error"
|
||||
UNFINISHED_STATUSES = {TASK_STATUS_QUEUED, TASK_STATUS_RUNNING}
|
||||
EDITABLE_FILE_PLAN_TYPES = ("Plus", "Team", "Pro", "Enterprise")
|
||||
EDITABLE_FILE_ROOT = DATA_DIR / "files"
|
||||
EDITABLE_FILE_TASKS_PATH = DATA_DIR / "editable_file_tasks.json"
|
||||
|
||||
|
||||
def _now_iso() -> str:
|
||||
return datetime.now().strftime("%Y-%m-%d %H:%M:%S")
|
||||
|
||||
|
||||
def _clean(value: object, default: str = "") -> str:
|
||||
return str(value or default).strip()
|
||||
|
||||
|
||||
def _owner_id(identity: dict[str, object]) -> str:
|
||||
return _clean(identity.get("id")) or "anonymous"
|
||||
|
||||
|
||||
def _task_key(owner_id: str, task_id: str) -> str:
|
||||
return f"{owner_id}:{task_id}"
|
||||
|
||||
|
||||
def _elapsed_seconds(task: dict[str, Any]) -> int:
|
||||
start = float(task.get("started_ts") or task.get("created_ts") or 0)
|
||||
end = float(task.get("ended_ts") or time.time())
|
||||
return max(0, int(end - start)) if start else 0
|
||||
|
||||
|
||||
def _file_url(path: Path, base_url: str) -> str:
|
||||
rel = path.resolve().relative_to(EDITABLE_FILE_ROOT.resolve()).as_posix()
|
||||
prefix = str(base_url or "").strip().rstrip("/")
|
||||
return f"{prefix}/files/{quote(rel, safe='/')}" if prefix else f"/files/{quote(rel, safe='/')}"
|
||||
|
||||
|
||||
def _editable_access_token() -> str:
|
||||
accounts = [
|
||||
item for item in account_service.list_accounts()
|
||||
if _clean(item.get("access_token"))
|
||||
and item.get("status") not in {"禁用", "异常"}
|
||||
and account_service._account_matches_any_plan_type(item, EDITABLE_FILE_PLAN_TYPES)
|
||||
]
|
||||
if not accounts:
|
||||
raise RuntimeError("no available plus/team/pro account")
|
||||
accounts.sort(key=lambda item: _clean(item.get("last_used_at")))
|
||||
token = _clean(accounts[0].get("access_token"))
|
||||
return account_service.refresh_access_token(token, event="editable_file_task") or token
|
||||
|
||||
|
||||
def _public_task(task: dict[str, Any]) -> dict[str, Any]:
|
||||
item = {
|
||||
"id": task.get("id"),
|
||||
"taskId": task.get("id"),
|
||||
"status": task.get("status"),
|
||||
"kind": task.get("kind"),
|
||||
"created_at": task.get("created_at"),
|
||||
"updated_at": task.get("updated_at"),
|
||||
"elapsed_seconds": _elapsed_seconds(task),
|
||||
}
|
||||
for key in ("result", "error"):
|
||||
if task.get(key):
|
||||
item[key] = task[key]
|
||||
return item
|
||||
|
||||
|
||||
class EditableFileTaskService:
|
||||
def __init__(self, path: Path = EDITABLE_FILE_TASKS_PATH) -> None:
|
||||
self.path = path
|
||||
self._lock = threading.RLock()
|
||||
self._tasks: dict[str, dict[str, Any]] = {}
|
||||
self.path.parent.mkdir(parents=True, exist_ok=True)
|
||||
with self._lock:
|
||||
self._tasks = self._load_locked()
|
||||
if self._recover_unfinished_locked():
|
||||
self._save_locked()
|
||||
|
||||
def submit_ppt(self, identity: dict[str, object], *, client_task_id: str = "", prompt: str = "", base64_images: list[str] | None = None, base_url: str = "") -> dict[str, Any]:
|
||||
return self._submit(identity, client_task_id=client_task_id, kind="ppt", prompt=prompt, base64_images=base64_images or [], base_url=base_url)
|
||||
|
||||
def submit_psd(self, identity: dict[str, object], *, client_task_id: str = "", prompt: str = "", base64_images: list[str] | None = None, base_url: str = "") -> dict[str, Any]:
|
||||
return self._submit(identity, client_task_id=client_task_id, kind="psd", prompt=prompt, base64_images=base64_images or [], base_url=base_url)
|
||||
|
||||
def list_tasks(self, identity: dict[str, object], task_ids: list[str]) -> dict[str, Any]:
|
||||
owner = _owner_id(identity)
|
||||
requested = [_clean(item) for item in task_ids if _clean(item)]
|
||||
with self._lock:
|
||||
if requested:
|
||||
items = [task for task_id in requested if (task := self._tasks.get(_task_key(owner, task_id)))]
|
||||
return {"items": [_public_task(item) for item in items], "missing_ids": [task_id for task_id in requested if _task_key(owner, task_id) not in self._tasks]}
|
||||
items = [task for task in self._tasks.values() if task.get("owner_id") == owner]
|
||||
items.sort(key=lambda item: str(item.get("updated_at") or ""), reverse=True)
|
||||
return {"items": [_public_task(item) for item in items], "missing_ids": []}
|
||||
|
||||
def _submit(self, identity: dict[str, object], *, client_task_id: str, kind: str, prompt: str, base64_images: list[str], base_url: str) -> dict[str, Any]:
|
||||
task_id = _clean(client_task_id) or new_uuid()
|
||||
owner = _owner_id(identity)
|
||||
key = _task_key(owner, task_id)
|
||||
now = _now_iso()
|
||||
with self._lock:
|
||||
if key in self._tasks:
|
||||
return _public_task(self._tasks[key])
|
||||
ts = time.time()
|
||||
self._tasks[key] = {"id": task_id, "owner_id": owner, "status": TASK_STATUS_QUEUED, "kind": kind, "model": EDITABLE_FILE_MODEL, "created_at": now, "updated_at": now, "created_ts": ts, "updated_ts": ts}
|
||||
task = dict(self._tasks[key])
|
||||
self._save_locked()
|
||||
threading.Thread(target=self._run_task, args=(key, kind, prompt, base64_images, dict(identity), base_url), name=f"{kind}-file-task-{task_id[:16]}", daemon=True).start()
|
||||
return _public_task(task)
|
||||
|
||||
def _run_task(self, key: str, kind: str, prompt: str, base64_images: list[str], identity: dict[str, object], base_url: str) -> None:
|
||||
started = time.time()
|
||||
token = ""
|
||||
account_email = ""
|
||||
self._update_task(key, status=TASK_STATUS_RUNNING, error="", started_ts=started)
|
||||
backend = None
|
||||
try:
|
||||
if kind == "psd" and not base64_images:
|
||||
raise ValueError("base64_images is empty")
|
||||
token = _editable_access_token()
|
||||
account = account_service.get_account(token) or {}
|
||||
account_email = _clean(account.get("email"))
|
||||
backend = OpenAIBackendAPI(token)
|
||||
output_dir = EDITABLE_FILE_ROOT / kind / key.rsplit(":", 1)[-1]
|
||||
result = backend.export_psd_zip(base64_images, prompt, output_dir) if kind == "psd" else backend.export_ppt_zip(base64_images, prompt, output_dir)
|
||||
account_service.mark_text_used(token)
|
||||
data = {"conversation_id": result.conversation_id, "primary_url": _file_url(result.primary_path, base_url), "zip_url": _file_url(result.zip_path, base_url)}
|
||||
self._update_task(key, status=TASK_STATUS_SUCCESS, result=data, account_email=account_email, error="", ended_ts=time.time())
|
||||
self._log_call(identity, kind, started, request_text(prompt), account_email=account_email, result=data)
|
||||
except Exception as exc:
|
||||
error = str(exc) or "editable file task failed"
|
||||
self._update_task(key, status=TASK_STATUS_ERROR, error=error, account_email=account_email, ended_ts=time.time())
|
||||
self._log_call(identity, kind, started, request_text(prompt), status="failed", error=error, account_email=account_email)
|
||||
finally:
|
||||
if backend is not None:
|
||||
backend.close()
|
||||
|
||||
def public_file_path(self, relative_path: str) -> Path:
|
||||
raw = str(relative_path or "").replace("\\", "/").lstrip("/")
|
||||
path = (EDITABLE_FILE_ROOT / raw).resolve()
|
||||
path.relative_to(EDITABLE_FILE_ROOT.resolve())
|
||||
if not path.is_file():
|
||||
raise FileNotFoundError(raw)
|
||||
return path
|
||||
|
||||
def _update_task(self, key: str, **updates: Any) -> None:
|
||||
with self._lock:
|
||||
task = self._tasks.get(key)
|
||||
if task is None:
|
||||
return
|
||||
task.update(updates)
|
||||
task["updated_at"] = _now_iso()
|
||||
task["updated_ts"] = time.time()
|
||||
self._save_locked()
|
||||
|
||||
def _load_locked(self) -> dict[str, dict[str, Any]]:
|
||||
if not self.path.exists():
|
||||
return {}
|
||||
try:
|
||||
raw = json.loads(self.path.read_text(encoding="utf-8"))
|
||||
except Exception:
|
||||
return {}
|
||||
tasks: dict[str, dict[str, Any]] = {}
|
||||
for item in (raw.get("tasks") if isinstance(raw, dict) else raw) or []:
|
||||
if not isinstance(item, dict):
|
||||
continue
|
||||
task_id = _clean(item.get("id"))
|
||||
owner = _clean(item.get("owner_id"))
|
||||
if not task_id or not owner:
|
||||
continue
|
||||
task = {
|
||||
"id": task_id,
|
||||
"owner_id": owner,
|
||||
"status": _clean(item.get("status"), TASK_STATUS_ERROR),
|
||||
"kind": "psd" if item.get("kind") == "psd" else "ppt",
|
||||
"created_at": _clean(item.get("created_at"), _now_iso()),
|
||||
"updated_at": _clean(item.get("updated_at"), _clean(item.get("created_at"), _now_iso())),
|
||||
"created_ts": float(item.get("created_ts") or 0),
|
||||
"updated_ts": float(item.get("updated_ts") or 0),
|
||||
}
|
||||
for field in ("result", "error", "started_ts", "ended_ts"):
|
||||
if item.get(field):
|
||||
task[field] = item[field]
|
||||
tasks[_task_key(owner, task_id)] = task
|
||||
return tasks
|
||||
|
||||
def _save_locked(self) -> None:
|
||||
items = sorted(self._tasks.values(), key=lambda item: str(item.get("updated_at") or ""), reverse=True)
|
||||
tmp_path = self.path.with_suffix(self.path.suffix + ".tmp")
|
||||
tmp_path.write_text(json.dumps({"tasks": items}, ensure_ascii=False, indent=2) + "\n", encoding="utf-8")
|
||||
tmp_path.replace(self.path)
|
||||
|
||||
def _recover_unfinished_locked(self) -> bool:
|
||||
changed = False
|
||||
for task in self._tasks.values():
|
||||
if task.get("status") in UNFINISHED_STATUSES:
|
||||
task["status"] = TASK_STATUS_ERROR
|
||||
task["error"] = "服务已重启,未完成的任务已中断"
|
||||
task["ended_ts"] = time.time()
|
||||
task["updated_at"] = _now_iso()
|
||||
task["updated_ts"] = time.time()
|
||||
changed = True
|
||||
return changed
|
||||
|
||||
def _log_call(
|
||||
self,
|
||||
identity: dict[str, object],
|
||||
kind: str,
|
||||
started: float,
|
||||
request_preview: str,
|
||||
*,
|
||||
status: str = "success",
|
||||
error: str = "",
|
||||
account_email: str = "",
|
||||
result: dict[str, str] | None = None,
|
||||
) -> None:
|
||||
detail = {
|
||||
"key_id": identity.get("id"),
|
||||
"key_name": identity.get("name"),
|
||||
"role": identity.get("role"),
|
||||
"endpoint": f"/v1/{kind}/generations",
|
||||
"model": EDITABLE_FILE_MODEL,
|
||||
"started_at": datetime.fromtimestamp(started).strftime("%Y-%m-%d %H:%M:%S"),
|
||||
"ended_at": _now_iso(),
|
||||
"duration_ms": int((time.time() - started) * 1000),
|
||||
"status": status,
|
||||
}
|
||||
if request_preview:
|
||||
detail["request_text"] = request_preview
|
||||
if account_email:
|
||||
detail["account_email"] = account_email
|
||||
if error:
|
||||
detail["error"] = error
|
||||
if result:
|
||||
detail["result"] = result
|
||||
try:
|
||||
log_service.add(LOG_TYPE_CALL, f"{kind.upper()}生成任务{'失败' if status == 'failed' else '完成'}", detail)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
|
||||
editable_file_task_service = EditableFileTaskService()
|
||||
@@ -0,0 +1,376 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import io
|
||||
import shutil
|
||||
import threading
|
||||
import time
|
||||
import zipfile
|
||||
from pathlib import Path
|
||||
|
||||
from fastapi import HTTPException
|
||||
from fastapi.responses import FileResponse, Response
|
||||
from PIL import Image, ImageOps
|
||||
|
||||
from services.config import config
|
||||
from services.image_storage_service import image_storage_service
|
||||
from services.image_tags_service import load_tags, remove_tags
|
||||
from utils.log import logger
|
||||
|
||||
THUMBNAIL_SIZE = (320, 320)
|
||||
|
||||
|
||||
def _cleanup_empty_dirs(root: Path) -> None:
|
||||
for path in sorted((p for p in root.rglob("*") if p.is_dir()), key=lambda p: len(p.parts), reverse=True):
|
||||
try:
|
||||
path.rmdir()
|
||||
except OSError:
|
||||
pass
|
||||
|
||||
|
||||
def _safe_relative_path(path: str) -> str:
|
||||
value = str(path or "").strip().replace("\\", "/").lstrip("/")
|
||||
if not value:
|
||||
raise HTTPException(status_code=404, detail="image not found")
|
||||
parts = Path(value).parts
|
||||
if any(part in {"", ".", ".."} for part in parts):
|
||||
raise HTTPException(status_code=404, detail="image not found")
|
||||
return Path(*parts).as_posix()
|
||||
|
||||
|
||||
def _safe_image_path(relative_path: str) -> Path:
|
||||
rel = _safe_relative_path(relative_path)
|
||||
root = config.images_dir.resolve()
|
||||
path = (root / rel).resolve()
|
||||
try:
|
||||
path.relative_to(root)
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=404, detail="image not found") from exc
|
||||
if not path.is_file():
|
||||
raise HTTPException(status_code=404, detail="image not found")
|
||||
return path
|
||||
|
||||
|
||||
def get_image_response(relative_path: str) -> FileResponse | Response:
|
||||
headers = {
|
||||
"Access-Control-Allow-Origin": "*",
|
||||
"Access-Control-Allow-Methods": "GET, OPTIONS",
|
||||
"Access-Control-Allow-Headers": "*",
|
||||
}
|
||||
if image_storage_service.has_local(relative_path):
|
||||
return FileResponse(_safe_image_path(relative_path), headers=headers)
|
||||
return Response(content=image_storage_service.get_bytes(relative_path), media_type="image/png", headers=headers)
|
||||
|
||||
|
||||
def _thumbnail_path(relative_path: str) -> Path:
|
||||
rel = _safe_relative_path(relative_path)
|
||||
return config.image_thumbnails_dir / f"{rel}.png"
|
||||
|
||||
|
||||
def thumbnail_url(base_url: str, relative_path: str) -> str:
|
||||
return f"{base_url.rstrip('/')}/image-thumbnails/{_safe_relative_path(relative_path)}"
|
||||
|
||||
|
||||
def _image_dimensions(path: Path) -> tuple[int, int] | None:
|
||||
try:
|
||||
with Image.open(path) as image:
|
||||
return image.size
|
||||
except Exception:
|
||||
return None
|
||||
|
||||
|
||||
def ensure_thumbnail(relative_path: str) -> Path:
|
||||
target = _thumbnail_path(relative_path)
|
||||
source_mtime = 0.0
|
||||
source: Path | None = None
|
||||
if image_storage_service.has_local(relative_path):
|
||||
source = _safe_image_path(relative_path)
|
||||
source_mtime = source.stat().st_mtime
|
||||
if target.exists() and (not source_mtime or target.stat().st_mtime >= source_mtime):
|
||||
return target
|
||||
|
||||
target.parent.mkdir(parents=True, exist_ok=True)
|
||||
try:
|
||||
image_source = source if source is not None else io.BytesIO(image_storage_service.get_bytes(relative_path))
|
||||
with Image.open(image_source) as image:
|
||||
image = ImageOps.exif_transpose(image)
|
||||
if image.mode not in {"RGB", "RGBA"}:
|
||||
image = image.convert("RGBA" if "A" in image.getbands() else "RGB")
|
||||
image.thumbnail(THUMBNAIL_SIZE, Image.Resampling.LANCZOS)
|
||||
image.save(target, format="PNG", optimize=True)
|
||||
except HTTPException:
|
||||
raise
|
||||
except Exception as exc:
|
||||
raise HTTPException(status_code=422, detail="failed to create thumbnail") from exc
|
||||
return target
|
||||
|
||||
|
||||
def get_thumbnail_response(relative_path: str) -> FileResponse:
|
||||
headers = {
|
||||
"Access-Control-Allow-Origin": "*",
|
||||
"Access-Control-Allow-Methods": "GET, OPTIONS",
|
||||
"Access-Control-Allow-Headers": "*",
|
||||
}
|
||||
return FileResponse(ensure_thumbnail(relative_path), headers=headers)
|
||||
|
||||
|
||||
def get_image_download_response(relative_path: str) -> FileResponse:
|
||||
cors_headers = {
|
||||
"Access-Control-Allow-Origin": "*",
|
||||
"Access-Control-Allow-Methods": "GET, OPTIONS",
|
||||
"Access-Control-Allow-Headers": "*",
|
||||
}
|
||||
if image_storage_service.has_local(relative_path):
|
||||
path = _safe_image_path(relative_path)
|
||||
headers = {**cors_headers, "Content-Disposition": f'attachment; filename="{path.name}"'}
|
||||
return FileResponse(path, filename=path.name, headers=headers)
|
||||
rel = _safe_relative_path(relative_path)
|
||||
headers = {
|
||||
**cors_headers,
|
||||
"Content-Disposition": f'attachment; filename="{Path(rel).name}"',
|
||||
}
|
||||
return Response(
|
||||
content=image_storage_service.get_bytes(rel),
|
||||
media_type="image/png",
|
||||
headers=headers,
|
||||
)
|
||||
|
||||
|
||||
def cleanup_image_thumbnails() -> int:
|
||||
thumbnails_root = config.image_thumbnails_dir
|
||||
removed = 0
|
||||
for path in thumbnails_root.rglob("*"):
|
||||
if not path.is_file():
|
||||
continue
|
||||
rel = path.relative_to(thumbnails_root).as_posix()
|
||||
if not rel.endswith(".png") or not image_storage_service.exists(rel[:-4]):
|
||||
path.unlink()
|
||||
removed += 1
|
||||
_cleanup_empty_dirs(thumbnails_root)
|
||||
return removed
|
||||
|
||||
def list_images(base_url: str, start_date: str = "", end_date: str = "") -> dict[str, object]:
|
||||
config.cleanup_old_images()
|
||||
cleanup_image_thumbnails()
|
||||
all_tags = load_tags()
|
||||
items = [
|
||||
{
|
||||
**item,
|
||||
"url": str(item.get("url") or f"{base_url.rstrip('/')}/images/{item['path']}"),
|
||||
"thumbnail_url": thumbnail_url(base_url, str(item["path"])),
|
||||
"tags": all_tags.get(str(item["path"]), []),
|
||||
}
|
||||
for item in image_storage_service.list_items(base_url, start_date, end_date)
|
||||
]
|
||||
groups: dict[str, list[dict[str, object]]] = {}
|
||||
for item in items:
|
||||
groups.setdefault(str(item["date"]), []).append(item)
|
||||
return {"items": items, "groups": [{"date": key, "items": value} for key, value in groups.items()]}
|
||||
|
||||
|
||||
def delete_images(paths: list[str] | None = None, start_date: str = "", end_date: str = "", all_matching: bool = False) -> dict[str, int]:
|
||||
root = config.images_dir.resolve()
|
||||
targets = [
|
||||
str(item["path"])
|
||||
for item in image_storage_service.list_items("", start_date=start_date, end_date=end_date)
|
||||
] if all_matching else (paths or [])
|
||||
removed = 0
|
||||
for item in targets:
|
||||
path = (root / item).resolve()
|
||||
try:
|
||||
path.relative_to(root)
|
||||
except ValueError:
|
||||
continue
|
||||
if image_storage_service.delete(item):
|
||||
removed += 1
|
||||
for thumbnail in (_thumbnail_path(item), config.image_thumbnails_dir / _safe_relative_path(item)):
|
||||
if thumbnail.is_file():
|
||||
thumbnail.unlink()
|
||||
remove_tags(item)
|
||||
_cleanup_empty_dirs(root)
|
||||
_cleanup_empty_dirs(config.image_thumbnails_dir)
|
||||
return {"removed": removed}
|
||||
|
||||
|
||||
def download_images_zip(paths: list[str]) -> io.BytesIO:
|
||||
root = config.images_dir.resolve()
|
||||
buf = io.BytesIO()
|
||||
added = 0
|
||||
used_names: set[str] = set()
|
||||
with zipfile.ZipFile(buf, "w", zipfile.ZIP_DEFLATED) as zf:
|
||||
for item in paths:
|
||||
rel = _safe_relative_path(item)
|
||||
path = (root / rel).resolve()
|
||||
payload: bytes | None = None
|
||||
try:
|
||||
path.relative_to(root)
|
||||
except ValueError:
|
||||
continue
|
||||
if path.is_file():
|
||||
payload = path.read_bytes()
|
||||
else:
|
||||
try:
|
||||
payload = image_storage_service.get_bytes(rel)
|
||||
except Exception:
|
||||
continue
|
||||
name = path.name
|
||||
if name in used_names:
|
||||
stem = path.stem
|
||||
suffix = path.suffix
|
||||
counter = 2
|
||||
while f"{stem}_{counter}{suffix}" in used_names:
|
||||
counter += 1
|
||||
name = f"{stem}_{counter}{suffix}"
|
||||
used_names.add(name)
|
||||
zf.writestr(name, payload)
|
||||
added += 1
|
||||
if added == 0:
|
||||
raise HTTPException(status_code=404, detail="no images found")
|
||||
buf.seek(0)
|
||||
return buf
|
||||
def storage_stats() -> dict:
|
||||
import shutil
|
||||
usage = shutil.disk_usage(config.images_dir)
|
||||
total_mb = usage.total // (1024 * 1024)
|
||||
used_mb = usage.used // (1024 * 1024)
|
||||
free_mb = usage.free // (1024 * 1024)
|
||||
|
||||
image_count = 0
|
||||
image_size = 0
|
||||
for p in config.images_dir.rglob("*"):
|
||||
if p.is_file():
|
||||
image_count += 1
|
||||
image_size += p.stat().st_size
|
||||
|
||||
return {
|
||||
"disk_total_mb": total_mb,
|
||||
"disk_used_mb": used_mb,
|
||||
"disk_free_mb": free_mb,
|
||||
"image_count": image_count,
|
||||
"image_size_mb": image_size // (1024 * 1024),
|
||||
"image_size_bytes": image_size,
|
||||
}
|
||||
|
||||
|
||||
def compress_images(quality: int = 60) -> dict:
|
||||
"""重新压缩所有图片,返回节省的空间"""
|
||||
saved = 0
|
||||
count = 0
|
||||
for p in sorted(config.images_dir.rglob("*.png")):
|
||||
if not p.is_file():
|
||||
continue
|
||||
try:
|
||||
orig = p.stat().st_size
|
||||
with Image.open(p) as img:
|
||||
img = ImageOps.exif_transpose(img)
|
||||
img.save(str(p) + ".tmp", format="PNG", optimize=True)
|
||||
new_size = Path(str(p) + ".tmp").stat().st_size
|
||||
if new_size < orig:
|
||||
Path(str(p) + ".tmp").replace(p)
|
||||
saved += orig - new_size
|
||||
count += 1
|
||||
else:
|
||||
Path(str(p) + ".tmp").unlink()
|
||||
except Exception:
|
||||
pass
|
||||
return {"compressed": count, "saved_bytes": saved, "saved_mb": saved // (1024 * 1024)}
|
||||
|
||||
|
||||
def delete_to_target(target_free_mb: int, dry_run: bool = False) -> dict:
|
||||
"""删除最旧的图片直到剩余空间达到 target_free_mb"""
|
||||
import shutil
|
||||
usage = shutil.disk_usage(config.images_dir)
|
||||
current_free = usage.free // (1024 * 1024)
|
||||
if current_free >= target_free_mb and not dry_run:
|
||||
return {"removed": 0, "current_free_mb": current_free, "target_free_mb": target_free_mb, "done": True}
|
||||
|
||||
files = sorted(
|
||||
(p for p in config.images_dir.rglob("*.png") if p.is_file()),
|
||||
key=lambda p: p.stat().st_mtime,
|
||||
)
|
||||
removed = 0
|
||||
freed = 0
|
||||
for p in files:
|
||||
if current_free + freed // (1024 * 1024) >= target_free_mb:
|
||||
break
|
||||
size = p.stat().st_size
|
||||
if not dry_run:
|
||||
rel = p.relative_to(config.images_dir).as_posix()
|
||||
for tp in (_thumbnail_path(rel), config.image_thumbnails_dir / _safe_relative_path(rel)):
|
||||
if tp.is_file():
|
||||
tp.unlink()
|
||||
remove_tags(rel)
|
||||
p.unlink()
|
||||
freed += size
|
||||
removed += 1
|
||||
|
||||
if not dry_run:
|
||||
_cleanup_empty_dirs(config.images_dir)
|
||||
_cleanup_empty_dirs(config.image_thumbnails_dir)
|
||||
|
||||
return {
|
||||
"removed": removed,
|
||||
"freed_mb": freed // (1024 * 1024),
|
||||
"target_free_mb": target_free_mb,
|
||||
"current_free_mb": current_free + (freed // (1024 * 1024)),
|
||||
"done": (current_free + freed // (1024 * 1024)) >= target_free_mb,
|
||||
"dry_run": dry_run,
|
||||
}
|
||||
|
||||
|
||||
def download_images_zip(paths: list[str]) -> io.BytesIO:
|
||||
root = config.images_dir.resolve()
|
||||
buf = io.BytesIO()
|
||||
added = 0
|
||||
used_names: set[str] = set()
|
||||
with zipfile.ZipFile(buf, "w", zipfile.ZIP_DEFLATED) as zf:
|
||||
for item in paths:
|
||||
rel = _safe_relative_path(item)
|
||||
path = (root / rel).resolve()
|
||||
try:
|
||||
path.relative_to(root)
|
||||
except ValueError:
|
||||
continue
|
||||
if not path.is_file():
|
||||
continue
|
||||
name = path.name
|
||||
if name in used_names:
|
||||
stem = path.stem
|
||||
suffix = path.suffix
|
||||
counter = 2
|
||||
while f"{stem}_{counter}{suffix}" in used_names:
|
||||
counter += 1
|
||||
name = f"{stem}_{counter}{suffix}"
|
||||
used_names.add(name)
|
||||
zf.write(path, name)
|
||||
added += 1
|
||||
if added == 0:
|
||||
raise HTTPException(status_code=404, detail="no images found")
|
||||
buf.seek(0)
|
||||
return buf
|
||||
|
||||
|
||||
def _auto_cleanup_worker(stop_event: threading.Event) -> None:
|
||||
"""后台线程:每30分钟检查存储,空间低于阈值自动清理最旧图片"""
|
||||
import shutil
|
||||
min_free_mb = getattr(config, "image_min_free_mb", None)
|
||||
if min_free_mb is None:
|
||||
min_free_mb = 500
|
||||
|
||||
while not stop_event.wait(1800): # 每30分钟
|
||||
try:
|
||||
config.cleanup_old_images()
|
||||
cleanup_image_thumbnails()
|
||||
usage = shutil.disk_usage(config.images_dir)
|
||||
free_mb = usage.free // (1024 * 1024)
|
||||
if free_mb < min_free_mb:
|
||||
logger.info({"event": "image_auto_cleanup", "free_mb": free_mb, "min_free_mb": min_free_mb})
|
||||
result = delete_to_target(min_free_mb)
|
||||
logger.info({"event": "image_auto_cleanup_done", **result})
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
|
||||
def start_image_cleanup_scheduler(stop_event: threading.Event) -> threading.Thread:
|
||||
t = threading.Thread(target=_auto_cleanup_worker, args=(stop_event,), daemon=True, name="image-cleanup")
|
||||
t.start()
|
||||
return t
|
||||
@@ -0,0 +1,405 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import hashlib
|
||||
import io
|
||||
import json
|
||||
import time
|
||||
from dataclasses import dataclass
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from threading import Lock
|
||||
from urllib.parse import quote, urlparse
|
||||
|
||||
from curl_cffi import requests
|
||||
from fastapi import HTTPException
|
||||
from PIL import Image
|
||||
|
||||
from services.config import DATA_DIR, config
|
||||
|
||||
IMAGE_INDEX_FILE = DATA_DIR / "image_index.json"
|
||||
IMAGE_INDEX_LOCK = Lock()
|
||||
IMAGE_EXTENSIONS = {".png", ".jpg", ".jpeg", ".webp"}
|
||||
|
||||
|
||||
class ImageStorageError(RuntimeError):
|
||||
pass
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class StoredImage:
|
||||
rel: str
|
||||
url: str
|
||||
storage: str
|
||||
size: int
|
||||
|
||||
|
||||
def _clean(value: object) -> str:
|
||||
return str(value or "").strip()
|
||||
|
||||
|
||||
def _now_iso() -> str:
|
||||
return datetime.now().strftime("%Y-%m-%d %H:%M:%S")
|
||||
|
||||
|
||||
def _safe_relative_path(path: str) -> str:
|
||||
value = str(path or "").strip().replace("\\", "/").lstrip("/")
|
||||
if not value:
|
||||
raise HTTPException(status_code=404, detail="image not found")
|
||||
parts = Path(value).parts
|
||||
if any(part in {"", ".", ".."} for part in parts):
|
||||
raise HTTPException(status_code=404, detail="image not found")
|
||||
return Path(*parts).as_posix()
|
||||
|
||||
|
||||
def _image_dimensions(payload: bytes) -> tuple[int, int] | None:
|
||||
try:
|
||||
with Image.open(io.BytesIO(payload)) as image:
|
||||
return image.size
|
||||
except Exception:
|
||||
return None
|
||||
|
||||
|
||||
def _is_image_rel(path: str) -> bool:
|
||||
try:
|
||||
safe_rel = _safe_relative_path(path)
|
||||
except HTTPException:
|
||||
return False
|
||||
return Path(safe_rel).suffix.lower() in IMAGE_EXTENSIONS
|
||||
|
||||
|
||||
def _local_image_path(relative_path: str) -> Path:
|
||||
rel = _safe_relative_path(relative_path)
|
||||
root = config.images_dir.resolve()
|
||||
path = (root / rel).resolve()
|
||||
try:
|
||||
path.relative_to(root)
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=404, detail="image not found") from exc
|
||||
return path
|
||||
|
||||
|
||||
def _read_json_object(path: Path) -> dict[str, object]:
|
||||
if not path.exists():
|
||||
return {}
|
||||
try:
|
||||
data = json.loads(path.read_text(encoding="utf-8"))
|
||||
except Exception:
|
||||
return {}
|
||||
return data if isinstance(data, dict) else {}
|
||||
|
||||
|
||||
def _write_json_object(path: Path, data: dict[str, object]) -> None:
|
||||
path.parent.mkdir(parents=True, exist_ok=True)
|
||||
tmp_path = path.with_suffix(path.suffix + ".tmp")
|
||||
tmp_path.write_text(json.dumps(data, ensure_ascii=False, indent=2) + "\n", encoding="utf-8")
|
||||
tmp_path.replace(path)
|
||||
|
||||
|
||||
class WebDAVClient:
|
||||
def __init__(self, settings: dict[str, object]):
|
||||
self.url = _clean(settings.get("webdav_url")).rstrip("/")
|
||||
self.username = _clean(settings.get("webdav_username"))
|
||||
self.password = _clean(settings.get("webdav_password"))
|
||||
self.root_path = _clean(settings.get("webdav_root_path")).strip("/")
|
||||
self.session = requests.Session()
|
||||
|
||||
def _auth_kwargs(self) -> dict[str, object]:
|
||||
return {"auth": (self.username, self.password)} if self.username or self.password else {}
|
||||
|
||||
def _request(self, method: str, url: str, **kwargs):
|
||||
response = self.session.request(method, url, timeout=30, **self._auth_kwargs(), **kwargs)
|
||||
if response.status_code >= 400 and not (method == "MKCOL" and response.status_code in {405}):
|
||||
raise ImageStorageError(f"WebDAV {method} failed: HTTP {response.status_code}")
|
||||
return response
|
||||
|
||||
def remote_url(self, rel: str = "") -> str:
|
||||
parts = [part for part in [self.root_path, _safe_relative_path(rel) if rel else ""] if part]
|
||||
encoded = "/".join(quote(part, safe="") for item in parts for part in item.split("/") if part)
|
||||
return f"{self.url}/{encoded}" if encoded else self.url
|
||||
|
||||
def ensure_dirs(self, rel: str) -> None:
|
||||
parts = [part for part in [self.root_path, Path(_safe_relative_path(rel)).parent.as_posix()] if part and part != "."]
|
||||
current = self.url
|
||||
for item in "/".join(parts).split("/"):
|
||||
if not item:
|
||||
continue
|
||||
current = f"{current}/{quote(item, safe='')}"
|
||||
response = self.session.request("MKCOL", current, timeout=30, **self._auth_kwargs())
|
||||
if response.status_code in {201, 405}:
|
||||
continue
|
||||
if response.status_code >= 400:
|
||||
raise ImageStorageError(f"WebDAV MKCOL failed: HTTP {response.status_code}")
|
||||
|
||||
def put(self, rel: str, payload: bytes, content_type: str = "image/png") -> str:
|
||||
self.ensure_dirs(rel)
|
||||
url = self.remote_url(rel)
|
||||
self._request("PUT", url, data=payload, headers={"Content-Type": content_type})
|
||||
return url
|
||||
|
||||
def get(self, rel: str) -> bytes:
|
||||
response = self._request("GET", self.remote_url(rel))
|
||||
return bytes(response.content)
|
||||
|
||||
def delete(self, rel: str) -> bool:
|
||||
response = self.session.request("DELETE", self.remote_url(rel), timeout=30, **self._auth_kwargs())
|
||||
if response.status_code in {200, 202, 204, 404}:
|
||||
return response.status_code != 404
|
||||
raise ImageStorageError(f"WebDAV DELETE failed: HTTP {response.status_code}")
|
||||
|
||||
def test(self) -> dict[str, object]:
|
||||
if not self.url:
|
||||
return {"ok": False, "status": 0, "error": "WebDAV URL is required"}
|
||||
if urlparse(self.url).scheme not in {"http", "https"}:
|
||||
return {"ok": False, "status": 0, "error": "invalid WebDAV URL"}
|
||||
test_rel = ".chatgpt2api_webdav_test.txt"
|
||||
try:
|
||||
self.put(test_rel, b"chatgpt2api webdav test\n", content_type="text/plain")
|
||||
self.delete(test_rel)
|
||||
return {"ok": True, "status": 200, "error": None}
|
||||
except ImageStorageError as exc:
|
||||
return {"ok": False, "status": 0, "error": str(exc)}
|
||||
except Exception as exc:
|
||||
return {"ok": False, "status": 0, "error": str(exc) or exc.__class__.__name__}
|
||||
finally:
|
||||
self.session.close()
|
||||
|
||||
|
||||
class ImageStorageService:
|
||||
def __init__(self, index_file: Path = IMAGE_INDEX_FILE):
|
||||
self.index_file = index_file
|
||||
self._index_lock = IMAGE_INDEX_LOCK
|
||||
|
||||
def settings(self) -> dict[str, object]:
|
||||
return config.get_image_storage_settings()
|
||||
|
||||
def mode(self) -> str:
|
||||
return _clean(self.settings().get("mode")) or "local"
|
||||
|
||||
def _load_index(self) -> dict[str, dict[str, object]]:
|
||||
raw = _read_json_object(self.index_file)
|
||||
items = raw.get("items")
|
||||
if not isinstance(items, dict):
|
||||
return {}
|
||||
return {str(key): value for key, value in items.items() if isinstance(value, dict)}
|
||||
|
||||
def _load_clean_index(self) -> dict[str, dict[str, object]]:
|
||||
items = self._load_index()
|
||||
return {rel: item for rel, item in items.items() if _is_image_rel(rel)}
|
||||
|
||||
def _save_index(self, items: dict[str, dict[str, object]]) -> None:
|
||||
_write_json_object(self.index_file, {"items": items})
|
||||
|
||||
def _public_url(self, rel: str, base_url: str | None = None) -> str:
|
||||
settings = self.settings()
|
||||
public_base_url = _clean(settings.get("public_base_url"))
|
||||
if public_base_url:
|
||||
return f"{public_base_url.rstrip('/')}/{_safe_relative_path(rel)}"
|
||||
return f"{(base_url or config.base_url).rstrip('/')}/images/{_safe_relative_path(rel)}"
|
||||
|
||||
def make_relative_path(self, image_data: bytes) -> str:
|
||||
file_hash = hashlib.md5(image_data).hexdigest()
|
||||
filename = f"{int(time.time())}_{file_hash}.png"
|
||||
relative_dir = Path(time.strftime("%Y"), time.strftime("%m"), time.strftime("%d"))
|
||||
return f"{relative_dir.as_posix()}/{filename}"
|
||||
|
||||
def save(self, image_data: bytes, base_url: str | None = None) -> StoredImage:
|
||||
config.cleanup_old_images()
|
||||
rel = self.make_relative_path(image_data)
|
||||
mode = self.mode()
|
||||
if mode not in {"local", "webdav", "both"}:
|
||||
mode = "local"
|
||||
stored_local = False
|
||||
stored_webdav = False
|
||||
remote_url = ""
|
||||
|
||||
if mode in {"local", "both"}:
|
||||
path = _local_image_path(rel)
|
||||
path.parent.mkdir(parents=True, exist_ok=True)
|
||||
path.write_bytes(image_data)
|
||||
stored_local = True
|
||||
|
||||
if mode in {"webdav", "both"}:
|
||||
remote_url = WebDAVClient(self.settings()).put(rel, image_data)
|
||||
stored_webdav = True
|
||||
|
||||
dimensions = _image_dimensions(image_data)
|
||||
item = {
|
||||
"rel": rel,
|
||||
"path": rel,
|
||||
"name": Path(rel).name,
|
||||
"date": "-".join(rel.split("/")[:3]),
|
||||
"size": len(image_data),
|
||||
"created_at": _now_iso(),
|
||||
"storage": "both" if stored_local and stored_webdav else ("webdav" if stored_webdav else "local"),
|
||||
"local": stored_local,
|
||||
"webdav": stored_webdav,
|
||||
"remote_url": remote_url,
|
||||
}
|
||||
if dimensions:
|
||||
item["width"], item["height"] = dimensions
|
||||
with self._index_lock:
|
||||
items = self._load_clean_index()
|
||||
items[rel] = item
|
||||
self._save_index(items)
|
||||
return StoredImage(rel=rel, url=self._public_url(rel, base_url), storage=str(item["storage"]), size=len(image_data))
|
||||
|
||||
def get_bytes(self, rel: str) -> bytes:
|
||||
safe_rel = _safe_relative_path(rel)
|
||||
if not _is_image_rel(safe_rel):
|
||||
raise HTTPException(status_code=404, detail="image not found")
|
||||
path = _local_image_path(safe_rel)
|
||||
if path.is_file():
|
||||
return path.read_bytes()
|
||||
item = self._load_clean_index().get(safe_rel, {})
|
||||
if item.get("webdav"):
|
||||
return WebDAVClient(self.settings()).get(safe_rel)
|
||||
raise HTTPException(status_code=404, detail="image not found")
|
||||
|
||||
def exists(self, rel: str) -> bool:
|
||||
safe_rel = _safe_relative_path(rel)
|
||||
if not _is_image_rel(safe_rel):
|
||||
return False
|
||||
if _local_image_path(safe_rel).is_file():
|
||||
return True
|
||||
item = self._load_clean_index().get(safe_rel, {})
|
||||
return bool(item.get("webdav"))
|
||||
|
||||
def has_local(self, rel: str) -> bool:
|
||||
safe_rel = _safe_relative_path(rel)
|
||||
return _is_image_rel(safe_rel) and _local_image_path(safe_rel).is_file()
|
||||
|
||||
def list_items(self, base_url: str, start_date: str = "", end_date: str = "") -> list[dict[str, object]]:
|
||||
with self._index_lock:
|
||||
indexed = self._load_clean_index()
|
||||
root = config.images_dir
|
||||
changed = False
|
||||
for path in root.rglob("*"):
|
||||
if not path.is_file() or not _is_image_rel(path.name):
|
||||
continue
|
||||
rel = path.relative_to(root).as_posix()
|
||||
if rel in indexed:
|
||||
continue
|
||||
dimensions = None
|
||||
try:
|
||||
dimensions = _image_dimensions(path.read_bytes())
|
||||
except Exception:
|
||||
dimensions = None
|
||||
indexed[rel] = {
|
||||
"rel": rel,
|
||||
"path": rel,
|
||||
"name": path.name,
|
||||
"date": "-".join(rel.split("/")[:3]) if len(rel.split("/")) >= 4 else datetime.fromtimestamp(path.stat().st_mtime).strftime("%Y-%m-%d"),
|
||||
"size": path.stat().st_size,
|
||||
"created_at": datetime.fromtimestamp(path.stat().st_mtime).strftime("%Y-%m-%d %H:%M:%S"),
|
||||
"storage": "local",
|
||||
"local": True,
|
||||
"webdav": False,
|
||||
**({"width": dimensions[0], "height": dimensions[1]} if dimensions else {}),
|
||||
}
|
||||
changed = True
|
||||
|
||||
items: list[dict[str, object]] = []
|
||||
for rel, item in list(indexed.items()):
|
||||
if not _is_image_rel(rel):
|
||||
indexed.pop(rel, None)
|
||||
changed = True
|
||||
continue
|
||||
local = _local_image_path(rel).is_file()
|
||||
webdav = bool(item.get("webdav"))
|
||||
if not local and not webdav:
|
||||
indexed.pop(rel, None)
|
||||
changed = True
|
||||
continue
|
||||
storage = "both" if local and webdav else ("webdav" if webdav else "local")
|
||||
if item.get("local") != local or item.get("storage") != storage:
|
||||
item = {
|
||||
**item,
|
||||
"local": local,
|
||||
"storage": storage,
|
||||
}
|
||||
indexed[rel] = item
|
||||
changed = True
|
||||
day = str(item.get("date") or "")
|
||||
if start_date and day < start_date:
|
||||
continue
|
||||
if end_date and day > end_date:
|
||||
continue
|
||||
items.append({
|
||||
**item,
|
||||
"rel": rel,
|
||||
"path": rel,
|
||||
"url": self._public_url(rel, base_url),
|
||||
})
|
||||
if changed:
|
||||
self._save_index(indexed)
|
||||
items.sort(key=lambda item: str(item.get("created_at") or ""), reverse=True)
|
||||
return items
|
||||
|
||||
def delete(self, rel: str) -> bool:
|
||||
safe_rel = _safe_relative_path(rel)
|
||||
removed = False
|
||||
path = _local_image_path(safe_rel)
|
||||
if path.is_file():
|
||||
path.unlink()
|
||||
removed = True
|
||||
with self._index_lock:
|
||||
items = self._load_clean_index()
|
||||
item = items.get(safe_rel, {})
|
||||
if item.get("webdav"):
|
||||
try:
|
||||
removed = WebDAVClient(self.settings()).delete(safe_rel) or removed
|
||||
except ImageStorageError:
|
||||
if not removed:
|
||||
raise
|
||||
if safe_rel in items:
|
||||
items.pop(safe_rel, None)
|
||||
self._save_index(items)
|
||||
return removed
|
||||
|
||||
def sync_all(self) -> dict[str, int]:
|
||||
settings = self.settings()
|
||||
if self.mode() not in {"webdav", "both"}:
|
||||
raise ImageStorageError("WebDAV 图片存储未启用")
|
||||
uploaded = 0
|
||||
skipped = 0
|
||||
failed = 0
|
||||
with self._index_lock:
|
||||
items = self._load_clean_index()
|
||||
client = WebDAVClient(settings)
|
||||
for path in sorted(config.images_dir.rglob("*")):
|
||||
if not path.is_file() or not _is_image_rel(path.name):
|
||||
continue
|
||||
rel = path.relative_to(config.images_dir).as_posix()
|
||||
item = items.get(rel, {})
|
||||
if item.get("webdav"):
|
||||
skipped += 1
|
||||
continue
|
||||
try:
|
||||
payload = path.read_bytes()
|
||||
remote_url = client.put(rel, payload)
|
||||
dimensions = _image_dimensions(payload)
|
||||
items[rel] = {
|
||||
**item,
|
||||
"rel": rel,
|
||||
"path": rel,
|
||||
"name": path.name,
|
||||
"date": "-".join(rel.split("/")[:3]) if len(rel.split("/")) >= 4 else datetime.fromtimestamp(path.stat().st_mtime).strftime("%Y-%m-%d"),
|
||||
"size": len(payload),
|
||||
"created_at": str(item.get("created_at") or datetime.fromtimestamp(path.stat().st_mtime).strftime("%Y-%m-%d %H:%M:%S")),
|
||||
"storage": "both",
|
||||
"local": True,
|
||||
"webdav": True,
|
||||
"remote_url": remote_url,
|
||||
**({"width": dimensions[0], "height": dimensions[1]} if dimensions else {}),
|
||||
}
|
||||
uploaded += 1
|
||||
except Exception:
|
||||
failed += 1
|
||||
self._save_index(items)
|
||||
return {"uploaded": uploaded, "skipped": skipped, "failed": failed}
|
||||
|
||||
def test_webdav(self) -> dict[str, object]:
|
||||
return WebDAVClient(self.settings()).test()
|
||||
|
||||
|
||||
image_storage_service = ImageStorageService()
|
||||
@@ -0,0 +1,76 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
from pathlib import Path
|
||||
|
||||
from services.config import DATA_DIR
|
||||
|
||||
TAGS_FILE = DATA_DIR / "image_tags.json"
|
||||
|
||||
|
||||
def _ensure_file() -> None:
|
||||
TAGS_FILE.parent.mkdir(parents=True, exist_ok=True)
|
||||
if not TAGS_FILE.exists():
|
||||
TAGS_FILE.write_text("{}", encoding="utf-8")
|
||||
|
||||
|
||||
def load_tags() -> dict[str, list[str]]:
|
||||
_ensure_file()
|
||||
try:
|
||||
data = json.loads(TAGS_FILE.read_text(encoding="utf-8"))
|
||||
except Exception:
|
||||
return {}
|
||||
return data if isinstance(data, dict) else {}
|
||||
|
||||
|
||||
def save_tags(data: dict[str, list[str]]) -> None:
|
||||
_ensure_file()
|
||||
TAGS_FILE.write_text(json.dumps(data, ensure_ascii=False, indent=2) + "\n", encoding="utf-8")
|
||||
|
||||
|
||||
def get_tags(image_rel: str) -> list[str]:
|
||||
return load_tags().get(image_rel, [])
|
||||
|
||||
|
||||
def set_tags(image_rel: str, tags: list[str]) -> list[str]:
|
||||
data = load_tags()
|
||||
cleaned = list(dict.fromkeys(t.strip() for t in tags if t.strip()))
|
||||
if cleaned:
|
||||
data[image_rel] = cleaned
|
||||
else:
|
||||
data.pop(image_rel, None)
|
||||
save_tags(data)
|
||||
return cleaned
|
||||
|
||||
|
||||
def remove_tags(image_rel: str) -> None:
|
||||
data = load_tags()
|
||||
if data.pop(image_rel, None) is not None:
|
||||
save_tags(data)
|
||||
|
||||
|
||||
def delete_tag(tag: str) -> int:
|
||||
"""从所有图片中删除指定标签,返回受影响的图片数。"""
|
||||
data = load_tags()
|
||||
count = 0
|
||||
for rel in list(data):
|
||||
if tag in data[rel]:
|
||||
data[rel] = [t for t in data[rel] if t != tag]
|
||||
if not data[rel]:
|
||||
del data[rel]
|
||||
count += 1
|
||||
if count > 0:
|
||||
save_tags(data)
|
||||
return count
|
||||
|
||||
|
||||
def get_all_tags() -> list[str]:
|
||||
data = load_tags()
|
||||
seen: set[str] = set()
|
||||
result: list[str] = []
|
||||
for tags in data.values():
|
||||
for t in tags:
|
||||
if t not in seen:
|
||||
seen.add(t)
|
||||
result.append(t)
|
||||
return result
|
||||
@@ -0,0 +1,576 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import threading
|
||||
import time
|
||||
from collections.abc import Callable
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
from services.config import DATA_DIR, config
|
||||
from services.content_filter import request_text
|
||||
from services.log_service import LOG_TYPE_CALL, log_service
|
||||
from services.protocol import openai_v1_image_edit, openai_v1_image_generations
|
||||
from utils.log import logger
|
||||
|
||||
TASK_STATUS_QUEUED = "queued"
|
||||
TASK_STATUS_RUNNING = "running"
|
||||
TASK_STATUS_SUCCESS = "success"
|
||||
TASK_STATUS_ERROR = "error"
|
||||
TERMINAL_STATUSES = {TASK_STATUS_SUCCESS, TASK_STATUS_ERROR}
|
||||
UNFINISHED_STATUSES = {TASK_STATUS_QUEUED, TASK_STATUS_RUNNING}
|
||||
|
||||
|
||||
def _now_iso() -> str:
|
||||
return datetime.now().strftime("%Y-%m-%d %H:%M:%S")
|
||||
|
||||
|
||||
def _timestamp(value: object) -> float:
|
||||
if not isinstance(value, str) or not value.strip():
|
||||
return 0.0
|
||||
for fmt in ("%Y-%m-%d %H:%M:%S", "%Y-%m-%dT%H:%M:%S.%f", "%Y-%m-%dT%H:%M:%S"):
|
||||
try:
|
||||
return datetime.strptime(value[:26], fmt).timestamp()
|
||||
except ValueError:
|
||||
continue
|
||||
try:
|
||||
return datetime.fromisoformat(value.replace("Z", "+00:00")).timestamp()
|
||||
except Exception:
|
||||
return 0.0
|
||||
|
||||
|
||||
def _clean(value: object, default: str = "") -> str:
|
||||
return str(value or default).strip()
|
||||
|
||||
|
||||
def _owner_id(identity: dict[str, object]) -> str:
|
||||
return _clean(identity.get("id")) or "anonymous"
|
||||
|
||||
|
||||
def _task_key(owner_id: str, task_id: str) -> str:
|
||||
return f"{owner_id}:{task_id}"
|
||||
|
||||
|
||||
def _collect_image_urls(data: list[Any]) -> list[str]:
|
||||
urls: list[str] = []
|
||||
for item in data:
|
||||
if isinstance(item, dict):
|
||||
url = item.get("url")
|
||||
if isinstance(url, str) and url:
|
||||
urls.append(url)
|
||||
return urls
|
||||
|
||||
|
||||
def _public_task(task: dict[str, Any]) -> dict[str, Any]:
|
||||
item = {
|
||||
"id": task.get("id"),
|
||||
"status": task.get("status"),
|
||||
"mode": task.get("mode"),
|
||||
"model": task.get("model"),
|
||||
"size": task.get("size"),
|
||||
"quality": task.get("quality"),
|
||||
"created_at": task.get("created_at"),
|
||||
"updated_at": task.get("updated_at"),
|
||||
}
|
||||
if task.get("conversation_id"):
|
||||
item["conversation_id"] = task.get("conversation_id")
|
||||
if task.get("data") is not None:
|
||||
item["data"] = task.get("data")
|
||||
if task.get("usage") is not None:
|
||||
item["usage"] = task.get("usage")
|
||||
if task.get("error"):
|
||||
item["error"] = task.get("error")
|
||||
if task.get("progress"):
|
||||
item["progress"] = task.get("progress")
|
||||
if task.get("duration_ms") is not None:
|
||||
item["duration_ms"] = task.get("duration_ms")
|
||||
if task.get("stage_durations_ms"):
|
||||
item["stage_durations_ms"] = dict(task["stage_durations_ms"])
|
||||
if task.get("status") in (TASK_STATUS_RUNNING, TASK_STATUS_QUEUED):
|
||||
if task.get("status") == TASK_STATUS_RUNNING:
|
||||
# Include account selection, upload and the upstream response wait.
|
||||
base_ts = task.get("started_ts")
|
||||
else:
|
||||
# QUEUED 状态从 created_ts 开始计时(排队等待中)
|
||||
base_ts = task.get("created_ts") or task.get("updated_ts")
|
||||
if base_ts:
|
||||
item["elapsed_secs"] = round(time.time() - base_ts, 1)
|
||||
return item
|
||||
|
||||
|
||||
class ImageTaskService:
|
||||
def __init__(
|
||||
self,
|
||||
path: Path,
|
||||
*,
|
||||
generation_handler: Callable[[dict[str, Any]], dict[str, Any]] = openai_v1_image_generations.handle,
|
||||
edit_handler: Callable[[dict[str, Any]], dict[str, Any]] = openai_v1_image_edit.handle,
|
||||
retention_days_getter: Callable[[], int] | None = None,
|
||||
):
|
||||
self.path = path
|
||||
self.generation_handler = generation_handler
|
||||
self.edit_handler = edit_handler
|
||||
self.retention_days_getter = retention_days_getter or (lambda: config.image_retention_days)
|
||||
self._lock = threading.RLock()
|
||||
self._tasks: dict[str, dict[str, Any]] = {}
|
||||
self.path.parent.mkdir(parents=True, exist_ok=True)
|
||||
with self._lock:
|
||||
self._tasks = self._load_locked()
|
||||
changed = self._recover_unfinished_locked()
|
||||
changed = self._cleanup_locked() or changed
|
||||
if changed:
|
||||
self._save_locked()
|
||||
|
||||
def submit_generation(
|
||||
self,
|
||||
identity: dict[str, object],
|
||||
*,
|
||||
client_task_id: str,
|
||||
prompt: str,
|
||||
model: str,
|
||||
size: str | None,
|
||||
quality: str = "auto",
|
||||
base_url: str = "",
|
||||
) -> dict[str, Any]:
|
||||
payload = {
|
||||
"prompt": prompt,
|
||||
"model": model,
|
||||
"n": 1,
|
||||
"size": size,
|
||||
"quality": quality,
|
||||
"response_format": "url",
|
||||
"base_url": base_url,
|
||||
}
|
||||
return self._submit(identity, client_task_id=client_task_id, mode="generate", payload=payload)
|
||||
|
||||
def submit_edit(
|
||||
self,
|
||||
identity: dict[str, object],
|
||||
*,
|
||||
client_task_id: str,
|
||||
prompt: str,
|
||||
model: str,
|
||||
size: str | None,
|
||||
quality: str = "auto",
|
||||
base_url: str = "",
|
||||
images: list[tuple[bytes, str, str]] | None = None,
|
||||
masks: list[tuple[bytes, str, str]] | None = None,
|
||||
) -> dict[str, Any]:
|
||||
payload = {
|
||||
"prompt": prompt,
|
||||
"images": images or [],
|
||||
"mask": masks or [],
|
||||
"model": model,
|
||||
"n": 1,
|
||||
"size": size,
|
||||
"quality": quality,
|
||||
"response_format": "url",
|
||||
"base_url": base_url,
|
||||
}
|
||||
return self._submit(identity, client_task_id=client_task_id, mode="edit", payload=payload)
|
||||
|
||||
def list_tasks(self, identity: dict[str, object], task_ids: list[str]) -> dict[str, Any]:
|
||||
owner = _owner_id(identity)
|
||||
requested_ids = [_clean(task_id) for task_id in task_ids if _clean(task_id)]
|
||||
with self._lock:
|
||||
if self._cleanup_locked():
|
||||
self._save_locked()
|
||||
items = []
|
||||
missing_ids = []
|
||||
for task_id in requested_ids:
|
||||
task = self._tasks.get(_task_key(owner, task_id))
|
||||
if task is None:
|
||||
missing_ids.append(task_id)
|
||||
else:
|
||||
items.append(_public_task(task))
|
||||
if not requested_ids:
|
||||
items = [
|
||||
_public_task(task)
|
||||
for task in self._tasks.values()
|
||||
if task.get("owner_id") == owner
|
||||
]
|
||||
items.sort(key=lambda item: str(item.get("updated_at") or ""), reverse=True)
|
||||
missing_ids = []
|
||||
return {"items": items, "missing_ids": missing_ids}
|
||||
|
||||
def _submit(
|
||||
self,
|
||||
identity: dict[str, object],
|
||||
*,
|
||||
client_task_id: str,
|
||||
mode: str,
|
||||
payload: dict[str, Any],
|
||||
) -> dict[str, Any]:
|
||||
task_id = _clean(client_task_id)
|
||||
if not task_id:
|
||||
raise ValueError("client_task_id is required")
|
||||
owner = _owner_id(identity)
|
||||
key = _task_key(owner, task_id)
|
||||
now = _now_iso()
|
||||
should_start = False
|
||||
with self._lock:
|
||||
cleaned = self._cleanup_locked()
|
||||
task = self._tasks.get(key)
|
||||
if task is not None:
|
||||
if cleaned:
|
||||
self._save_locked()
|
||||
return _public_task(task)
|
||||
task = {
|
||||
"id": task_id,
|
||||
"owner_id": owner,
|
||||
"status": TASK_STATUS_QUEUED,
|
||||
"mode": mode,
|
||||
"model": _clean(payload.get("model"), "gpt-image-2"),
|
||||
"size": _clean(payload.get("size")),
|
||||
"quality": _clean(payload.get("quality"), "auto"),
|
||||
"created_at": now,
|
||||
"updated_at": now,
|
||||
"created_ts": time.time(),
|
||||
}
|
||||
self._tasks[key] = task
|
||||
self._save_locked()
|
||||
should_start = True
|
||||
|
||||
if should_start:
|
||||
thread = threading.Thread(
|
||||
target=self._run_task,
|
||||
args=(key, mode, payload, dict(identity), _clean(payload.get("model"), "gpt-image-2")),
|
||||
name=f"image-task-{task_id[:16]}",
|
||||
daemon=True,
|
||||
)
|
||||
thread.start()
|
||||
return _public_task(task)
|
||||
|
||||
def _run_task(
|
||||
self,
|
||||
key: str,
|
||||
mode: str,
|
||||
payload: dict[str, Any],
|
||||
identity: dict[str, object],
|
||||
model: str,
|
||||
) -> None:
|
||||
started = time.time()
|
||||
self._update_task(key, status=TASK_STATUS_RUNNING, error="", started_ts=started)
|
||||
stage_started = time.monotonic()
|
||||
current_stage = "getting_account"
|
||||
stage_durations: dict[str, int] = {}
|
||||
timing_lock = threading.Lock()
|
||||
|
||||
def advance_stage(step: str | None) -> dict[str, int]:
|
||||
nonlocal stage_started, current_stage
|
||||
with timing_lock:
|
||||
now = time.monotonic()
|
||||
stage_durations[current_stage] = stage_durations.get(current_stage, 0) + max(0, int((now - stage_started) * 1000))
|
||||
stage_started = now
|
||||
if step:
|
||||
current_stage = step
|
||||
return dict(stage_durations)
|
||||
|
||||
# 创建进度回调,每个步骤完成后更新任务状态
|
||||
def progress_callback(step: str) -> None:
|
||||
self._update_task(key, progress=step, stage_durations_ms=advance_stage(step))
|
||||
# 将进度回调添加到 payload 中(handler 会提取并传递给 ConversationRequest)
|
||||
payload_with_progress = {**payload, "progress_callback": progress_callback}
|
||||
try:
|
||||
handler = self.edit_handler if mode == "edit" else self.generation_handler
|
||||
result = handler(payload_with_progress)
|
||||
if not isinstance(result, dict):
|
||||
raise RuntimeError("image task returned streaming result unexpectedly")
|
||||
data = result.get("data")
|
||||
account_email = _clean(result.get("_account_email") or result.get("account_email"))
|
||||
if not isinstance(data, list) or not data:
|
||||
upstream = _clean(result.get("message"))
|
||||
if upstream:
|
||||
message = upstream
|
||||
else:
|
||||
message = "号池中没有可用账号或所有账号均被限流,请检查号池状态(账号额度、是否被封禁、是否到达生图上限)"
|
||||
error = RuntimeError(message)
|
||||
if account_email:
|
||||
setattr(error, "account_email", account_email)
|
||||
raise error
|
||||
usage = result.get("usage")
|
||||
duration_ms = int((time.time() - started) * 1000)
|
||||
timings = advance_stage(None)
|
||||
self._update_task(key, status=TASK_STATUS_SUCCESS, data=data, usage=usage, error="", duration_ms=duration_ms, stage_durations_ms=timings)
|
||||
logger.info({"event": "image_task_timings", "task_id": payload.get("client_task_id"), "duration_ms": duration_ms, "stages_ms": timings})
|
||||
self._log_call(
|
||||
identity,
|
||||
mode,
|
||||
model,
|
||||
started,
|
||||
"调用完成",
|
||||
request_preview=request_text(payload.get("prompt")),
|
||||
urls=_collect_image_urls(data),
|
||||
account_email=account_email,
|
||||
)
|
||||
except Exception as exc:
|
||||
error_message = str(exc) or "image task failed"
|
||||
account_email = _clean(getattr(exc, "account_email", ""))
|
||||
conversation_id = _clean(getattr(exc, "conversation_id", ""))
|
||||
duration_ms = int((time.time() - started) * 1000)
|
||||
timings = advance_stage(None)
|
||||
self._update_task(key, status=TASK_STATUS_ERROR, error=error_message, data=[],
|
||||
duration_ms=duration_ms, stage_durations_ms=timings,
|
||||
**({"conversation_id": conversation_id} if conversation_id else {}))
|
||||
logger.info({"event": "image_task_timings", "task_id": payload.get("client_task_id"), "duration_ms": duration_ms, "stages_ms": timings})
|
||||
self._log_call(
|
||||
identity,
|
||||
mode,
|
||||
model,
|
||||
started,
|
||||
"调用失败",
|
||||
request_preview=request_text(payload.get("prompt")),
|
||||
status="failed",
|
||||
error=error_message,
|
||||
account_email=account_email,
|
||||
)
|
||||
|
||||
def _log_call(
|
||||
self,
|
||||
identity: dict[str, object],
|
||||
mode: str,
|
||||
model: str,
|
||||
started: float,
|
||||
suffix: str,
|
||||
*,
|
||||
request_preview: str = "",
|
||||
status: str = "success",
|
||||
error: str = "",
|
||||
urls: list[str] | None = None,
|
||||
account_email: str = "",
|
||||
) -> None:
|
||||
endpoint = "/v1/images/edits" if mode == "edit" else "/v1/images/generations"
|
||||
summary_prefix = "图生图" if mode == "edit" else "文生图"
|
||||
detail = {
|
||||
"key_id": identity.get("id"),
|
||||
"key_name": identity.get("name"),
|
||||
"role": identity.get("role"),
|
||||
"endpoint": endpoint,
|
||||
"model": model,
|
||||
"started_at": datetime.fromtimestamp(started).strftime("%Y-%m-%d %H:%M:%S"),
|
||||
"ended_at": _now_iso(),
|
||||
"duration_ms": int((time.time() - started) * 1000),
|
||||
"status": status,
|
||||
}
|
||||
if request_preview:
|
||||
detail["request_text"] = request_preview
|
||||
if error:
|
||||
detail["error"] = error
|
||||
if account_email:
|
||||
detail["account_email"] = account_email
|
||||
if urls:
|
||||
detail["urls"] = list(dict.fromkeys(urls))
|
||||
try:
|
||||
log_service.add(LOG_TYPE_CALL, f"{summary_prefix}{suffix}", detail)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def _update_task(self, key: str, **updates: Any) -> None:
|
||||
with self._lock:
|
||||
task = self._tasks.get(key)
|
||||
if task is None:
|
||||
return
|
||||
task.update(updates)
|
||||
task["updated_at"] = _now_iso()
|
||||
task["updated_ts"] = time.time()
|
||||
self._save_locked()
|
||||
|
||||
def _load_locked(self) -> dict[str, dict[str, Any]]:
|
||||
if not self.path.exists():
|
||||
return {}
|
||||
try:
|
||||
raw = json.loads(self.path.read_text(encoding="utf-8"))
|
||||
except Exception:
|
||||
return {}
|
||||
raw_items = raw.get("tasks") if isinstance(raw, dict) else raw
|
||||
if not isinstance(raw_items, list):
|
||||
return {}
|
||||
tasks: dict[str, dict[str, Any]] = {}
|
||||
for item in raw_items:
|
||||
if not isinstance(item, dict):
|
||||
continue
|
||||
task_id = _clean(item.get("id"))
|
||||
owner = _clean(item.get("owner_id"))
|
||||
if not task_id or not owner:
|
||||
continue
|
||||
status = _clean(item.get("status"))
|
||||
if status not in {TASK_STATUS_QUEUED, TASK_STATUS_RUNNING, TASK_STATUS_SUCCESS, TASK_STATUS_ERROR}:
|
||||
status = TASK_STATUS_ERROR
|
||||
task = {
|
||||
"id": task_id,
|
||||
"owner_id": owner,
|
||||
"status": status,
|
||||
"mode": "edit" if item.get("mode") == "edit" else "generate",
|
||||
"model": _clean(item.get("model"), "gpt-image-2"),
|
||||
"size": _clean(item.get("size")),
|
||||
"quality": _clean(item.get("quality"), "auto"),
|
||||
"created_at": _clean(item.get("created_at"), _now_iso()),
|
||||
"updated_at": _clean(item.get("updated_at"), _clean(item.get("created_at"), _now_iso())),
|
||||
"created_ts": item.get("created_ts"),
|
||||
"updated_ts": item.get("updated_ts"),
|
||||
"started_ts": item.get("started_ts"),
|
||||
"duration_ms": item.get("duration_ms"),
|
||||
}
|
||||
data = item.get("data")
|
||||
if isinstance(data, list):
|
||||
task["data"] = data
|
||||
usage = item.get("usage")
|
||||
if isinstance(usage, dict):
|
||||
task["usage"] = usage
|
||||
timings = item.get("stage_durations_ms")
|
||||
if isinstance(timings, dict):
|
||||
task["stage_durations_ms"] = {
|
||||
str(stage): duration for stage, duration in timings.items()
|
||||
if isinstance(duration, int) and duration >= 0
|
||||
}
|
||||
error = _clean(item.get("error"))
|
||||
if error:
|
||||
task["error"] = error
|
||||
tasks[_task_key(owner, task_id)] = task
|
||||
return tasks
|
||||
|
||||
def _save_locked(self) -> None:
|
||||
items = sorted(self._tasks.values(), key=lambda item: str(item.get("updated_at") or ""), reverse=True)
|
||||
tmp_path = self.path.with_suffix(self.path.suffix + ".tmp")
|
||||
tmp_path.write_text(json.dumps({"tasks": items}, ensure_ascii=False, indent=2) + "\n", encoding="utf-8")
|
||||
tmp_path.replace(self.path)
|
||||
|
||||
def _recover_unfinished_locked(self) -> bool:
|
||||
changed = False
|
||||
for task in self._tasks.values():
|
||||
if task.get("status") in UNFINISHED_STATUSES:
|
||||
task["status"] = TASK_STATUS_ERROR
|
||||
task["error"] = "服务已重启,未完成的图片任务已中断"
|
||||
task["updated_at"] = _now_iso()
|
||||
changed = True
|
||||
return changed
|
||||
|
||||
def _cleanup_locked(self) -> bool:
|
||||
try:
|
||||
retention_days = max(1, int(self.retention_days_getter()))
|
||||
except Exception:
|
||||
retention_days = 30
|
||||
cutoff = time.time() - retention_days * 86400
|
||||
removed_keys = [
|
||||
key
|
||||
for key, task in self._tasks.items()
|
||||
if task.get("status") in TERMINAL_STATUSES and _timestamp(task.get("updated_at")) < cutoff
|
||||
]
|
||||
for key in removed_keys:
|
||||
self._tasks.pop(key, None)
|
||||
return bool(removed_keys)
|
||||
|
||||
def resume_poll(
|
||||
self,
|
||||
identity: dict[str, object],
|
||||
task_id: str,
|
||||
extra_timeout_secs: float = 30.0,
|
||||
) -> dict[str, Any]:
|
||||
"""恢复对已超时任务的轮询,额外等待 extra_timeout_secs 秒。"""
|
||||
owner = _owner_id(identity)
|
||||
key = _task_key(owner, _clean(task_id))
|
||||
with self._lock:
|
||||
task = self._tasks.get(key)
|
||||
if task is None:
|
||||
raise ValueError("task not found")
|
||||
if task.get("status") != TASK_STATUS_ERROR:
|
||||
raise ValueError("task is not in error state")
|
||||
error_msg = _clean(task.get("error"))
|
||||
if "超时" not in error_msg:
|
||||
raise ValueError("task error is not a timeout error")
|
||||
conversation_id = _clean(task.get("conversation_id"))
|
||||
if not conversation_id:
|
||||
raise ValueError("task has no conversation_id")
|
||||
mode = task.get("mode", "generate")
|
||||
model = task.get("model", "gpt-image-2")
|
||||
# 将任务状态重置为 running
|
||||
self._update_task(key, status=TASK_STATUS_RUNNING, error="")
|
||||
|
||||
# 启动新线程继续轮询
|
||||
thread = threading.Thread(
|
||||
target=self._run_resume_poll,
|
||||
args=(key, conversation_id, extra_timeout_secs, dict(identity), mode, model),
|
||||
name=f"image-resume-{_clean(task_id)[:16]}",
|
||||
daemon=True,
|
||||
)
|
||||
thread.start()
|
||||
return _public_task(task)
|
||||
|
||||
def _run_resume_poll(
|
||||
self,
|
||||
key: str,
|
||||
conversation_id: str,
|
||||
extra_timeout_secs: float,
|
||||
identity: dict[str, object],
|
||||
mode: str,
|
||||
model: str,
|
||||
) -> None:
|
||||
"""后台线程:继续轮询已有 conversation_id 的图片结果。"""
|
||||
started = time.time()
|
||||
backend = None
|
||||
try:
|
||||
from services.openai_backend_api import OpenAIBackendAPI
|
||||
from services.protocol.conversation import format_image_result
|
||||
|
||||
backend = OpenAIBackendAPI(proxy_url=config.proxy_url or None)
|
||||
file_ids, sediment_ids = backend._poll_image_results(
|
||||
conversation_id,
|
||||
extra_timeout_secs,
|
||||
)
|
||||
if not file_ids and not sediment_ids:
|
||||
raise RuntimeError(
|
||||
f"继续等待 {extra_timeout_secs} 秒后仍未找到图片结果。"
|
||||
)
|
||||
|
||||
image_urls = backend.resolve_conversation_image_urls(
|
||||
conversation_id, file_ids, sediment_ids, poll=False,
|
||||
)
|
||||
if not image_urls:
|
||||
raise RuntimeError("图片 URL 解析失败")
|
||||
|
||||
image_items = [
|
||||
{"b64_json": __import__("base64").b64encode(image_data).decode("ascii")}
|
||||
for image_data in backend.download_image_bytes(image_urls)
|
||||
]
|
||||
# 获取 task 的原始 prompt(从 _public_task 的 mode 判断)
|
||||
with self._lock:
|
||||
task = self._tasks.get(key)
|
||||
quality = _clean(task.get("quality"), "auto") if task else "auto"
|
||||
size = _clean(task.get("size")) if task else None
|
||||
data = format_image_result(
|
||||
image_items,
|
||||
"", # prompt 已不重要,结果已经拿到了
|
||||
"b64_json",
|
||||
"",
|
||||
int(time.time()),
|
||||
)["data"]
|
||||
self._update_task(key, status=TASK_STATUS_SUCCESS, data=data, error="", duration_ms=int((time.time() - started) * 1000))
|
||||
self._log_call(
|
||||
identity,
|
||||
mode,
|
||||
model,
|
||||
started,
|
||||
"调用完成(续轮询)",
|
||||
status="success",
|
||||
urls=_collect_image_urls(data),
|
||||
)
|
||||
except Exception as exc:
|
||||
error_message = str(exc) or "resume poll failed"
|
||||
duration_ms = int((time.time() - started) * 1000)
|
||||
self._update_task(key, status=TASK_STATUS_ERROR, error=error_message, data=[], duration_ms=duration_ms)
|
||||
self._log_call(
|
||||
identity,
|
||||
mode,
|
||||
model,
|
||||
started,
|
||||
"调用失败(续轮询)",
|
||||
status="failed",
|
||||
error=error_message,
|
||||
)
|
||||
finally:
|
||||
if backend is not None:
|
||||
backend.close()
|
||||
|
||||
|
||||
image_task_service = ImageTaskService(DATA_DIR / "image_tasks.json")
|
||||
@@ -0,0 +1,337 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import hashlib
|
||||
import json
|
||||
import itertools
|
||||
import time
|
||||
from dataclasses import dataclass, field
|
||||
from datetime import datetime
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
from uuid import uuid4
|
||||
|
||||
from fastapi import HTTPException
|
||||
from fastapi.concurrency import run_in_threadpool
|
||||
from fastapi.responses import JSONResponse, StreamingResponse
|
||||
|
||||
from services.config import DATA_DIR
|
||||
from services.protocol.error_response import anthropic_error_response, openai_error_response
|
||||
from utils.helper import anthropic_sse_stream, sse_json_stream
|
||||
|
||||
LOG_TYPE_CALL = "call"
|
||||
LOG_TYPE_ACCOUNT = "account"
|
||||
INTERNAL_RESPONSE_KEYS = {"_account_email", "_conversation_id"}
|
||||
|
||||
|
||||
class LogService:
|
||||
def __init__(self, path: Path):
|
||||
self.path = path
|
||||
self.path.parent.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
@staticmethod
|
||||
def _legacy_id(raw_line: str, line_number: int) -> str:
|
||||
payload = f"{line_number}:{raw_line}".encode("utf-8", errors="ignore")
|
||||
return hashlib.sha1(payload).hexdigest()[:24]
|
||||
|
||||
def _parse_line(self, raw_line: str, line_number: int) -> dict[str, Any] | None:
|
||||
try:
|
||||
item = json.loads(raw_line)
|
||||
except Exception:
|
||||
return None
|
||||
if not isinstance(item, dict):
|
||||
return None
|
||||
parsed = dict(item)
|
||||
parsed["id"] = str(parsed.get("id") or self._legacy_id(raw_line, line_number))
|
||||
return parsed
|
||||
|
||||
@staticmethod
|
||||
def _serialize_item(item: dict[str, Any]) -> str:
|
||||
return json.dumps(item, ensure_ascii=False, separators=(",", ":"))
|
||||
|
||||
@staticmethod
|
||||
def _matches_filters(item: dict[str, Any], *, type: str = "", start_date: str = "", end_date: str = "") -> bool:
|
||||
t = str(item.get("time") or "")
|
||||
day = t[:10]
|
||||
if type and item.get("type") != type:
|
||||
return False
|
||||
if start_date and day < start_date:
|
||||
return False
|
||||
if end_date and day > end_date:
|
||||
return False
|
||||
return True
|
||||
|
||||
def add(self, type: str, summary: str = "", detail: dict[str, Any] | None = None, **data: Any) -> None:
|
||||
item = {
|
||||
"id": uuid4().hex,
|
||||
"time": datetime.now().strftime("%Y-%m-%d %H:%M:%S"),
|
||||
"type": type,
|
||||
"summary": summary,
|
||||
"detail": detail or data,
|
||||
}
|
||||
with self.path.open("a", encoding="utf-8") as file:
|
||||
file.write(self._serialize_item(item) + "\n")
|
||||
|
||||
def list(self, type: str = "", start_date: str = "", end_date: str = "", limit: int = 200) -> list[dict[str, Any]]:
|
||||
if not self.path.exists():
|
||||
return []
|
||||
items: list[dict[str, Any]] = []
|
||||
lines = self.path.read_text(encoding="utf-8").splitlines()
|
||||
for line_number in range(len(lines) - 1, -1, -1):
|
||||
item = self._parse_line(lines[line_number], line_number)
|
||||
if item is None:
|
||||
continue
|
||||
if not self._matches_filters(item, type=type, start_date=start_date, end_date=end_date):
|
||||
continue
|
||||
items.append(item)
|
||||
if len(items) >= limit:
|
||||
break
|
||||
return items
|
||||
|
||||
def delete(self, ids: list[str]) -> dict[str, int]:
|
||||
target_ids = {str(item or "").strip() for item in ids if str(item or "").strip()}
|
||||
if not self.path.exists() or not target_ids:
|
||||
return {"removed": 0}
|
||||
lines = self.path.read_text(encoding="utf-8").splitlines()
|
||||
kept_lines: list[str] = []
|
||||
removed = 0
|
||||
for line_number, raw_line in enumerate(lines):
|
||||
item = self._parse_line(raw_line, line_number)
|
||||
if item is None:
|
||||
kept_lines.append(raw_line)
|
||||
continue
|
||||
if str(item.get("id") or "") in target_ids:
|
||||
removed += 1
|
||||
continue
|
||||
kept_lines.append(self._serialize_item(item))
|
||||
content = "\n".join(kept_lines)
|
||||
if content:
|
||||
content += "\n"
|
||||
self.path.write_text(content, encoding="utf-8")
|
||||
return {"removed": removed}
|
||||
|
||||
|
||||
log_service = LogService(DATA_DIR / "logs.jsonl")
|
||||
|
||||
|
||||
def _collect_urls(value: object) -> list[str]:
|
||||
urls: list[str] = []
|
||||
if isinstance(value, dict):
|
||||
for key, item in value.items():
|
||||
if key == "url" and isinstance(item, str):
|
||||
urls.append(item)
|
||||
elif key == "urls" and isinstance(item, list):
|
||||
urls.extend(str(url) for url in item if isinstance(url, str))
|
||||
else:
|
||||
urls.extend(_collect_urls(item))
|
||||
elif isinstance(value, list):
|
||||
for item in value:
|
||||
urls.extend(_collect_urls(item))
|
||||
return urls
|
||||
|
||||
|
||||
def _collect_account_emails(value: object) -> list[str]:
|
||||
emails: list[str] = []
|
||||
if isinstance(value, dict):
|
||||
for key, item in value.items():
|
||||
if key in {"_account_email", "account_email"} and isinstance(item, str) and item.strip():
|
||||
emails.append(item.strip())
|
||||
else:
|
||||
emails.extend(_collect_account_emails(item))
|
||||
elif isinstance(value, list):
|
||||
for item in value:
|
||||
emails.extend(_collect_account_emails(item))
|
||||
return emails
|
||||
|
||||
|
||||
def _collect_conversation_ids(value: object) -> list[str]:
|
||||
ids: list[str] = []
|
||||
if isinstance(value, dict):
|
||||
for key, item in value.items():
|
||||
if key == "_conversation_id" and isinstance(item, str) and item.strip():
|
||||
ids.append(item.strip())
|
||||
else:
|
||||
ids.extend(_collect_conversation_ids(item))
|
||||
elif isinstance(value, list):
|
||||
for item in value:
|
||||
ids.extend(_collect_conversation_ids(item))
|
||||
return ids
|
||||
|
||||
|
||||
def _strip_internal_response_fields(value: object) -> object:
|
||||
if isinstance(value, dict):
|
||||
return {
|
||||
key: _strip_internal_response_fields(item)
|
||||
for key, item in value.items()
|
||||
if key not in INTERNAL_RESPONSE_KEYS
|
||||
}
|
||||
if isinstance(value, list):
|
||||
return [_strip_internal_response_fields(item) for item in value]
|
||||
return value
|
||||
|
||||
|
||||
def _request_excerpt(text: object, limit: int = 1000) -> str:
|
||||
value = str(text or "").strip()
|
||||
if not value:
|
||||
return ""
|
||||
normalized = " ".join(value.split())
|
||||
if len(normalized) <= limit:
|
||||
return normalized
|
||||
return normalized[: limit - 1].rstrip() + "…"
|
||||
|
||||
|
||||
def _image_error_response(exc: Exception) -> JSONResponse:
|
||||
from services.protocol.conversation import public_image_error_message
|
||||
|
||||
message = public_image_error_message(str(exc))
|
||||
if "no available image quota" in message.lower():
|
||||
return openai_error_response(
|
||||
{
|
||||
"error": {
|
||||
"message": "no available image quota",
|
||||
"type": "insufficient_quota",
|
||||
"param": None,
|
||||
"code": "insufficient_quota",
|
||||
}
|
||||
},
|
||||
429,
|
||||
)
|
||||
if hasattr(exc, "to_openai_error") and hasattr(exc, "status_code"):
|
||||
return JSONResponse(status_code=int(exc.status_code), content=exc.to_openai_error())
|
||||
return openai_error_response(message, 502)
|
||||
|
||||
|
||||
def _protocol_error_response(exc: Exception, status_code: int, sse: str) -> JSONResponse:
|
||||
message = str(exc)
|
||||
if sse == "anthropic":
|
||||
return anthropic_error_response(message, status_code)
|
||||
return openai_error_response(message, status_code)
|
||||
|
||||
|
||||
def _next_item(items):
|
||||
try:
|
||||
return True, next(items)
|
||||
except StopIteration:
|
||||
return False, None
|
||||
|
||||
|
||||
@dataclass
|
||||
class LoggedCall:
|
||||
identity: dict[str, object]
|
||||
endpoint: str
|
||||
model: str
|
||||
summary: str
|
||||
started: float = field(default_factory=time.time)
|
||||
request_text: str = ""
|
||||
request_shape: dict[str, int] | None = None
|
||||
|
||||
async def run(self, handler, *args, sse: str = "openai"):
|
||||
from services.protocol.conversation import ImageGenerationError
|
||||
|
||||
try:
|
||||
result = await run_in_threadpool(handler, *args)
|
||||
except ImageGenerationError as exc:
|
||||
self.log("调用失败", status="failed", error=str(exc), account_email=getattr(exc, "account_email", ""),
|
||||
conversation_id=getattr(exc, "conversation_id", ""))
|
||||
return _image_error_response(exc)
|
||||
except HTTPException as exc:
|
||||
self.log("调用失败", status="failed", error=str(exc.detail))
|
||||
raise
|
||||
except Exception as exc:
|
||||
self.log("调用失败", status="failed", error=str(exc), account_email=getattr(exc, "account_email", ""))
|
||||
if self.endpoint.startswith("/v1/images"):
|
||||
return _image_error_response(exc)
|
||||
return _protocol_error_response(exc, 502, sse)
|
||||
|
||||
if isinstance(result, dict):
|
||||
self.log("调用完成", result)
|
||||
response = dict(result)
|
||||
response.pop("_account_email", None)
|
||||
return response
|
||||
|
||||
sender = anthropic_sse_stream if sse == "anthropic" else sse_json_stream
|
||||
try:
|
||||
has_first, first = await run_in_threadpool(_next_item, result)
|
||||
except ImageGenerationError as exc:
|
||||
self.log("调用失败", status="failed", error=str(exc), account_email=getattr(exc, "account_email", ""),
|
||||
conversation_id=getattr(exc, "conversation_id", ""))
|
||||
return _image_error_response(exc)
|
||||
except HTTPException as exc:
|
||||
self.log("调用失败", status="failed", error=str(exc.detail))
|
||||
raise
|
||||
except Exception as exc:
|
||||
self.log("调用失败", status="failed", error=str(exc), account_email=getattr(exc, "account_email", ""))
|
||||
if self.endpoint.startswith("/v1/images"):
|
||||
return _image_error_response(exc)
|
||||
return _protocol_error_response(exc, 502, sse)
|
||||
if not has_first:
|
||||
self.log("流式调用结束")
|
||||
return StreamingResponse(sender(()), media_type="text/event-stream")
|
||||
return StreamingResponse(sender(self.stream(itertools.chain([first], result))), media_type="text/event-stream")
|
||||
|
||||
def stream(self, items):
|
||||
urls: list[str] = []
|
||||
account_emails: list[str] = []
|
||||
conversation_ids: list[str] = []
|
||||
failed = False
|
||||
try:
|
||||
for item in items:
|
||||
urls.extend(_collect_urls(item))
|
||||
account_emails.extend(_collect_account_emails(item))
|
||||
conversation_ids.extend(_collect_conversation_ids(item))
|
||||
yield _strip_internal_response_fields(item)
|
||||
except Exception as exc:
|
||||
failed = True
|
||||
self.log(
|
||||
"流式调用失败",
|
||||
status="failed",
|
||||
error=str(exc),
|
||||
urls=urls,
|
||||
account_email=(account_emails[0] if account_emails else getattr(exc, "account_email", "")),
|
||||
conversation_id=(conversation_ids[0] if conversation_ids else getattr(exc, "conversation_id", "")),
|
||||
)
|
||||
if self.endpoint.startswith("/v1/images") and not hasattr(exc, "to_openai_error"):
|
||||
from services.protocol.conversation import ImageGenerationError, public_image_error_message
|
||||
|
||||
raise ImageGenerationError(public_image_error_message(str(exc))) from exc
|
||||
raise
|
||||
finally:
|
||||
if not failed:
|
||||
self.log("流式调用结束", urls=urls, account_email=account_emails[0] if account_emails else "",
|
||||
conversation_id=conversation_ids[0] if conversation_ids else "")
|
||||
|
||||
def log(self, suffix: str, result: object = None, status: str = "success", error: str = "",
|
||||
urls: list[str] | None = None, account_email: str = "", conversation_id: str = "") -> None:
|
||||
detail = {
|
||||
"key_id": self.identity.get("id"),
|
||||
"key_name": self.identity.get("name"),
|
||||
"role": self.identity.get("role"),
|
||||
"endpoint": self.endpoint,
|
||||
"model": self.model,
|
||||
"started_at": datetime.fromtimestamp(self.started).strftime("%Y-%m-%d %H:%M:%S"),
|
||||
"ended_at": datetime.now().strftime("%Y-%m-%d %H:%M:%S"),
|
||||
"duration_ms": int((time.time() - self.started) * 1000),
|
||||
"status": status,
|
||||
}
|
||||
request_excerpt = _request_excerpt(self.request_text)
|
||||
if request_excerpt:
|
||||
detail["request_text"] = request_excerpt
|
||||
if self.request_shape:
|
||||
detail["request_shape"] = self.request_shape
|
||||
if error:
|
||||
detail["error"] = error
|
||||
email = str(account_email or "").strip()
|
||||
if not email:
|
||||
emails = _collect_account_emails(result)
|
||||
email = emails[0] if emails else ""
|
||||
if email:
|
||||
detail["account_email"] = email
|
||||
conv_id = str(conversation_id or "").strip()
|
||||
if not conv_id:
|
||||
conv_ids = _collect_conversation_ids(result)
|
||||
conv_id = conv_ids[0] if conv_ids else ""
|
||||
if conv_id:
|
||||
detail["conversation_id"] = conv_id
|
||||
collected_urls = [*(urls or []), *_collect_urls(result)]
|
||||
if collected_urls and not self.endpoint.startswith("/v1/search"):
|
||||
detail["urls"] = list(dict.fromkeys(collected_urls))
|
||||
log_service.add(LOG_TYPE_CALL, f"{self.summary}{suffix}", detail)
|
||||
@@ -0,0 +1,182 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import time
|
||||
from collections.abc import Callable
|
||||
from concurrent.futures import ThreadPoolExecutor
|
||||
from dataclasses import dataclass
|
||||
from threading import RLock
|
||||
from typing import Any
|
||||
|
||||
from services.account_service import AccountService, account_service
|
||||
from services.openai_backend_api import OpenAIBackendAPI
|
||||
from utils.log import logger
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ModelRoute:
|
||||
account_types: frozenset[str]
|
||||
allow_anonymous: bool = False
|
||||
|
||||
|
||||
class ModelUnavailableError(RuntimeError):
|
||||
pass
|
||||
|
||||
|
||||
class ModelCatalogService:
|
||||
"""Caches the model catalogs advertised to each active account type."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
accounts: AccountService,
|
||||
*,
|
||||
backend_factory: Callable[..., Any] = OpenAIBackendAPI,
|
||||
cache_ttl_seconds: float = 300,
|
||||
clock: Callable[[], float] = time.monotonic,
|
||||
) -> None:
|
||||
self._accounts = accounts
|
||||
self._backend_factory = backend_factory
|
||||
self._cache_ttl_seconds = max(1.0, float(cache_ttl_seconds))
|
||||
self._clock = clock
|
||||
self._lock = RLock()
|
||||
self._expires_at = 0.0
|
||||
self._account_signature: tuple[tuple[str, int], ...] = ()
|
||||
self._anonymous_models: dict[str, dict[str, Any]] = {}
|
||||
self._models_by_account_type: dict[str, dict[str, dict[str, Any]]] = {}
|
||||
|
||||
@staticmethod
|
||||
def _model_map(result: object) -> dict[str, dict[str, Any]]:
|
||||
if not isinstance(result, dict) or not isinstance(result.get("data"), list):
|
||||
raise TypeError("upstream model response has no data list")
|
||||
models: dict[str, dict[str, Any]] = {}
|
||||
for item in result["data"]:
|
||||
if not isinstance(item, dict):
|
||||
continue
|
||||
model_id = str(item.get("id") or "").strip()
|
||||
if model_id and model_id not in models:
|
||||
models[model_id] = dict(item)
|
||||
return models
|
||||
|
||||
def _active_accounts_by_type(self) -> dict[str, list[str]]:
|
||||
groups: dict[str, list[str]] = {}
|
||||
for account in self._accounts.list_accounts():
|
||||
if not isinstance(account, dict) or account.get("status") in {"禁用", "异常"}:
|
||||
continue
|
||||
access_token = str(account.get("access_token") or "").strip()
|
||||
account_type = self._accounts._normalize_account_type(account.get("type"))
|
||||
if access_token and account_type:
|
||||
groups.setdefault(account_type, []).append(access_token)
|
||||
return groups
|
||||
|
||||
@staticmethod
|
||||
def _signature(groups: dict[str, list[str]]) -> tuple[tuple[str, int], ...]:
|
||||
return tuple(
|
||||
(account_type, len(tokens))
|
||||
for account_type, tokens in sorted(groups.items())
|
||||
)
|
||||
|
||||
def _fetch_models(self, access_token: str = "") -> dict[str, dict[str, Any]]:
|
||||
backend = self._backend_factory(access_token=access_token)
|
||||
try:
|
||||
return self._model_map(backend.list_models())
|
||||
finally:
|
||||
backend.close()
|
||||
|
||||
def _fetch_account_type_models(
|
||||
self,
|
||||
account_type: str,
|
||||
access_tokens: list[str],
|
||||
) -> dict[str, dict[str, Any]] | None:
|
||||
attempted_tokens: set[str] = set()
|
||||
last_error: Exception | None = None
|
||||
for access_token in access_tokens:
|
||||
try:
|
||||
resolved_token = self._accounts.refresh_access_token(
|
||||
access_token,
|
||||
event="list_models",
|
||||
) or access_token
|
||||
if resolved_token in attempted_tokens:
|
||||
continue
|
||||
attempted_tokens.add(resolved_token)
|
||||
return self._fetch_models(resolved_token)
|
||||
except Exception as exc: # noqa: BLE001 - try the next account for any upstream failure
|
||||
last_error = exc
|
||||
if last_error is not None:
|
||||
logger.warning({
|
||||
"event": "model_catalog_account_type_failed",
|
||||
"account_type": account_type,
|
||||
"error_type": type(last_error).__name__,
|
||||
})
|
||||
return None
|
||||
|
||||
def _refresh(self, groups: dict[str, list[str]], signature: tuple[tuple[str, int], ...]) -> None:
|
||||
models_by_account_type: dict[str, dict[str, dict[str, Any]]] = {}
|
||||
with ThreadPoolExecutor(max_workers=min(4, len(groups) + 1)) as executor:
|
||||
anonymous_future = executor.submit(self._fetch_models)
|
||||
account_futures = {
|
||||
account_type: executor.submit(
|
||||
self._fetch_account_type_models,
|
||||
account_type,
|
||||
access_tokens,
|
||||
)
|
||||
for account_type, access_tokens in groups.items()
|
||||
}
|
||||
try:
|
||||
anonymous_models = anonymous_future.result()
|
||||
except Exception as exc: # noqa: BLE001 - retain cached models on upstream failure
|
||||
logger.warning({
|
||||
"event": "model_catalog_anonymous_failed",
|
||||
"error_type": type(exc).__name__,
|
||||
})
|
||||
anonymous_models = self._anonymous_models
|
||||
|
||||
for account_type, future in account_futures.items():
|
||||
models = future.result()
|
||||
if models is not None:
|
||||
models_by_account_type[account_type] = models
|
||||
elif account_type in self._models_by_account_type:
|
||||
models_by_account_type[account_type] = self._models_by_account_type[account_type]
|
||||
|
||||
self._anonymous_models = anonymous_models
|
||||
self._models_by_account_type = models_by_account_type
|
||||
self._account_signature = signature
|
||||
self._expires_at = self._clock() + self._cache_ttl_seconds
|
||||
|
||||
def _ensure_catalog(self) -> None:
|
||||
groups = self._active_accounts_by_type()
|
||||
signature = self._signature(groups)
|
||||
with self._lock:
|
||||
if signature == self._account_signature and self._clock() < self._expires_at:
|
||||
return
|
||||
self._refresh(groups, signature)
|
||||
|
||||
def list_models(self) -> dict[str, Any]:
|
||||
self._ensure_catalog()
|
||||
with self._lock:
|
||||
union: dict[str, dict[str, Any]] = {
|
||||
model_id: dict(item)
|
||||
for model_id, item in self._anonymous_models.items()
|
||||
}
|
||||
for account_type in sorted(self._models_by_account_type):
|
||||
for model_id, item in self._models_by_account_type[account_type].items():
|
||||
union.setdefault(model_id, dict(item))
|
||||
return {
|
||||
"object": "list",
|
||||
"data": [union[model_id] for model_id in sorted(union)],
|
||||
}
|
||||
|
||||
def route_for_model(self, model: str) -> ModelRoute:
|
||||
model = str(model or "").strip()
|
||||
self._ensure_catalog()
|
||||
with self._lock:
|
||||
account_types = frozenset(
|
||||
account_type
|
||||
for account_type, models in self._models_by_account_type.items()
|
||||
if model in models
|
||||
)
|
||||
return ModelRoute(
|
||||
account_types=account_types,
|
||||
allow_anonymous=model in self._anonymous_models,
|
||||
)
|
||||
|
||||
|
||||
model_catalog_service = ModelCatalogService(account_service)
|
||||
@@ -0,0 +1,267 @@
|
||||
"""手动 OAuth 桥服务
|
||||
|
||||
让用户用自己浏览器走一遍 OpenAI 的标准 OAuth + PKCE 授权码流程:
|
||||
1. 后端生成 code_verifier / code_challenge / state,构造 authorize URL。
|
||||
2. 用户在浏览器登录,浏览器最终被 OpenAI 重定向到 platform.openai.com 的
|
||||
callback 地址;用户从地址栏或 devtools 抓出 code,回填到前端。
|
||||
3. 后端拿之前存好的 code_verifier + 回填的 code 调用 /api/accounts/oauth/token
|
||||
得到 {access_token, refresh_token, id_token}。
|
||||
|
||||
得到的 refresh_token 跟 account_service 自动刷新机制用的 client_id 是同一个
|
||||
(app_2SKx67EdpoN0G6j64rFvigXD),所以落盘后能直接进入 keepalive 周期。
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import secrets
|
||||
import threading
|
||||
import time
|
||||
import uuid
|
||||
from typing import Any
|
||||
from urllib.parse import parse_qs, urlencode, urlparse
|
||||
|
||||
from curl_cffi import requests
|
||||
|
||||
from services.openai_oauth import (
|
||||
auth_base,
|
||||
common_headers,
|
||||
platform_auth0_client,
|
||||
platform_base,
|
||||
platform_oauth_audience,
|
||||
platform_oauth_client_id,
|
||||
platform_oauth_redirect_uri,
|
||||
sec_ch_ua,
|
||||
user_agent,
|
||||
)
|
||||
from services.proxy_service import proxy_settings
|
||||
|
||||
|
||||
class OAuthLoginError(Exception):
|
||||
"""OAuth 桥流程中的可预期错误,会被 API 层翻译成 400。"""
|
||||
|
||||
|
||||
class OAuthLoginService:
|
||||
"""维护 PKCE 临时会话,并完成 code → token 的兑换。"""
|
||||
|
||||
_SESSION_TTL_SECONDS = 10 * 60 # 用户点开浏览器 + 拿 code 给的时间上限
|
||||
_MAX_SESSIONS = 64 # 防止异常累积;超过容量时清理最老的
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._lock = threading.Lock()
|
||||
self._sessions: dict[str, dict[str, Any]] = {}
|
||||
|
||||
@staticmethod
|
||||
def _generate_pkce() -> tuple[str, str]:
|
||||
"""生成 PKCE code_verifier 与对应的 code_challenge(S256)。"""
|
||||
from utils.pkce import generate_pkce
|
||||
return generate_pkce()
|
||||
|
||||
def _purge_expired_locked(self) -> None:
|
||||
"""清理过期或溢出容量的会话,必须在持锁状态下调用。"""
|
||||
now = time.time()
|
||||
expired = [sid for sid, item in self._sessions.items() if now - item["created_at"] > self._SESSION_TTL_SECONDS]
|
||||
for sid in expired:
|
||||
self._sessions.pop(sid, None)
|
||||
if len(self._sessions) > self._MAX_SESSIONS:
|
||||
ordered = sorted(self._sessions.items(), key=lambda kv: kv[1]["created_at"])
|
||||
for sid, _ in ordered[: len(self._sessions) - self._MAX_SESSIONS]:
|
||||
self._sessions.pop(sid, None)
|
||||
|
||||
def start(self, email_hint: str = "") -> dict[str, str]:
|
||||
"""登记一个新的 PKCE 会话,返回 session_id 与可让用户打开的 authorize_url。
|
||||
|
||||
state 形如 "<session_id>.<nonce>",让 callback URL 自带 session_id,
|
||||
finish 时即便前端 React 状态被覆盖也能从 URL 恢复正确的 verifier。
|
||||
"""
|
||||
verifier, challenge = self._generate_pkce()
|
||||
nonce = secrets.token_urlsafe(32)
|
||||
device_id = str(uuid.uuid4())
|
||||
session_id = uuid.uuid4().hex
|
||||
state = f"{session_id}.{secrets.token_urlsafe(16)}"
|
||||
|
||||
params = {
|
||||
"issuer": auth_base,
|
||||
"client_id": platform_oauth_client_id,
|
||||
"audience": platform_oauth_audience,
|
||||
"redirect_uri": platform_oauth_redirect_uri,
|
||||
"device_id": device_id,
|
||||
"screen_hint": "login_or_signup",
|
||||
"max_age": "0",
|
||||
"scope": "openid profile email offline_access",
|
||||
"response_type": "code",
|
||||
"response_mode": "query",
|
||||
"state": state,
|
||||
"nonce": nonce,
|
||||
"code_challenge": challenge,
|
||||
"code_challenge_method": "S256",
|
||||
"auth0Client": platform_auth0_client,
|
||||
}
|
||||
email_hint = str(email_hint or "").strip()
|
||||
if email_hint:
|
||||
params["login_hint"] = email_hint
|
||||
|
||||
authorize_url = f"{auth_base}/api/accounts/authorize?{urlencode(params)}"
|
||||
|
||||
with self._lock:
|
||||
self._purge_expired_locked()
|
||||
self._sessions[session_id] = {
|
||||
"code_verifier": verifier,
|
||||
"state": state,
|
||||
"created_at": time.time(),
|
||||
"redirect_uri": platform_oauth_redirect_uri,
|
||||
}
|
||||
|
||||
return {
|
||||
"session_id": session_id,
|
||||
"authorize_url": authorize_url,
|
||||
"expires_in": str(self._SESSION_TTL_SECONDS),
|
||||
"redirect_uri_prefix": platform_oauth_redirect_uri,
|
||||
}
|
||||
|
||||
@staticmethod
|
||||
def _extract_code_from_callback(value: str) -> tuple[str, str]:
|
||||
"""从 callback URL 或 raw code 中提取 (code, state)。
|
||||
|
||||
既允许用户粘贴整段 platform.openai.com/auth/callback?code=...&state=... 的 URL,
|
||||
也允许只粘 code 本身。
|
||||
"""
|
||||
raw = str(value or "").strip()
|
||||
if not raw:
|
||||
return "", ""
|
||||
if raw.startswith("http://") or raw.startswith("https://"):
|
||||
try:
|
||||
parsed = parse_qs(urlparse(raw).query)
|
||||
except Exception as exc:
|
||||
raise OAuthLoginError(f"无法解析 callback URL: {exc}") from exc
|
||||
code = str((parsed.get("code") or [""])[0]).strip()
|
||||
state = str((parsed.get("state") or [""])[0]).strip()
|
||||
if not code:
|
||||
err = str((parsed.get("error_description") or parsed.get("error") or [""])[0]).strip()
|
||||
raise OAuthLoginError(err or "callback URL 中没有 code 参数")
|
||||
return code, state
|
||||
# 用户可能直接粘了 code 字符串
|
||||
return raw, ""
|
||||
|
||||
def finish(self, session_id: str, callback: str) -> dict[str, str]:
|
||||
"""用 session_id 配对的 code_verifier 把 callback 里的 code 换成 token 三件套。
|
||||
|
||||
- 优先用 callback URL 自带 state 里的 session_id(更可靠),
|
||||
找不到才用前端传来的 session_id;
|
||||
- 失败时不立刻销毁 session(OAuth code 错配换 token 失败通常不会消耗 code),
|
||||
只有成功兑换才 pop,便于用户用同一 verifier 重试。
|
||||
"""
|
||||
body_sid = str(session_id or "").strip()
|
||||
code, state = self._extract_code_from_callback(callback)
|
||||
if not code:
|
||||
raise OAuthLoginError("缺少 code 或 callback URL")
|
||||
|
||||
# state 里嵌的 session_id 优先级最高
|
||||
state_sid = state.split(".", 1)[0] if state else ""
|
||||
candidate_sids = [sid for sid in (state_sid, body_sid) if sid]
|
||||
if not candidate_sids:
|
||||
raise OAuthLoginError("既未提供 session_id,callback URL 中也未携带 state")
|
||||
|
||||
with self._lock:
|
||||
self._purge_expired_locked()
|
||||
session = None
|
||||
picked_sid = ""
|
||||
for sid in candidate_sids:
|
||||
cur = self._sessions.get(sid)
|
||||
if cur is not None:
|
||||
session = cur
|
||||
picked_sid = sid
|
||||
break
|
||||
if session is None:
|
||||
raise OAuthLoginError(
|
||||
"OAuth 会话已过期或不存在,请回到导入对话框点\"重新生成\"再走一次"
|
||||
)
|
||||
|
||||
if state and session.get("state") and state != session["state"]:
|
||||
raise OAuthLoginError(
|
||||
"state 不匹配。常见原因:你点过两次\"打开授权页面\",但浏览器里登录的还是前一次的窗口。请点\"重新生成\"重来。"
|
||||
)
|
||||
|
||||
tokens = self._exchange_code(
|
||||
code,
|
||||
session["code_verifier"],
|
||||
session.get("redirect_uri") or platform_oauth_redirect_uri,
|
||||
)
|
||||
# 仅在成功兑换之后才消耗 session
|
||||
with self._lock:
|
||||
self._sessions.pop(picked_sid, None)
|
||||
return tokens
|
||||
|
||||
@staticmethod
|
||||
def _exchange_code(code: str, code_verifier: str, redirect_uri: str) -> dict[str, str]:
|
||||
"""调用 /api/accounts/oauth/token 用 code+verifier 换 token 三件套。"""
|
||||
kwargs = proxy_settings.build_session_kwargs(impersonate="chrome", verify=False)
|
||||
session = requests.Session(**kwargs)
|
||||
try:
|
||||
response = session.post(
|
||||
f"{auth_base}/api/accounts/oauth/token",
|
||||
headers={
|
||||
**common_headers,
|
||||
"referer": f"{platform_base}/",
|
||||
"origin": platform_base,
|
||||
"auth0-client": platform_auth0_client,
|
||||
"sec-ch-ua": sec_ch_ua,
|
||||
"user-agent": user_agent,
|
||||
},
|
||||
json={
|
||||
"client_id": platform_oauth_client_id,
|
||||
"code_verifier": code_verifier,
|
||||
"grant_type": "authorization_code",
|
||||
"code": code,
|
||||
"redirect_uri": redirect_uri,
|
||||
},
|
||||
timeout=60,
|
||||
)
|
||||
except Exception as exc:
|
||||
raise OAuthLoginError(f"换 token 网络异常: {exc}") from exc
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
try:
|
||||
data = response.json() if response.text else {}
|
||||
except Exception:
|
||||
data = {}
|
||||
|
||||
if response.status_code != 200 or not isinstance(data, dict) or not data.get("access_token"):
|
||||
detail = ""
|
||||
if isinstance(data, dict):
|
||||
detail = str(data.get("error_description") or data.get("error") or data.get("message") or "")
|
||||
if not detail:
|
||||
try:
|
||||
detail = str(response.text or "")[:300]
|
||||
except Exception:
|
||||
detail = ""
|
||||
# 打到 docker logs 方便排错——OAuth 换 token 的失败原因往往只有这里能看到
|
||||
print(
|
||||
f"[oauth-login] /api/accounts/oauth/token rejected: "
|
||||
f"status={response.status_code} detail={detail!r} "
|
||||
f"raw_body={(getattr(response, 'text', '') or '')[:500]!r}",
|
||||
flush=True,
|
||||
)
|
||||
raise OAuthLoginError(
|
||||
f"OpenAI 拒绝换 token (HTTP {response.status_code}){': ' + detail if detail else ''}"
|
||||
)
|
||||
|
||||
access_token = str(data.get("access_token") or "").strip()
|
||||
refresh_token = str(data.get("refresh_token") or "").strip()
|
||||
id_token = str(data.get("id_token") or "").strip()
|
||||
|
||||
if not access_token:
|
||||
raise OAuthLoginError("OpenAI 返回的 access_token 为空")
|
||||
if not refresh_token:
|
||||
# scope 含 offline_access 时正常会下发 refresh_token;这里给出明确提示
|
||||
raise OAuthLoginError(
|
||||
"OpenAI 没有返回 refresh_token(可能 scope 未包含 offline_access 或 code 已使用过)"
|
||||
)
|
||||
|
||||
return {
|
||||
"access_token": access_token,
|
||||
"refresh_token": refresh_token,
|
||||
"id_token": id_token,
|
||||
}
|
||||
|
||||
|
||||
oauth_login_service = OAuthLoginService()
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,32 @@
|
||||
auth_base = "https://auth.openai.com"
|
||||
platform_base = "https://platform.openai.com"
|
||||
platform_oauth_client_id = "app_2SKx67EdpoN0G6j64rFvigXD"
|
||||
platform_oauth_redirect_uri = f"{platform_base}/auth/callback"
|
||||
platform_oauth_audience = "https://api.openai.com/v1"
|
||||
platform_auth0_client = "eyJuYW1lIjoiYXV0aDAtc3BhLWpzIiwidmVyc2lvbiI6IjEuMjEuMCJ9"
|
||||
user_agent = (
|
||||
"Mozilla/5.0 (Windows NT 10.0; Win64; x64) "
|
||||
"AppleWebKit/537.36 (KHTML, like Gecko) "
|
||||
"Chrome/145.0.0.0 Safari/537.36"
|
||||
)
|
||||
sec_ch_ua = '"Google Chrome";v="145", "Not?A_Brand";v="8", "Chromium";v="145"'
|
||||
|
||||
common_headers = {
|
||||
"accept": "application/json",
|
||||
"accept-encoding": "gzip, deflate, br",
|
||||
"accept-language": "en-US,en;q=0.9",
|
||||
"cache-control": "no-cache",
|
||||
"connection": "keep-alive",
|
||||
"content-type": "application/json",
|
||||
"dnt": "1",
|
||||
"origin": auth_base,
|
||||
"priority": "u=1, i",
|
||||
"sec-gpc": "1",
|
||||
"sec-ch-ua": sec_ch_ua,
|
||||
"sec-ch-ua-mobile": "?0",
|
||||
"sec-ch-ua-platform": '"Windows"',
|
||||
"sec-fetch-dest": "empty",
|
||||
"sec-fetch-mode": "cors",
|
||||
"sec-fetch-site": "same-origin",
|
||||
"user-agent": user_agent,
|
||||
}
|
||||
@@ -0,0 +1,2 @@
|
||||
"""Protocol converters for OpenAI-compatible endpoints."""
|
||||
|
||||
@@ -0,0 +1,307 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import html
|
||||
import json
|
||||
import re
|
||||
import time
|
||||
import uuid
|
||||
from collections.abc import Callable, Iterable, Iterator
|
||||
from dataclasses import dataclass
|
||||
from typing import Any
|
||||
|
||||
from services.account_service import account_service
|
||||
from services.openai_backend_api import OpenAIBackendAPI
|
||||
from services.protocol.conversation import count_message_tokens, count_text_tokens, normalize_messages
|
||||
from services.protocol.openai_v1_chat_complete import collect_chat_content, stream_text_chat_completion
|
||||
|
||||
XML_TOOL_RULE = """Tool output adapter: when calling tools, output ONLY this XML and no prose/markdown:
|
||||
<tool_calls><tool_call><tool_name>TOOL_NAME</tool_name><parameters><PARAM><![CDATA[value]]></PARAM></parameters></tool_call></tool_calls>"""
|
||||
|
||||
|
||||
@dataclass
|
||||
class MessageRequest:
|
||||
backend: OpenAIBackendAPI
|
||||
messages: list[dict[str, Any]]
|
||||
model: str
|
||||
tools: Any = None
|
||||
|
||||
|
||||
def _tool_meta(tool: dict[str, object]) -> tuple[str, str, object]:
|
||||
fn = tool.get("function") if isinstance(tool.get("function"), dict) else {}
|
||||
name = str(tool.get("name") or fn.get("name") or "").strip()
|
||||
desc = str(tool.get("description") or fn.get("description") or "").strip()
|
||||
schema = tool.get("input_schema") or tool.get("parameters") or fn.get("input_schema") or fn.get("parameters") or {}
|
||||
return name, desc, schema
|
||||
|
||||
|
||||
def build_tool_prompt(tools: object) -> str:
|
||||
if not isinstance(tools, list):
|
||||
return ""
|
||||
blocks = []
|
||||
for tool in tools:
|
||||
if not isinstance(tool, dict):
|
||||
continue
|
||||
name, desc, schema = _tool_meta(tool)
|
||||
if name:
|
||||
blocks.append(f"Tool: {name}\nDescription: {desc}\nParameters: {json.dumps(schema, ensure_ascii=False)}")
|
||||
if not blocks:
|
||||
return ""
|
||||
return "Available tools:\n" + "\n".join(blocks) + """
|
||||
|
||||
Tool use rules:
|
||||
- If the user asks to list/read/search files, inspect project state, run a command, or answer from local code, you MUST call a suitable tool first. Do not say you cannot access files.
|
||||
- To call tools, output ONLY XML and no prose/markdown:
|
||||
<tool_calls><tool_call><tool_name>TOOL_NAME</tool_name><parameters><PARAM><![CDATA[value]]></PARAM></parameters></tool_call></tool_calls>
|
||||
- Put parameters under <parameters> using the exact schema names.
|
||||
""".strip()
|
||||
|
||||
|
||||
def merge_system(system: object, extra: str) -> object:
|
||||
system = compact_system(system)
|
||||
if _has_claude_code_system(system):
|
||||
extra = XML_TOOL_RULE
|
||||
if not extra:
|
||||
return system
|
||||
if isinstance(system, str) and system.strip():
|
||||
return f"{system.strip()}\n\n{extra}"
|
||||
if isinstance(system, list):
|
||||
return [*system, {"type": "text", "text": extra}]
|
||||
return extra
|
||||
|
||||
|
||||
def _has_claude_code_system(system: object) -> bool:
|
||||
if isinstance(system, str):
|
||||
return "You are Claude Code" in system
|
||||
if isinstance(system, list):
|
||||
return any(isinstance(item, dict) and "You are Claude Code" in str(item.get("text") or "") for item in system)
|
||||
return False
|
||||
|
||||
|
||||
def compact_system(system: object) -> object:
|
||||
if isinstance(system, str):
|
||||
return _compact_system_text(system)
|
||||
if isinstance(system, list):
|
||||
result = []
|
||||
for item in system:
|
||||
if isinstance(item, dict) and str(item.get("type") or "") == "text":
|
||||
copied = dict(item)
|
||||
copied["text"] = _compact_system_text(str(item.get("text") or ""))
|
||||
result.append(copied)
|
||||
else:
|
||||
result.append(item)
|
||||
return result
|
||||
return system
|
||||
|
||||
|
||||
def _compact_system_text(text: str) -> str:
|
||||
return text or ""
|
||||
|
||||
|
||||
def _compact_message_text(text: str) -> str:
|
||||
return text or ""
|
||||
|
||||
|
||||
def preprocess_payload(payload: dict[str, object], text_mapper: Callable[[str], str] | None = None) -> dict[str, object]:
|
||||
payload["messages"] = preprocess_messages(payload.get("messages"), text_mapper)
|
||||
payload["system"] = merge_system(payload.get("system"), build_tool_prompt(payload.get("tools")))
|
||||
return payload
|
||||
|
||||
|
||||
def message_request(body: dict[str, Any]) -> MessageRequest:
|
||||
payload = preprocess_payload(dict(body))
|
||||
model = str(payload.get("model") or "auto").strip() or "auto"
|
||||
return MessageRequest(
|
||||
backend=OpenAIBackendAPI(access_token=account_service.get_text_access_token(model=model)),
|
||||
messages=normalize_messages(payload.get("messages"), payload.get("system")),
|
||||
model=model,
|
||||
tools=payload.get("tools"),
|
||||
)
|
||||
|
||||
|
||||
def preprocess_messages(messages: object, text_mapper: Callable[[str], str] | None = None) -> object:
|
||||
if not isinstance(messages, list):
|
||||
return messages
|
||||
mapper = text_mapper or (lambda text: text)
|
||||
result = []
|
||||
for message in messages:
|
||||
if not isinstance(message, dict):
|
||||
continue
|
||||
item = dict(message)
|
||||
content = item.get("content")
|
||||
if isinstance(content, str):
|
||||
item["content"] = _compact_message_text(mapper(content))
|
||||
elif isinstance(content, list):
|
||||
item["content"] = [_preprocess_block(block, mapper) for block in content]
|
||||
result.append(item)
|
||||
return result
|
||||
|
||||
|
||||
def _preprocess_block(block: object, text_mapper: Callable[[str], str]) -> object:
|
||||
if not isinstance(block, dict):
|
||||
return block
|
||||
block_type = str(block.get("type") or "")
|
||||
if block_type == "text":
|
||||
item = dict(block)
|
||||
item["text"] = _compact_message_text(text_mapper(str(block.get("text") or "")))
|
||||
return item
|
||||
if block_type == "tool_use":
|
||||
return {"type": "text", "text": f"<tool_calls><tool_call><tool_name>{block.get('name') or ''}</tool_name><parameters>{json.dumps(block.get('input') or {}, ensure_ascii=False)}</parameters></tool_call></tool_calls>"}
|
||||
if block_type == "tool_result":
|
||||
return {"type": "text", "text": f"Tool result {block.get('tool_use_id') or ''}: {block.get('content') or ''}"}
|
||||
return block
|
||||
|
||||
|
||||
def message_response(model: str, text: str, input_tokens: int, output_tokens: int, tools: object = None) -> dict[str, object]:
|
||||
content, stop_reason = content_blocks(text, tools)
|
||||
return {
|
||||
"id": f"msg_{uuid.uuid4()}",
|
||||
"type": "message",
|
||||
"role": "assistant",
|
||||
"model": model,
|
||||
"content": content,
|
||||
"stop_reason": stop_reason,
|
||||
"stop_sequence": None,
|
||||
"usage": {"input_tokens": input_tokens, "output_tokens": output_tokens},
|
||||
}
|
||||
|
||||
|
||||
def content_blocks(text: str, tools: object = None) -> tuple[list[dict[str, object]], str]:
|
||||
calls = parse_tool_calls(text) if isinstance(tools, list) and tools else []
|
||||
text = strip_tool_markup(text)
|
||||
if calls:
|
||||
content = ([{"type": "text", "text": text}] if text else []) + [{"type": "tool_use", "id": f"toolu_{uuid.uuid4()}", "name": name, "input": args} for name, args in calls]
|
||||
return content, "tool_use"
|
||||
return [{"type": "text", "text": text}], "end_turn"
|
||||
|
||||
|
||||
def strip_tool_markup(text: str) -> str:
|
||||
return re.sub(r"(?is)<tool_calls\b[^>]*>.*?</tool_calls>|<tool_call\b[^>]*>.*?</tool_call>|<function_call\b[^>]*>.*?</function_call>|<invoke\b[^>]*>.*?</invoke>", "", text or "").strip()
|
||||
|
||||
|
||||
def streamable_text(text: str) -> str:
|
||||
text = text or ""
|
||||
match = re.search(r"(?is)<tool_calls\b|<tool_call\b|<function_call\b|<invoke\b", text)
|
||||
return text[:match.start()].rstrip() if match else text
|
||||
|
||||
|
||||
def parse_tool_calls(text: str) -> list[tuple[str, dict[str, object]]]:
|
||||
text = re.sub(r"(?is)```.*?```", "", text or "").strip()
|
||||
blocks = re.findall(r"(?is)<tool_call\b[^>]*>(.*?)</tool_call>|<function_call\b[^>]*>(.*?)</function_call>|<invoke\b[^>]*>(.*?)</invoke>", text)
|
||||
result = []
|
||||
for block in (next((part for part in match if part), "") for match in blocks):
|
||||
name = xml_value(block, "tool_name") or xml_value(block, "name") or xml_value(block, "function")
|
||||
params = xml_value(block, "parameters") or xml_value(block, "input") or xml_value(block, "arguments") or "{}"
|
||||
if name:
|
||||
result.append((name, parse_tool_params(params)))
|
||||
return result
|
||||
|
||||
|
||||
def xml_value(text: str, tag: str) -> str:
|
||||
match = re.search(rf"(?is)<{tag}\b[^>]*>(.*?)</{tag}>", text)
|
||||
if not match:
|
||||
return ""
|
||||
value = match.group(1).strip()
|
||||
cdata = re.fullmatch(r"(?is)<!\[CDATA\[(.*?)]]>", value)
|
||||
return html.unescape(cdata.group(1) if cdata else value).strip()
|
||||
|
||||
|
||||
def parse_tool_params(raw: str) -> dict[str, object]:
|
||||
raw = raw.strip()
|
||||
try:
|
||||
parsed = json.loads(raw)
|
||||
return parsed if isinstance(parsed, dict) else {}
|
||||
except Exception:
|
||||
return {m.group(1): parse_tool_value(m.group(2)) for m in re.finditer(r"(?is)<([\w.-]+)\b[^>]*>(.*?)</\1>", raw)}
|
||||
|
||||
|
||||
def parse_tool_value(raw: str) -> object:
|
||||
value = xml_value(f"<x>{raw}</x>", "x")
|
||||
try:
|
||||
return json.loads(value)
|
||||
except Exception:
|
||||
return value
|
||||
|
||||
|
||||
def stream_events(chunks: Iterable[dict[str, object]], model: str, input_tokens: int, output_tokens: Callable[[str], int], tools: object = None) -> Iterator[dict[str, object]]:
|
||||
message_id = f"msg_{uuid.uuid4()}"
|
||||
created = int(time.time())
|
||||
current_text = ""
|
||||
streamed_text = ""
|
||||
tool_mode = isinstance(tools, list) and bool(tools)
|
||||
tool_started = False
|
||||
text_open = False
|
||||
yield {"type": "message_start", "message": {"id": message_id, "type": "message", "role": "assistant", "model": model, "content": [], "stop_reason": None, "stop_sequence": None, "usage": {"input_tokens": input_tokens, "output_tokens": 0}}}
|
||||
if not tool_mode:
|
||||
text_open = True
|
||||
yield {"type": "content_block_start", "index": 0, "content_block": {"type": "text", "text": ""}}
|
||||
for chunk in chunks:
|
||||
choice = (chunk.get("choices") or [{}])[0]
|
||||
delta = choice.get("delta") or {}
|
||||
text_delta = delta.get("content", "") if isinstance(delta, dict) else ""
|
||||
if text_delta:
|
||||
current_text += text_delta
|
||||
if not tool_started:
|
||||
visible_text = current_text if not tool_mode else streamable_text(current_text)
|
||||
if visible_text.startswith(streamed_text):
|
||||
text_delta = visible_text[len(streamed_text):]
|
||||
if text_delta:
|
||||
if not text_open:
|
||||
text_open = True
|
||||
yield {"type": "content_block_start", "index": 0, "content_block": {"type": "text", "text": ""}}
|
||||
streamed_text = visible_text
|
||||
yield {"type": "content_block_delta", "index": 0, "delta": {"type": "text_delta", "text": text_delta}}
|
||||
tool_started = tool_mode and visible_text != current_text
|
||||
if choice.get("finish_reason"):
|
||||
content, stop_reason = content_blocks(current_text, tools)
|
||||
if text_open:
|
||||
yield {"type": "content_block_stop", "index": 0}
|
||||
if stop_reason == "tool_use":
|
||||
start_index = 1 if text_open else 0
|
||||
if content and content[0]["type"] == "text":
|
||||
remaining = str(content[0].get("text") or "")[len(streamed_text):]
|
||||
if remaining:
|
||||
if not text_open:
|
||||
yield {"type": "content_block_start", "index": 0, "content_block": {"type": "text", "text": ""}}
|
||||
yield {"type": "content_block_delta", "index": 0, "delta": {"type": "text_delta", "text": remaining}}
|
||||
if not text_open:
|
||||
yield {"type": "content_block_stop", "index": 0}
|
||||
start_index = 1
|
||||
content = content[1:]
|
||||
yield from _stream_buffered_blocks(content, start_index)
|
||||
yield {"type": "message_delta", "delta": {"stop_reason": stop_reason, "stop_sequence": None}, "usage": {"output_tokens": output_tokens(current_text)}}
|
||||
break
|
||||
yield {"type": "message_stop", "created": created}
|
||||
|
||||
|
||||
def _stream_buffered_blocks(content: list[dict[str, object]], start_index: int = 0) -> Iterator[dict[str, object]]:
|
||||
for offset, block in enumerate(content):
|
||||
index = start_index + offset
|
||||
if block["type"] == "tool_use":
|
||||
start = {"type": "tool_use", "id": block["id"], "name": block["name"], "input": {}}
|
||||
delta = {"type": "input_json_delta", "partial_json": json.dumps(block.get("input") or {}, ensure_ascii=False)}
|
||||
else:
|
||||
start = {"type": "text", "text": ""}
|
||||
delta = {"type": "text_delta", "text": block.get("text") or ""}
|
||||
yield {"type": "content_block_start", "index": index, "content_block": start}
|
||||
yield {"type": "content_block_delta", "index": index, "delta": delta}
|
||||
yield {"type": "content_block_stop", "index": index}
|
||||
|
||||
|
||||
def handle(body: dict[str, Any]) -> dict[str, Any] | Iterator[dict[str, Any]]:
|
||||
request = message_request(body)
|
||||
if body.get("stream"):
|
||||
return stream_events(
|
||||
stream_text_chat_completion(request.backend, request.messages, request.model),
|
||||
request.model,
|
||||
count_message_tokens(request.messages, request.model),
|
||||
lambda text: count_text_tokens(text, request.model),
|
||||
request.tools,
|
||||
)
|
||||
text = collect_chat_content(stream_text_chat_completion(request.backend, request.messages, request.model))
|
||||
return message_response(
|
||||
request.model,
|
||||
text,
|
||||
count_message_tokens(request.messages, request.model),
|
||||
count_text_tokens(text, request.model),
|
||||
request.tools,
|
||||
)
|
||||
@@ -0,0 +1,238 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import copy
|
||||
import hashlib
|
||||
import json
|
||||
import threading
|
||||
import time
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Callable, Iterable, Iterator
|
||||
|
||||
from services.config import config
|
||||
|
||||
CACHEABLE_TEXT_KEYS = {
|
||||
"frequency_penalty",
|
||||
"max_completion_tokens",
|
||||
"max_tokens",
|
||||
"metadata",
|
||||
"model",
|
||||
"presence_penalty",
|
||||
"reasoning_effort",
|
||||
"response_format",
|
||||
"seed",
|
||||
"stop",
|
||||
"temperature",
|
||||
"thinking_effort",
|
||||
"tool_choice",
|
||||
"tools",
|
||||
"top_p",
|
||||
"user",
|
||||
"reasoning",
|
||||
}
|
||||
|
||||
|
||||
@dataclass
|
||||
class CacheEntry:
|
||||
expires_at: float
|
||||
value: Any
|
||||
|
||||
|
||||
@dataclass
|
||||
class InflightCall:
|
||||
condition: threading.Condition = field(default_factory=lambda: threading.Condition(threading.RLock()))
|
||||
done: bool = False
|
||||
value: Any = None
|
||||
error: BaseException | None = None
|
||||
|
||||
|
||||
def _json_safe(value: Any) -> Any:
|
||||
if isinstance(value, bytes):
|
||||
return {"__bytes_sha256__": hashlib.sha256(value).hexdigest(), "length": len(value)}
|
||||
if isinstance(value, bytearray):
|
||||
data = bytes(value)
|
||||
return {"__bytes_sha256__": hashlib.sha256(data).hexdigest(), "length": len(data)}
|
||||
if isinstance(value, dict):
|
||||
return {str(key): _json_safe(item) for key, item in value.items()}
|
||||
if isinstance(value, (list, tuple)):
|
||||
return [_json_safe(item) for item in value]
|
||||
return value
|
||||
|
||||
|
||||
def canonical_body(body: dict[str, Any], messages: list[dict[str, Any]], *, stream: bool) -> dict[str, Any]:
|
||||
payload = {key: body.get(key) for key in CACHEABLE_TEXT_KEYS if key in body}
|
||||
payload["messages"] = messages
|
||||
payload["stream"] = bool(stream)
|
||||
return payload
|
||||
|
||||
|
||||
def cache_key(body: dict[str, Any], messages: list[dict[str, Any]], *, stream: bool) -> str:
|
||||
encoded = json.dumps(
|
||||
_json_safe(canonical_body(body, messages, stream=stream)),
|
||||
ensure_ascii=False,
|
||||
sort_keys=True,
|
||||
separators=(",", ":"),
|
||||
).encode("utf-8")
|
||||
return hashlib.sha256(encoded).hexdigest()
|
||||
|
||||
|
||||
def _message_signature(message: dict[str, Any]) -> str:
|
||||
return json.dumps(_json_safe(message), ensure_ascii=False, sort_keys=True, separators=(",", ":"))
|
||||
|
||||
|
||||
def normalize_text_messages(messages: list[dict[str, Any]]) -> list[dict[str, Any]]:
|
||||
settings = config.get_chat_completion_cache_settings()
|
||||
if not settings.get("normalize_messages"):
|
||||
return messages
|
||||
|
||||
normalized: list[dict[str, Any]] = []
|
||||
previous_signature = ""
|
||||
for message in messages:
|
||||
if settings.get("drop_assistant_history") and str(message.get("role") or "") == "assistant":
|
||||
continue
|
||||
signature = _message_signature(message)
|
||||
if settings.get("drop_adjacent_duplicates") and signature == previous_signature:
|
||||
continue
|
||||
normalized.append(message)
|
||||
previous_signature = signature
|
||||
return normalized
|
||||
|
||||
|
||||
class ChatCompletionCache:
|
||||
def __init__(self) -> None:
|
||||
self._lock = threading.RLock()
|
||||
self._entries: dict[str, CacheEntry] = {}
|
||||
self._inflight: dict[str, InflightCall] = {}
|
||||
|
||||
def clear(self) -> None:
|
||||
with self._lock:
|
||||
self._entries.clear()
|
||||
self._inflight.clear()
|
||||
|
||||
def _settings(self) -> dict[str, object]:
|
||||
return config.get_chat_completion_cache_settings()
|
||||
|
||||
def _prune_locked(self, now: float, max_entries: int) -> None:
|
||||
expired = [key for key, item in self._entries.items() if item.expires_at <= now]
|
||||
for key in expired:
|
||||
self._entries.pop(key, None)
|
||||
while len(self._entries) > max_entries:
|
||||
oldest_key = min(self._entries, key=lambda key: self._entries[key].expires_at)
|
||||
self._entries.pop(oldest_key, None)
|
||||
|
||||
@staticmethod
|
||||
def _copy(value: Any) -> Any:
|
||||
return copy.deepcopy(value)
|
||||
|
||||
def get_or_compute_response(self, key: str, compute: Callable[[], dict[str, Any]]) -> dict[str, Any]:
|
||||
settings = self._settings()
|
||||
if not settings.get("enabled") or int(settings.get("ttl_seconds") or 0) <= 0:
|
||||
return compute()
|
||||
|
||||
now = time.time()
|
||||
max_entries = int(settings.get("max_entries") or 1)
|
||||
with self._lock:
|
||||
self._prune_locked(now, max_entries)
|
||||
entry = self._entries.get(key)
|
||||
if entry and entry.expires_at > now:
|
||||
return self._copy(entry.value)
|
||||
inflight = self._inflight.get(key) if settings.get("dedupe_inflight") else None
|
||||
if inflight is None:
|
||||
inflight = InflightCall()
|
||||
if settings.get("dedupe_inflight"):
|
||||
self._inflight[key] = inflight
|
||||
owner = True
|
||||
else:
|
||||
owner = False
|
||||
|
||||
if not owner:
|
||||
with inflight.condition:
|
||||
while not inflight.done:
|
||||
inflight.condition.wait()
|
||||
if inflight.error:
|
||||
raise inflight.error
|
||||
return self._copy(inflight.value)
|
||||
|
||||
try:
|
||||
value = compute()
|
||||
except BaseException as exc:
|
||||
with self._lock:
|
||||
self._inflight.pop(key, None)
|
||||
with inflight.condition:
|
||||
inflight.error = exc
|
||||
inflight.done = True
|
||||
inflight.condition.notify_all()
|
||||
raise
|
||||
|
||||
expires_at = time.time() + int(settings.get("ttl_seconds") or 0)
|
||||
with self._lock:
|
||||
self._entries[key] = CacheEntry(expires_at=expires_at, value=self._copy(value))
|
||||
self._prune_locked(time.time(), max_entries)
|
||||
self._inflight.pop(key, None)
|
||||
with inflight.condition:
|
||||
inflight.value = self._copy(value)
|
||||
inflight.done = True
|
||||
inflight.condition.notify_all()
|
||||
return value
|
||||
|
||||
def get_or_compute_stream(self, key: str, compute: Callable[[], Iterable[dict[str, Any]]]) -> Iterator[dict[str, Any]]:
|
||||
settings = self._settings()
|
||||
if (
|
||||
not settings.get("enabled")
|
||||
or not settings.get("stream_cache")
|
||||
or int(settings.get("ttl_seconds") or 0) <= 0
|
||||
):
|
||||
yield from compute()
|
||||
return
|
||||
|
||||
now = time.time()
|
||||
max_entries = int(settings.get("max_entries") or 1)
|
||||
with self._lock:
|
||||
self._prune_locked(now, max_entries)
|
||||
entry = self._entries.get(key)
|
||||
if entry and entry.expires_at > now:
|
||||
yield from self._copy(entry.value)
|
||||
return
|
||||
inflight = self._inflight.get(key) if settings.get("dedupe_inflight") else None
|
||||
if inflight is None:
|
||||
inflight = InflightCall()
|
||||
if settings.get("dedupe_inflight"):
|
||||
self._inflight[key] = inflight
|
||||
owner = True
|
||||
else:
|
||||
owner = False
|
||||
|
||||
if not owner:
|
||||
with inflight.condition:
|
||||
while not inflight.done:
|
||||
inflight.condition.wait()
|
||||
if inflight.error:
|
||||
raise inflight.error
|
||||
yield from self._copy(inflight.value)
|
||||
return
|
||||
|
||||
chunks: list[dict[str, Any]] = []
|
||||
try:
|
||||
for chunk in compute():
|
||||
chunks.append(self._copy(chunk))
|
||||
yield chunk
|
||||
except BaseException as exc:
|
||||
with self._lock:
|
||||
self._inflight.pop(key, None)
|
||||
with inflight.condition:
|
||||
inflight.error = exc
|
||||
inflight.done = True
|
||||
inflight.condition.notify_all()
|
||||
raise
|
||||
|
||||
expires_at = time.time() + int(settings.get("ttl_seconds") or 0)
|
||||
with self._lock:
|
||||
self._entries[key] = CacheEntry(expires_at=expires_at, value=self._copy(chunks))
|
||||
self._prune_locked(time.time(), max_entries)
|
||||
self._inflight.pop(key, None)
|
||||
with inflight.condition:
|
||||
inflight.value = self._copy(chunks)
|
||||
inflight.done = True
|
||||
inflight.condition.notify_all()
|
||||
|
||||
|
||||
chat_completion_cache = ChatCompletionCache()
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,124 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any
|
||||
|
||||
from fastapi.responses import JSONResponse
|
||||
|
||||
|
||||
def _message_from_value(value: object) -> str:
|
||||
if isinstance(value, str):
|
||||
return value
|
||||
if not isinstance(value, dict):
|
||||
return ""
|
||||
message = value.get("message")
|
||||
if isinstance(message, str) and message:
|
||||
return message
|
||||
return _message_from_value(value.get("error"))
|
||||
|
||||
|
||||
def error_message_from_detail(detail: object) -> str:
|
||||
if isinstance(detail, list):
|
||||
messages = []
|
||||
for item in detail:
|
||||
if not isinstance(item, dict):
|
||||
continue
|
||||
location = ".".join(str(part) for part in item.get("loc", []) if part != "body")
|
||||
message = str(item.get("msg") or "").strip()
|
||||
if location and message:
|
||||
messages.append(f"{location}: {message}")
|
||||
elif message:
|
||||
messages.append(message)
|
||||
return "; ".join(messages)
|
||||
if isinstance(detail, dict):
|
||||
message = _message_from_value(detail.get("error")) or _message_from_value(detail)
|
||||
if message:
|
||||
return message
|
||||
return str(detail or "").strip()
|
||||
|
||||
|
||||
def _default_error_type(status_code: int) -> str:
|
||||
if status_code == 401:
|
||||
return "authentication_error"
|
||||
if status_code == 403:
|
||||
return "permission_error"
|
||||
if status_code == 429:
|
||||
return "rate_limit_error"
|
||||
if 400 <= status_code < 500:
|
||||
return "invalid_request_error"
|
||||
return "server_error"
|
||||
|
||||
|
||||
def _default_error_code(status_code: int) -> str:
|
||||
if status_code == 401:
|
||||
return "invalid_api_key"
|
||||
if status_code == 403:
|
||||
return "permission_denied"
|
||||
if status_code == 429:
|
||||
return "rate_limit_exceeded"
|
||||
if 400 <= status_code < 500:
|
||||
return "bad_request"
|
||||
return "upstream_error"
|
||||
|
||||
|
||||
def openai_error_payload(
|
||||
detail: object,
|
||||
status_code: int,
|
||||
*,
|
||||
error_type: str | None = None,
|
||||
code: object | None = None,
|
||||
param: object | None = None,
|
||||
) -> dict[str, Any]:
|
||||
error_detail = detail.get("error") if isinstance(detail, dict) else None
|
||||
if isinstance(error_detail, dict):
|
||||
return {
|
||||
"error": {
|
||||
"message": error_message_from_detail(error_detail) or "request failed",
|
||||
"type": str(error_detail.get("type") or error_type or _default_error_type(status_code)),
|
||||
"param": error_detail.get("param", param),
|
||||
"code": error_detail.get("code", code if code is not None else _default_error_code(status_code)),
|
||||
}
|
||||
}
|
||||
return {
|
||||
"error": {
|
||||
"message": error_message_from_detail(detail) or "request failed",
|
||||
"type": error_type or _default_error_type(status_code),
|
||||
"param": param,
|
||||
"code": code if code is not None else _default_error_code(status_code),
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
def openai_error_response(
|
||||
detail: object,
|
||||
status_code: int,
|
||||
*,
|
||||
headers: dict[str, str] | None = None,
|
||||
error_type: str | None = None,
|
||||
code: object | None = None,
|
||||
param: object | None = None,
|
||||
) -> JSONResponse:
|
||||
return JSONResponse(
|
||||
status_code=status_code,
|
||||
content=openai_error_payload(detail, status_code, error_type=error_type, code=code, param=param),
|
||||
headers=headers,
|
||||
)
|
||||
|
||||
|
||||
def anthropic_error_response(
|
||||
detail: object,
|
||||
status_code: int,
|
||||
*,
|
||||
headers: dict[str, str] | None = None,
|
||||
) -> JSONResponse:
|
||||
error_type = "api_error" if status_code >= 500 else _default_error_type(status_code)
|
||||
return JSONResponse(
|
||||
status_code=status_code,
|
||||
content={
|
||||
"type": "error",
|
||||
"error": {
|
||||
"type": error_type,
|
||||
"message": error_message_from_detail(detail) or "request failed",
|
||||
},
|
||||
},
|
||||
headers=headers,
|
||||
)
|
||||
@@ -0,0 +1,19 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from services.account_service import account_service
|
||||
from services.openai_backend_api import OpenAIBackendAPI, SEARCH_MODEL
|
||||
|
||||
MODEL = SEARCH_MODEL
|
||||
|
||||
|
||||
def handle(body: dict[str, object]) -> dict[str, object]:
|
||||
token = account_service.get_text_access_token()
|
||||
account = account_service.get_account(token) or {}
|
||||
backend = OpenAIBackendAPI(token)
|
||||
try:
|
||||
result = backend.search(str(body["prompt"]))
|
||||
finally:
|
||||
backend.close()
|
||||
account_service.mark_text_used(token)
|
||||
result["_account_email"] = str(account.get("email") or "")
|
||||
return result
|
||||
@@ -0,0 +1,316 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import time
|
||||
import uuid
|
||||
from typing import Any, Iterable, Iterator
|
||||
|
||||
from fastapi import HTTPException
|
||||
|
||||
from services.protocol.chat_completion_cache import cache_key, chat_completion_cache, normalize_text_messages
|
||||
from services.protocol.conversation import (
|
||||
ConversationRequest,
|
||||
ImageOutput,
|
||||
collect_image_outputs,
|
||||
collect_text,
|
||||
count_message_image_tokens,
|
||||
count_message_text_tokens,
|
||||
count_text_tokens,
|
||||
encode_images,
|
||||
normalize_messages,
|
||||
stream_image_outputs_with_pool,
|
||||
stream_text_deltas,
|
||||
text_backend,
|
||||
)
|
||||
from services.protocol.web_search_tool import (
|
||||
WEB_SEARCH_TOOL_TYPES,
|
||||
has_unsupported_tools,
|
||||
is_web_search_chat_request,
|
||||
run_web_search,
|
||||
search_query_from_messages,
|
||||
text_with_url_citations,
|
||||
)
|
||||
from utils.helper import build_chat_image_markdown_content, extract_chat_image, extract_chat_prompt, is_image_chat_request, parse_image_count
|
||||
from utils.image_tokens import (
|
||||
chat_usage_from_image_usage,
|
||||
count_image_inputs_tokens,
|
||||
count_image_output_items_tokens,
|
||||
image_usage,
|
||||
)
|
||||
|
||||
TOOL_UNAVAILABLE_SYSTEM_MESSAGE = (
|
||||
"This compatibility backend cannot execute local tools, shell commands, non-search tools, "
|
||||
"or file operations. Do not claim to have run tools or inspected external resources. "
|
||||
"If a user asks you to use a tool, say that tool execution is unavailable through this backend."
|
||||
)
|
||||
|
||||
|
||||
def normalize_thinking_effort(value: object) -> str:
|
||||
normalized = str(value or "").strip().lower()
|
||||
if normalized in {"", "none"}:
|
||||
return ""
|
||||
if normalized in {"low", "medium", "high"}:
|
||||
return normalized
|
||||
if normalized in {"xhigh", "extended"}:
|
||||
return "extended"
|
||||
return ""
|
||||
|
||||
|
||||
def thinking_effort_from_body(body: dict[str, Any]) -> str:
|
||||
if "thinking_effort" in body:
|
||||
return normalize_thinking_effort(body.get("thinking_effort"))
|
||||
if "reasoning_effort" in body:
|
||||
return normalize_thinking_effort(body.get("reasoning_effort"))
|
||||
reasoning = body.get("reasoning")
|
||||
if isinstance(reasoning, dict):
|
||||
return normalize_thinking_effort(reasoning.get("effort"))
|
||||
return ""
|
||||
|
||||
|
||||
def completion_chunk(model: str, delta: dict[str, Any], finish_reason: str | None = None, completion_id: str = "", created: int | None = None) -> dict[str, Any]:
|
||||
return {
|
||||
"id": completion_id or f"chatcmpl-{uuid.uuid4().hex}",
|
||||
"object": "chat.completion.chunk",
|
||||
"created": created or int(time.time()),
|
||||
"model": model,
|
||||
"choices": [{"index": 0, "delta": delta, "finish_reason": finish_reason}],
|
||||
}
|
||||
|
||||
|
||||
def completion_response(
|
||||
model: str,
|
||||
content: str,
|
||||
created: int | None = None,
|
||||
messages: list[dict[str, Any]] | None = None,
|
||||
annotations: list[dict[str, Any]] | None = None,
|
||||
) -> dict[str, Any]:
|
||||
prompt_text_tokens = count_message_text_tokens(messages, model) if messages else 0
|
||||
prompt_image_tokens = count_message_image_tokens(messages, model) if messages else 0
|
||||
prompt_tokens = prompt_text_tokens + prompt_image_tokens
|
||||
completion_tokens = count_text_tokens(content, model) if messages else 0
|
||||
message = {"role": "assistant", "content": content}
|
||||
if annotations:
|
||||
message["annotations"] = annotations
|
||||
return {
|
||||
"id": f"chatcmpl-{uuid.uuid4().hex}",
|
||||
"object": "chat.completion",
|
||||
"created": created or int(time.time()),
|
||||
"model": model,
|
||||
"choices": [{
|
||||
"index": 0,
|
||||
"message": message,
|
||||
"finish_reason": "stop",
|
||||
}],
|
||||
"usage": {
|
||||
"prompt_tokens": prompt_tokens,
|
||||
"completion_tokens": completion_tokens,
|
||||
"total_tokens": prompt_tokens + completion_tokens,
|
||||
"prompt_tokens_details": {
|
||||
"text_tokens": prompt_text_tokens,
|
||||
"image_tokens": prompt_image_tokens,
|
||||
"cached_tokens": 0,
|
||||
},
|
||||
"completion_tokens_details": {
|
||||
"text_tokens": completion_tokens,
|
||||
"image_tokens": 0,
|
||||
"reasoning_tokens": 0,
|
||||
},
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def stream_text_chat_completion(
|
||||
backend,
|
||||
messages: list[dict[str, Any]],
|
||||
model: str,
|
||||
thinking_effort: str = "",
|
||||
) -> Iterator[dict[str, Any]]:
|
||||
completion_id = f"chatcmpl-{uuid.uuid4().hex}"
|
||||
created = int(time.time())
|
||||
sent_role = False
|
||||
request = ConversationRequest(model=model, messages=messages, thinking_effort=thinking_effort)
|
||||
for delta_text in stream_text_deltas(backend, request):
|
||||
if not sent_role:
|
||||
sent_role = True
|
||||
yield completion_chunk(model, {"role": "assistant", "content": delta_text}, None, completion_id, created)
|
||||
else:
|
||||
yield completion_chunk(model, {"content": delta_text}, None, completion_id, created)
|
||||
if not sent_role:
|
||||
yield completion_chunk(model, {"role": "assistant", "content": ""}, None, completion_id, created)
|
||||
yield completion_chunk(model, {}, "stop", completion_id, created)
|
||||
|
||||
|
||||
def collect_chat_content(chunks: Iterable[dict[str, Any]]) -> str:
|
||||
parts: list[str] = []
|
||||
for chunk in chunks:
|
||||
choices = chunk.get("choices")
|
||||
first = choices[0] if isinstance(choices, list) and choices and isinstance(choices[0], dict) else {}
|
||||
delta = first.get("delta") if isinstance(first.get("delta"), dict) else {}
|
||||
content = str(delta.get("content") or "")
|
||||
if content:
|
||||
parts.append(content)
|
||||
return "".join(parts)
|
||||
|
||||
|
||||
def chat_messages_from_body(body: dict[str, Any]) -> list[dict[str, Any]]:
|
||||
messages = body.get("messages")
|
||||
if isinstance(messages, list) and messages:
|
||||
return [message for message in messages if isinstance(message, dict)]
|
||||
prompt = str(body.get("prompt") or "").strip()
|
||||
if prompt:
|
||||
return [{"role": "user", "content": prompt}]
|
||||
raise HTTPException(status_code=400, detail={"error": "messages or prompt is required"})
|
||||
|
||||
|
||||
def chat_image_args(body: dict[str, Any]) -> tuple[str, str, int, list[tuple[bytes, str, str]]]:
|
||||
model = str(body.get("model") or "gpt-image-2").strip() or "gpt-image-2"
|
||||
prompt = extract_chat_prompt(body)
|
||||
if not prompt:
|
||||
raise HTTPException(status_code=400, detail={"error": "prompt is required"})
|
||||
images = [
|
||||
(data, f"image_{idx}.png", mime)
|
||||
for idx, (data, mime) in enumerate(extract_chat_image(body), start=1)
|
||||
]
|
||||
return model, prompt, parse_image_count(body.get("n")), images
|
||||
|
||||
|
||||
def text_chat_parts(body: dict[str, Any]) -> tuple[str, list[dict[str, Any]]]:
|
||||
model = str(body.get("model") or "auto").strip() or "auto"
|
||||
messages = normalize_text_messages(normalize_messages(chat_messages_from_body(body)))
|
||||
if has_unsupported_tools(body, WEB_SEARCH_TOOL_TYPES):
|
||||
messages.insert(0, {"role": "system", "content": TOOL_UNAVAILABLE_SYSTEM_MESSAGE})
|
||||
return model, messages
|
||||
|
||||
|
||||
def chat_completion_annotations(annotations: list[dict[str, Any]]) -> list[dict[str, Any]]:
|
||||
output = []
|
||||
for item in annotations:
|
||||
if item.get("type") != "url_citation":
|
||||
continue
|
||||
output.append({
|
||||
"type": "url_citation",
|
||||
"url_citation": {
|
||||
"start_index": item.get("start_index", 0),
|
||||
"end_index": item.get("end_index", 0),
|
||||
"url": item.get("url", ""),
|
||||
"title": item.get("title", ""),
|
||||
},
|
||||
})
|
||||
return output
|
||||
|
||||
|
||||
def web_search_chat_response(messages: list[dict[str, Any]], model: str) -> dict[str, Any]:
|
||||
query = search_query_from_messages(messages)
|
||||
if not query:
|
||||
raise HTTPException(status_code=400, detail={"error": "messages or prompt is required for web search"})
|
||||
text, annotations = text_with_url_citations(run_web_search(query))
|
||||
return completion_response(
|
||||
model,
|
||||
text,
|
||||
messages=messages,
|
||||
annotations=chat_completion_annotations(annotations),
|
||||
)
|
||||
|
||||
|
||||
def stream_web_search_chat_completion(messages: list[dict[str, Any]], model: str) -> Iterator[dict[str, Any]]:
|
||||
query = search_query_from_messages(messages)
|
||||
if not query:
|
||||
raise HTTPException(status_code=400, detail={"error": "messages or prompt is required for web search"})
|
||||
text, _annotations = text_with_url_citations(run_web_search(query))
|
||||
completion_id = f"chatcmpl-{uuid.uuid4().hex}"
|
||||
created = int(time.time())
|
||||
yield completion_chunk(model, {"role": "assistant", "content": text}, None, completion_id, created)
|
||||
yield completion_chunk(model, {}, "stop", completion_id, created)
|
||||
|
||||
|
||||
def image_result_content(result: dict[str, Any]) -> str:
|
||||
data = result.get("data")
|
||||
if isinstance(data, list) and data:
|
||||
return build_chat_image_markdown_content(result)
|
||||
return str(result.get("message") or "Image generation completed.")
|
||||
|
||||
|
||||
def image_chat_response(body: dict[str, Any]) -> dict[str, Any]:
|
||||
model, prompt, n, images = chat_image_args(body)
|
||||
result = collect_image_outputs(stream_image_outputs_with_pool(ConversationRequest(
|
||||
prompt=prompt,
|
||||
model=model,
|
||||
n=n,
|
||||
response_format="b64_json",
|
||||
images=encode_images(images) or None,
|
||||
)))
|
||||
response = completion_response(model, image_result_content(result), int(result.get("created") or 0) or None)
|
||||
usage = image_usage(
|
||||
input_text_tokens=count_text_tokens(prompt, model),
|
||||
input_image_tokens=count_image_inputs_tokens(images, model),
|
||||
output_tokens=count_image_output_items_tokens(result.get("data")),
|
||||
)
|
||||
response["usage"] = chat_usage_from_image_usage(usage)
|
||||
return response
|
||||
|
||||
|
||||
def image_chat_events(body: dict[str, Any]) -> Iterator[dict[str, Any]]:
|
||||
model, prompt, n, images = chat_image_args(body)
|
||||
image_outputs = stream_image_outputs_with_pool(ConversationRequest(
|
||||
prompt=prompt,
|
||||
model=model,
|
||||
n=n,
|
||||
response_format="b64_json",
|
||||
images=encode_images(images) or None,
|
||||
))
|
||||
yield from stream_image_chat_completion(image_outputs, model)
|
||||
|
||||
|
||||
def stream_image_chat_completion(image_outputs: Iterable[ImageOutput], model: str) -> Iterator[dict[str, Any]]:
|
||||
completion_id = f"chatcmpl-{uuid.uuid4().hex}"
|
||||
created = int(time.time())
|
||||
sent_role = False
|
||||
sent_text = ""
|
||||
for output in image_outputs:
|
||||
content = ""
|
||||
if output.kind == "progress":
|
||||
content = output.text
|
||||
sent_text += content
|
||||
elif output.kind == "result":
|
||||
content = build_chat_image_markdown_content({"data": output.data})
|
||||
elif output.kind == "message":
|
||||
content = output.text[len(sent_text):] if output.text.startswith(sent_text) else output.text
|
||||
if not content:
|
||||
continue
|
||||
if not sent_role:
|
||||
sent_role = True
|
||||
yield completion_chunk(model, {"role": "assistant", "content": content}, None, completion_id, created)
|
||||
else:
|
||||
yield completion_chunk(model, {"content": content}, None, completion_id, created)
|
||||
if not sent_role:
|
||||
yield completion_chunk(model, {"role": "assistant", "content": ""}, None, completion_id, created)
|
||||
yield completion_chunk(model, {}, "stop", completion_id, created)
|
||||
|
||||
|
||||
def handle(body: dict[str, Any]) -> dict[str, Any] | Iterator[dict[str, Any]]:
|
||||
if body.get("stream"):
|
||||
if is_image_chat_request(body):
|
||||
return image_chat_events(body)
|
||||
model, messages = text_chat_parts(body)
|
||||
if is_web_search_chat_request(body) and not has_unsupported_tools(body, WEB_SEARCH_TOOL_TYPES):
|
||||
return stream_web_search_chat_completion(messages, model)
|
||||
thinking_effort = thinking_effort_from_body(body)
|
||||
key = cache_key(body, messages, stream=True)
|
||||
return chat_completion_cache.get_or_compute_stream(
|
||||
key,
|
||||
lambda: stream_text_chat_completion(text_backend(model), messages, model, thinking_effort),
|
||||
)
|
||||
if is_image_chat_request(body):
|
||||
return image_chat_response(body)
|
||||
model, messages = text_chat_parts(body)
|
||||
if is_web_search_chat_request(body) and not has_unsupported_tools(body, WEB_SEARCH_TOOL_TYPES):
|
||||
return web_search_chat_response(messages, model)
|
||||
thinking_effort = thinking_effort_from_body(body)
|
||||
key = cache_key(body, messages, stream=False)
|
||||
return chat_completion_cache.get_or_compute_response(
|
||||
key,
|
||||
lambda: completion_response(
|
||||
model,
|
||||
collect_text(text_backend(model), ConversationRequest(model=model, messages=messages, thinking_effort=thinking_effort)),
|
||||
messages=messages,
|
||||
),
|
||||
)
|
||||
@@ -0,0 +1,86 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from io import BytesIO
|
||||
from typing import Any, Iterator
|
||||
|
||||
from PIL import Image
|
||||
|
||||
from services.protocol.conversation import (
|
||||
ConversationRequest,
|
||||
ImageGenerationError,
|
||||
collect_image_outputs,
|
||||
count_text_tokens,
|
||||
encode_images,
|
||||
stream_image_chunks,
|
||||
stream_image_outputs_with_pool,
|
||||
)
|
||||
from utils.image_tokens import count_image_inputs_tokens, count_image_output_items_tokens, image_usage
|
||||
|
||||
|
||||
def _composite_mask(
|
||||
images: list[tuple[bytes, str, str]],
|
||||
masks: list[tuple[bytes, str, str]],
|
||||
) -> list[tuple[bytes, str, str]]:
|
||||
"""将 mask 的 alpha 通道合成到图片中,标识需要编辑的区域。
|
||||
|
||||
mask 的透明区域(低 alpha)= 需要编辑的区域,
|
||||
mask 的不透明区域(高 alpha)= 保留的区域。
|
||||
如果无 mask 则返回原图。
|
||||
"""
|
||||
if not masks:
|
||||
return images
|
||||
result: list[tuple[bytes, str, str]] = []
|
||||
for i, (data, filename, mime_type) in enumerate(images):
|
||||
mask_data = masks[i][0] if i < len(masks) else masks[-1][0]
|
||||
img = Image.open(BytesIO(data)).convert("RGBA")
|
||||
mask_img = Image.open(BytesIO(mask_data))
|
||||
if mask_img.mode == "RGBA":
|
||||
alpha = mask_img.split()[3]
|
||||
elif mask_img.mode == "L":
|
||||
alpha = mask_img
|
||||
else:
|
||||
alpha = mask_img.convert("L")
|
||||
alpha = alpha.resize(img.size, Image.LANCZOS)
|
||||
img.putalpha(alpha)
|
||||
buf = BytesIO()
|
||||
img.save(buf, format="PNG")
|
||||
result.append((buf.getvalue(), filename, "image/png"))
|
||||
return result
|
||||
|
||||
|
||||
def handle(body: dict[str, Any]) -> dict[str, Any] | Iterator[dict[str, Any]]:
|
||||
prompt = str(body.get("prompt") or "")
|
||||
images = body.get("images") or []
|
||||
masks = body.get("mask") or []
|
||||
images = _composite_mask(images, masks)
|
||||
model = str(body.get("model") or "gpt-image-2")
|
||||
n = int(body.get("n") or 1)
|
||||
size = body.get("size")
|
||||
quality = str(body.get("quality") or "auto")
|
||||
response_format = str(body.get("response_format") or "b64_json")
|
||||
base_url = str(body.get("base_url") or "") or None
|
||||
progress_callback = body.get("progress_callback")
|
||||
encoded_images = encode_images(images)
|
||||
if not encoded_images:
|
||||
raise ImageGenerationError("image is required")
|
||||
outputs = stream_image_outputs_with_pool(ConversationRequest(
|
||||
prompt=prompt,
|
||||
model=model,
|
||||
n=n,
|
||||
size=size,
|
||||
quality=quality,
|
||||
response_format=response_format,
|
||||
base_url=base_url,
|
||||
images=encoded_images,
|
||||
message_as_error=True,
|
||||
progress_callback=progress_callback,
|
||||
))
|
||||
if body.get("stream"):
|
||||
return stream_image_chunks(outputs)
|
||||
result = collect_image_outputs(outputs)
|
||||
result["usage"] = image_usage(
|
||||
input_text_tokens=count_text_tokens(prompt, model),
|
||||
input_image_tokens=count_image_inputs_tokens(images, model),
|
||||
output_tokens=count_image_output_items_tokens(result.get("data"), size, quality),
|
||||
)
|
||||
return result
|
||||
@@ -0,0 +1,42 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any, Iterator
|
||||
|
||||
from services.protocol.conversation import (
|
||||
ConversationRequest,
|
||||
collect_image_outputs,
|
||||
count_text_tokens,
|
||||
stream_image_chunks,
|
||||
stream_image_outputs_with_pool,
|
||||
)
|
||||
from utils.image_tokens import count_image_output_items_tokens, image_usage
|
||||
|
||||
|
||||
def handle(body: dict[str, Any]) -> dict[str, Any] | Iterator[dict[str, Any]]:
|
||||
prompt = str(body.get("prompt") or "")
|
||||
model = str(body.get("model") or "gpt-image-2")
|
||||
n = int(body.get("n") or 1)
|
||||
size = body.get("size")
|
||||
quality = str(body.get("quality") or "auto")
|
||||
response_format = str(body.get("response_format") or "b64_json")
|
||||
base_url = str(body.get("base_url") or "") or None
|
||||
progress_callback = body.get("progress_callback")
|
||||
outputs = stream_image_outputs_with_pool(ConversationRequest(
|
||||
prompt=prompt,
|
||||
model=model,
|
||||
n=n,
|
||||
size=size,
|
||||
quality=quality,
|
||||
response_format=response_format,
|
||||
base_url=base_url,
|
||||
message_as_error=True,
|
||||
progress_callback=progress_callback,
|
||||
))
|
||||
if body.get("stream"):
|
||||
return stream_image_chunks(outputs)
|
||||
result = collect_image_outputs(outputs)
|
||||
result["usage"] = image_usage(
|
||||
input_text_tokens=count_text_tokens(prompt, model),
|
||||
output_tokens=count_image_output_items_tokens(result.get("data"), size, quality),
|
||||
)
|
||||
return result
|
||||
@@ -0,0 +1,53 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any
|
||||
|
||||
from services.account_service import account_service
|
||||
from services.model_service import model_catalog_service
|
||||
from utils.helper import CODEX_IMAGE_MODEL
|
||||
|
||||
|
||||
def list_models() -> dict[str, Any]:
|
||||
result = model_catalog_service.list_models()
|
||||
data = result.get("data")
|
||||
if not isinstance(data, list):
|
||||
return result
|
||||
seen = {str(item.get("id") or "").strip() for item in data if isinstance(item, dict)}
|
||||
dynamic_models: set[str] = set()
|
||||
accounts = account_service.list_accounts()
|
||||
web_image_accounts = [
|
||||
account
|
||||
for account in accounts
|
||||
if isinstance(account, dict)
|
||||
]
|
||||
codex_types = {
|
||||
normalized
|
||||
for account in accounts
|
||||
if isinstance(account, dict)
|
||||
and account_service._normalize_source_type(account.get("source_type")) == "codex"
|
||||
and (normalized := account_service._normalize_account_type(account.get("type")))
|
||||
}
|
||||
|
||||
if web_image_accounts:
|
||||
dynamic_models.add("gpt-image-2")
|
||||
if codex_types & {"Plus", "Team", "Pro"}:
|
||||
dynamic_models.add(CODEX_IMAGE_MODEL)
|
||||
if "Plus" in codex_types:
|
||||
dynamic_models.add(f"plus-{CODEX_IMAGE_MODEL}")
|
||||
if "Team" in codex_types:
|
||||
dynamic_models.add(f"team-{CODEX_IMAGE_MODEL}")
|
||||
if "Pro" in codex_types:
|
||||
dynamic_models.add(f"pro-{CODEX_IMAGE_MODEL}")
|
||||
|
||||
for model in sorted(dynamic_models):
|
||||
if model not in seen:
|
||||
data.append({
|
||||
"id": model,
|
||||
"object": "model",
|
||||
"created": 0,
|
||||
"owned_by": "chatgpt2api",
|
||||
"permission": [],
|
||||
"root": model,
|
||||
"parent": None,
|
||||
})
|
||||
return result
|
||||
@@ -0,0 +1,453 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import time
|
||||
import uuid
|
||||
from typing import Any, Iterable, Iterator
|
||||
|
||||
from fastapi import HTTPException
|
||||
|
||||
from services.protocol.chat_completion_cache import cache_key, chat_completion_cache, normalize_text_messages
|
||||
from services.protocol.conversation import (
|
||||
ConversationRequest,
|
||||
ImageOutput,
|
||||
count_message_image_tokens,
|
||||
count_message_text_tokens,
|
||||
count_text_tokens,
|
||||
encode_images,
|
||||
normalize_messages,
|
||||
stream_image_outputs_with_pool,
|
||||
stream_text_deltas,
|
||||
text_backend,
|
||||
)
|
||||
from services.protocol.web_search_tool import (
|
||||
WEB_SEARCH_TOOL_TYPES,
|
||||
has_unsupported_tools,
|
||||
has_web_search_tool,
|
||||
normalized_sources,
|
||||
run_web_search,
|
||||
search_query_from_messages,
|
||||
text_with_url_citations,
|
||||
)
|
||||
from utils.helper import extract_image_from_message_content, extract_response_prompt, has_response_image_generation_tool
|
||||
from utils.image_tokens import (
|
||||
count_image_content_tokens,
|
||||
count_image_output_items_tokens,
|
||||
image_usage,
|
||||
token_usage,
|
||||
)
|
||||
|
||||
TOOL_UNAVAILABLE_SYSTEM_MESSAGE = (
|
||||
"This compatibility backend cannot execute local tools, shell commands, non-search tools, "
|
||||
"or file operations. Do not claim to have run tools or inspected external resources. "
|
||||
"If a user asks you to use a tool, say that tool execution is unavailable through this backend."
|
||||
)
|
||||
|
||||
RESPONSE_CONTENT_PART_TYPES = {"text", "input_text", "output_text", "image_url", "input_image", "image"}
|
||||
|
||||
|
||||
def normalize_thinking_effort(value: object) -> str:
|
||||
normalized = str(value or "").strip().lower()
|
||||
if normalized in {"", "none"}:
|
||||
return ""
|
||||
if normalized in {"low", "medium", "high"}:
|
||||
return normalized
|
||||
if normalized in {"xhigh", "extended"}:
|
||||
return "extended"
|
||||
return ""
|
||||
|
||||
|
||||
def thinking_effort_from_body(body: dict[str, Any]) -> str:
|
||||
reasoning = body.get("reasoning")
|
||||
if isinstance(reasoning, dict):
|
||||
return normalize_thinking_effort(reasoning.get("effort"))
|
||||
if "thinking_effort" in body:
|
||||
return normalize_thinking_effort(body.get("thinking_effort"))
|
||||
if "reasoning_effort" in body:
|
||||
return normalize_thinking_effort(body.get("reasoning_effort"))
|
||||
return ""
|
||||
|
||||
|
||||
def is_text_response_request(body: dict[str, Any]) -> bool:
|
||||
return not has_response_image_generation_tool(body)
|
||||
|
||||
|
||||
def has_unsupported_response_tools(body: dict[str, Any]) -> bool:
|
||||
return has_unsupported_tools(body, {"image_generation", *WEB_SEARCH_TOOL_TYPES})
|
||||
|
||||
|
||||
def response_image_tool(body: dict[str, Any]) -> dict[str, object]:
|
||||
for tool in body.get("tools") or []:
|
||||
if isinstance(tool, dict) and tool.get("type") == "image_generation":
|
||||
return tool
|
||||
return {}
|
||||
|
||||
|
||||
def extract_response_image(input_value: object) -> tuple[bytes, str] | None:
|
||||
if isinstance(input_value, dict):
|
||||
if str(input_value.get("type") or "").strip() == "input_image":
|
||||
images = extract_image_from_message_content([input_value])
|
||||
return images[0] if images else None
|
||||
images = extract_image_from_message_content(input_value.get("content"))
|
||||
return images[0] if images else None
|
||||
if not isinstance(input_value, list):
|
||||
return None
|
||||
for item in reversed(input_value):
|
||||
if isinstance(item, dict):
|
||||
if str(item.get("type") or "").strip() == "input_image":
|
||||
images = extract_image_from_message_content([item])
|
||||
if images:
|
||||
return images[0]
|
||||
images = extract_image_from_message_content(item.get("content"))
|
||||
if images:
|
||||
return images[0]
|
||||
return None
|
||||
|
||||
|
||||
def _input_image_parts(input_value: object) -> list[dict[str, Any]]:
|
||||
parts: list[dict[str, Any]] = []
|
||||
if isinstance(input_value, dict):
|
||||
content = input_value.get("content")
|
||||
if isinstance(content, list):
|
||||
parts.extend(item for item in content if isinstance(item, dict))
|
||||
return parts
|
||||
if not isinstance(input_value, list):
|
||||
return parts
|
||||
if all(isinstance(item, dict) and item.get("type") for item in input_value):
|
||||
return [item for item in input_value if isinstance(item, dict)]
|
||||
for item in input_value:
|
||||
if isinstance(item, dict):
|
||||
content = item.get("content")
|
||||
if isinstance(content, list):
|
||||
parts.extend(part for part in content if isinstance(part, dict))
|
||||
return parts
|
||||
|
||||
|
||||
def _is_response_content_part(value: object) -> bool:
|
||||
if not isinstance(value, dict):
|
||||
return False
|
||||
part_type = str(value.get("type") or "").strip()
|
||||
return part_type in RESPONSE_CONTENT_PART_TYPES or ("image_url" in value and part_type != "message")
|
||||
|
||||
|
||||
def _message_content_from_response_item(item: dict[str, Any]) -> object:
|
||||
content = item.get("content")
|
||||
if isinstance(content, list):
|
||||
return [dict(part) if isinstance(part, dict) else part for part in content]
|
||||
if isinstance(content, str):
|
||||
return content
|
||||
return extract_response_prompt([item]) or content or ""
|
||||
|
||||
|
||||
def _append_response_message(messages: list[dict[str, Any]], role: object, content: object) -> None:
|
||||
if isinstance(content, str):
|
||||
if content.strip():
|
||||
messages.append({"role": str(role or "user"), "content": content.strip()})
|
||||
return
|
||||
if isinstance(content, list) and content:
|
||||
messages.append({"role": str(role or "user"), "content": content})
|
||||
|
||||
|
||||
def messages_from_input(input_value: object, instructions: object = None) -> list[dict[str, Any]]:
|
||||
messages: list[dict[str, Any]] = []
|
||||
system_text = str(instructions or "").strip()
|
||||
if system_text:
|
||||
messages.append({"role": "system", "content": system_text})
|
||||
if isinstance(input_value, str):
|
||||
if input_value.strip():
|
||||
messages.append({"role": "user", "content": input_value.strip()})
|
||||
return messages
|
||||
if isinstance(input_value, dict):
|
||||
if _is_response_content_part(input_value):
|
||||
_append_response_message(messages, "user", [dict(input_value)])
|
||||
return messages
|
||||
_append_response_message(
|
||||
messages,
|
||||
input_value.get("role") or "user",
|
||||
_message_content_from_response_item(input_value),
|
||||
)
|
||||
return messages
|
||||
if isinstance(input_value, list):
|
||||
if all(_is_response_content_part(item) for item in input_value):
|
||||
_append_response_message(messages, "user", [dict(item) for item in input_value if isinstance(item, dict)])
|
||||
return messages
|
||||
pending_parts: list[dict[str, Any]] = []
|
||||
for item in input_value:
|
||||
if _is_response_content_part(item):
|
||||
pending_parts.append(dict(item))
|
||||
continue
|
||||
if pending_parts:
|
||||
_append_response_message(messages, "user", pending_parts)
|
||||
pending_parts = []
|
||||
if not isinstance(item, dict):
|
||||
continue
|
||||
_append_response_message(
|
||||
messages,
|
||||
item.get("role") or "user",
|
||||
_message_content_from_response_item(item),
|
||||
)
|
||||
if pending_parts:
|
||||
_append_response_message(messages, "user", pending_parts)
|
||||
return messages
|
||||
|
||||
|
||||
def text_output_item(
|
||||
text: str,
|
||||
item_id: str | None = None,
|
||||
status: str = "completed",
|
||||
annotations: list[dict[str, Any]] | None = None,
|
||||
) -> dict[str, Any]:
|
||||
return {
|
||||
"id": item_id or f"msg_{uuid.uuid4().hex}",
|
||||
"type": "message",
|
||||
"status": status,
|
||||
"role": "assistant",
|
||||
"content": [{"type": "output_text", "text": text, "annotations": annotations or []}],
|
||||
}
|
||||
|
||||
|
||||
def web_search_call_item(
|
||||
query: str,
|
||||
item_id: str | None = None,
|
||||
status: str = "completed",
|
||||
sources: list[dict[str, str]] | None = None,
|
||||
) -> dict[str, Any]:
|
||||
action: dict[str, Any] = {
|
||||
"type": "search",
|
||||
"query": query,
|
||||
"queries": [query],
|
||||
}
|
||||
if sources:
|
||||
action["sources"] = [
|
||||
{"type": "url", "url": source["url"]}
|
||||
for source in sources
|
||||
if source.get("url")
|
||||
]
|
||||
return {
|
||||
"id": item_id or f"ws_{uuid.uuid4().hex}",
|
||||
"type": "web_search_call",
|
||||
"status": status,
|
||||
"action": action,
|
||||
}
|
||||
|
||||
|
||||
def image_output_items(prompt: str, data: list[dict[str, Any]], item_id: str | None = None) -> list[dict[str, Any]]:
|
||||
output = []
|
||||
for item in data:
|
||||
b64_json = str(item.get("b64_json") or "").strip()
|
||||
if b64_json:
|
||||
output.append({
|
||||
"id": item_id or f"ig_{len(output) + 1}",
|
||||
"type": "image_generation_call",
|
||||
"status": "completed",
|
||||
"result": b64_json,
|
||||
"revised_prompt": str(item.get("revised_prompt") or prompt).strip() or prompt,
|
||||
})
|
||||
return output
|
||||
|
||||
|
||||
def response_created(response_id: str, model: str, created: int) -> dict[str, Any]:
|
||||
return {
|
||||
"type": "response.created",
|
||||
"response": {
|
||||
"id": response_id,
|
||||
"object": "response",
|
||||
"created_at": created,
|
||||
"status": "in_progress",
|
||||
"error": None,
|
||||
"incomplete_details": None,
|
||||
"model": model,
|
||||
"output": [],
|
||||
"parallel_tool_calls": False,
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def response_completed(
|
||||
response_id: str,
|
||||
model: str,
|
||||
created: int,
|
||||
output: list[dict[str, Any]],
|
||||
usage: dict[str, Any] | None = None,
|
||||
) -> dict[str, Any]:
|
||||
response = {
|
||||
"type": "response.completed",
|
||||
"response": {
|
||||
"id": response_id,
|
||||
"object": "response",
|
||||
"created_at": created,
|
||||
"status": "completed",
|
||||
"error": None,
|
||||
"incomplete_details": None,
|
||||
"model": model,
|
||||
"output": output,
|
||||
"parallel_tool_calls": False,
|
||||
},
|
||||
}
|
||||
if usage:
|
||||
response["response"]["usage"] = usage
|
||||
return response
|
||||
|
||||
|
||||
def text_response_parts(body: dict[str, Any]) -> tuple[str, list[dict[str, Any]]]:
|
||||
model = str(body.get("model") or "auto").strip() or "auto"
|
||||
messages = normalize_text_messages(normalize_messages(messages_from_input(body.get("input"), body.get("instructions"))))
|
||||
if has_unsupported_response_tools(body):
|
||||
messages.insert(0, {"role": "system", "content": TOOL_UNAVAILABLE_SYSTEM_MESSAGE})
|
||||
return model, messages
|
||||
|
||||
|
||||
def stream_text_response(backend, body: dict[str, Any], messages: list[dict[str, Any]] | None = None) -> Iterator[dict[str, Any]]:
|
||||
model = str(body.get("model") or "auto").strip() or "auto"
|
||||
messages = messages if messages is not None else messages_from_input(body.get("input"), body.get("instructions"))
|
||||
thinking_effort = thinking_effort_from_body(body)
|
||||
response_id = f"resp_{uuid.uuid4().hex}"
|
||||
item_id = f"msg_{uuid.uuid4().hex}"
|
||||
created = int(time.time())
|
||||
full_text = ""
|
||||
yield response_created(response_id, model, created)
|
||||
yield {"type": "response.output_item.added", "output_index": 0, "item": text_output_item("", item_id, "in_progress")}
|
||||
request = ConversationRequest(model=model, messages=messages, thinking_effort=thinking_effort)
|
||||
for delta in stream_text_deltas(backend, request):
|
||||
full_text += delta
|
||||
yield {"type": "response.output_text.delta", "item_id": item_id, "output_index": 0, "content_index": 0, "delta": delta}
|
||||
yield {"type": "response.output_text.done", "item_id": item_id, "output_index": 0, "content_index": 0, "text": full_text}
|
||||
item = text_output_item(full_text, item_id, "completed")
|
||||
yield {"type": "response.output_item.done", "output_index": 0, "item": item}
|
||||
usage = token_usage(
|
||||
input_text_tokens=count_message_text_tokens(messages, model),
|
||||
input_image_tokens=count_message_image_tokens(messages, model),
|
||||
output_text_tokens=count_text_tokens(full_text, model),
|
||||
)
|
||||
yield response_completed(response_id, model, created, [item], usage)
|
||||
|
||||
|
||||
def stream_web_search_response(body: dict[str, Any], messages: list[dict[str, Any]] | None = None) -> Iterator[dict[str, Any]]:
|
||||
model = str(body.get("model") or "auto").strip() or "auto"
|
||||
messages = messages if messages is not None else messages_from_input(body.get("input"), body.get("instructions"))
|
||||
query = search_query_from_messages(messages) or extract_response_prompt(body.get("input"))
|
||||
if not query:
|
||||
raise HTTPException(status_code=400, detail={"error": "input text is required for web_search"})
|
||||
|
||||
response_id = f"resp_{uuid.uuid4().hex}"
|
||||
search_id = f"ws_{uuid.uuid4().hex}"
|
||||
item_id = f"msg_{uuid.uuid4().hex}"
|
||||
created = int(time.time())
|
||||
yield response_created(response_id, model, created)
|
||||
|
||||
searching_item = web_search_call_item(query, search_id, "in_progress")
|
||||
yield {"type": "response.output_item.added", "output_index": 0, "item": searching_item}
|
||||
yield {"type": "response.web_search_call.in_progress", "output_index": 0, "item_id": search_id}
|
||||
yield {"type": "response.web_search_call.searching", "output_index": 0, "item_id": search_id}
|
||||
result = run_web_search(query)
|
||||
search_item = web_search_call_item(query, search_id, "completed", normalized_sources(result))
|
||||
yield {"type": "response.web_search_call.completed", "output_index": 0, "item_id": search_id}
|
||||
yield {"type": "response.output_item.done", "output_index": 0, "item": search_item}
|
||||
|
||||
text, annotations = text_with_url_citations(result)
|
||||
message_item = text_output_item("", item_id, "in_progress", annotations)
|
||||
yield {"type": "response.output_item.added", "output_index": 1, "item": message_item}
|
||||
if text:
|
||||
yield {"type": "response.output_text.delta", "item_id": item_id, "output_index": 1, "content_index": 0, "delta": text}
|
||||
yield {"type": "response.output_text.done", "item_id": item_id, "output_index": 1, "content_index": 0, "text": text}
|
||||
message_item = text_output_item(text, item_id, "completed", annotations)
|
||||
yield {"type": "response.output_item.done", "output_index": 1, "item": message_item}
|
||||
usage = token_usage(
|
||||
input_text_tokens=count_message_text_tokens(messages, model),
|
||||
input_image_tokens=count_message_image_tokens(messages, model),
|
||||
output_text_tokens=count_text_tokens(text, model),
|
||||
)
|
||||
yield response_completed(response_id, model, created, [search_item, message_item], usage)
|
||||
|
||||
|
||||
def stream_image_response(
|
||||
image_outputs: Iterable[ImageOutput],
|
||||
prompt: str,
|
||||
model: str,
|
||||
input_image_tokens: int = 0,
|
||||
size: object = None,
|
||||
quality: str = "auto",
|
||||
) -> Iterator[dict[str, Any]]:
|
||||
response_id = f"resp_{uuid.uuid4().hex}"
|
||||
created = int(time.time())
|
||||
yield response_created(response_id, model, created)
|
||||
for output in image_outputs:
|
||||
if output.kind == "message":
|
||||
text = output.text
|
||||
item = text_output_item(text)
|
||||
usage = token_usage(
|
||||
input_text_tokens=count_text_tokens(prompt, model),
|
||||
input_image_tokens=input_image_tokens,
|
||||
output_text_tokens=count_text_tokens(text, model),
|
||||
)
|
||||
yield {"type": "response.output_text.delta", "item_id": item["id"], "output_index": 0, "content_index": 0, "delta": text}
|
||||
yield {"type": "response.output_text.done", "item_id": item["id"], "output_index": 0, "content_index": 0, "text": text}
|
||||
yield {"type": "response.output_item.done", "output_index": 0, "item": item}
|
||||
yield response_completed(response_id, model, created, [item], usage)
|
||||
return
|
||||
if output.kind != "result":
|
||||
continue
|
||||
items = image_output_items(prompt, output.data)
|
||||
if items:
|
||||
usage = image_usage(
|
||||
input_text_tokens=count_text_tokens(prompt, model),
|
||||
input_image_tokens=input_image_tokens,
|
||||
output_tokens=count_image_output_items_tokens(output.data, size, quality),
|
||||
)
|
||||
for output_index, item in enumerate(items):
|
||||
yield {"type": "response.output_item.done", "output_index": output_index, "item": item}
|
||||
yield response_completed(response_id, model, created, items, usage)
|
||||
return
|
||||
raise RuntimeError("image generation failed")
|
||||
|
||||
|
||||
def collect_response(events: Iterable[dict[str, Any]]) -> dict[str, Any]:
|
||||
completed = {}
|
||||
for event in events:
|
||||
if event.get("type") == "response.completed":
|
||||
completed = event.get("response") if isinstance(event.get("response"), dict) else {}
|
||||
if not completed:
|
||||
raise RuntimeError("response generation failed")
|
||||
return completed
|
||||
|
||||
|
||||
def response_events(body: dict[str, Any]) -> Iterator[dict[str, Any]]:
|
||||
if is_text_response_request(body):
|
||||
model, messages = text_response_parts(body)
|
||||
if has_web_search_tool(body) and not has_unsupported_response_tools(body):
|
||||
yield from stream_web_search_response(body, messages)
|
||||
return
|
||||
key = cache_key(body, messages, stream=bool(body.get("stream")))
|
||||
yield from chat_completion_cache.get_or_compute_stream(
|
||||
key,
|
||||
lambda: stream_text_response(text_backend(model), body, messages),
|
||||
)
|
||||
return
|
||||
|
||||
prompt = extract_response_prompt(body.get("input"))
|
||||
if not prompt:
|
||||
raise HTTPException(status_code=400, detail={"error": "input text is required"})
|
||||
model = str(body.get("model") or "gpt-image-2").strip() or "gpt-image-2"
|
||||
image_info = extract_response_image(body.get("input"))
|
||||
if image_info:
|
||||
image_data, mime_type = image_info
|
||||
images = encode_images([(image_data, "image.png", mime_type)])
|
||||
else:
|
||||
images = None
|
||||
input_image_tokens = count_image_content_tokens(_input_image_parts(body.get("input")), model)
|
||||
tool = response_image_tool(body)
|
||||
image_outputs = stream_image_outputs_with_pool(ConversationRequest(
|
||||
prompt=prompt,
|
||||
model=model,
|
||||
size=tool.get("size"),
|
||||
quality=str(tool.get("quality") or "auto"),
|
||||
response_format="b64_json",
|
||||
images=images,
|
||||
))
|
||||
yield from stream_image_response(image_outputs, prompt, model, input_image_tokens, tool.get("size"), str(tool.get("quality") or "auto"))
|
||||
|
||||
|
||||
def handle(body: dict[str, Any]) -> dict[str, Any] | Iterator[dict[str, Any]]:
|
||||
events = response_events(body)
|
||||
if body.get("stream"):
|
||||
return events
|
||||
return collect_response(events)
|
||||
@@ -0,0 +1,160 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from typing import Any
|
||||
|
||||
from services.account_service import account_service
|
||||
from services.openai_backend_api import OpenAIBackendAPI
|
||||
|
||||
WEB_SEARCH_TOOL_TYPES = {"web_search", "web_search_preview", "web_search_preview_2025_03_11"}
|
||||
SEARCH_CHAT_MODEL_PREFIXES = (
|
||||
"gpt-4o-search-preview",
|
||||
"gpt-4o-mini-search-preview",
|
||||
"gpt-5-search-api",
|
||||
)
|
||||
|
||||
|
||||
def _tool_type(tool: object) -> str:
|
||||
return str(tool.get("type") or "").strip() if isinstance(tool, dict) else ""
|
||||
|
||||
|
||||
def has_web_search_tool(body: dict[str, Any]) -> bool:
|
||||
tools = body.get("tools")
|
||||
if isinstance(tools, list):
|
||||
return any(_tool_type(tool) in WEB_SEARCH_TOOL_TYPES for tool in tools)
|
||||
tool_choice = body.get("tool_choice")
|
||||
return _tool_type(tool_choice) in WEB_SEARCH_TOOL_TYPES
|
||||
|
||||
|
||||
def is_web_search_chat_request(body: dict[str, Any]) -> bool:
|
||||
model = str(body.get("model") or "").strip()
|
||||
return (
|
||||
has_web_search_tool(body)
|
||||
or isinstance(body.get("web_search_options"), dict)
|
||||
or any(
|
||||
model == prefix or model.startswith(f"{prefix}-")
|
||||
for prefix in SEARCH_CHAT_MODEL_PREFIXES
|
||||
)
|
||||
)
|
||||
|
||||
|
||||
def has_unsupported_tools(body: dict[str, Any], allowed_types: set[str]) -> bool:
|
||||
tools = body.get("tools")
|
||||
if not isinstance(tools, list):
|
||||
return False
|
||||
return any(_tool_type(tool) not in allowed_types for tool in tools if isinstance(tool, dict))
|
||||
|
||||
|
||||
def message_text(value: object) -> str:
|
||||
if isinstance(value, str):
|
||||
return value.strip()
|
||||
if isinstance(value, list):
|
||||
parts: list[str] = []
|
||||
for item in value:
|
||||
if isinstance(item, str):
|
||||
text = item.strip()
|
||||
elif isinstance(item, dict):
|
||||
text = str(item.get("text") or item.get("input_text") or "").strip()
|
||||
else:
|
||||
text = ""
|
||||
if text:
|
||||
parts.append(text)
|
||||
return "\n".join(parts).strip()
|
||||
return ""
|
||||
|
||||
|
||||
def search_query_from_messages(messages: list[dict[str, Any]]) -> str:
|
||||
for message in reversed(messages):
|
||||
if str(message.get("role") or "").strip().lower() != "user":
|
||||
continue
|
||||
text = message_text(message.get("content"))
|
||||
if text:
|
||||
return text
|
||||
return ""
|
||||
|
||||
|
||||
def _readable_annotation_part(parts: list[str]) -> str:
|
||||
for part in parts:
|
||||
value = part.strip()
|
||||
lower = value.lower()
|
||||
if value and not (
|
||||
lower.startswith(("turn", "source", "sources"))
|
||||
or re.fullmatch(r"\d+", value)
|
||||
):
|
||||
return value
|
||||
return ""
|
||||
|
||||
|
||||
def clean_search_text(text: str) -> str:
|
||||
def replace_annotation(match: re.Match[str]) -> str:
|
||||
parts = [part.strip() for part in match.group(1).split("\ue202")]
|
||||
kind = (parts[0] if parts else "").lower()
|
||||
data = parts[1:]
|
||||
if kind == "url":
|
||||
label = data[0] if data else ""
|
||||
url = data[1] if len(data) > 1 else ""
|
||||
if label and url.startswith(("http://", "https://")):
|
||||
return f"{label} ({url})"
|
||||
return label or url
|
||||
if kind == "cite":
|
||||
return _readable_annotation_part(data)
|
||||
return _readable_annotation_part(data)
|
||||
|
||||
text = re.sub(r"\ue200([^\ue201]*)\ue201", replace_annotation, text)
|
||||
text = re.sub(r"\ue200[^\ue201]*$", "", text)
|
||||
return re.sub(r"\s+([.,;:!?])", r"\1", text).strip()
|
||||
|
||||
|
||||
def normalized_sources(result: dict[str, Any]) -> list[dict[str, str]]:
|
||||
sources = result.get("sources")
|
||||
if not isinstance(sources, list):
|
||||
return []
|
||||
output: list[dict[str, str]] = []
|
||||
seen: set[str] = set()
|
||||
for item in sources:
|
||||
if not isinstance(item, dict):
|
||||
continue
|
||||
url = str(item.get("url") or "").strip()
|
||||
title = str(item.get("title") or "").strip()
|
||||
snippet = str(item.get("snippet") or "").strip()
|
||||
if not url or url in seen:
|
||||
continue
|
||||
seen.add(url)
|
||||
output.append({"title": title, "url": url, "snippet": snippet})
|
||||
return output
|
||||
|
||||
|
||||
def text_with_url_citations(result: dict[str, Any]) -> tuple[str, list[dict[str, Any]]]:
|
||||
text = clean_search_text(str(result.get("answer") or ""))
|
||||
annotations: list[dict[str, Any]] = []
|
||||
sources = normalized_sources(result)
|
||||
if sources:
|
||||
text = text.rstrip()
|
||||
if text:
|
||||
text += "\n\n"
|
||||
text += "Sources:\n"
|
||||
for index, source in enumerate(sources, start=1):
|
||||
title = source["title"] or source["url"]
|
||||
line_prefix = f"{index}. {title}"
|
||||
text += line_prefix
|
||||
if source["url"]:
|
||||
if source["title"]:
|
||||
text += " - "
|
||||
start = len(text)
|
||||
text += source["url"]
|
||||
annotations.append({
|
||||
"type": "url_citation",
|
||||
"start_index": start,
|
||||
"end_index": len(text),
|
||||
"url": source["url"],
|
||||
"title": source["title"] or source["url"],
|
||||
})
|
||||
text += "\n"
|
||||
return text.strip(), annotations
|
||||
|
||||
|
||||
def run_web_search(query: str) -> dict[str, Any]:
|
||||
token = account_service.get_text_access_token()
|
||||
result = OpenAIBackendAPI(token).search(query)
|
||||
account_service.mark_text_used(token)
|
||||
return result
|
||||
@@ -0,0 +1,648 @@
|
||||
"""Global outbound proxy and Cloudflare clearance helpers."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass, field, replace
|
||||
import json
|
||||
import re
|
||||
import threading
|
||||
import time
|
||||
from typing import Callable, Mapping
|
||||
from urllib import request as urllib_request
|
||||
from urllib.parse import quote, urlparse
|
||||
|
||||
from curl_cffi.requests import Session
|
||||
|
||||
from services.config import config
|
||||
|
||||
|
||||
FlareSolverrRequestMethod = Callable[[str, bytes, dict[str, str], float], bytes]
|
||||
|
||||
|
||||
def normalize_proxy_url(url: str) -> str:
|
||||
"""Normalize proxy URLs for curl_cffi.
|
||||
|
||||
SOCKS proxies should use remote-DNS resolution by default, so generic
|
||||
``socks://`` and ``socks5://`` inputs are upgraded to ``socks5h://``.
|
||||
HTTP/HTTPS/socks5h inputs are otherwise left untouched except trimming.
|
||||
"""
|
||||
candidate = str(url or "").strip()
|
||||
if candidate and "://" not in candidate:
|
||||
candidate = _colon_proxy_to_url(candidate)
|
||||
lowered = candidate.lower()
|
||||
if lowered.startswith("socks://"):
|
||||
return "socks5h://" + candidate[len("socks://") :]
|
||||
if lowered.startswith("socks5://"):
|
||||
return "socks5h://" + candidate[len("socks5://") :]
|
||||
return candidate
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ProxyRuntimeProfile:
|
||||
proxy_url: str = ""
|
||||
proxy_source: str = "direct"
|
||||
resource: bool = False
|
||||
runtime_enabled: bool = False
|
||||
egress_mode: str = "direct"
|
||||
skip_ssl_verify: bool = False
|
||||
reset_session_status_codes: tuple[int, ...] = field(default_factory=lambda: (403,))
|
||||
clearance: dict[str, object] = field(default_factory=dict, repr=False)
|
||||
|
||||
@property
|
||||
def clearance_enabled(self) -> bool:
|
||||
return (
|
||||
self.runtime_enabled
|
||||
and bool(self.clearance.get("enabled"))
|
||||
and self.clearance_mode in {"manual", "flaresolverr"}
|
||||
)
|
||||
|
||||
@property
|
||||
def clearance_mode(self) -> str:
|
||||
return str(self.clearance.get("mode") or "none").strip().lower()
|
||||
|
||||
@property
|
||||
def refresh_interval(self) -> int:
|
||||
try:
|
||||
return max(0, int(self.clearance.get("refresh_interval") or 0))
|
||||
except (OverflowError, TypeError, ValueError):
|
||||
return 0
|
||||
|
||||
@property
|
||||
def timeout_sec(self) -> int:
|
||||
try:
|
||||
return max(1, int(self.clearance.get("timeout_sec") or 60))
|
||||
except (OverflowError, TypeError, ValueError):
|
||||
return 60
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ClearanceBundle:
|
||||
target_host: str
|
||||
proxy_url: str = ""
|
||||
cookies: dict[str, str] = field(default_factory=dict, repr=False)
|
||||
user_agent: str = ""
|
||||
created_at: float = field(default_factory=time.time)
|
||||
expires_at: float | None = None
|
||||
|
||||
def is_valid_for(self, target_host: str, proxy_url: str, *, now: float | None = None) -> bool:
|
||||
host = _normalize_host(target_host)
|
||||
if self.target_host and host and _normalize_host(self.target_host) != host:
|
||||
return False
|
||||
if normalize_proxy_url(self.proxy_url) != normalize_proxy_url(proxy_url):
|
||||
return False
|
||||
if self.expires_at is not None and (time.time() if now is None else now) >= self.expires_at:
|
||||
return False
|
||||
return bool(self.cookies or self.user_agent)
|
||||
|
||||
def cookie_header(self) -> str:
|
||||
return _cookies_to_header(self.cookies)
|
||||
|
||||
|
||||
class FlareSolverrClearanceProvider:
|
||||
def __init__(self, flaresolverr_url: str, request_method: FlareSolverrRequestMethod | None = None) -> None:
|
||||
self.flaresolverr_url = str(flaresolverr_url or "").strip().rstrip("/")
|
||||
self._request_method = request_method or self._urllib_post
|
||||
|
||||
def get_clearance(self, target_url: str, proxy_url: str = "", timeout_sec: int = 60) -> ClearanceBundle | None:
|
||||
if not self.flaresolverr_url:
|
||||
return None
|
||||
|
||||
timeout = _coerce_timeout(timeout_sec)
|
||||
payload: dict[str, object] = {
|
||||
"cmd": "request.get",
|
||||
"url": str(target_url or ""),
|
||||
"maxTimeout": int(timeout * 1000),
|
||||
}
|
||||
proxy_url = normalize_proxy_url(proxy_url)
|
||||
if proxy_url:
|
||||
payload["proxy"] = {"url": proxy_url}
|
||||
|
||||
endpoint = f"{self.flaresolverr_url}/v1"
|
||||
try:
|
||||
body = json.dumps(payload).encode("utf-8")
|
||||
raw_response = self._request_method(
|
||||
endpoint,
|
||||
body,
|
||||
{"Content-Type": "application/json"},
|
||||
timeout,
|
||||
)
|
||||
data = json.loads(raw_response.decode("utf-8") if isinstance(raw_response, bytes) else raw_response)
|
||||
except Exception:
|
||||
return None
|
||||
|
||||
if not isinstance(data, dict) or str(data.get("status") or "").lower() != "ok":
|
||||
return None
|
||||
solution = data.get("solution")
|
||||
if not isinstance(solution, dict):
|
||||
return None
|
||||
|
||||
target_host = _host_from_url(target_url)
|
||||
cookies = _filter_flaresolverr_cookies(solution.get("cookies"), target_host)
|
||||
user_agent = str(solution.get("userAgent") or "").strip()
|
||||
if not cookies and not user_agent:
|
||||
return None
|
||||
return ClearanceBundle(
|
||||
target_host=target_host,
|
||||
proxy_url=proxy_url,
|
||||
cookies=cookies,
|
||||
user_agent=user_agent,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _urllib_post(endpoint: str, body: bytes, headers: dict[str, str], timeout: float) -> bytes:
|
||||
req = urllib_request.Request(endpoint, data=body, headers=headers, method="POST")
|
||||
with urllib_request.urlopen(req, timeout=timeout) as response:
|
||||
return response.read()
|
||||
|
||||
|
||||
class ProxySettingsStore:
|
||||
def __init__(
|
||||
self,
|
||||
config_store=None,
|
||||
clearance_provider_factory: Callable[[str], FlareSolverrClearanceProvider] | None = None,
|
||||
) -> None:
|
||||
self._config = config_store or config
|
||||
self._clearance_provider_factory = clearance_provider_factory or FlareSolverrClearanceProvider
|
||||
self._clearance_cache: dict[tuple[str, str], ClearanceBundle] = {}
|
||||
self._provider_cache: dict[str, FlareSolverrClearanceProvider] = {}
|
||||
self._flight_locks: dict[tuple[str, str], threading.Lock] = {}
|
||||
self._lock = threading.RLock()
|
||||
|
||||
def get_profile(
|
||||
self,
|
||||
account: dict | None = None,
|
||||
proxy: str = "",
|
||||
resource: bool = False,
|
||||
upstream: bool = False,
|
||||
) -> ProxyRuntimeProfile:
|
||||
runtime = self._get_runtime_settings()
|
||||
clearance = dict(runtime.get("clearance") if isinstance(runtime.get("clearance"), dict) else {})
|
||||
runtime_enabled = bool(runtime.get("enabled"))
|
||||
egress_mode = str(runtime.get("egress_mode") or "direct").strip().lower()
|
||||
|
||||
account_proxy = _clean((account or {}).get("proxy") if isinstance(account, dict) else "")
|
||||
explicit_proxy = _clean(proxy)
|
||||
legacy_proxy = _clean(self._config.get_proxy_settings())
|
||||
|
||||
runtime_proxy = ""
|
||||
runtime_proxy_source = "runtime"
|
||||
if upstream and runtime_enabled and egress_mode == "single_proxy":
|
||||
resource_proxy = _clean(runtime.get("resource_proxy_url")) if resource else ""
|
||||
runtime_proxy = resource_proxy or _clean(runtime.get("proxy_url"))
|
||||
runtime_proxy_source = "runtime_resource" if resource_proxy else "runtime"
|
||||
|
||||
selected_proxy = ""
|
||||
source = "direct"
|
||||
if account_proxy:
|
||||
selected_proxy = account_proxy
|
||||
source = "account"
|
||||
elif runtime_proxy:
|
||||
selected_proxy = runtime_proxy
|
||||
source = runtime_proxy_source
|
||||
elif explicit_proxy:
|
||||
selected_proxy = explicit_proxy
|
||||
source = "explicit"
|
||||
elif legacy_proxy:
|
||||
selected_proxy = legacy_proxy
|
||||
source = "global"
|
||||
|
||||
return ProxyRuntimeProfile(
|
||||
proxy_url=normalize_proxy_url(selected_proxy),
|
||||
proxy_source=source,
|
||||
resource=bool(resource),
|
||||
runtime_enabled=runtime_enabled,
|
||||
egress_mode=egress_mode,
|
||||
skip_ssl_verify=bool(runtime.get("skip_ssl_verify")) if runtime_enabled else False,
|
||||
reset_session_status_codes=_status_codes_tuple(runtime.get("reset_session_status_codes")),
|
||||
clearance=clearance,
|
||||
)
|
||||
|
||||
def build_session_kwargs(
|
||||
self,
|
||||
account: dict | None = None,
|
||||
proxy: str = "",
|
||||
resource: bool = False,
|
||||
upstream: bool = False,
|
||||
**session_kwargs,
|
||||
) -> dict[str, object]:
|
||||
profile = self.get_profile(account=account, proxy=proxy, resource=resource, upstream=upstream)
|
||||
if profile.proxy_url:
|
||||
session_kwargs["proxy"] = profile.proxy_url
|
||||
if profile.runtime_enabled and profile.skip_ssl_verify:
|
||||
session_kwargs["verify"] = False
|
||||
return session_kwargs
|
||||
|
||||
def build_headers(
|
||||
self,
|
||||
headers: Mapping[str, object] | None = None,
|
||||
target_url: str = "https://chatgpt.com",
|
||||
account: dict | None = None,
|
||||
proxy: str = "",
|
||||
resource: bool = False,
|
||||
upstream: bool = True,
|
||||
) -> dict[str, object]:
|
||||
merged_headers: dict[str, object] = dict(headers or {})
|
||||
profile = self.get_profile(account=account, proxy=proxy, resource=resource, upstream=upstream)
|
||||
if not profile.clearance_enabled:
|
||||
return merged_headers
|
||||
|
||||
target_host = _host_from_url(target_url)
|
||||
bundle = self._bundle_for_headers(profile, target_host)
|
||||
if bundle is None or not bundle.is_valid_for(target_host, profile.proxy_url):
|
||||
return merged_headers
|
||||
|
||||
if bundle.user_agent and _find_header_key(merged_headers, "user-agent") is None:
|
||||
merged_headers["User-Agent"] = bundle.user_agent
|
||||
|
||||
if bundle.cookies:
|
||||
cookie_key = _find_header_key(merged_headers, "cookie") or "Cookie"
|
||||
existing_cookie = str(merged_headers.get(cookie_key) or "")
|
||||
cookie_header = _merge_cookie_header(existing_cookie, bundle.cookies)
|
||||
if cookie_header:
|
||||
merged_headers[cookie_key] = cookie_header
|
||||
return merged_headers
|
||||
|
||||
def refresh_clearance(
|
||||
self,
|
||||
target_url: str = "https://chatgpt.com",
|
||||
account: dict | None = None,
|
||||
proxy: str = "",
|
||||
resource: bool = False,
|
||||
force: bool = False,
|
||||
upstream: bool = True,
|
||||
) -> ClearanceBundle | None:
|
||||
profile = self.get_profile(account=account, proxy=proxy, resource=resource, upstream=upstream)
|
||||
if not profile.clearance_enabled:
|
||||
return None
|
||||
|
||||
target_host = _host_from_url(target_url)
|
||||
key = self._cache_key(profile.proxy_url, target_host)
|
||||
if profile.clearance_mode == "manual":
|
||||
bundle = self._build_manual_bundle(profile, target_host)
|
||||
if bundle is not None:
|
||||
self._set_cached_bundle(key, bundle)
|
||||
return bundle
|
||||
if profile.clearance_mode != "flaresolverr":
|
||||
return None
|
||||
|
||||
cached_before = self._get_cached_bundle(key)
|
||||
if cached_before is not None and not force and cached_before.is_valid_for(target_host, profile.proxy_url):
|
||||
return cached_before
|
||||
|
||||
lock = self._get_flight_lock(key)
|
||||
if not lock.acquire(blocking=False):
|
||||
with lock:
|
||||
pass
|
||||
return self._get_cached_bundle(key) or cached_before
|
||||
|
||||
try:
|
||||
cached_now = self._get_cached_bundle(key)
|
||||
if cached_now is not None and not force and cached_now.is_valid_for(target_host, profile.proxy_url):
|
||||
return cached_now
|
||||
|
||||
flaresolverr_url = str(profile.clearance.get("flaresolverr_url") or "").strip()
|
||||
provider = self._get_provider(flaresolverr_url)
|
||||
new_bundle = provider.get_clearance(target_url, proxy_url=profile.proxy_url, timeout_sec=profile.timeout_sec)
|
||||
if new_bundle is not None:
|
||||
expires_at = time.time() + profile.refresh_interval if profile.refresh_interval else None
|
||||
if (
|
||||
not new_bundle.target_host
|
||||
or normalize_proxy_url(new_bundle.proxy_url) != normalize_proxy_url(profile.proxy_url)
|
||||
or new_bundle.expires_at != expires_at
|
||||
):
|
||||
new_bundle = replace(
|
||||
new_bundle,
|
||||
target_host=new_bundle.target_host or target_host,
|
||||
proxy_url=profile.proxy_url,
|
||||
expires_at=expires_at,
|
||||
)
|
||||
self._set_cached_bundle(key, new_bundle)
|
||||
return new_bundle
|
||||
return cached_now or cached_before
|
||||
finally:
|
||||
lock.release()
|
||||
|
||||
def invalidate_clearance(
|
||||
self,
|
||||
target_url: str = "https://chatgpt.com",
|
||||
account: dict | None = None,
|
||||
proxy: str = "",
|
||||
resource: bool = False,
|
||||
upstream: bool = True,
|
||||
) -> None:
|
||||
profile = self.get_profile(account=account, proxy=proxy, resource=resource, upstream=upstream)
|
||||
target_host = _host_from_url(target_url)
|
||||
key = self._cache_key(profile.proxy_url, target_host)
|
||||
with self._lock:
|
||||
self._clearance_cache.pop(key, None)
|
||||
|
||||
def get_runtime_status(self) -> dict[str, object]:
|
||||
profile = self.get_profile(upstream=True)
|
||||
with self._lock:
|
||||
cached_hosts = [host for _proxy, host in self._clearance_cache]
|
||||
cached_count = len(self._clearance_cache)
|
||||
return {
|
||||
"enabled": profile.runtime_enabled,
|
||||
"egress_mode": profile.egress_mode,
|
||||
"proxy_source": profile.proxy_source,
|
||||
"has_proxy": bool(profile.proxy_url),
|
||||
"clearance_enabled": profile.clearance_enabled,
|
||||
"clearance_mode": profile.clearance_mode,
|
||||
"has_clearance_bundle": cached_count > 0,
|
||||
"cached_clearance_hosts": sorted(set(cached_hosts)),
|
||||
}
|
||||
|
||||
def _get_runtime_settings(self) -> dict[str, object]:
|
||||
try:
|
||||
runtime = self._config.get_proxy_runtime_settings()
|
||||
except AttributeError:
|
||||
runtime = {}
|
||||
return runtime if isinstance(runtime, dict) else {}
|
||||
|
||||
def _bundle_for_headers(self, profile: ProxyRuntimeProfile, target_host: str) -> ClearanceBundle | None:
|
||||
key = self._cache_key(profile.proxy_url, target_host)
|
||||
if profile.clearance_mode == "manual":
|
||||
bundle = self._build_manual_bundle(profile, target_host)
|
||||
if bundle is not None:
|
||||
self._set_cached_bundle(key, bundle)
|
||||
return bundle
|
||||
if profile.clearance_mode == "flaresolverr":
|
||||
return self._get_cached_bundle(key)
|
||||
return None
|
||||
|
||||
def _build_manual_bundle(self, profile: ProxyRuntimeProfile, target_host: str) -> ClearanceBundle | None:
|
||||
cookies = _parse_cookie_header(str(profile.clearance.get("cf_cookies") or ""))
|
||||
cf_clearance = str(profile.clearance.get("cf_clearance") or "").strip()
|
||||
if cf_clearance and "cf_clearance" not in cookies:
|
||||
cookies["cf_clearance"] = cf_clearance
|
||||
user_agent = str(profile.clearance.get("user_agent") or "").strip()
|
||||
if not cookies and not user_agent:
|
||||
return None
|
||||
|
||||
now = time.time()
|
||||
expires_at = now + profile.refresh_interval if profile.refresh_interval else None
|
||||
return ClearanceBundle(
|
||||
target_host=target_host,
|
||||
proxy_url=profile.proxy_url,
|
||||
cookies=cookies,
|
||||
user_agent=user_agent,
|
||||
created_at=now,
|
||||
expires_at=expires_at,
|
||||
)
|
||||
|
||||
def _get_provider(self, flaresolverr_url: str) -> FlareSolverrClearanceProvider:
|
||||
url = str(flaresolverr_url or "").strip().rstrip("/")
|
||||
with self._lock:
|
||||
provider = self._provider_cache.get(url)
|
||||
if provider is None:
|
||||
provider = self._clearance_provider_factory(url)
|
||||
self._provider_cache[url] = provider
|
||||
return provider
|
||||
|
||||
def _get_flight_lock(self, key: tuple[str, str]) -> threading.Lock:
|
||||
with self._lock:
|
||||
lock = self._flight_locks.get(key)
|
||||
if lock is None:
|
||||
lock = threading.Lock()
|
||||
self._flight_locks[key] = lock
|
||||
return lock
|
||||
|
||||
def _get_cached_bundle(self, key: tuple[str, str]) -> ClearanceBundle | None:
|
||||
with self._lock:
|
||||
return self._clearance_cache.get(key)
|
||||
|
||||
def _set_cached_bundle(self, key: tuple[str, str], bundle: ClearanceBundle) -> None:
|
||||
with self._lock:
|
||||
self._clearance_cache[key] = bundle
|
||||
|
||||
@staticmethod
|
||||
def _cache_key(proxy_url: str, target_host: str) -> tuple[str, str]:
|
||||
return (normalize_proxy_url(proxy_url), _normalize_host(target_host))
|
||||
|
||||
|
||||
def _clean(value: object) -> str:
|
||||
return str(value or "").strip()
|
||||
|
||||
|
||||
def _colon_proxy_to_url(url: str) -> str:
|
||||
parts = url.split(":", 3)
|
||||
if len(parts) == 4 and parts[1].isdigit():
|
||||
host, port, username, password = parts
|
||||
return f"http://{quote(username, safe='')}:{quote(password, safe='')}@{host}:{port}"
|
||||
if len(parts) == 2 and parts[1].isdigit():
|
||||
return f"http://{url}"
|
||||
return url
|
||||
|
||||
|
||||
def _normalize_host(host: str) -> str:
|
||||
return str(host or "").strip().strip(".").lower()
|
||||
|
||||
|
||||
def _host_from_url(url: str) -> str:
|
||||
candidate = str(url or "").strip()
|
||||
parsed = urlparse(candidate)
|
||||
if not parsed.hostname and candidate and "://" not in candidate:
|
||||
parsed = urlparse(f"https://{candidate}")
|
||||
return _normalize_host(parsed.hostname or "")
|
||||
|
||||
|
||||
def _status_codes_tuple(value: object) -> tuple[int, ...]:
|
||||
source = value if isinstance(value, list) else [403]
|
||||
codes: list[int] = []
|
||||
for item in source:
|
||||
if isinstance(item, bool):
|
||||
continue
|
||||
try:
|
||||
code = int(item)
|
||||
except (OverflowError, TypeError, ValueError):
|
||||
continue
|
||||
if 100 <= code <= 599 and code not in codes:
|
||||
codes.append(code)
|
||||
return tuple(codes or [403])
|
||||
|
||||
|
||||
def _coerce_timeout(value: object) -> float:
|
||||
try:
|
||||
timeout = float(value)
|
||||
except (OverflowError, TypeError, ValueError):
|
||||
timeout = 60.0
|
||||
return max(1.0, timeout)
|
||||
|
||||
|
||||
def _is_valid_proxy_url(url: str) -> bool:
|
||||
parsed = urlparse(normalize_proxy_url(url))
|
||||
return parsed.scheme in {"http", "https", "socks5", "socks5h"} and bool(parsed.netloc)
|
||||
|
||||
|
||||
def _domain_matches(host: str, domain: str) -> bool:
|
||||
normalized_host = _normalize_host(host)
|
||||
normalized_domain = _normalize_host(domain.lstrip("."))
|
||||
if not normalized_domain:
|
||||
return True
|
||||
return normalized_host == normalized_domain or normalized_host.endswith(f".{normalized_domain}")
|
||||
|
||||
|
||||
def _filter_flaresolverr_cookies(raw_cookies: object, target_host: str) -> dict[str, str]:
|
||||
if not isinstance(raw_cookies, list):
|
||||
return {}
|
||||
|
||||
filtered_cookies: dict[str, str] = {}
|
||||
for item in raw_cookies:
|
||||
if not isinstance(item, dict):
|
||||
continue
|
||||
name = str(item.get("name") or "").strip()
|
||||
if not name:
|
||||
continue
|
||||
value = str(item.get("value") or "")
|
||||
domain = str(item.get("domain") or "").strip()
|
||||
if not domain or _domain_matches(target_host, domain):
|
||||
filtered_cookies[name] = value
|
||||
return filtered_cookies
|
||||
|
||||
|
||||
def _parse_cookie_header(header: str) -> dict[str, str]:
|
||||
cookies: dict[str, str] = {}
|
||||
for part in str(header or "").split(";"):
|
||||
name, sep, value = part.strip().partition("=")
|
||||
if sep and name:
|
||||
cookies[name.strip()] = value.strip()
|
||||
return cookies
|
||||
|
||||
|
||||
def _cookies_to_header(cookies: Mapping[str, str]) -> str:
|
||||
return "; ".join(f"{name}={value}" for name, value in cookies.items() if name)
|
||||
|
||||
|
||||
def _merge_cookie_header(existing_header: str, cookies: Mapping[str, str]) -> str:
|
||||
existing = str(existing_header or "").strip()
|
||||
existing_names = set(_parse_cookie_header(existing).keys())
|
||||
additions = [f"{name}={value}" for name, value in cookies.items() if name and name not in existing_names]
|
||||
if existing and additions:
|
||||
return existing.rstrip("; ") + "; " + "; ".join(additions)
|
||||
if existing:
|
||||
return existing
|
||||
return "; ".join(additions)
|
||||
|
||||
|
||||
def _find_header_key(headers: Mapping[str, object], name: str) -> str | None:
|
||||
target = name.lower()
|
||||
for key in headers:
|
||||
if str(key).lower() == target:
|
||||
return str(key)
|
||||
return None
|
||||
|
||||
|
||||
def _redact_url_credentials(text: str) -> str:
|
||||
return re.sub(
|
||||
r"((?:https?|socks5h?|socks)://)([^\s/@:]+):([^\s/@]+)@",
|
||||
r"\1[REDACTED]@",
|
||||
str(text or ""),
|
||||
flags=re.IGNORECASE,
|
||||
)
|
||||
|
||||
|
||||
def test_proxy(url: str = "", *, timeout: float = 15.0) -> dict:
|
||||
candidate = normalize_proxy_url(_clean(url))
|
||||
proxy_source = "input"
|
||||
if not candidate:
|
||||
profile = proxy_settings.get_profile(upstream=True)
|
||||
candidate = profile.proxy_url
|
||||
proxy_source = profile.proxy_source
|
||||
result_base = {"proxy_source": proxy_source, "has_proxy": bool(candidate)}
|
||||
if not candidate:
|
||||
return {
|
||||
"ok": False,
|
||||
"status": 0,
|
||||
"latency_ms": 0,
|
||||
"error": "no active proxy configured",
|
||||
**result_base,
|
||||
}
|
||||
if not _is_valid_proxy_url(candidate):
|
||||
return {
|
||||
"ok": False,
|
||||
"status": 0,
|
||||
"latency_ms": 0,
|
||||
"error": "invalid proxy url",
|
||||
**result_base,
|
||||
}
|
||||
session = Session(impersonate="edge101", verify=True, proxy=candidate)
|
||||
started = time.perf_counter()
|
||||
try:
|
||||
response = session.get(
|
||||
"https://chatgpt.com/api/auth/csrf",
|
||||
headers={"user-agent": "Mozilla/5.0 (chatgpt2api proxy test)"},
|
||||
timeout=timeout,
|
||||
)
|
||||
latency_ms = int((time.perf_counter() - started) * 1000)
|
||||
return {
|
||||
"ok": response.status_code < 500,
|
||||
"status": int(response.status_code),
|
||||
"latency_ms": latency_ms,
|
||||
"error": None if response.status_code < 500 else f"HTTP {response.status_code}",
|
||||
**result_base,
|
||||
}
|
||||
except Exception as exc:
|
||||
latency_ms = int((time.perf_counter() - started) * 1000)
|
||||
return {
|
||||
"ok": False,
|
||||
"status": 0,
|
||||
"latency_ms": latency_ms,
|
||||
"error": _redact_url_credentials(str(exc) or exc.__class__.__name__),
|
||||
**result_base,
|
||||
}
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
|
||||
def test_clearance(target_url: str = "https://chatgpt.com") -> dict:
|
||||
target_url = str(target_url or "https://chatgpt.com").strip() or "https://chatgpt.com"
|
||||
started = time.perf_counter()
|
||||
status = proxy_settings.get_runtime_status()
|
||||
if not status.get("clearance_enabled"):
|
||||
return {
|
||||
"ok": False,
|
||||
"status": "disabled",
|
||||
"latency_ms": 0,
|
||||
"has_cookies": False,
|
||||
"user_agent": "",
|
||||
"error": "clearance is disabled",
|
||||
"runtime": status,
|
||||
}
|
||||
try:
|
||||
bundle = proxy_settings.refresh_clearance(target_url=target_url, force=True, upstream=True)
|
||||
except Exception as exc:
|
||||
latency_ms = int((time.perf_counter() - started) * 1000)
|
||||
return {
|
||||
"ok": False,
|
||||
"status": "error",
|
||||
"latency_ms": latency_ms,
|
||||
"has_cookies": False,
|
||||
"user_agent": "",
|
||||
"error": _redact_url_credentials(str(exc) or exc.__class__.__name__),
|
||||
"runtime": proxy_settings.get_runtime_status(),
|
||||
}
|
||||
|
||||
latency_ms = int((time.perf_counter() - started) * 1000)
|
||||
runtime = proxy_settings.get_runtime_status()
|
||||
if bundle is None:
|
||||
return {
|
||||
"ok": False,
|
||||
"status": "failed",
|
||||
"latency_ms": latency_ms,
|
||||
"has_cookies": False,
|
||||
"user_agent": "",
|
||||
"error": "clearance refresh returned no bundle",
|
||||
"runtime": runtime,
|
||||
}
|
||||
return {
|
||||
"ok": True,
|
||||
"status": "ok",
|
||||
"latency_ms": latency_ms,
|
||||
"has_cookies": bool(bundle.cookies),
|
||||
"user_agent": bundle.user_agent or "",
|
||||
"error": None,
|
||||
"runtime": runtime,
|
||||
}
|
||||
|
||||
|
||||
proxy_settings = ProxySettingsStore()
|
||||
@@ -0,0 +1,5 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from services.storage.factory import create_storage_backend
|
||||
|
||||
__all__ = ["create_storage_backend"]
|
||||
@@ -0,0 +1,38 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from abc import ABC, abstractmethod
|
||||
from typing import Any
|
||||
|
||||
|
||||
class StorageBackend(ABC):
|
||||
"""抽象存储后端基类"""
|
||||
|
||||
@abstractmethod
|
||||
def load_accounts(self) -> list[dict[str, Any]]:
|
||||
"""加载所有账号数据"""
|
||||
pass
|
||||
|
||||
@abstractmethod
|
||||
def save_accounts(self, accounts: list[dict[str, Any]]) -> None:
|
||||
"""保存所有账号数据"""
|
||||
pass
|
||||
|
||||
@abstractmethod
|
||||
def load_auth_keys(self) -> list[dict[str, Any]]:
|
||||
"""加载所有鉴权密钥数据"""
|
||||
pass
|
||||
|
||||
@abstractmethod
|
||||
def save_auth_keys(self, auth_keys: list[dict[str, Any]]) -> None:
|
||||
"""保存所有鉴权密钥数据"""
|
||||
pass
|
||||
|
||||
@abstractmethod
|
||||
def health_check(self) -> dict[str, Any]:
|
||||
"""健康检查,返回存储后端状态"""
|
||||
pass
|
||||
|
||||
@abstractmethod
|
||||
def get_backend_info(self) -> dict[str, Any]:
|
||||
"""获取存储后端信息"""
|
||||
pass
|
||||
@@ -0,0 +1,194 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
from typing import Any
|
||||
|
||||
from sqlalchemy import Column, String, Text, create_engine, Integer, text
|
||||
from sqlalchemy.ext.declarative import declarative_base
|
||||
from sqlalchemy.orm import sessionmaker
|
||||
|
||||
from services.storage.base import StorageBackend
|
||||
|
||||
Base = declarative_base()
|
||||
|
||||
|
||||
class AccountModel(Base):
|
||||
"""账号数据模型"""
|
||||
__tablename__ = "accounts"
|
||||
|
||||
id = Column(Integer, primary_key=True, autoincrement=True)
|
||||
access_token = Column(String(2048), unique=True, nullable=False, index=True)
|
||||
data = Column(Text, nullable=False) # JSON 格式存储完整账号数据
|
||||
|
||||
|
||||
class AuthKeyModel(Base):
|
||||
"""鉴权密钥数据模型"""
|
||||
__tablename__ = "auth_keys"
|
||||
|
||||
id = Column(Integer, primary_key=True, autoincrement=True)
|
||||
key_id = Column(String(255), unique=True, nullable=False, index=True)
|
||||
data = Column(Text, nullable=False)
|
||||
|
||||
|
||||
class DatabaseStorageBackend(StorageBackend):
|
||||
"""数据库存储后端(支持 SQLite、PostgreSQL、MySQL 等)"""
|
||||
|
||||
def __init__(self, database_url: str):
|
||||
self.database_url = database_url
|
||||
self.engine = create_engine(
|
||||
database_url,
|
||||
pool_pre_ping=True, # 自动检测连接是否有效
|
||||
pool_recycle=3600, # 1小时回收连接
|
||||
)
|
||||
Base.metadata.create_all(self.engine)
|
||||
self.Session = sessionmaker(bind=self.engine)
|
||||
|
||||
def load_accounts(self) -> list[dict[str, Any]]:
|
||||
"""从数据库加载账号数据"""
|
||||
session = self.Session()
|
||||
try:
|
||||
accounts = []
|
||||
for row in session.query(AccountModel).all():
|
||||
try:
|
||||
account_data = json.loads(row.data)
|
||||
if isinstance(account_data, dict):
|
||||
accounts.append(account_data)
|
||||
except json.JSONDecodeError:
|
||||
continue
|
||||
return accounts
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
def save_accounts(self, accounts: list[dict[str, Any]]) -> None:
|
||||
"""保存账号数据到数据库"""
|
||||
self._save_rows(AccountModel, accounts, "access_token")
|
||||
|
||||
def load_auth_keys(self) -> list[dict[str, Any]]:
|
||||
"""从数据库加载鉴权密钥数据"""
|
||||
return self._load_rows(AuthKeyModel)
|
||||
|
||||
def save_auth_keys(self, auth_keys: list[dict[str, Any]]) -> None:
|
||||
"""保存鉴权密钥数据到数据库"""
|
||||
self._save_rows(AuthKeyModel, auth_keys, "id", "key_id")
|
||||
|
||||
def _load_rows(self, model: type[AccountModel] | type[AuthKeyModel]) -> list[dict[str, Any]]:
|
||||
session = self.Session()
|
||||
try:
|
||||
items = []
|
||||
for row in session.query(model).all():
|
||||
try:
|
||||
item_data = json.loads(row.data)
|
||||
if isinstance(item_data, dict):
|
||||
items.append(item_data)
|
||||
except json.JSONDecodeError:
|
||||
continue
|
||||
return items
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
def _save_rows(
|
||||
self,
|
||||
model: type[AccountModel] | type[AuthKeyModel],
|
||||
items: list[dict[str, Any]],
|
||||
source_key: str,
|
||||
target_key: str | None = None,
|
||||
) -> None:
|
||||
session = self.Session()
|
||||
try:
|
||||
key_column = target_key or source_key
|
||||
existing_rows = {
|
||||
str(getattr(row, key_column)): row
|
||||
for row in session.query(model).all()
|
||||
}
|
||||
incoming_keys: set[str] = set()
|
||||
|
||||
for item in items:
|
||||
if not isinstance(item, dict):
|
||||
continue
|
||||
key_value = str(item.get(source_key) or "").strip()
|
||||
if not key_value:
|
||||
continue
|
||||
if key_value in incoming_keys:
|
||||
raise ValueError(f"Duplicate {source_key} in storage snapshot")
|
||||
|
||||
incoming_keys.add(key_value)
|
||||
serialized_data = json.dumps(item, ensure_ascii=False)
|
||||
existing_row = existing_rows.get(key_value)
|
||||
if existing_row is None:
|
||||
session.add(
|
||||
model(
|
||||
**{key_column: key_value},
|
||||
data=serialized_data,
|
||||
)
|
||||
)
|
||||
elif existing_row.data != serialized_data:
|
||||
existing_row.data = serialized_data
|
||||
|
||||
for key_value, row in existing_rows.items():
|
||||
if key_value not in incoming_keys:
|
||||
session.delete(row)
|
||||
|
||||
session.commit()
|
||||
except Exception:
|
||||
session.rollback()
|
||||
raise
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
def health_check(self) -> dict[str, Any]:
|
||||
"""健康检查"""
|
||||
try:
|
||||
session = self.Session()
|
||||
try:
|
||||
# 尝试执行简单查询
|
||||
session.execute(text("SELECT 1"))
|
||||
count = session.query(AccountModel).count()
|
||||
auth_key_count = session.query(AuthKeyModel).count()
|
||||
return {
|
||||
"status": "healthy",
|
||||
"backend": "database",
|
||||
"database_url": self._mask_password(self.database_url),
|
||||
"account_count": count,
|
||||
"auth_key_count": auth_key_count,
|
||||
}
|
||||
finally:
|
||||
session.close()
|
||||
except Exception as e:
|
||||
return {
|
||||
"status": "unhealthy",
|
||||
"backend": "database",
|
||||
"error": str(e),
|
||||
}
|
||||
|
||||
def get_backend_info(self) -> dict[str, Any]:
|
||||
"""获取存储后端信息"""
|
||||
db_type = "unknown"
|
||||
if "sqlite" in self.database_url:
|
||||
db_type = "sqlite"
|
||||
elif "postgresql" in self.database_url or "postgres" in self.database_url:
|
||||
db_type = "postgresql"
|
||||
elif "mysql" in self.database_url:
|
||||
db_type = "mysql"
|
||||
|
||||
return {
|
||||
"type": "database",
|
||||
"db_type": db_type,
|
||||
"description": f"数据库存储 ({db_type})",
|
||||
"database_url": self._mask_password(self.database_url),
|
||||
}
|
||||
|
||||
@staticmethod
|
||||
def _mask_password(url: str) -> str:
|
||||
"""隐藏数据库连接字符串中的密码"""
|
||||
if "://" not in url:
|
||||
return url
|
||||
try:
|
||||
protocol, rest = url.split("://", 1)
|
||||
if "@" in rest:
|
||||
credentials, host = rest.split("@", 1)
|
||||
if ":" in credentials:
|
||||
username, _ = credentials.split(":", 1)
|
||||
return f"{protocol}://{username}:****@{host}"
|
||||
return url
|
||||
except Exception:
|
||||
return url
|
||||
@@ -0,0 +1,104 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from pathlib import Path
|
||||
|
||||
from services.storage.base import StorageBackend
|
||||
from services.storage.database_storage import DatabaseStorageBackend
|
||||
from services.storage.git_storage import GitStorageBackend
|
||||
from services.storage.json_storage import JSONStorageBackend
|
||||
|
||||
|
||||
def create_storage_backend(data_dir: Path) -> StorageBackend:
|
||||
"""
|
||||
根据环境变量创建存储后端
|
||||
|
||||
环境变量:
|
||||
- STORAGE_BACKEND: json|sqlite|postgres|git (默认 json)
|
||||
- DATABASE_URL: 数据库连接字符串 (用于 sqlite/postgres)
|
||||
- GIT_REPO_URL: Git 仓库地址 (用于 git)
|
||||
- GIT_TOKEN: Git 访问令牌 (用于 git)
|
||||
- GIT_BRANCH: Git 分支 (默认 main)
|
||||
- GIT_FILE_PATH: Git 仓库中的文件路径 (默认 accounts.json)
|
||||
"""
|
||||
backend_type = os.getenv("STORAGE_BACKEND", "json").lower().strip()
|
||||
|
||||
print(f"[storage] Initializing storage backend: {backend_type}")
|
||||
|
||||
if backend_type == "json":
|
||||
# 本地 JSON 文件存储
|
||||
file_path = data_dir / "accounts.json"
|
||||
auth_keys_path = data_dir / "auth_keys.json"
|
||||
print(f"[storage] Using JSON storage: {file_path}")
|
||||
return JSONStorageBackend(file_path, auth_keys_path)
|
||||
|
||||
elif backend_type in ("sqlite", "postgres", "postgresql", "mysql", "database"):
|
||||
# 数据库存储
|
||||
database_url = os.getenv("DATABASE_URL", "").strip()
|
||||
|
||||
if not database_url:
|
||||
# 如果没有指定 DATABASE_URL,使用本地 SQLite
|
||||
database_url = f"sqlite:///{data_dir / 'accounts.db'}"
|
||||
print(f"[storage] No DATABASE_URL provided, using local SQLite: {database_url}")
|
||||
else:
|
||||
print(f"[storage] Using database storage: {_mask_password(database_url)}")
|
||||
|
||||
return DatabaseStorageBackend(database_url)
|
||||
|
||||
elif backend_type == "git":
|
||||
# Git 仓库存储
|
||||
repo_url = os.getenv("GIT_REPO_URL", "").strip()
|
||||
token = os.getenv("GIT_TOKEN", "").strip()
|
||||
branch = os.getenv("GIT_BRANCH", "main").strip()
|
||||
file_path = os.getenv("GIT_FILE_PATH", "accounts.json").strip()
|
||||
auth_keys_file_path = os.getenv("GIT_AUTH_KEYS_FILE_PATH", "auth_keys.json").strip()
|
||||
|
||||
if not repo_url:
|
||||
raise ValueError(
|
||||
"GIT_REPO_URL is required when using git storage backend. "
|
||||
"Please set GIT_REPO_URL environment variable."
|
||||
)
|
||||
|
||||
print(f"[storage] Using Git storage: {_mask_token(repo_url)}, branch: {branch}, file: {file_path}")
|
||||
|
||||
cache_dir = data_dir / "git_cache"
|
||||
return GitStorageBackend(
|
||||
repo_url=repo_url,
|
||||
token=token,
|
||||
branch=branch,
|
||||
file_path=file_path,
|
||||
auth_keys_file_path=auth_keys_file_path,
|
||||
local_cache_dir=cache_dir,
|
||||
)
|
||||
|
||||
else:
|
||||
raise ValueError(
|
||||
f"Unknown storage backend: {backend_type}. "
|
||||
f"Supported backends: json, sqlite, postgres, git"
|
||||
)
|
||||
|
||||
|
||||
def _mask_password(url: str) -> str:
|
||||
"""隐藏数据库连接字符串中的密码"""
|
||||
if "://" not in url:
|
||||
return url
|
||||
try:
|
||||
protocol, rest = url.split("://", 1)
|
||||
if "@" in rest:
|
||||
credentials, host = rest.split("@", 1)
|
||||
if ":" in credentials:
|
||||
username, _ = credentials.split(":", 1)
|
||||
return f"{protocol}://{username}:****@{host}"
|
||||
return url
|
||||
except Exception:
|
||||
return url
|
||||
|
||||
|
||||
def _mask_token(url: str) -> str:
|
||||
"""隐藏 URL 中的 token"""
|
||||
if "@" in url and "://" in url:
|
||||
protocol, rest = url.split("://", 1)
|
||||
if "@" in rest:
|
||||
_, host = rest.split("@", 1)
|
||||
return f"{protocol}://****@{host}"
|
||||
return url
|
||||
@@ -0,0 +1,183 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import shutil
|
||||
import tempfile
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
from git import Repo
|
||||
from git.exc import GitCommandError
|
||||
|
||||
from services.storage.base import StorageBackend
|
||||
|
||||
|
||||
class GitStorageBackend(StorageBackend):
|
||||
"""Git 私有仓库存储后端"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
repo_url: str,
|
||||
token: str,
|
||||
branch: str = "main",
|
||||
file_path: str = "accounts.json",
|
||||
auth_keys_file_path: str = "auth_keys.json",
|
||||
local_cache_dir: Path | None = None,
|
||||
):
|
||||
self.repo_url = repo_url
|
||||
self.token = token
|
||||
self.branch = branch
|
||||
self.file_path = file_path
|
||||
self.auth_keys_file_path = auth_keys_file_path
|
||||
|
||||
# 本地缓存目录
|
||||
if local_cache_dir is None:
|
||||
local_cache_dir = Path(tempfile.gettempdir()) / "chatgpt2api_git_cache"
|
||||
self.local_cache_dir = local_cache_dir
|
||||
self.local_cache_dir.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
# 构建带认证的 Git URL
|
||||
self.auth_repo_url = self._build_auth_url(repo_url, token)
|
||||
|
||||
@staticmethod
|
||||
def _build_auth_url(repo_url: str, token: str) -> str:
|
||||
"""构建带认证的 Git URL"""
|
||||
if not token:
|
||||
return repo_url
|
||||
|
||||
# 支持 HTTPS 格式:https://github.com/user/repo.git
|
||||
if repo_url.startswith("https://"):
|
||||
# 插入 token
|
||||
return repo_url.replace("https://", f"https://{token}@")
|
||||
|
||||
# 支持 git@ 格式:git@github.com:user/repo.git
|
||||
# 转换为 HTTPS 格式
|
||||
if repo_url.startswith("git@"):
|
||||
repo_url = repo_url.replace("git@", "https://")
|
||||
repo_url = repo_url.replace(".com:", ".com/")
|
||||
return repo_url.replace("https://", f"https://{token}@")
|
||||
|
||||
return repo_url
|
||||
|
||||
def _clone_or_pull(self) -> Repo:
|
||||
"""克隆或拉取仓库"""
|
||||
repo_path = self.local_cache_dir / "repo"
|
||||
|
||||
if repo_path.exists() and (repo_path / ".git").exists():
|
||||
# 仓库已存在,拉取最新代码
|
||||
try:
|
||||
repo = Repo(repo_path)
|
||||
origin = repo.remote("origin")
|
||||
origin.pull(self.branch)
|
||||
return repo
|
||||
except GitCommandError:
|
||||
# 拉取失败,删除重新克隆
|
||||
shutil.rmtree(repo_path)
|
||||
|
||||
# 克隆仓库
|
||||
repo = Repo.clone_from(
|
||||
self.auth_repo_url,
|
||||
repo_path,
|
||||
branch=self.branch,
|
||||
)
|
||||
return repo
|
||||
|
||||
def load_accounts(self) -> list[dict[str, Any]]:
|
||||
"""从 Git 仓库加载账号数据"""
|
||||
try:
|
||||
return self._load_json_file(self.file_path)
|
||||
except Exception as e:
|
||||
print(f"[git-storage] load failed: {e}")
|
||||
raise
|
||||
|
||||
def save_accounts(self, accounts: list[dict[str, Any]]) -> None:
|
||||
"""保存账号数据到 Git 仓库"""
|
||||
try:
|
||||
self._save_json_file(self.file_path, accounts, "Update accounts data")
|
||||
except Exception as e:
|
||||
print(f"[git-storage] save failed: {e}")
|
||||
raise e
|
||||
|
||||
def load_auth_keys(self) -> list[dict[str, Any]]:
|
||||
"""从 Git 仓库加载鉴权密钥数据"""
|
||||
try:
|
||||
data = self._load_json_value(self.auth_keys_file_path)
|
||||
if isinstance(data, dict):
|
||||
data = data.get("items")
|
||||
return data if isinstance(data, list) else []
|
||||
except Exception as e:
|
||||
print(f"[git-storage] load failed: {e}")
|
||||
raise
|
||||
|
||||
def save_auth_keys(self, auth_keys: list[dict[str, Any]]) -> None:
|
||||
"""保存鉴权密钥数据到 Git 仓库"""
|
||||
try:
|
||||
self._save_json_file(self.auth_keys_file_path, {"items": auth_keys}, "Update auth keys data")
|
||||
except Exception as e:
|
||||
print(f"[git-storage] save failed: {e}")
|
||||
raise e
|
||||
|
||||
def _load_json_file(self, file_path: str) -> list[dict[str, Any]]:
|
||||
data = self._load_json_value(file_path)
|
||||
return data if isinstance(data, list) else []
|
||||
|
||||
def _load_json_value(self, file_path: str) -> Any:
|
||||
repo = self._clone_or_pull()
|
||||
file_full_path = Path(repo.working_dir) / file_path
|
||||
if not file_full_path.exists():
|
||||
return None
|
||||
return json.loads(file_full_path.read_text(encoding="utf-8"))
|
||||
|
||||
def _save_json_file(self, file_path: str, items: Any, message: str) -> None:
|
||||
repo = self._clone_or_pull()
|
||||
file_full_path = Path(repo.working_dir) / file_path
|
||||
file_full_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
file_full_path.write_text(
|
||||
json.dumps(items, ensure_ascii=False, indent=2) + "\n",
|
||||
encoding="utf-8",
|
||||
)
|
||||
repo.index.add([file_path])
|
||||
if repo.is_dirty():
|
||||
repo.index.commit(message)
|
||||
repo.remote("origin").push(self.branch)
|
||||
|
||||
def health_check(self) -> dict[str, Any]:
|
||||
"""健康检查"""
|
||||
try:
|
||||
repo = self._clone_or_pull()
|
||||
return {
|
||||
"status": "healthy",
|
||||
"backend": "git",
|
||||
"repo_url": self._mask_token(self.repo_url),
|
||||
"branch": self.branch,
|
||||
"file_path": self.file_path,
|
||||
"auth_keys_file_path": self.auth_keys_file_path,
|
||||
"last_commit": repo.head.commit.hexsha[:8],
|
||||
}
|
||||
except Exception as e:
|
||||
return {
|
||||
"status": "unhealthy",
|
||||
"backend": "git",
|
||||
"error": str(e),
|
||||
}
|
||||
|
||||
def get_backend_info(self) -> dict[str, Any]:
|
||||
"""获取存储后端信息"""
|
||||
return {
|
||||
"type": "git",
|
||||
"description": "Git 私有仓库存储",
|
||||
"repo_url": self._mask_token(self.repo_url),
|
||||
"branch": self.branch,
|
||||
"file_path": self.file_path,
|
||||
"auth_keys_file_path": self.auth_keys_file_path,
|
||||
}
|
||||
|
||||
@staticmethod
|
||||
def _mask_token(url: str) -> str:
|
||||
"""隐藏 URL 中的 token"""
|
||||
if "@" in url and "://" in url:
|
||||
protocol, rest = url.split("://", 1)
|
||||
if "@" in rest:
|
||||
_, host = rest.split("@", 1)
|
||||
return f"{protocol}://****@{host}"
|
||||
return url
|
||||
@@ -0,0 +1,95 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
from services.storage.base import StorageBackend
|
||||
|
||||
|
||||
class JSONStorageBackend(StorageBackend):
|
||||
"""本地 JSON 文件存储后端"""
|
||||
|
||||
def __init__(self, file_path: Path, auth_keys_path: Path | None = None):
|
||||
self.file_path = file_path
|
||||
self.auth_keys_path = auth_keys_path or file_path.with_name("auth_keys.json")
|
||||
self.file_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
self.auth_keys_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
@staticmethod
|
||||
def _load_json_list(file_path: Path) -> list[dict[str, Any]]:
|
||||
if not file_path.exists():
|
||||
return []
|
||||
try:
|
||||
data = json.loads(file_path.read_text(encoding="utf-8"))
|
||||
return data if isinstance(data, list) else []
|
||||
except (json.JSONDecodeError, Exception):
|
||||
return []
|
||||
|
||||
@staticmethod
|
||||
def _save_json_list(file_path: Path, items: list[dict[str, Any]]) -> None:
|
||||
file_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
file_path.write_text(
|
||||
json.dumps(items, ensure_ascii=False, indent=2) + "\n",
|
||||
encoding="utf-8",
|
||||
)
|
||||
|
||||
def load_accounts(self) -> list[dict[str, Any]]:
|
||||
"""从 JSON 文件加载账号数据"""
|
||||
return self._load_json_list(self.file_path)
|
||||
|
||||
def save_accounts(self, accounts: list[dict[str, Any]]) -> None:
|
||||
"""保存账号数据到 JSON 文件"""
|
||||
self._save_json_list(self.file_path, accounts)
|
||||
|
||||
def load_auth_keys(self) -> list[dict[str, Any]]:
|
||||
"""从 JSON 文件加载鉴权密钥数据"""
|
||||
if not self.auth_keys_path.exists():
|
||||
return []
|
||||
try:
|
||||
data = json.loads(self.auth_keys_path.read_text(encoding="utf-8"))
|
||||
except (json.JSONDecodeError, Exception):
|
||||
return []
|
||||
if isinstance(data, dict):
|
||||
data = data.get("items")
|
||||
return data if isinstance(data, list) else []
|
||||
|
||||
def save_auth_keys(self, auth_keys: list[dict[str, Any]]) -> None:
|
||||
"""保存鉴权密钥数据到 JSON 文件"""
|
||||
self.auth_keys_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
self.auth_keys_path.write_text(
|
||||
json.dumps({"items": auth_keys}, ensure_ascii=False, indent=2) + "\n",
|
||||
encoding="utf-8",
|
||||
)
|
||||
|
||||
def health_check(self) -> dict[str, Any]:
|
||||
"""健康检查"""
|
||||
try:
|
||||
# 检查文件是否可读写
|
||||
if self.file_path.exists():
|
||||
self.file_path.read_text(encoding="utf-8")
|
||||
return {
|
||||
"status": "healthy",
|
||||
"backend": "json",
|
||||
"file_exists": self.file_path.exists(),
|
||||
"file_path": str(self.file_path),
|
||||
"auth_keys_file_exists": self.auth_keys_path.exists(),
|
||||
"auth_keys_file_path": str(self.auth_keys_path),
|
||||
}
|
||||
except Exception as e:
|
||||
return {
|
||||
"status": "unhealthy",
|
||||
"backend": "json",
|
||||
"error": str(e),
|
||||
}
|
||||
|
||||
def get_backend_info(self) -> dict[str, Any]:
|
||||
"""获取存储后端信息"""
|
||||
return {
|
||||
"type": "json",
|
||||
"description": "本地 JSON 文件存储",
|
||||
"file_path": str(self.file_path),
|
||||
"file_exists": self.file_path.exists(),
|
||||
"auth_keys_file_path": str(self.auth_keys_path),
|
||||
"auth_keys_file_exists": self.auth_keys_path.exists(),
|
||||
}
|
||||
@@ -0,0 +1,531 @@
|
||||
"""Sub2API integration for browsing and importing ChatGPT OAuth accounts from a sub2api admin."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import threading
|
||||
import time
|
||||
import uuid
|
||||
from datetime import datetime, timezone
|
||||
from pathlib import Path
|
||||
from threading import Lock
|
||||
|
||||
from curl_cffi.requests import Session
|
||||
|
||||
from services.account_service import account_service
|
||||
from services.config import DATA_DIR
|
||||
|
||||
|
||||
SUB2API_CONFIG_FILE = DATA_DIR / "sub2api_config.json"
|
||||
|
||||
# Cached JWT per server to avoid re-login on every list/import call.
|
||||
# Token lifetime on sub2api defaults to 24h; we refresh 5 min before expiry.
|
||||
_TOKEN_REFRESH_SKEW = 5 * 60
|
||||
|
||||
|
||||
def _new_id() -> str:
|
||||
return uuid.uuid4().hex[:12]
|
||||
|
||||
|
||||
def _now_iso() -> str:
|
||||
return datetime.now(timezone.utc).isoformat()
|
||||
|
||||
|
||||
def _clean(value: object) -> str:
|
||||
return str(value or "").strip()
|
||||
|
||||
|
||||
def _normalize_import_job(raw: object, *, fail_unfinished: bool) -> dict | None:
|
||||
if not isinstance(raw, dict):
|
||||
return None
|
||||
status = _clean(raw.get("status")) or "failed"
|
||||
if fail_unfinished and status in {"pending", "running"}:
|
||||
status = "failed"
|
||||
return {
|
||||
"job_id": _clean(raw.get("job_id")) or uuid.uuid4().hex,
|
||||
"status": status,
|
||||
"created_at": _clean(raw.get("created_at")) or _now_iso(),
|
||||
"updated_at": _clean(raw.get("updated_at")) or _clean(raw.get("created_at")) or _now_iso(),
|
||||
"total": int(raw.get("total") or 0),
|
||||
"completed": int(raw.get("completed") or 0),
|
||||
"added": int(raw.get("added") or 0),
|
||||
"skipped": int(raw.get("skipped") or 0),
|
||||
"refreshed": int(raw.get("refreshed") or 0),
|
||||
"failed": int(raw.get("failed") or 0),
|
||||
"errors": raw.get("errors") if isinstance(raw.get("errors"), list) else [],
|
||||
}
|
||||
|
||||
|
||||
def _normalize_server(raw: dict) -> dict:
|
||||
return {
|
||||
"id": _clean(raw.get("id")) or _new_id(),
|
||||
"name": _clean(raw.get("name")),
|
||||
"base_url": _clean(raw.get("base_url")),
|
||||
"email": _clean(raw.get("email")),
|
||||
"password": _clean(raw.get("password")),
|
||||
"api_key": _clean(raw.get("api_key")),
|
||||
"group_id": _clean(raw.get("group_id")),
|
||||
"import_job": _normalize_import_job(raw.get("import_job"), fail_unfinished=True),
|
||||
}
|
||||
|
||||
|
||||
class Sub2APIConfig:
|
||||
def __init__(self, store_file: Path):
|
||||
self._store_file = store_file
|
||||
self._lock = Lock()
|
||||
self._servers: list[dict] = self._load()
|
||||
|
||||
def _load(self) -> list[dict]:
|
||||
if not self._store_file.exists():
|
||||
return []
|
||||
try:
|
||||
raw = json.loads(self._store_file.read_text(encoding="utf-8"))
|
||||
if isinstance(raw, list):
|
||||
return [_normalize_server(item) for item in raw if isinstance(item, dict)]
|
||||
except Exception:
|
||||
pass
|
||||
return []
|
||||
|
||||
def _save(self) -> None:
|
||||
self._store_file.parent.mkdir(parents=True, exist_ok=True)
|
||||
self._store_file.write_text(
|
||||
json.dumps(self._servers, ensure_ascii=False, indent=2) + "\n",
|
||||
encoding="utf-8",
|
||||
)
|
||||
|
||||
def list_servers(self) -> list[dict]:
|
||||
with self._lock:
|
||||
return [dict(server) for server in self._servers]
|
||||
|
||||
def get_server(self, server_id: str) -> dict | None:
|
||||
with self._lock:
|
||||
for server in self._servers:
|
||||
if server["id"] == server_id:
|
||||
return dict(server)
|
||||
return None
|
||||
|
||||
def add_server(
|
||||
self,
|
||||
*,
|
||||
name: str,
|
||||
base_url: str,
|
||||
email: str,
|
||||
password: str,
|
||||
api_key: str,
|
||||
group_id: str = "",
|
||||
) -> dict:
|
||||
server = _normalize_server({
|
||||
"id": _new_id(),
|
||||
"name": name,
|
||||
"base_url": base_url,
|
||||
"email": email,
|
||||
"password": password,
|
||||
"api_key": api_key,
|
||||
"group_id": group_id,
|
||||
})
|
||||
with self._lock:
|
||||
self._servers.append(server)
|
||||
self._save()
|
||||
_token_cache.pop(server["id"], None)
|
||||
return dict(server)
|
||||
|
||||
def update_server(self, server_id: str, updates: dict) -> dict | None:
|
||||
with self._lock:
|
||||
for index, server in enumerate(self._servers):
|
||||
if server["id"] != server_id:
|
||||
continue
|
||||
merged = {**server, **{k: v for k, v in updates.items() if v is not None}, "id": server_id}
|
||||
self._servers[index] = _normalize_server(merged)
|
||||
self._save()
|
||||
result = dict(self._servers[index])
|
||||
break
|
||||
else:
|
||||
return None
|
||||
_token_cache.pop(server_id, None)
|
||||
return result
|
||||
|
||||
def delete_server(self, server_id: str) -> bool:
|
||||
with self._lock:
|
||||
before = len(self._servers)
|
||||
self._servers = [server for server in self._servers if server["id"] != server_id]
|
||||
removed = len(self._servers) < before
|
||||
if removed:
|
||||
self._save()
|
||||
if removed:
|
||||
_token_cache.pop(server_id, None)
|
||||
return removed
|
||||
|
||||
def set_import_job(self, server_id: str, import_job: dict | None) -> dict | None:
|
||||
with self._lock:
|
||||
for index, server in enumerate(self._servers):
|
||||
if server["id"] != server_id:
|
||||
continue
|
||||
next_server = dict(server)
|
||||
next_server["import_job"] = _normalize_import_job(import_job, fail_unfinished=False)
|
||||
self._servers[index] = next_server
|
||||
self._save()
|
||||
return dict(next_server)
|
||||
return None
|
||||
|
||||
def get_import_job(self, server_id: str) -> dict | None:
|
||||
with self._lock:
|
||||
for server in self._servers:
|
||||
if server["id"] == server_id:
|
||||
job = server.get("import_job")
|
||||
return dict(job) if isinstance(job, dict) else None
|
||||
return None
|
||||
|
||||
|
||||
# Per-server cached access token: {server_id: (jwt, expires_at_epoch)}
|
||||
_token_cache: dict[str, tuple[str, float]] = {}
|
||||
_token_cache_lock = Lock()
|
||||
|
||||
|
||||
def _login(base_url: str, email: str, password: str) -> tuple[str, float]:
|
||||
url = f"{base_url.rstrip('/')}/api/v1/auth/login"
|
||||
session = Session(verify=True)
|
||||
try:
|
||||
response = session.post(
|
||||
url,
|
||||
json={"email": email, "password": password},
|
||||
headers={"Accept": "application/json", "Content-Type": "application/json"},
|
||||
timeout=30,
|
||||
)
|
||||
if not response.ok:
|
||||
raise RuntimeError(f"sub2api login failed: HTTP {response.status_code} {response.text[:200]}")
|
||||
payload = response.json()
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
body = _unwrap_envelope(payload)
|
||||
if not isinstance(body, dict):
|
||||
raise RuntimeError("sub2api login payload is invalid")
|
||||
|
||||
token = _clean(body.get("access_token"))
|
||||
if not token:
|
||||
raise RuntimeError("sub2api login did not return access_token")
|
||||
|
||||
expires_in = int(body.get("expires_in") or 3600)
|
||||
expires_at = time.time() + max(60, expires_in) - _TOKEN_REFRESH_SKEW
|
||||
return token, expires_at
|
||||
|
||||
|
||||
def _auth_headers(server: dict) -> dict[str, str]:
|
||||
api_key = _clean(server.get("api_key"))
|
||||
if api_key:
|
||||
return {"x-api-key": api_key, "Accept": "application/json"}
|
||||
|
||||
email = _clean(server.get("email"))
|
||||
password = _clean(server.get("password"))
|
||||
if not email or not password:
|
||||
raise RuntimeError("sub2api server requires email+password or api_key")
|
||||
|
||||
server_id = _clean(server.get("id"))
|
||||
base_url = _clean(server.get("base_url"))
|
||||
|
||||
with _token_cache_lock:
|
||||
cached = _token_cache.get(server_id)
|
||||
if cached and cached[1] > time.time():
|
||||
return {"Authorization": f"Bearer {cached[0]}", "Accept": "application/json"}
|
||||
|
||||
token, expires_at = _login(base_url, email, password)
|
||||
with _token_cache_lock:
|
||||
_token_cache[server_id] = (token, expires_at)
|
||||
return {"Authorization": f"Bearer {token}", "Accept": "application/json"}
|
||||
|
||||
|
||||
def _extract_access_token(credentials: object) -> str:
|
||||
if not isinstance(credentials, dict):
|
||||
return ""
|
||||
for key in ("access_token", "accessToken", "token"):
|
||||
value = _clean(credentials.get(key))
|
||||
if value:
|
||||
return value
|
||||
return ""
|
||||
|
||||
|
||||
def _unwrap_envelope(payload: object) -> object:
|
||||
"""Peel sub2api's `{code, message, data}` envelope, returning the inner `data` field
|
||||
when present. Also handles unwrapped responses from older/alt versions."""
|
||||
if isinstance(payload, dict) and "data" in payload and "code" in payload:
|
||||
return payload.get("data")
|
||||
return payload
|
||||
|
||||
|
||||
def _extract_paged_items(payload: object) -> tuple[list, int]:
|
||||
"""Return (items, total) from a paginated sub2api response.
|
||||
|
||||
Handles both the wrapped shape `{code,data:{items,total,...}}` and a few looser
|
||||
variants (`{data:[...]}`, `[...]`, `{items:[...],total:N}`)."""
|
||||
inner = _unwrap_envelope(payload)
|
||||
if isinstance(inner, list):
|
||||
return inner, len(inner)
|
||||
if isinstance(inner, dict):
|
||||
for key in ("items", "data", "list"):
|
||||
value = inner.get(key)
|
||||
if isinstance(value, list):
|
||||
return value, int(inner.get("total") or len(value))
|
||||
return [], 0
|
||||
|
||||
|
||||
def list_remote_accounts(server: dict) -> list[dict]:
|
||||
"""Return a flat list of OpenAI OAuth accounts from a sub2api server."""
|
||||
base_url = _clean(server.get("base_url"))
|
||||
if not base_url:
|
||||
return []
|
||||
|
||||
headers = _auth_headers(server)
|
||||
group_id = _clean(server.get("group_id"))
|
||||
|
||||
session = Session(verify=True)
|
||||
items: list[dict] = []
|
||||
try:
|
||||
page = 1
|
||||
while True:
|
||||
params: dict[str, object] = {
|
||||
"platform": "openai",
|
||||
"type": "oauth",
|
||||
"page": page,
|
||||
"page_size": 200,
|
||||
}
|
||||
if group_id:
|
||||
params["group"] = group_id
|
||||
response = session.get(
|
||||
f"{base_url.rstrip('/')}/api/v1/admin/accounts",
|
||||
headers=headers,
|
||||
params=params,
|
||||
timeout=30,
|
||||
)
|
||||
if not response.ok:
|
||||
raise RuntimeError(f"sub2api list failed: HTTP {response.status_code} {response.text[:200]}")
|
||||
payload = response.json()
|
||||
|
||||
data, total = _extract_paged_items(payload)
|
||||
if not data:
|
||||
break
|
||||
|
||||
for account in data:
|
||||
if not isinstance(account, dict):
|
||||
continue
|
||||
credentials = account.get("credentials") if isinstance(account.get("credentials"), dict) else {}
|
||||
account_id = account.get("id")
|
||||
if account_id is None:
|
||||
continue
|
||||
items.append({
|
||||
"id": str(account_id),
|
||||
"name": _clean(account.get("name")),
|
||||
"email": _clean(credentials.get("email")) or _clean(account.get("name")),
|
||||
"plan_type": _clean(credentials.get("plan_type")),
|
||||
"status": _clean(account.get("status")),
|
||||
"expires_at": _clean(credentials.get("expires_at")),
|
||||
"has_refresh_token": bool(_clean(credentials.get("refresh_token"))),
|
||||
})
|
||||
|
||||
if page * 200 >= total or len(data) < 200:
|
||||
break
|
||||
page += 1
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
return items
|
||||
|
||||
|
||||
def list_remote_groups(server: dict) -> list[dict]:
|
||||
"""Return OpenAI account groups from a sub2api server."""
|
||||
base_url = _clean(server.get("base_url"))
|
||||
if not base_url:
|
||||
return []
|
||||
|
||||
headers = _auth_headers(server)
|
||||
|
||||
session = Session(verify=True)
|
||||
items: list[dict] = []
|
||||
try:
|
||||
page = 1
|
||||
while True:
|
||||
response = session.get(
|
||||
f"{base_url.rstrip('/')}/api/v1/admin/groups",
|
||||
headers=headers,
|
||||
params={
|
||||
"page": page,
|
||||
"page_size": 200,
|
||||
},
|
||||
timeout=30,
|
||||
)
|
||||
if not response.ok:
|
||||
raise RuntimeError(f"sub2api groups failed: HTTP {response.status_code} {response.text[:200]}")
|
||||
payload = response.json()
|
||||
|
||||
data, total = _extract_paged_items(payload)
|
||||
if not data:
|
||||
break
|
||||
|
||||
for group in data:
|
||||
if not isinstance(group, dict):
|
||||
continue
|
||||
group_id = group.get("id")
|
||||
if group_id is None:
|
||||
continue
|
||||
items.append({
|
||||
"id": str(group_id),
|
||||
"name": _clean(group.get("name")),
|
||||
"description": _clean(group.get("description")),
|
||||
"platform": _clean(group.get("platform")),
|
||||
"status": _clean(group.get("status")),
|
||||
"account_count": int(group.get("account_count") or 0),
|
||||
"active_account_count": int(group.get("active_account_count") or 0),
|
||||
})
|
||||
|
||||
if page * 200 >= total or len(data) < 200:
|
||||
break
|
||||
page += 1
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
return items
|
||||
|
||||
|
||||
def _fetch_access_tokens_for_accounts(server: dict, account_ids: list[str]) -> tuple[list[str], list[dict]]:
|
||||
"""Return exported access tokens and per-account errors from sub2api."""
|
||||
base_url = _clean(server.get("base_url"))
|
||||
headers = _auth_headers(server)
|
||||
ids = [_clean(item) for item in account_ids if _clean(item)]
|
||||
if not ids:
|
||||
return [], []
|
||||
|
||||
session = Session(verify=True)
|
||||
try:
|
||||
response = session.get(
|
||||
f"{base_url.rstrip('/')}/api/v1/admin/accounts/data",
|
||||
headers=headers,
|
||||
params={"ids": ",".join(ids), "timezone": "Asia/Shanghai"},
|
||||
timeout=30,
|
||||
)
|
||||
if not response.ok:
|
||||
raise RuntimeError(f"HTTP {response.status_code}")
|
||||
payload = response.json()
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
data = _unwrap_envelope(payload)
|
||||
accounts = data.get("accounts") if isinstance(data, dict) else None
|
||||
if not isinstance(accounts, list):
|
||||
raise RuntimeError("invalid export payload")
|
||||
|
||||
tokens: list[str] = []
|
||||
errors: list[dict] = []
|
||||
for account in accounts:
|
||||
if not isinstance(account, dict):
|
||||
continue
|
||||
credentials = account.get("credentials") if isinstance(account.get("credentials"), dict) else {}
|
||||
token = _extract_access_token(credentials)
|
||||
account_id = _clean(account.get("id")) or _clean(credentials.get("chatgpt_account_id")) or _clean(account.get("name"))
|
||||
if token:
|
||||
tokens.append(token)
|
||||
else:
|
||||
errors.append({"name": account_id or _clean(account.get("name")) or "unknown", "error": "missing access_token"})
|
||||
|
||||
if len(accounts) < len(ids):
|
||||
errors.append({"name": ",".join(ids), "error": f"exported {len(accounts)}/{len(ids)} accounts"})
|
||||
|
||||
return tokens, errors
|
||||
|
||||
|
||||
class Sub2APIImportService:
|
||||
def __init__(self, sub2api_config: Sub2APIConfig):
|
||||
self._config = sub2api_config
|
||||
|
||||
def start_import(self, server: dict, account_ids: list[str]) -> dict:
|
||||
ids = [_clean(item) for item in account_ids if _clean(item)]
|
||||
if not ids:
|
||||
raise ValueError("account ids is required")
|
||||
|
||||
server_id = _clean(server.get("id"))
|
||||
job = {
|
||||
"job_id": uuid.uuid4().hex,
|
||||
"status": "pending",
|
||||
"created_at": _now_iso(),
|
||||
"updated_at": _now_iso(),
|
||||
"total": len(ids),
|
||||
"completed": 0,
|
||||
"added": 0,
|
||||
"skipped": 0,
|
||||
"refreshed": 0,
|
||||
"failed": 0,
|
||||
"errors": [],
|
||||
}
|
||||
saved = self._config.set_import_job(server_id, job)
|
||||
if saved is None:
|
||||
raise ValueError("server not found")
|
||||
|
||||
thread = threading.Thread(
|
||||
target=self._run_import,
|
||||
args=(server_id, server, ids),
|
||||
name=f"sub2api-import-{server_id}",
|
||||
daemon=True,
|
||||
)
|
||||
thread.start()
|
||||
return dict(saved.get("import_job") or job)
|
||||
|
||||
def _update_job(self, server_id: str, **updates) -> None:
|
||||
current = self._config.get_import_job(server_id)
|
||||
if current is None:
|
||||
return
|
||||
next_job = {**current, **updates, "updated_at": _now_iso()}
|
||||
self._config.set_import_job(server_id, next_job)
|
||||
|
||||
def _append_error(self, server_id: str, account_id: str, message: str) -> None:
|
||||
current = self._config.get_import_job(server_id)
|
||||
if current is None:
|
||||
return
|
||||
errors = list(current.get("errors") or [])
|
||||
errors.append({"name": account_id, "error": message})
|
||||
self._update_job(server_id, errors=errors, failed=len(errors))
|
||||
|
||||
def _run_import(self, server_id: str, server: dict, account_ids: list[str]) -> None:
|
||||
self._update_job(server_id, status="running")
|
||||
|
||||
try:
|
||||
tokens, errors = _fetch_access_tokens_for_accounts(server, account_ids)
|
||||
except Exception as exc:
|
||||
message = str(exc) or "unknown error"
|
||||
for account_id in account_ids:
|
||||
self._append_error(server_id, account_id, message)
|
||||
tokens = []
|
||||
else:
|
||||
for error in errors:
|
||||
self._append_error(server_id, _clean(error.get("name")), _clean(error.get("error")) or "unknown error")
|
||||
|
||||
current = self._config.get_import_job(server_id) or {}
|
||||
self._update_job(
|
||||
server_id,
|
||||
completed=len(account_ids),
|
||||
failed=len(current.get("errors") or []),
|
||||
)
|
||||
|
||||
if not tokens:
|
||||
current = self._config.get_import_job(server_id) or {}
|
||||
self._update_job(
|
||||
server_id,
|
||||
status="failed",
|
||||
completed=int(current.get("total") or 0),
|
||||
failed=len(current.get("errors") or []),
|
||||
)
|
||||
return
|
||||
|
||||
add_result = account_service.add_accounts(tokens, source_type="codex")
|
||||
refresh_result = account_service.refresh_accounts(tokens)
|
||||
current = self._config.get_import_job(server_id) or {}
|
||||
self._update_job(
|
||||
server_id,
|
||||
status="completed",
|
||||
completed=len(account_ids),
|
||||
added=int(add_result.get("added") or 0),
|
||||
skipped=int(add_result.get("skipped") or 0),
|
||||
refreshed=int(refresh_result.get("refreshed") or 0),
|
||||
failed=len(current.get("errors") or []),
|
||||
)
|
||||
|
||||
|
||||
sub2api_config = Sub2APIConfig(SUB2API_CONFIG_FILE)
|
||||
sub2api_import_service = Sub2APIImportService(sub2api_config)
|
||||
@@ -0,0 +1,68 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import re
|
||||
from dataclasses import dataclass
|
||||
from datetime import datetime, timedelta, timezone
|
||||
|
||||
from utils.helper import UpstreamHTTPError
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class UploadLimit:
|
||||
blocked_until: datetime
|
||||
reason: str
|
||||
|
||||
|
||||
class UploadUnavailableError(RuntimeError):
|
||||
def __init__(self, blocked_until: datetime | None = None, *, attempts_exhausted: bool = False):
|
||||
message = (
|
||||
"多个账号上传受限,本次自动切换已达到上限,请稍后重试。"
|
||||
if attempts_exhausted else "当前没有可用于参考图上传的账号,请等待上传额度恢复或添加可用账号。"
|
||||
)
|
||||
if blocked_until:
|
||||
message += f" 已知上传限制最早预计恢复时间:{blocked_until.astimezone().strftime('%Y-%m-%d %H:%M:%S %Z')}。"
|
||||
super().__init__(message)
|
||||
|
||||
|
||||
def parse_upload_limit(error: Exception, now: datetime | None = None) -> UploadLimit | None:
|
||||
"""Recognize file quota failures only at the upstream upload allocation endpoint."""
|
||||
if not isinstance(error, UpstreamHTTPError) or error.status_code != 429 or error.context != "/backend-api/files":
|
||||
return None
|
||||
body = error.body
|
||||
if isinstance(body, str):
|
||||
try:
|
||||
body = json.loads(body)
|
||||
except (ValueError, TypeError):
|
||||
return None
|
||||
if not isinstance(body, dict):
|
||||
return None
|
||||
detail = body.get("detail") or body.get("error") or body
|
||||
if not isinstance(detail, dict):
|
||||
return None
|
||||
reason = str(detail.get("message") or "文件上传额度已用尽")
|
||||
codes = {str(detail.get(key) or "").lower() for key in ("code", "error_code", "type")}
|
||||
if not codes.intersection({"throttled", "file_upload_limit_exceeded", "upload_limit_exceeded"}) and not (
|
||||
"上传上限" in reason or "upload limit" in reason.lower()
|
||||
):
|
||||
return None
|
||||
now = now or datetime.now(timezone.utc)
|
||||
for key in ("retry_at", "reset_at"):
|
||||
value = detail.get(key)
|
||||
if value:
|
||||
try:
|
||||
reset = datetime.fromisoformat(str(value).replace("Z", "+00:00"))
|
||||
if reset.tzinfo and reset > now:
|
||||
return UploadLimit(reset, reason)
|
||||
except (ValueError, TypeError):
|
||||
pass
|
||||
if error.retry_after is not None and error.retry_after > 0:
|
||||
seconds = min(error.retry_after, 365 * 86400)
|
||||
else:
|
||||
units = {"小时": 3600, "分钟": 60, "秒": 1, "天": 86400,
|
||||
"day": 86400, "hour": 3600, "minute": 60, "second": 1}
|
||||
matches = re.findall(r"(\d+(?:\.\d+)?)\s*(小时|分钟|秒|天|days?|hours?|minutes?|seconds?)", reason.lower())
|
||||
seconds = sum(float(number) * units[unit.rstrip("s")] for number, unit in matches)
|
||||
# Unknown reset time: temporary cooling, never a fabricated daily reset.
|
||||
seconds = min(seconds, 365 * 86400) if seconds > 0 else 15 * 60
|
||||
return UploadLimit(now + timedelta(seconds=max(1, seconds)), reason)
|
||||
@@ -0,0 +1 @@
|
||||
|
||||
@@ -0,0 +1,118 @@
|
||||
import base64
|
||||
import json
|
||||
import unittest
|
||||
from typing import Any
|
||||
|
||||
from services.account_service import AccountService
|
||||
|
||||
|
||||
class MemoryStorage:
|
||||
def __init__(self, accounts: list[dict[str, Any]] | None = None) -> None:
|
||||
self.accounts = list(accounts or [])
|
||||
|
||||
def load_accounts(self) -> list[dict[str, Any]]:
|
||||
return list(self.accounts)
|
||||
|
||||
def save_accounts(self, accounts: list[dict[str, Any]]) -> None:
|
||||
self.accounts = list(accounts)
|
||||
|
||||
def load_auth_keys(self) -> list[dict[str, Any]]:
|
||||
return []
|
||||
|
||||
def save_auth_keys(self, auth_keys: list[dict[str, Any]]) -> None:
|
||||
pass
|
||||
|
||||
def health_check(self) -> dict[str, Any]:
|
||||
return {"ok": True}
|
||||
|
||||
def get_backend_info(self) -> dict[str, Any]:
|
||||
return {"type": "memory"}
|
||||
|
||||
|
||||
def make_jwt(payload: dict[str, Any]) -> str:
|
||||
def encode(value: dict[str, Any]) -> str:
|
||||
raw = json.dumps(value, separators=(",", ":")).encode("utf-8")
|
||||
return base64.urlsafe_b64encode(raw).decode("ascii").rstrip("=")
|
||||
|
||||
return f'{encode({"alg": "none", "typ": "JWT"})}.{encode(payload)}.sig'
|
||||
|
||||
|
||||
class AccountExportTests(unittest.TestCase):
|
||||
def test_build_export_items_uses_codex_shape_and_jwt_claims(self) -> None:
|
||||
access_token = make_jwt(
|
||||
{
|
||||
"exp": 0,
|
||||
"iat": 3600,
|
||||
"https://api.openai.com/auth": {"chatgpt_account_id": "acct_123"},
|
||||
"https://api.openai.com/profile": {"email": "test@example.com"},
|
||||
}
|
||||
)
|
||||
id_token = make_jwt({"email": "fallback@example.com"})
|
||||
service = AccountService(
|
||||
MemoryStorage(
|
||||
[
|
||||
{
|
||||
"access_token": access_token,
|
||||
"id_token": id_token,
|
||||
"refresh_token": "rt_test",
|
||||
}
|
||||
]
|
||||
)
|
||||
)
|
||||
|
||||
[item] = service.build_export_items([access_token])
|
||||
|
||||
self.assertEqual(item["type"], "codex")
|
||||
self.assertEqual(item["email"], "test@example.com")
|
||||
self.assertEqual(item["expired"], "1970-01-01T08:00:00+08:00")
|
||||
self.assertEqual(item["account_id"], "acct_123")
|
||||
self.assertEqual(item["access_token"], access_token)
|
||||
self.assertEqual(item["last_refresh"], "1970-01-01T09:00:00+08:00")
|
||||
self.assertEqual(item["id_token"], id_token)
|
||||
self.assertEqual(item["refresh_token"], "rt_test")
|
||||
|
||||
def test_build_export_items_skips_accounts_missing_complete_tokens(self) -> None:
|
||||
complete_access_token = make_jwt({"exp": 0})
|
||||
complete_id_token = make_jwt({"email": "complete@example.com"})
|
||||
service = AccountService(
|
||||
MemoryStorage(
|
||||
[
|
||||
{"access_token": "only_access"},
|
||||
{"access_token": "missing_id", "refresh_token": "rt_missing_id"},
|
||||
{"access_token": complete_access_token, "id_token": complete_id_token, "refresh_token": "rt_complete"},
|
||||
]
|
||||
)
|
||||
)
|
||||
|
||||
items = service.build_export_items()
|
||||
|
||||
self.assertEqual(len(items), 1)
|
||||
self.assertEqual(items[0]["access_token"], complete_access_token)
|
||||
self.assertEqual(items[0]["id_token"], complete_id_token)
|
||||
self.assertEqual(items[0]["refresh_token"], "rt_complete")
|
||||
|
||||
def test_add_account_items_preserves_export_fields_without_overwriting_plan_type(self) -> None:
|
||||
service = AccountService(MemoryStorage())
|
||||
|
||||
result = service.add_account_items(
|
||||
[
|
||||
{
|
||||
"type": "codex",
|
||||
"access_token": "access_token_test",
|
||||
"refresh_token": "rt_test",
|
||||
"account_id": "acct_123",
|
||||
}
|
||||
]
|
||||
)
|
||||
|
||||
account = service.get_account("access_token_test")
|
||||
self.assertEqual(result["added"], 1)
|
||||
self.assertIsNotNone(account)
|
||||
self.assertEqual(account["type"], "free")
|
||||
self.assertEqual(account["export_type"], "codex")
|
||||
self.assertEqual(account["refresh_token"], "rt_test")
|
||||
self.assertEqual(account["account_id"], "acct_123")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,233 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
import tempfile
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
from unittest.mock import patch
|
||||
|
||||
os.environ.setdefault("CHATGPT2API_AUTH_KEY", "test-auth")
|
||||
|
||||
from services.account_service import AccountService
|
||||
from services.auth_service import AuthService
|
||||
from services.config import config
|
||||
from services.openai_backend_api import InvalidAccessTokenError
|
||||
from services.storage.json_storage import JSONStorageBackend
|
||||
from utils.helper import anonymize_token, split_image_model
|
||||
|
||||
|
||||
class AccountCapabilityTests(unittest.TestCase):
|
||||
def test_image_accounts_require_positive_quota(self) -> None:
|
||||
self.assertFalse(
|
||||
AccountService._is_image_account_available(
|
||||
{"status": "限流", "quota": 1}
|
||||
)
|
||||
)
|
||||
self.assertFalse(
|
||||
AccountService._is_image_account_available(
|
||||
{"status": "正常", "quota": 0}
|
||||
)
|
||||
)
|
||||
self.assertTrue(AccountService._is_image_account_available({"status": "正常", "quota": 1}))
|
||||
|
||||
def test_prolite_variants_are_normalized(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = AccountService(JSONStorageBackend(Path(tmp_dir) / "accounts.json"))
|
||||
self.assertEqual(service._normalize_account_type("prolite"), "ProLite")
|
||||
self.assertEqual(service._normalize_account_type("pro_lite"), "ProLite")
|
||||
|
||||
def test_search_account_type_ignores_unrelated_scalar_values(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = AccountService(JSONStorageBackend(Path(tmp_dir) / "accounts.json"))
|
||||
self.assertIsNone(
|
||||
service._search_account_type(
|
||||
{
|
||||
"amr": ["pwd", "otp", "mfa"],
|
||||
"chatgpt_compute_residency": "no_constraint",
|
||||
"chatgpt_data_residency": "no_constraint",
|
||||
"user_id": "user-I52GFfLGFM0dokFk2dBiKEBn",
|
||||
}
|
||||
)
|
||||
)
|
||||
|
||||
def test_mark_image_result_consumes_quota(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = AccountService(JSONStorageBackend(Path(tmp_dir) / "accounts.json"))
|
||||
service.add_accounts(["token-1"])
|
||||
service.update_account(
|
||||
"token-1",
|
||||
{
|
||||
"status": "正常",
|
||||
"quota": 1,
|
||||
},
|
||||
)
|
||||
|
||||
updated = service.mark_image_result("token-1", success=True)
|
||||
|
||||
self.assertIsNotNone(updated)
|
||||
self.assertEqual(updated["quota"], 0)
|
||||
self.assertEqual(updated["status"], "限流")
|
||||
|
||||
def test_split_image_model_supports_plan_type_prefix(self) -> None:
|
||||
self.assertEqual(split_image_model("gpt-image-2"), (None, "gpt-image-2"))
|
||||
self.assertEqual(split_image_model("plus-codex-gpt-image-2"), ("plus", "codex-gpt-image-2"))
|
||||
self.assertEqual(split_image_model("team-codex-gpt-image-2"), ("team", "codex-gpt-image-2"))
|
||||
self.assertEqual(split_image_model("pro-codex-gpt-image-2"), ("pro", "codex-gpt-image-2"))
|
||||
self.assertEqual(split_image_model("plus-gpt-image-2"), (None, None))
|
||||
self.assertEqual(split_image_model("unknown-image-model"), (None, None))
|
||||
|
||||
def test_get_available_access_token_filters_by_plan_type(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = AccountService(JSONStorageBackend(Path(tmp_dir) / "accounts.json"))
|
||||
service.add_account_items(
|
||||
[
|
||||
{"access_token": "token-plus", "type": "Plus", "status": "正常", "quota": 3},
|
||||
{"access_token": "token-pro", "type": "Pro", "status": "正常", "quota": 3},
|
||||
]
|
||||
)
|
||||
|
||||
service.fetch_remote_info = lambda access_token, event="fetch_remote_info": service.get_account(access_token)
|
||||
|
||||
plus_token = service.get_available_access_token(plan_type="plus")
|
||||
pro_token = service.get_available_access_token(plan_type="pro")
|
||||
service.release_image_slot(plus_token)
|
||||
service.release_image_slot(pro_token)
|
||||
|
||||
self.assertEqual(plus_token, "token-plus")
|
||||
self.assertEqual(pro_token, "token-pro")
|
||||
|
||||
def test_refresh_accounts_can_remove_invalid_token_without_confirmation_delay(self) -> None:
|
||||
original_value = config.data.get("auto_remove_invalid_accounts")
|
||||
config.data["auto_remove_invalid_accounts"] = True
|
||||
try:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = AccountService(JSONStorageBackend(Path(tmp_dir) / "accounts.json"))
|
||||
service.add_account_items([{"access_token": "invalid-token", "status": "正常"}])
|
||||
|
||||
with patch(
|
||||
"services.openai_backend_api.OpenAIBackendAPI.get_user_info",
|
||||
side_effect=InvalidAccessTokenError("token invalidated (/backend-api/me)"),
|
||||
):
|
||||
result = service.refresh_accounts(["invalid-token"], defer_invalid_removal=False)
|
||||
|
||||
self.assertEqual(result["refreshed"], 0)
|
||||
self.assertEqual(len(result["errors"]), 1)
|
||||
self.assertEqual(result["items"], [])
|
||||
self.assertIsNone(service.get_account("invalid-token"))
|
||||
finally:
|
||||
if original_value is None:
|
||||
config.data.pop("auto_remove_invalid_accounts", None)
|
||||
else:
|
||||
config.data["auto_remove_invalid_accounts"] = original_value
|
||||
|
||||
def test_refresh_accounts_defers_invalid_token_removal_by_default(self) -> None:
|
||||
original_value = config.data.get("auto_remove_invalid_accounts")
|
||||
config.data["auto_remove_invalid_accounts"] = True
|
||||
try:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = AccountService(JSONStorageBackend(Path(tmp_dir) / "accounts.json"))
|
||||
service.add_account_items([{"access_token": "invalid-token", "status": "正常"}])
|
||||
|
||||
with patch(
|
||||
"services.openai_backend_api.OpenAIBackendAPI.get_user_info",
|
||||
side_effect=InvalidAccessTokenError("token invalidated (/backend-api/me)"),
|
||||
):
|
||||
result = service.refresh_accounts(["invalid-token"])
|
||||
|
||||
account = service.get_account("invalid-token")
|
||||
self.assertEqual(result["refreshed"], 0)
|
||||
self.assertEqual(len(result["errors"]), 1)
|
||||
self.assertIsNotNone(account)
|
||||
self.assertEqual(account["invalid_count"], 1)
|
||||
finally:
|
||||
if original_value is None:
|
||||
config.data.pop("auto_remove_invalid_accounts", None)
|
||||
else:
|
||||
config.data["auto_remove_invalid_accounts"] = original_value
|
||||
|
||||
|
||||
class TokenLogTests(unittest.TestCase):
|
||||
def test_anonymize_token_hides_raw_value(self) -> None:
|
||||
token = "super-secret-token"
|
||||
token_ref = anonymize_token(token)
|
||||
|
||||
self.assertTrue(token_ref.startswith("token:"))
|
||||
self.assertNotIn(token, token_ref)
|
||||
|
||||
|
||||
class AuthServiceTests(unittest.TestCase):
|
||||
def test_create_authenticate_disable_and_delete_user_key(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = AuthService(JSONStorageBackend(Path(tmp_dir) / "accounts.json", Path(tmp_dir) / "auth_keys.json"))
|
||||
|
||||
item, raw_key = service.create_key(role="user", name="Alice")
|
||||
|
||||
self.assertEqual(item["role"], "user")
|
||||
self.assertEqual(item["name"], "Alice")
|
||||
self.assertTrue(item["enabled"])
|
||||
self.assertTrue(raw_key.startswith("sk-"))
|
||||
|
||||
authed = service.authenticate(raw_key)
|
||||
self.assertIsNotNone(authed)
|
||||
self.assertEqual(authed["id"], item["id"])
|
||||
self.assertEqual(authed["role"], "user")
|
||||
self.assertIsNotNone(authed["last_used_at"])
|
||||
|
||||
updated = service.update_key(item["id"], {"enabled": False}, role="user")
|
||||
self.assertIsNotNone(updated)
|
||||
self.assertFalse(updated["enabled"])
|
||||
self.assertIsNone(service.authenticate(raw_key))
|
||||
|
||||
self.assertTrue(service.delete_key(item["id"], role="user"))
|
||||
self.assertFalse(service.delete_key(item["id"], role="user"))
|
||||
self.assertEqual(service.list_keys(role="user"), [])
|
||||
|
||||
def test_authenticate_ignores_last_used_save_failure(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = AuthService(JSONStorageBackend(Path(tmp_dir) / "accounts.json", Path(tmp_dir) / "auth_keys.json"))
|
||||
item, raw_key = service.create_key(role="user", name="Alice")
|
||||
|
||||
def fail_save() -> None:
|
||||
raise OSError("disk unavailable")
|
||||
|
||||
service._save = fail_save
|
||||
|
||||
authed = service.authenticate(raw_key)
|
||||
|
||||
self.assertIsNotNone(authed)
|
||||
self.assertEqual(authed["id"], item["id"])
|
||||
self.assertIsNotNone(authed["last_used_at"])
|
||||
|
||||
def test_update_user_key_replaces_raw_key(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = AuthService(JSONStorageBackend(Path(tmp_dir) / "accounts.json", Path(tmp_dir) / "auth_keys.json"))
|
||||
item, raw_key = service.create_key(role="user", name="Alice")
|
||||
|
||||
updated = service.update_key(item["id"], {"key": "sk-user-custom-key"}, role="user")
|
||||
|
||||
self.assertIsNotNone(updated)
|
||||
self.assertIsNone(service.authenticate(raw_key))
|
||||
|
||||
authed = service.authenticate("sk-user-custom-key")
|
||||
self.assertIsNotNone(authed)
|
||||
self.assertEqual(authed["id"], item["id"])
|
||||
|
||||
def test_user_key_name_must_be_unique(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = AuthService(JSONStorageBackend(Path(tmp_dir) / "accounts.json", Path(tmp_dir) / "auth_keys.json"))
|
||||
first, _ = service.create_key(role="user", name="Alice")
|
||||
second, _ = service.create_key(role="user", name="Bob")
|
||||
|
||||
with self.assertRaisesRegex(ValueError, "这个名称已经在使用中了"):
|
||||
service.create_key(role="user", name="Alice")
|
||||
|
||||
with self.assertRaisesRegex(ValueError, "这个名称已经在使用中了"):
|
||||
service.update_key(second["id"], {"name": "Alice"}, role="user")
|
||||
|
||||
updated = service.update_key(first["id"], {"name": "Alice"}, role="user")
|
||||
self.assertIsNotNone(updated)
|
||||
self.assertEqual(updated["name"], "Alice")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,94 @@
|
||||
import tempfile
|
||||
import unittest
|
||||
from datetime import datetime, timedelta, timezone
|
||||
from pathlib import Path
|
||||
from unittest.mock import patch
|
||||
|
||||
from services.account_service import AccountService
|
||||
from services.storage.json_storage import JSONStorageBackend
|
||||
from services.upload_limits import UploadLimit, UploadUnavailableError
|
||||
|
||||
|
||||
class AccountLiveValidationTests(unittest.TestCase):
|
||||
def setUp(self):
|
||||
temp = tempfile.TemporaryDirectory()
|
||||
self.addCleanup(temp.cleanup)
|
||||
for target in ("services.account_service.AccountService._save_cumulative_total",
|
||||
"services.account_service.log_service.add"):
|
||||
patcher = patch(target)
|
||||
patcher.start()
|
||||
self.addCleanup(patcher.stop)
|
||||
self.service = AccountService(JSONStorageBackend(Path(temp.name) / "accounts.json"))
|
||||
self.service.add_account_items([{"access_token": "test-token", "quota": 5, "status": "正常"}])
|
||||
patcher = patch("services.openai_backend_api.OpenAIBackendAPI")
|
||||
self.backend = patcher.start()
|
||||
self.addCleanup(patcher.stop)
|
||||
self.backend.return_value.get_user_info.return_value = {"quota": 5, "status": "正常"}
|
||||
|
||||
def acquire(self, **kwargs):
|
||||
token = self.service.get_available_access_token(**kwargs)
|
||||
self.service.release_image_slot(token)
|
||||
return token
|
||||
|
||||
def test_repeated_selection_always_refreshes_remote_quota(self):
|
||||
self.acquire()
|
||||
self.service.mark_image_result("test-token", True)
|
||||
self.backend.return_value.get_user_info.return_value = {"quota": 2, "status": "正常"}
|
||||
self.acquire()
|
||||
self.assertEqual(self.backend.return_value.get_user_info.call_count, 2)
|
||||
self.assertEqual(self.service.get_account("test-token")["quota"], 2)
|
||||
|
||||
def test_recent_background_refresh_does_not_skip_live_validation(self):
|
||||
self.service.fetch_remote_info("test-token")
|
||||
self.acquire()
|
||||
self.assertEqual(self.backend.return_value.get_user_info.call_count, 2)
|
||||
|
||||
def test_remote_quota_exhaustion_is_detected_immediately(self):
|
||||
self.acquire()
|
||||
self.backend.return_value.get_user_info.return_value = {"quota": 0, "status": "限流"}
|
||||
with self.assertRaises(RuntimeError):
|
||||
self.acquire()
|
||||
self.assertEqual(self.backend.return_value.get_user_info.call_count, 2)
|
||||
self.assertEqual(self.service._image_inflight, {})
|
||||
|
||||
def test_generation_failure_is_followed_by_live_validation(self):
|
||||
self.acquire()
|
||||
self.service.mark_image_result("test-token", False)
|
||||
self.acquire()
|
||||
self.assertEqual(self.backend.return_value.get_user_info.call_count, 2)
|
||||
|
||||
def test_manual_disable_and_zero_quota_are_excluded_before_validation(self):
|
||||
self.acquire()
|
||||
self.service.update_account("test-token", {"status": "禁用"}, manual=True)
|
||||
with self.assertRaises(RuntimeError):
|
||||
self.acquire()
|
||||
self.service.update_account("test-token", {"status": "正常", "quota": 0}, manual=True)
|
||||
with self.assertRaises(RuntimeError):
|
||||
self.acquire()
|
||||
self.assertEqual(self.backend.return_value.get_user_info.call_count, 1)
|
||||
|
||||
def test_upload_cooldown_is_respected_but_text_generation_revalidates(self):
|
||||
self.acquire()
|
||||
self.service.mark_upload_limited("test-token", UploadLimit(datetime.now(timezone.utc) + timedelta(hours=1), "limited"))
|
||||
with self.assertRaises(UploadUnavailableError):
|
||||
self.acquire(requires_upload=True)
|
||||
self.assertEqual(self.acquire(), "test-token")
|
||||
self.assertEqual(self.backend.return_value.get_user_info.call_count, 2)
|
||||
|
||||
def test_remote_failure_does_not_fall_back_to_previous_validation(self):
|
||||
self.acquire()
|
||||
self.backend.return_value.get_user_info.side_effect = RuntimeError("upstream unavailable")
|
||||
with self.assertRaises(RuntimeError):
|
||||
self.acquire()
|
||||
self.assertEqual(self.backend.return_value.get_user_info.call_count, 2)
|
||||
self.assertEqual(self.service._image_inflight, {})
|
||||
|
||||
def test_stats_count_active_upload_limits_independently(self):
|
||||
self.service.add_account_items([{"access_token": "expired", "quota": 5, "status": "正常"}])
|
||||
now = datetime.now(timezone.utc)
|
||||
self.service.mark_upload_limited("test-token", UploadLimit(now + timedelta(hours=1), "limited"))
|
||||
self.service.mark_upload_limited("expired", UploadLimit(now - timedelta(seconds=1), "expired"))
|
||||
stats = self.service.get_stats()
|
||||
self.assertEqual(stats["upload_limited"], 1)
|
||||
self.assertEqual(stats["active"], 2)
|
||||
self.assertEqual(stats["limited"], 0)
|
||||
@@ -0,0 +1,137 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import tempfile
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
from unittest.mock import patch
|
||||
|
||||
from fastapi import FastAPI
|
||||
from fastapi.testclient import TestClient
|
||||
|
||||
import api.accounts as accounts_api
|
||||
from services.account_service import AccountService
|
||||
from services.config import config
|
||||
from services.storage.json_storage import JSONStorageBackend
|
||||
|
||||
|
||||
class ManualAccountStatusTests(unittest.TestCase):
|
||||
def setUp(self):
|
||||
temp = tempfile.TemporaryDirectory()
|
||||
self.addCleanup(temp.cleanup)
|
||||
self.storage = JSONStorageBackend(Path(temp.name) / "accounts.json")
|
||||
self.storage.save_accounts([
|
||||
{"access_token": "token", "status": "正常", "quota": 3},
|
||||
])
|
||||
self.service = AccountService(self.storage)
|
||||
settings = patch.dict(config.data, {
|
||||
"auto_remove_rate_limited_accounts": False,
|
||||
"auto_remove_invalid_accounts": False,
|
||||
"auto_relogin_after_refresh": False,
|
||||
})
|
||||
settings.start()
|
||||
self.addCleanup(settings.stop)
|
||||
logs = patch("services.account_service.log_service.add")
|
||||
logs.start()
|
||||
self.addCleanup(logs.stop)
|
||||
|
||||
def refresh(self, during_fetch=None):
|
||||
def remote_info(_backend):
|
||||
if during_fetch:
|
||||
during_fetch()
|
||||
return {"status": "正常", "quota": 5, "email": "test@example.test"}
|
||||
|
||||
with patch.object(self.service, "refresh_access_token", side_effect=lambda token, **_: token), patch(
|
||||
"services.openai_backend_api.OpenAIBackendAPI.get_user_info", autospec=True, side_effect=remote_info
|
||||
):
|
||||
return self.service.fetch_remote_info("token", "test")
|
||||
|
||||
def test_refresh_finishing_after_manual_edit_preserves_status(self):
|
||||
for status in ("禁用", "限流"):
|
||||
with self.subTest(status=status):
|
||||
# Model the admin edit happening while the remote request is running.
|
||||
result = self.refresh(lambda: self.service.update_account("token", {"status": status}, manual=True))
|
||||
self.assertEqual(result["status"], status)
|
||||
self.assertEqual(result["quota"], 5)
|
||||
self.assertEqual(result["email"], "test@example.test")
|
||||
self.assertFalse(self.service._is_image_account_available(result))
|
||||
|
||||
def test_task_completion_does_not_clear_manual_status_or_delete_account(self):
|
||||
with patch.dict(config.data, {"auto_remove_rate_limited_accounts": True}):
|
||||
for status in ("禁用", "限流"):
|
||||
for quota in (1, 3):
|
||||
with self.subTest(status=status, quota=quota):
|
||||
self.service.update_account("token", {"status": status, "quota": quota}, manual=True)
|
||||
result = self.service.mark_image_result("token", True)
|
||||
self.assertIsNotNone(result)
|
||||
self.assertEqual(result["status"], status)
|
||||
self.assertEqual(result["quota"], quota - 1)
|
||||
self.assertIsNotNone(self.service.get_account("token"))
|
||||
|
||||
def test_manual_status_survives_reload_token_rotation_and_background_update(self):
|
||||
for status in ("禁用", "限流"):
|
||||
with self.subTest(status=status):
|
||||
self.service.update_account("token", {"status": status}, manual=True)
|
||||
reloaded = AccountService(self.storage)
|
||||
new_token = reloaded._apply_refreshed_tokens("token", {"access_token": "rotated"}, "test")
|
||||
result = reloaded.update_account(new_token, {"status": "正常"}, quiet=True)
|
||||
self.assertEqual(result["status"], status)
|
||||
reloaded._apply_refreshed_tokens(new_token, {"access_token": "token"}, "test")
|
||||
|
||||
def test_manual_normal_clears_override_and_allows_automatic_recovery(self):
|
||||
self.service.update_account("token", {"status": "限流"}, manual=True)
|
||||
self.assertNotIn("token", self.service.list_limited_tokens())
|
||||
self.service.update_account("token", {"status": "正常"}, manual=True)
|
||||
self.service.update_account("token", {"status": "限流", "quota": 0})
|
||||
self.assertIn("token", self.service.list_limited_tokens())
|
||||
self.assertEqual(self.refresh()["status"], "正常")
|
||||
self.assertIsNone(self.service.get_account("token")["manual_status"])
|
||||
|
||||
def test_legacy_disabled_accounts_stay_disabled_but_automatic_limits_recover(self):
|
||||
for status in ("禁用", "限流"):
|
||||
with self.subTest(status=status):
|
||||
self.storage.save_accounts([{"access_token": "token", "status": status, "quota": 0}])
|
||||
self.service = AccountService(self.storage)
|
||||
expected = "禁用" if status == "禁用" else "正常"
|
||||
self.assertEqual(self.refresh()["status"], expected)
|
||||
|
||||
def test_background_invalid_token_cleanup_keeps_manual_accounts(self):
|
||||
with patch.dict(config.data, {"auto_remove_invalid_accounts": True}):
|
||||
for status in ("禁用", "限流"):
|
||||
with self.subTest(status=status):
|
||||
self.service.update_account("token", {"status": status}, manual=True)
|
||||
self.assertFalse(self.service.remove_invalid_token("token", "test"))
|
||||
self.assertEqual(self.service.get_account("token")["status"], status)
|
||||
|
||||
def test_admin_update_endpoint_sets_and_clears_manual_override(self):
|
||||
app = FastAPI()
|
||||
app.include_router(accounts_api.create_router())
|
||||
with patch.object(accounts_api, "account_service", self.service), patch.object(
|
||||
accounts_api, "require_admin", return_value={"id": "admin", "role": "admin"}
|
||||
), TestClient(app) as client:
|
||||
for status in ("禁用", "限流", "正常"):
|
||||
response = client.post("/api/accounts/update", json={"access_token": "token", "status": status})
|
||||
self.assertEqual(response.status_code, 200, response.text)
|
||||
item = response.json()["item"]
|
||||
self.assertEqual(item["manual_status"], None if status == "正常" else status)
|
||||
client.post("/api/accounts/update", json={"access_token": "token", "status": "禁用"})
|
||||
response = client.post("/api/accounts/update", json={"access_token": "token", "quota": 8})
|
||||
self.assertEqual(response.json()["item"]["manual_status"], "禁用")
|
||||
|
||||
def test_manual_edit_during_invalid_cleanup_prevents_deletion(self):
|
||||
delete = self.service.delete_accounts
|
||||
|
||||
def concurrent_delete(tokens, **kwargs):
|
||||
self.service.update_account("token", {"status": "禁用"}, manual=True)
|
||||
return delete(tokens, **kwargs)
|
||||
|
||||
with patch.dict(config.data, {"auto_remove_invalid_accounts": True}), patch.object(
|
||||
self.service, "delete_accounts", side_effect=concurrent_delete
|
||||
):
|
||||
self.assertFalse(self.service.remove_invalid_token("token", "test"))
|
||||
self.assertEqual(self.service.get_account("token")["status"], "禁用")
|
||||
# Explicit administrator deletion is still allowed.
|
||||
self.assertEqual(self.service.delete_accounts(["token"])["removed"], 1)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,643 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import unittest
|
||||
from unittest import mock
|
||||
import json
|
||||
import base64
|
||||
|
||||
from services.config import config
|
||||
from services.protocol import openai_v1_chat_complete, openai_v1_response
|
||||
from services.protocol.chat_completion_cache import cache_key, chat_completion_cache
|
||||
from services.protocol.conversation import iter_conversation_payloads, sanitize_output_text
|
||||
from utils.helper import extract_image_from_message_content
|
||||
|
||||
|
||||
PNG_1X1 = base64.b64decode(
|
||||
"iVBORw0KGgoAAAANSUhEUgAAAAEAAAABCAIAAACQd1PeAAAADUlEQVR4nGP8z8BQDwAFgwJ/luzl4wAAAABJRU5ErkJggg=="
|
||||
)
|
||||
PNG_1X1_DATA_URL = "data:image/png;base64," + base64.b64encode(PNG_1X1).decode("ascii")
|
||||
|
||||
|
||||
class ChatCompletionCacheTests(unittest.TestCase):
|
||||
def setUp(self) -> None:
|
||||
self.old_cache_settings = config.data.get("chat_completion_cache")
|
||||
config.data["chat_completion_cache"] = {
|
||||
"enabled": True,
|
||||
"ttl_seconds": 60,
|
||||
"max_entries": 32,
|
||||
"dedupe_inflight": True,
|
||||
"stream_cache": True,
|
||||
"normalize_messages": True,
|
||||
"drop_adjacent_duplicates": True,
|
||||
"drop_assistant_history": False,
|
||||
}
|
||||
chat_completion_cache.clear()
|
||||
|
||||
def tearDown(self) -> None:
|
||||
if self.old_cache_settings is None:
|
||||
config.data.pop("chat_completion_cache", None)
|
||||
else:
|
||||
config.data["chat_completion_cache"] = self.old_cache_settings
|
||||
chat_completion_cache.clear()
|
||||
|
||||
def test_repeated_non_stream_text_completion_uses_cache(self) -> None:
|
||||
calls = 0
|
||||
|
||||
def fake_collect_text(_backend, _request):
|
||||
nonlocal calls
|
||||
calls += 1
|
||||
return f"cached answer {calls}"
|
||||
|
||||
body = {
|
||||
"model": "auto",
|
||||
"messages": [{"role": "user", "content": "cache this exact prompt"}],
|
||||
}
|
||||
|
||||
with (
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.text_backend", return_value=object()),
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.collect_text", side_effect=fake_collect_text),
|
||||
):
|
||||
first = openai_v1_chat_complete.handle(body)
|
||||
second = openai_v1_chat_complete.handle(body)
|
||||
|
||||
self.assertEqual(calls, 1)
|
||||
self.assertEqual(
|
||||
first["choices"][0]["message"]["content"],
|
||||
second["choices"][0]["message"]["content"],
|
||||
)
|
||||
|
||||
def test_cache_key_distinguishes_thinking_effort_inputs(self) -> None:
|
||||
messages = [{"role": "user", "content": "same prompt"}]
|
||||
base = {"model": "auto", "messages": messages}
|
||||
|
||||
default_key = cache_key(base, messages, stream=False)
|
||||
thinking_key = cache_key({**base, "thinking_effort": "high"}, messages, stream=False)
|
||||
reasoning_key = cache_key({**base, "reasoning": {"effort": "high"}}, messages, stream=False)
|
||||
|
||||
self.assertNotEqual(default_key, thinking_key)
|
||||
self.assertNotEqual(default_key, reasoning_key)
|
||||
self.assertNotEqual(thinking_key, reasoning_key)
|
||||
|
||||
def test_chat_completion_reasoning_effort_reaches_conversation_request(self) -> None:
|
||||
captured_efforts: list[str] = []
|
||||
|
||||
def fake_collect_text(_backend, request):
|
||||
captured_efforts.append(request.thinking_effort)
|
||||
return "ok"
|
||||
|
||||
body = {
|
||||
"model": "auto",
|
||||
"reasoning_effort": "xhigh",
|
||||
"messages": [{"role": "user", "content": "use more reasoning"}],
|
||||
}
|
||||
|
||||
with (
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.text_backend", return_value=object()),
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.collect_text", side_effect=fake_collect_text),
|
||||
):
|
||||
openai_v1_chat_complete.handle(body)
|
||||
|
||||
self.assertEqual(captured_efforts, ["extended"])
|
||||
|
||||
def test_responses_reasoning_effort_reaches_conversation_request(self) -> None:
|
||||
captured_efforts: list[str] = []
|
||||
|
||||
def fake_stream_text_deltas(_backend, request):
|
||||
captured_efforts.append(request.thinking_effort)
|
||||
yield "ok"
|
||||
|
||||
body = {
|
||||
"model": "auto",
|
||||
"input": "use more reasoning",
|
||||
"reasoning": {"effort": "xhigh"},
|
||||
}
|
||||
|
||||
with (
|
||||
mock.patch("services.protocol.openai_v1_response.text_backend", return_value=object()),
|
||||
mock.patch("services.protocol.openai_v1_response.stream_text_deltas", side_effect=fake_stream_text_deltas),
|
||||
):
|
||||
openai_v1_response.handle(body)
|
||||
|
||||
self.assertEqual(captured_efforts, ["extended"])
|
||||
|
||||
def test_repeated_stream_text_completion_replays_cached_chunks(self) -> None:
|
||||
calls = 0
|
||||
|
||||
def fake_stream_text_deltas(_backend, _request):
|
||||
nonlocal calls
|
||||
calls += 1
|
||||
yield "streamed"
|
||||
yield " answer"
|
||||
|
||||
body = {
|
||||
"model": "auto",
|
||||
"stream": True,
|
||||
"messages": [{"role": "user", "content": "stream cache this exact prompt"}],
|
||||
}
|
||||
|
||||
with (
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.text_backend", return_value=object()),
|
||||
mock.patch(
|
||||
"services.protocol.openai_v1_chat_complete.stream_text_deltas",
|
||||
side_effect=fake_stream_text_deltas,
|
||||
),
|
||||
):
|
||||
first = list(openai_v1_chat_complete.handle(body))
|
||||
second = list(openai_v1_chat_complete.handle(body))
|
||||
|
||||
self.assertEqual(calls, 1)
|
||||
self.assertEqual(first, second)
|
||||
content = "".join(str(chunk["choices"][0]["delta"].get("content") or "") for chunk in second)
|
||||
self.assertEqual(content, "streamed answer")
|
||||
|
||||
def test_adjacent_duplicate_messages_are_removed_before_upstream_call(self) -> None:
|
||||
captured_messages = []
|
||||
|
||||
def fake_collect_text(_backend, request):
|
||||
captured_messages.extend(request.messages or [])
|
||||
return "ok"
|
||||
|
||||
body = {
|
||||
"model": "auto",
|
||||
"messages": [
|
||||
{"role": "user", "content": "repeat me"},
|
||||
{"role": "user", "content": "repeat me"},
|
||||
{"role": "assistant", "content": "old answer"},
|
||||
{"role": "user", "content": "next prompt"},
|
||||
],
|
||||
}
|
||||
|
||||
with (
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.text_backend", return_value=object()),
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.collect_text", side_effect=fake_collect_text),
|
||||
):
|
||||
openai_v1_chat_complete.handle(body)
|
||||
|
||||
self.assertEqual(
|
||||
captured_messages,
|
||||
[
|
||||
{"role": "user", "content": "repeat me"},
|
||||
{"role": "assistant", "content": "old answer"},
|
||||
{"role": "user", "content": "next prompt"},
|
||||
],
|
||||
)
|
||||
|
||||
def test_chat_completion_usage_includes_cached_tokens(self) -> None:
|
||||
with (
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.text_backend", return_value=object()),
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.collect_text", return_value="ok"),
|
||||
):
|
||||
response = openai_v1_chat_complete.handle({
|
||||
"model": "auto",
|
||||
"messages": [{"role": "user", "content": "usage shape"}],
|
||||
})
|
||||
|
||||
details = response["usage"]["prompt_tokens_details"]
|
||||
self.assertEqual(details["cached_tokens"], 0)
|
||||
output_details = response["usage"]["completion_tokens_details"]
|
||||
self.assertEqual(output_details["reasoning_tokens"], 0)
|
||||
|
||||
def test_responses_completed_usage_includes_cached_tokens(self) -> None:
|
||||
with (
|
||||
mock.patch("services.protocol.openai_v1_response.text_backend", return_value=object()),
|
||||
mock.patch("services.protocol.openai_v1_response.stream_text_deltas", return_value=iter(["ok"])),
|
||||
):
|
||||
response = openai_v1_response.handle({
|
||||
"model": "auto",
|
||||
"input": "usage shape",
|
||||
})
|
||||
|
||||
details = response["usage"]["input_tokens_details"]
|
||||
self.assertEqual(details["cached_tokens"], 0)
|
||||
output_details = response["usage"]["output_tokens_details"]
|
||||
self.assertEqual(output_details["reasoning_tokens"], 0)
|
||||
|
||||
def test_repeated_responses_text_request_uses_cache(self) -> None:
|
||||
calls = 0
|
||||
|
||||
def fake_stream_text_deltas(_backend, _request):
|
||||
nonlocal calls
|
||||
calls += 1
|
||||
yield f"response cache {calls}"
|
||||
|
||||
body = {
|
||||
"model": "auto",
|
||||
"input": "cache this responses prompt",
|
||||
"stream": True,
|
||||
}
|
||||
|
||||
with (
|
||||
mock.patch("services.protocol.openai_v1_response.text_backend", return_value=object()),
|
||||
mock.patch("services.protocol.openai_v1_response.stream_text_deltas", side_effect=fake_stream_text_deltas),
|
||||
):
|
||||
first = list(openai_v1_response.handle(body))
|
||||
second = list(openai_v1_response.handle(body))
|
||||
|
||||
self.assertEqual(calls, 1)
|
||||
self.assertEqual(first, second)
|
||||
|
||||
def test_output_sanitizer_removes_chatgpt_annotation_markup(self) -> None:
|
||||
text = (
|
||||
"Repo: \ue200url\ue202basketikun/chatgpt2api"
|
||||
"\ue202https://github.com/basketikun/chatgpt2api\ue201 "
|
||||
"details \ue200cite\ue202turn0search0\ue201."
|
||||
)
|
||||
|
||||
self.assertEqual(
|
||||
sanitize_output_text(text),
|
||||
"Repo: basketikun/chatgpt2api (https://github.com/basketikun/chatgpt2api) details.",
|
||||
)
|
||||
|
||||
def test_output_sanitizer_preserves_annotated_entity_text(self) -> None:
|
||||
text = (
|
||||
"The character is from \ue200entity\ue202Invincible\ue201, "
|
||||
"which is based on the comic series \ue200entity\ue202Invincible\ue201."
|
||||
)
|
||||
|
||||
self.assertEqual(
|
||||
sanitize_output_text(text),
|
||||
"The character is from Invincible, which is based on the comic series Invincible.",
|
||||
)
|
||||
|
||||
def test_output_sanitizer_preserves_readable_cite_label(self) -> None:
|
||||
text = "The character is \ue200cite\ue202Invincible\ue202turn0search0\ue201."
|
||||
|
||||
self.assertEqual(sanitize_output_text(text), "The character is Invincible.")
|
||||
|
||||
def test_output_sanitizer_preserves_code_spaces_before_punctuation(self) -> None:
|
||||
self.assertEqual(sanitize_output_text("find ."), "find .")
|
||||
self.assertEqual(sanitize_output_text("if ! test -f x; then"), "if ! test -f x; then")
|
||||
|
||||
def test_stream_sanitizer_does_not_emit_partial_annotation_or_repeat_prefix(self) -> None:
|
||||
events = [
|
||||
{"p": "/message/content/parts/0", "o": "append", "v": "Repo: \ue200url\ue202chat"},
|
||||
{"p": "/message/content/parts/0", "o": "append", "v": "gpt2api\ue202turn0search0\ue201 done \ue200cite\ue202turn0\ue201."},
|
||||
"[DONE]",
|
||||
]
|
||||
payloads = [json.dumps(event, ensure_ascii=False) if isinstance(event, dict) else event for event in events]
|
||||
deltas = [
|
||||
str(event.get("delta") or "")
|
||||
for event in iter_conversation_payloads(iter(payloads))
|
||||
if event.get("type") == "conversation.delta"
|
||||
]
|
||||
|
||||
self.assertEqual("".join(deltas), "Repo: chatgpt2api done.")
|
||||
self.assertFalse(any("\ue200" in delta or "\ue202" in delta or "\ue201" in delta for delta in deltas))
|
||||
|
||||
def test_stream_ignores_internal_tool_recipient_messages(self) -> None:
|
||||
events = [
|
||||
{
|
||||
"message": {
|
||||
"author": {"role": "assistant"},
|
||||
"content": {
|
||||
"content_type": "code",
|
||||
"text": 'search("\\u56fd\\u5bb6\\u6d77\\u6d0b")',
|
||||
},
|
||||
"recipient": "web",
|
||||
"status": "finished_successfully",
|
||||
},
|
||||
},
|
||||
{
|
||||
"message": {
|
||||
"author": {"name": "web.run", "role": "tool"},
|
||||
"content": {"content_type": "text", "parts": [""]},
|
||||
"recipient": "all",
|
||||
"status": "finished_successfully",
|
||||
},
|
||||
},
|
||||
{
|
||||
"v": {
|
||||
"message": {
|
||||
"author": {"role": "assistant"},
|
||||
"content": {
|
||||
"content_type": "code",
|
||||
"text": '{"aspect_ratio":"16:9","query":["museum"],"num_per_query":2}',
|
||||
},
|
||||
"recipient": "web",
|
||||
"status": "finished_successfully",
|
||||
},
|
||||
},
|
||||
},
|
||||
{
|
||||
"message": {
|
||||
"author": {"role": "assistant"},
|
||||
"channel": "final",
|
||||
"content": {"content_type": "text", "parts": ["Final answer."]},
|
||||
"recipient": "all",
|
||||
"status": "finished_successfully",
|
||||
},
|
||||
},
|
||||
"[DONE]",
|
||||
]
|
||||
payloads = [json.dumps(event, ensure_ascii=False) if isinstance(event, dict) else event for event in events]
|
||||
deltas = [
|
||||
str(event.get("delta") or "")
|
||||
for event in iter_conversation_payloads(iter(payloads))
|
||||
if event.get("type") == "conversation.delta"
|
||||
]
|
||||
|
||||
self.assertEqual("".join(deltas), "Final answer.")
|
||||
|
||||
def test_stream_ignores_hidden_and_non_final_assistant_messages(self) -> None:
|
||||
events = [
|
||||
{
|
||||
"message": {
|
||||
"author": {"role": "assistant"},
|
||||
"channel": "final",
|
||||
"content": {"content_type": "text", "parts": ["Hidden text."]},
|
||||
"metadata": {"is_visually_hidden_from_conversation": True},
|
||||
"recipient": "all",
|
||||
},
|
||||
},
|
||||
{
|
||||
"message": {
|
||||
"author": {"role": "assistant"},
|
||||
"channel": "analysis",
|
||||
"content": {"content_type": "text", "parts": ["Private reasoning."]},
|
||||
"recipient": "all",
|
||||
},
|
||||
},
|
||||
{
|
||||
"message": {
|
||||
"author": {"role": "assistant"},
|
||||
"channel": "final",
|
||||
"content": {"content_type": "text", "parts": ["Visible text."]},
|
||||
"recipient": "all",
|
||||
},
|
||||
},
|
||||
"[DONE]",
|
||||
]
|
||||
payloads = [json.dumps(event, ensure_ascii=False) if isinstance(event, dict) else event for event in events]
|
||||
deltas = [
|
||||
str(event.get("delta") or "")
|
||||
for event in iter_conversation_payloads(iter(payloads))
|
||||
if event.get("type") == "conversation.delta"
|
||||
]
|
||||
|
||||
self.assertEqual("".join(deltas), "Visible text.")
|
||||
|
||||
def test_stream_preserves_user_visible_code_messages(self) -> None:
|
||||
events = [
|
||||
{
|
||||
"message": {
|
||||
"author": {"role": "assistant"},
|
||||
"channel": "final",
|
||||
"content": {"content_type": "code", "text": 'print("hello")'},
|
||||
"recipient": "all",
|
||||
},
|
||||
},
|
||||
"[DONE]",
|
||||
]
|
||||
payloads = [json.dumps(event, ensure_ascii=False) if isinstance(event, dict) else event for event in events]
|
||||
deltas = [
|
||||
str(event.get("delta") or "")
|
||||
for event in iter_conversation_payloads(iter(payloads))
|
||||
if event.get("type") == "conversation.delta"
|
||||
]
|
||||
|
||||
self.assertEqual("".join(deltas), 'print("hello")')
|
||||
|
||||
def test_responses_tools_add_honest_no_tool_guard(self) -> None:
|
||||
model, messages = openai_v1_response.text_response_parts({
|
||||
"model": "auto",
|
||||
"input": "run echo hi",
|
||||
"tools": [{"type": "function", "name": "shell"}],
|
||||
})
|
||||
|
||||
self.assertEqual(model, "auto")
|
||||
self.assertEqual(messages[0]["role"], "system")
|
||||
self.assertIn("cannot execute local tools", str(messages[0]["content"]))
|
||||
|
||||
def test_responses_web_search_tool_returns_search_output(self) -> None:
|
||||
search_result = {
|
||||
"answer": "Latest answer.",
|
||||
"sources": [{"title": "Example", "url": "https://example.com/news", "snippet": "Snippet"}],
|
||||
}
|
||||
body = {
|
||||
"model": "auto",
|
||||
"input": "latest example news",
|
||||
"tools": [{"type": "web_search"}],
|
||||
}
|
||||
|
||||
with mock.patch("services.protocol.openai_v1_response.run_web_search", return_value=search_result) as search:
|
||||
response = openai_v1_response.handle(body)
|
||||
|
||||
search.assert_called_once_with("latest example news")
|
||||
self.assertEqual(response["output"][0]["type"], "web_search_call")
|
||||
self.assertEqual(response["output"][0]["status"], "completed")
|
||||
self.assertEqual(response["output"][0]["action"]["query"], "latest example news")
|
||||
message = response["output"][1]
|
||||
self.assertEqual(message["type"], "message")
|
||||
content = message["content"][0]
|
||||
self.assertIn("Latest answer.", content["text"])
|
||||
self.assertEqual(content["annotations"][0]["type"], "url_citation")
|
||||
self.assertEqual(content["annotations"][0]["url"], "https://example.com/news")
|
||||
|
||||
def test_responses_web_search_tool_streams_search_events(self) -> None:
|
||||
search_result = {
|
||||
"answer": "Streamed search answer.",
|
||||
"sources": [{"title": "Example", "url": "https://example.com/stream", "snippet": ""}],
|
||||
}
|
||||
body = {
|
||||
"model": "auto",
|
||||
"stream": True,
|
||||
"input": "stream search",
|
||||
"tools": [{"type": "web_search_preview"}],
|
||||
}
|
||||
|
||||
with mock.patch("services.protocol.openai_v1_response.run_web_search", return_value=search_result):
|
||||
events = list(openai_v1_response.handle(body))
|
||||
|
||||
event_types = [event["type"] for event in events]
|
||||
self.assertIn("response.web_search_call.in_progress", event_types)
|
||||
self.assertIn("response.web_search_call.searching", event_types)
|
||||
self.assertIn("response.web_search_call.completed", event_types)
|
||||
completed = events[-1]["response"]
|
||||
self.assertEqual(completed["output"][0]["type"], "web_search_call")
|
||||
self.assertEqual(completed["output"][1]["type"], "message")
|
||||
|
||||
def test_responses_versioned_web_search_tool_returns_search_output(self) -> None:
|
||||
search_result = {
|
||||
"answer": "Versioned search answer.",
|
||||
"sources": [{"title": "Example", "url": "https://example.com/versioned", "snippet": ""}],
|
||||
}
|
||||
body = {
|
||||
"model": "auto",
|
||||
"input": "versioned search",
|
||||
"tools": [{"type": "web_search_preview_2025_03_11"}],
|
||||
}
|
||||
|
||||
with mock.patch("services.protocol.openai_v1_response.run_web_search", return_value=search_result) as search:
|
||||
response = openai_v1_response.handle(body)
|
||||
|
||||
search.assert_called_once_with("versioned search")
|
||||
self.assertEqual(response["output"][0]["type"], "web_search_call")
|
||||
self.assertIn("Versioned search answer.", response["output"][1]["content"][0]["text"])
|
||||
|
||||
def test_chat_completions_web_search_tool_returns_search_answer(self) -> None:
|
||||
search_result = {
|
||||
"answer": "Chat search answer.",
|
||||
"sources": [{"title": "Example", "url": "https://example.com/chat", "snippet": ""}],
|
||||
}
|
||||
body = {
|
||||
"model": "auto",
|
||||
"messages": [{"role": "user", "content": "search chat"}],
|
||||
"tools": [{"type": "web_search"}],
|
||||
}
|
||||
|
||||
with mock.patch("services.protocol.openai_v1_chat_complete.run_web_search", return_value=search_result) as search:
|
||||
response = openai_v1_chat_complete.handle(body)
|
||||
|
||||
search.assert_called_once_with("search chat")
|
||||
message = response["choices"][0]["message"]
|
||||
self.assertIn("Chat search answer.", message["content"])
|
||||
self.assertEqual(message["annotations"][0]["type"], "url_citation")
|
||||
self.assertEqual(message["annotations"][0]["url_citation"]["url"], "https://example.com/chat")
|
||||
|
||||
def test_chat_completions_web_search_options_trigger_search(self) -> None:
|
||||
search_result = {
|
||||
"answer": "Options search answer.",
|
||||
"sources": [{"title": "Example", "url": "https://example.com/options", "snippet": ""}],
|
||||
}
|
||||
body = {
|
||||
"model": "auto",
|
||||
"messages": [{"role": "user", "content": "search options"}],
|
||||
"web_search_options": {"search_context_size": "low"},
|
||||
}
|
||||
|
||||
with mock.patch("services.protocol.openai_v1_chat_complete.run_web_search", return_value=search_result) as search:
|
||||
response = openai_v1_chat_complete.handle(body)
|
||||
|
||||
search.assert_called_once_with("search options")
|
||||
self.assertIn("Options search answer.", response["choices"][0]["message"]["content"])
|
||||
|
||||
def test_chat_completions_search_model_triggers_search(self) -> None:
|
||||
search_result = {
|
||||
"answer": "Search model answer.",
|
||||
"sources": [{"title": "Example", "url": "https://example.com/model", "snippet": ""}],
|
||||
}
|
||||
body = {
|
||||
"model": "gpt-5-search-api-2026-06-01",
|
||||
"messages": [{"role": "user", "content": "search model"}],
|
||||
}
|
||||
|
||||
with mock.patch("services.protocol.openai_v1_chat_complete.run_web_search", return_value=search_result) as search:
|
||||
response = openai_v1_chat_complete.handle(body)
|
||||
|
||||
search.assert_called_once_with("search model")
|
||||
self.assertEqual(response["model"], "gpt-5-search-api-2026-06-01")
|
||||
self.assertIn("Search model answer.", response["choices"][0]["message"]["content"])
|
||||
|
||||
def test_chat_completions_search_like_model_does_not_trigger_search(self) -> None:
|
||||
body = {
|
||||
"model": "gpt-5-search-apiary",
|
||||
"messages": [{"role": "user", "content": "not actually a search model"}],
|
||||
}
|
||||
|
||||
with (
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.run_web_search") as search,
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.text_backend", return_value=object()),
|
||||
mock.patch("services.protocol.openai_v1_chat_complete.collect_text", return_value="plain text answer"),
|
||||
):
|
||||
response = openai_v1_chat_complete.handle(body)
|
||||
|
||||
search.assert_not_called()
|
||||
self.assertIn("plain text answer", response["choices"][0]["message"]["content"])
|
||||
|
||||
def test_chat_completions_accepts_remote_image_url(self) -> None:
|
||||
class FakeImageResponse:
|
||||
status_code = 200
|
||||
headers = {"content-type": "image/png", "content-length": str(len(PNG_1X1))}
|
||||
content = PNG_1X1
|
||||
|
||||
with mock.patch("utils.helper.requests.get", return_value=FakeImageResponse()) as request_get:
|
||||
model, messages = openai_v1_chat_complete.text_chat_parts({
|
||||
"model": "auto",
|
||||
"messages": [{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "text", "text": "Describe this"},
|
||||
{"type": "image_url", "image_url": {"url": "https://example.test/image.png"}},
|
||||
],
|
||||
}],
|
||||
})
|
||||
|
||||
request_get.assert_called_once()
|
||||
self.assertEqual(model, "auto")
|
||||
content = messages[0]["content"]
|
||||
self.assertEqual(content[0], {"type": "text", "text": "Describe this"})
|
||||
self.assertEqual(content[1]["type"], "image")
|
||||
self.assertEqual(content[1]["data"], PNG_1X1)
|
||||
self.assertEqual(content[1]["mime"], "image/png")
|
||||
|
||||
def test_responses_text_request_preserves_input_image(self) -> None:
|
||||
captured = {}
|
||||
|
||||
def fake_stream_text_deltas(_backend, request):
|
||||
captured["messages"] = request.messages
|
||||
yield "red"
|
||||
|
||||
body = {
|
||||
"model": "auto",
|
||||
"input": [
|
||||
{"type": "input_text", "text": "What color is this image?"},
|
||||
{"type": "input_image", "image_url": PNG_1X1_DATA_URL},
|
||||
],
|
||||
}
|
||||
|
||||
with (
|
||||
mock.patch("services.protocol.openai_v1_response.text_backend", return_value=object()),
|
||||
mock.patch("services.protocol.openai_v1_response.stream_text_deltas", side_effect=fake_stream_text_deltas),
|
||||
):
|
||||
response = openai_v1_response.handle(body)
|
||||
|
||||
self.assertEqual(response["output"][0]["content"][0]["text"], "red")
|
||||
content = captured["messages"][0]["content"]
|
||||
self.assertEqual(content[0], {"type": "text", "text": "What color is this image?"})
|
||||
self.assertEqual(content[1]["type"], "image")
|
||||
self.assertEqual(content[1]["mime"], "image/png")
|
||||
self.assertEqual(content[1]["data"], PNG_1X1)
|
||||
self.assertGreater(response["usage"]["input_tokens_details"]["image_tokens"], 0)
|
||||
|
||||
def test_responses_text_request_accepts_remote_input_image_url(self) -> None:
|
||||
class FakeImageResponse:
|
||||
status_code = 200
|
||||
headers = {"content-type": "image/png", "content-length": str(len(PNG_1X1))}
|
||||
content = PNG_1X1
|
||||
|
||||
with mock.patch("utils.helper.requests.get", return_value=FakeImageResponse()) as request_get:
|
||||
_model, messages = openai_v1_response.text_response_parts({
|
||||
"model": "auto",
|
||||
"input": [{
|
||||
"type": "message",
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "input_text", "text": "Describe this"},
|
||||
{"type": "input_image", "image_url": {"url": "https://example.test/image.png"}},
|
||||
],
|
||||
}],
|
||||
})
|
||||
|
||||
request_get.assert_called_once()
|
||||
content = messages[0]["content"]
|
||||
self.assertEqual(content[0], {"type": "text", "text": "Describe this"})
|
||||
self.assertEqual(content[1]["type"], "image")
|
||||
self.assertEqual(content[1]["data"], PNG_1X1)
|
||||
self.assertEqual(content[1]["mime"], "image/png")
|
||||
|
||||
def test_image_extractor_supports_extra_image_object_shapes(self) -> None:
|
||||
encoded = base64.b64encode(PNG_1X1).decode("ascii")
|
||||
|
||||
images = extract_image_from_message_content([
|
||||
{"type": "image", "data": PNG_1X1, "mime": "image/png"},
|
||||
{"type": "input_image", "base64": encoded, "mime_type": "image/png"},
|
||||
{"type": "input_image", "source": {"type": "base64", "data": encoded, "media_type": "image/png"}},
|
||||
])
|
||||
|
||||
self.assertEqual(len(images), 3)
|
||||
self.assertEqual([image[1] for image in images], ["image/png", "image/png", "image/png"])
|
||||
self.assertTrue(all(image[0] == PNG_1X1 for image in images))
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,86 @@
|
||||
#!/usr/bin/env python3
|
||||
# Test script: directly call https://chatgpt.com/backend-api/codex/responses to generate one 2K image.
|
||||
# Only edit ACCESS_TOKEN, then run: python codex_responses_image_test.py
|
||||
# Fixed request parameters:
|
||||
# prompt: A highly detailed square 2K image of a quiet futuristic library at sunrise
|
||||
# responses model: gpt-5.5
|
||||
# image model: gpt-image-2
|
||||
# size: 2048x2048
|
||||
# quality: auto
|
||||
# output_format: png
|
||||
# output file: codex_4k.png
|
||||
|
||||
import base64
|
||||
import json
|
||||
import time
|
||||
import urllib.request
|
||||
|
||||
ACCESS_TOKEN = ""
|
||||
|
||||
|
||||
def parse_events(raw):
|
||||
ctype, text = raw.headers.get("content-type", ""), raw.read().decode("utf-8", "replace")
|
||||
if "application/json" in ctype:
|
||||
return [json.loads(text)]
|
||||
events, lines = [], []
|
||||
for line in text.splitlines() + [""]:
|
||||
if not line:
|
||||
if lines:
|
||||
data = "\n".join(lines).strip()
|
||||
if data and data != "[DONE]":
|
||||
events.append(json.loads(data))
|
||||
lines = []
|
||||
elif line.startswith("data:"):
|
||||
lines.append(line[5:].lstrip())
|
||||
return events
|
||||
|
||||
|
||||
def find_images(value):
|
||||
if isinstance(value, dict):
|
||||
if value.get("type") == "image_generation_call" and isinstance(value.get("result"), str):
|
||||
result = value["result"].strip()
|
||||
return [result.split(",", 1)[1] if result.startswith("data:image/") else result]
|
||||
return [image for item in value.values() for image in find_images(item)]
|
||||
if isinstance(value, list):
|
||||
return [image for item in value for image in find_images(item)]
|
||||
return []
|
||||
|
||||
|
||||
def main():
|
||||
start_time = time.time()
|
||||
body = {
|
||||
"model": "gpt-5.5",
|
||||
"instructions": "Use the image_generation tool to create exactly one image for the user's request. Return the generated image result.",
|
||||
"store": False,
|
||||
"input": [{"role": "user", "content": [{"type": "input_text", "text": "A highly detailed square 2K image of a quiet futuristic library at sunrise"}]}],
|
||||
"tools": [{
|
||||
"type": "image_generation",
|
||||
"model": "gpt-image-2",
|
||||
"action": "generate",
|
||||
"size": "3840x2160",
|
||||
"quality": "auto",
|
||||
"output_format": "png"
|
||||
}],
|
||||
"tool_choice": {"type": "image_generation"},
|
||||
"stream": True
|
||||
}
|
||||
headers = {"Authorization": f"Bearer {ACCESS_TOKEN}", "Content-Type": "application/json"}
|
||||
|
||||
req = urllib.request.Request("https://chatgpt.com/backend-api/codex/responses", json.dumps(body).encode(), headers, method="POST")
|
||||
try:
|
||||
images = find_images(parse_events(urllib.request.urlopen(req, timeout=1200)))
|
||||
except urllib.error.HTTPError as error:
|
||||
raise SystemExit(f"HTTP {error.code}: {error.read().decode('utf-8', 'replace')[:1000]}")
|
||||
|
||||
if not images:
|
||||
raise SystemExit("No image result found in response")
|
||||
|
||||
with open("codex_4k.png", "wb") as file:
|
||||
file.write(base64.b64decode(images[0]))
|
||||
print("saved codex_4k.png")
|
||||
end_time = time.time()
|
||||
print(f"total time: {end_time - start_time:.2f} seconds")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,63 @@
|
||||
import json
|
||||
import tempfile
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
|
||||
|
||||
ROOT_DIR = Path(__file__).resolve().parents[1]
|
||||
ROOT_CONFIG_FILE = ROOT_DIR / "config.json"
|
||||
|
||||
|
||||
class ConfigLoadingTests(unittest.TestCase):
|
||||
@classmethod
|
||||
def setUpClass(cls) -> None:
|
||||
cls._created_root_config = False
|
||||
if not ROOT_CONFIG_FILE.exists():
|
||||
ROOT_CONFIG_FILE.write_text(json.dumps({"auth-key": "test-auth"}), encoding="utf-8")
|
||||
cls._created_root_config = True
|
||||
|
||||
from services import config as config_module
|
||||
|
||||
cls.config_module = config_module
|
||||
|
||||
@classmethod
|
||||
def tearDownClass(cls) -> None:
|
||||
if cls._created_root_config and ROOT_CONFIG_FILE.exists():
|
||||
ROOT_CONFIG_FILE.unlink()
|
||||
|
||||
def test_load_settings_ignores_directory_config_path(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
base_dir = Path(tmp_dir)
|
||||
data_dir = base_dir / "data"
|
||||
config_dir = base_dir / "config.json"
|
||||
os_auth_key = "env-auth"
|
||||
|
||||
config_dir.mkdir()
|
||||
|
||||
module = self.config_module
|
||||
old_base_dir = module.BASE_DIR
|
||||
old_data_dir = module.DATA_DIR
|
||||
old_config_file = module.CONFIG_FILE
|
||||
old_env_auth_key = module.os.environ.get("CHATGPT2API_AUTH_KEY")
|
||||
try:
|
||||
module.BASE_DIR = base_dir
|
||||
module.DATA_DIR = data_dir
|
||||
module.CONFIG_FILE = config_dir
|
||||
module.os.environ["CHATGPT2API_AUTH_KEY"] = os_auth_key
|
||||
|
||||
settings = module._load_settings()
|
||||
|
||||
self.assertEqual(settings.auth_key, os_auth_key)
|
||||
self.assertEqual(settings.refresh_account_interval_minute, 5)
|
||||
finally:
|
||||
module.BASE_DIR = old_base_dir
|
||||
module.DATA_DIR = old_data_dir
|
||||
module.CONFIG_FILE = old_config_file
|
||||
if old_env_auth_key is None:
|
||||
module.os.environ.pop("CHATGPT2API_AUTH_KEY", None)
|
||||
else:
|
||||
module.os.environ["CHATGPT2API_AUTH_KEY"] = old_env_auth_key
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,159 @@
|
||||
import json
|
||||
|
||||
import pytest
|
||||
|
||||
from services.storage.database_storage import (
|
||||
AccountModel,
|
||||
AuthKeyModel,
|
||||
DatabaseStorageBackend,
|
||||
)
|
||||
|
||||
|
||||
def _account_rows(backend: DatabaseStorageBackend) -> dict[str, AccountModel]:
|
||||
session = backend.Session()
|
||||
try:
|
||||
return {
|
||||
row.access_token: row
|
||||
for row in session.query(AccountModel).order_by(AccountModel.id).all()
|
||||
}
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
|
||||
def test_save_accounts_preserves_existing_rows_and_updates_only_changed_data(tmp_path):
|
||||
backend = DatabaseStorageBackend(f"sqlite:///{tmp_path / 'accounts.db'}")
|
||||
backend.save_accounts(
|
||||
[
|
||||
{"access_token": "token-a", "name": "A"},
|
||||
{"access_token": "token-b", "name": "B"},
|
||||
]
|
||||
)
|
||||
|
||||
before = _account_rows(backend)
|
||||
before_ids = {token: row.id for token, row in before.items()}
|
||||
before_b_data = before["token-b"].data
|
||||
|
||||
backend.save_accounts(
|
||||
[
|
||||
{"access_token": "token-b", "name": "B"},
|
||||
{"access_token": "token-a", "name": "A updated"},
|
||||
{"access_token": "token-c", "name": "C"},
|
||||
]
|
||||
)
|
||||
|
||||
after = _account_rows(backend)
|
||||
assert set(after) == {"token-a", "token-b", "token-c"}
|
||||
assert after["token-a"].id == before_ids["token-a"]
|
||||
assert after["token-b"].id == before_ids["token-b"]
|
||||
assert after["token-b"].data == before_b_data
|
||||
assert json.loads(after["token-a"].data)["name"] == "A updated"
|
||||
|
||||
|
||||
def test_save_accounts_deletes_only_rows_missing_from_new_snapshot(tmp_path):
|
||||
backend = DatabaseStorageBackend(f"sqlite:///{tmp_path / 'accounts.db'}")
|
||||
backend.save_accounts(
|
||||
[
|
||||
{"access_token": "token-a", "name": "A"},
|
||||
{"access_token": "token-b", "name": "B"},
|
||||
]
|
||||
)
|
||||
before = _account_rows(backend)
|
||||
token_b_id = before["token-b"].id
|
||||
|
||||
backend.save_accounts([{"access_token": "token-b", "name": "B"}])
|
||||
|
||||
after = _account_rows(backend)
|
||||
assert set(after) == {"token-b"}
|
||||
assert after["token-b"].id == token_b_id
|
||||
|
||||
|
||||
def test_save_accounts_rejects_duplicate_tokens_and_rolls_back(tmp_path):
|
||||
backend = DatabaseStorageBackend(f"sqlite:///{tmp_path / 'accounts.db'}")
|
||||
original = {"access_token": "token-a", "name": "A"}
|
||||
backend.save_accounts([original])
|
||||
|
||||
with pytest.raises(ValueError, match="Duplicate access_token") as exc_info:
|
||||
backend.save_accounts(
|
||||
[
|
||||
{"access_token": "token-a", "name": "first update"},
|
||||
{"access_token": "token-a", "name": "second update"},
|
||||
]
|
||||
)
|
||||
|
||||
assert "token-a" not in str(exc_info.value)
|
||||
assert backend.load_accounts() == [original]
|
||||
|
||||
|
||||
def test_save_accounts_rejects_duplicate_new_tokens_and_rolls_back(tmp_path):
|
||||
backend = DatabaseStorageBackend(f"sqlite:///{tmp_path / 'accounts.db'}")
|
||||
original = {"access_token": "token-a", "name": "A"}
|
||||
backend.save_accounts([original])
|
||||
|
||||
with pytest.raises(ValueError, match="Duplicate access_token") as exc_info:
|
||||
backend.save_accounts(
|
||||
[
|
||||
original,
|
||||
{"access_token": "token-b", "name": "first new"},
|
||||
{"access_token": "token-b", "name": "second new"},
|
||||
]
|
||||
)
|
||||
|
||||
assert "token-b" not in str(exc_info.value)
|
||||
assert backend.load_accounts() == [original]
|
||||
|
||||
|
||||
def test_save_auth_keys_preserves_ids_with_target_key_mapping(tmp_path):
|
||||
backend = DatabaseStorageBackend(f"sqlite:///{tmp_path / 'auth-keys.db'}")
|
||||
backend.save_auth_keys(
|
||||
[
|
||||
{"id": "key-a", "name": "A"},
|
||||
{"id": "key-b", "name": "B"},
|
||||
]
|
||||
)
|
||||
|
||||
session = backend.Session()
|
||||
try:
|
||||
before_ids = {
|
||||
row.key_id: row.id
|
||||
for row in session.query(AuthKeyModel).order_by(AuthKeyModel.id).all()
|
||||
}
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
backend.save_auth_keys(
|
||||
[
|
||||
{"id": "key-b", "name": "B"},
|
||||
{"id": "key-a", "name": "A updated"},
|
||||
{"id": "key-c", "name": "C"},
|
||||
]
|
||||
)
|
||||
|
||||
session = backend.Session()
|
||||
try:
|
||||
after = {
|
||||
row.key_id: row
|
||||
for row in session.query(AuthKeyModel).order_by(AuthKeyModel.id).all()
|
||||
}
|
||||
assert set(after) == {"key-a", "key-b", "key-c"}
|
||||
assert after["key-a"].id == before_ids["key-a"]
|
||||
assert after["key-b"].id == before_ids["key-b"]
|
||||
assert json.loads(after["key-a"].data)["name"] == "A updated"
|
||||
finally:
|
||||
session.close()
|
||||
|
||||
|
||||
def test_save_auth_keys_rejects_duplicate_ids_and_rolls_back(tmp_path):
|
||||
backend = DatabaseStorageBackend(f"sqlite:///{tmp_path / 'auth-keys.db'}")
|
||||
original = {"id": "key-a", "name": "A"}
|
||||
backend.save_auth_keys([original])
|
||||
|
||||
with pytest.raises(ValueError, match="Duplicate id") as exc_info:
|
||||
backend.save_auth_keys(
|
||||
[
|
||||
{"id": "key-a", "name": "first update"},
|
||||
{"id": "key-a", "name": "second update"},
|
||||
]
|
||||
)
|
||||
|
||||
assert "key-a" not in str(exc_info.value)
|
||||
assert backend.load_auth_keys() == [original]
|
||||
@@ -0,0 +1,12 @@
|
||||
from test.utils import post_json, save_image
|
||||
|
||||
|
||||
def main() -> None:
|
||||
prompt = "A cute orange cat sitting on a chair"
|
||||
result = post_json("/v1/images/generations", {"prompt": prompt, "model": "gpt-image-2", "n": 1})
|
||||
for index, item in enumerate(result["data"], start=1):
|
||||
print(save_image(item["b64_json"], f"generations_{index}"))
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,19 @@
|
||||
from test.utils import post_json
|
||||
|
||||
|
||||
def main() -> None:
|
||||
result = post_json(
|
||||
"/v1/images/generations",
|
||||
{
|
||||
"prompt": "一只橘猫坐在窗边,午后阳光,写实摄影",
|
||||
"model": "gpt-image-2",
|
||||
"n": 1,
|
||||
"response_format": "url",
|
||||
},
|
||||
)
|
||||
for item in result.get("data", []):
|
||||
print(item.get("url", ""))
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,58 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import time
|
||||
import urllib.error
|
||||
import urllib.parse
|
||||
import urllib.request
|
||||
from pathlib import Path
|
||||
from uuid import uuid4
|
||||
|
||||
BASE_URL = "http://127.0.0.1:8000"
|
||||
PROMPT = "生成一份 2026 年 Q2 电商运营复盘 PPT,8 页以内,商务科技风,包含销售、用户、渠道、广告、618 活动和 Q3 规划。"
|
||||
BASE64_IMAGES: list[str] = []
|
||||
TIMEOUT_SECS = 600
|
||||
POLL_INTERVAL_SECS = 5
|
||||
|
||||
|
||||
def request_json(method: str, path: str, payload: dict | None = None) -> dict:
|
||||
api_key = json.loads((Path(__file__).resolve().parents[1] / "config.json").read_text(encoding="utf-8"))["auth-key"]
|
||||
if not api_key.strip():
|
||||
raise ValueError("API_KEY is empty")
|
||||
data = None if payload is None else json.dumps(payload, ensure_ascii=False).encode()
|
||||
request = urllib.request.Request(
|
||||
BASE_URL.rstrip("/") + path,
|
||||
data=data,
|
||||
method=method,
|
||||
headers={"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"},
|
||||
)
|
||||
try:
|
||||
with urllib.request.urlopen(request, timeout=60) as response:
|
||||
return json.loads(response.read().decode())
|
||||
except urllib.error.HTTPError as exc:
|
||||
raise RuntimeError(exc.read().decode("utf-8", "replace")) from exc
|
||||
|
||||
|
||||
def main() -> None:
|
||||
task = request_json("POST", "/v1/ppt/generations", {
|
||||
"client_task_id": str(uuid4()),
|
||||
"prompt": PROMPT,
|
||||
"base64_images": BASE64_IMAGES,
|
||||
})
|
||||
task_id = str(task.get("taskId") or task.get("id") or "")
|
||||
if not task_id:
|
||||
raise RuntimeError(f"missing taskId: {task}")
|
||||
print(json.dumps(task, ensure_ascii=False, indent=2))
|
||||
deadline = time.time() + TIMEOUT_SECS
|
||||
while time.time() < deadline:
|
||||
time.sleep(POLL_INTERVAL_SECS)
|
||||
status = request_json("GET", "/v1/editable-file-tasks?ids=" + urllib.parse.quote(task_id))
|
||||
print(json.dumps(status, ensure_ascii=False, indent=2))
|
||||
item = (status.get("items") or [{}])[0]
|
||||
if item.get("status") in {"success", "error"}:
|
||||
return
|
||||
raise TimeoutError(f"task timeout: {task_id}")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,58 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import time
|
||||
import urllib.error
|
||||
import urllib.parse
|
||||
import urllib.request
|
||||
from pathlib import Path
|
||||
from uuid import uuid4
|
||||
|
||||
BASE_URL = "http://127.0.0.1:8000"
|
||||
PROMPT = "按原图位置拆分海报元素并合成可编辑 PSD,同时输出每个图层素材 zip。"
|
||||
BASE64_IMAGES: list[str] = []
|
||||
TIMEOUT_SECS = 600
|
||||
POLL_INTERVAL_SECS = 5
|
||||
|
||||
|
||||
def request_json(method: str, path: str, payload: dict | None = None) -> dict:
|
||||
api_key = json.loads((Path(__file__).resolve().parents[1] / "config.json").read_text(encoding="utf-8"))["auth-key"]
|
||||
if not api_key.strip():
|
||||
raise ValueError("API_KEY is empty")
|
||||
data = None if payload is None else json.dumps(payload, ensure_ascii=False).encode()
|
||||
request = urllib.request.Request(
|
||||
BASE_URL.rstrip("/") + path,
|
||||
data=data,
|
||||
method=method,
|
||||
headers={"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"},
|
||||
)
|
||||
try:
|
||||
with urllib.request.urlopen(request, timeout=60) as response:
|
||||
return json.loads(response.read().decode())
|
||||
except urllib.error.HTTPError as exc:
|
||||
raise RuntimeError(exc.read().decode("utf-8", "replace")) from exc
|
||||
|
||||
|
||||
def main() -> None:
|
||||
task = request_json("POST", "/v1/psd/generations", {
|
||||
"client_task_id": str(uuid4()),
|
||||
"prompt": PROMPT,
|
||||
"base64_images": BASE64_IMAGES,
|
||||
})
|
||||
task_id = str(task.get("taskId") or task.get("id") or "")
|
||||
if not task_id:
|
||||
raise RuntimeError(f"missing taskId: {task}")
|
||||
print(json.dumps(task, ensure_ascii=False, indent=2))
|
||||
deadline = time.time() + TIMEOUT_SECS
|
||||
while time.time() < deadline:
|
||||
time.sleep(POLL_INTERVAL_SECS)
|
||||
status = request_json("GET", "/v1/editable-file-tasks?ids=" + urllib.parse.quote(task_id))
|
||||
print(json.dumps(status, ensure_ascii=False, indent=2))
|
||||
item = (status.get("items") or [{}])[0]
|
||||
if item.get("status") in {"success", "error"}:
|
||||
return
|
||||
raise TimeoutError(f"task timeout: {task_id}")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,21 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
sys.path.insert(0, str(Path(__file__).resolve().parents[1]))
|
||||
|
||||
from services.openai_backend_api import OpenAIBackendAPI
|
||||
|
||||
|
||||
def main() -> None:
|
||||
ACCESS_TOKEN = ""
|
||||
PROMPT = "帮我去网上搜索关于chatgpt2api的相关项目"
|
||||
if not ACCESS_TOKEN.strip():
|
||||
raise ValueError("ACCESS_TOKEN is empty")
|
||||
print(json.dumps(OpenAIBackendAPI(ACCESS_TOKEN).search(PROMPT), ensure_ascii=False, indent=2))
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,15 @@
|
||||
from __future__ import annotations
|
||||
|
||||
from services.protocol import openai_v1_image_generations
|
||||
from test.utils import save_image
|
||||
|
||||
|
||||
def main() -> None:
|
||||
prompt = "一只橘猫坐在窗台上,午后阳光,写实摄影"
|
||||
data = openai_v1_image_generations.handle({"prompt": prompt, "model": "gpt-5-3", "n": 1})
|
||||
for index, item in enumerate(data["data"], start=1):
|
||||
print(save_image(item["b64_json"], f"image_{index}"))
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,43 @@
|
||||
import unittest
|
||||
from types import SimpleNamespace
|
||||
from unittest import mock
|
||||
|
||||
import api.support as api_support
|
||||
|
||||
|
||||
class ImageBaseUrlApiTests(unittest.TestCase):
|
||||
def setUp(self) -> None:
|
||||
self.fake_config = SimpleNamespace(base_url="https://public.example.com")
|
||||
patcher = mock.patch.object(api_support, "config", self.fake_config)
|
||||
patcher.start()
|
||||
self.addCleanup(patcher.stop)
|
||||
|
||||
def test_prefers_configured_base_url(self) -> None:
|
||||
request = SimpleNamespace(
|
||||
url=SimpleNamespace(scheme="http", netloc="127.0.0.1:8000"),
|
||||
headers={"host": "127.0.0.1:8000"},
|
||||
)
|
||||
|
||||
self.assertEqual(api_support.resolve_image_base_url(request), "https://public.example.com")
|
||||
|
||||
def test_falls_back_to_request_host(self) -> None:
|
||||
self.fake_config.base_url = ""
|
||||
request = SimpleNamespace(
|
||||
url=SimpleNamespace(scheme="http", netloc="127.0.0.1:8000"),
|
||||
headers={"host": "internal.example:9000"},
|
||||
)
|
||||
|
||||
self.assertEqual(api_support.resolve_image_base_url(request), "http://internal.example:9000")
|
||||
|
||||
def test_falls_back_to_request_netloc_when_host_missing(self) -> None:
|
||||
self.fake_config.base_url = ""
|
||||
request = SimpleNamespace(
|
||||
url=SimpleNamespace(scheme="https", netloc="public.example.com"),
|
||||
headers={},
|
||||
)
|
||||
|
||||
self.assertEqual(api_support.resolve_image_base_url(request), "https://public.example.com")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,33 @@
|
||||
import json
|
||||
import urllib.error
|
||||
import urllib.request
|
||||
|
||||
from test.utils import BASE_URL, load_auth_key
|
||||
|
||||
|
||||
def main() -> None:
|
||||
payload = {
|
||||
"prompt": "一只橘猫坐在窗台上,午后阳光,写实摄影",
|
||||
"model": "gpt-image-2",
|
||||
"n": 1,
|
||||
"response_format": "url",
|
||||
}
|
||||
request = urllib.request.Request(
|
||||
BASE_URL + "/v1/images/generations",
|
||||
data=json.dumps(payload).encode(),
|
||||
headers={"Content-Type": "application/json", "Authorization": f"Bearer {load_auth_key()}"},
|
||||
method="POST",
|
||||
)
|
||||
try:
|
||||
with urllib.request.urlopen(request) as response:
|
||||
body = response.read().decode()
|
||||
except urllib.error.HTTPError as error:
|
||||
body = error.read().decode()
|
||||
try:
|
||||
print(json.dumps(json.loads(body), ensure_ascii=False, indent=2))
|
||||
except json.JSONDecodeError:
|
||||
print(body)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,54 @@
|
||||
import threading
|
||||
import unittest
|
||||
|
||||
from services.config import config
|
||||
from services.protocol.conversation import _remove_image_conversation_later
|
||||
|
||||
|
||||
class FakeBackend:
|
||||
def __init__(self) -> None:
|
||||
self.called = threading.Event()
|
||||
|
||||
def delete_conversation(self, conversation_id: str) -> dict:
|
||||
self.called.set()
|
||||
return {}
|
||||
|
||||
|
||||
class RemoveImageConversationGateTests(unittest.TestCase):
|
||||
def setUp(self) -> None:
|
||||
self._saved = dict(config.data)
|
||||
|
||||
def tearDown(self) -> None:
|
||||
config.data = self._saved
|
||||
|
||||
def _removed(self, *, after_result: bool, always: bool, success: bool) -> bool:
|
||||
config.data = dict(
|
||||
self._saved,
|
||||
image_remove_conversation_after_result=after_result,
|
||||
image_remove_conversation_always=always,
|
||||
)
|
||||
backend = FakeBackend()
|
||||
_remove_image_conversation_later(backend, "conv-1", success=success)
|
||||
return backend.called.wait(2.0)
|
||||
|
||||
def test_both_off_never_removes(self) -> None:
|
||||
self.assertFalse(self._removed(after_result=False, always=False, success=True))
|
||||
self.assertFalse(self._removed(after_result=False, always=False, success=False))
|
||||
|
||||
def test_after_result_only_removes_on_success(self) -> None:
|
||||
self.assertTrue(self._removed(after_result=True, always=False, success=True))
|
||||
self.assertFalse(self._removed(after_result=True, always=False, success=False))
|
||||
|
||||
def test_always_removes_regardless_of_success(self) -> None:
|
||||
self.assertTrue(self._removed(after_result=False, always=True, success=True))
|
||||
self.assertTrue(self._removed(after_result=False, always=True, success=False))
|
||||
|
||||
def test_empty_conversation_id_is_noop(self) -> None:
|
||||
config.data = dict(self._saved, image_remove_conversation_always=True)
|
||||
backend = FakeBackend()
|
||||
_remove_image_conversation_later(backend, "", success=False)
|
||||
self.assertFalse(backend.called.wait(0.2))
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,139 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import tempfile
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
from unittest import mock
|
||||
|
||||
from PIL import Image
|
||||
|
||||
from services.image_storage_service import ImageStorageService
|
||||
|
||||
|
||||
def png_bytes() -> bytes:
|
||||
path = Path(tempfile.gettempdir()) / "chatgpt2api-test-image.png"
|
||||
Image.new("RGB", (2, 2), color=(255, 0, 0)).save(path, format="PNG")
|
||||
return path.read_bytes()
|
||||
|
||||
|
||||
class FakeWebDAVClient:
|
||||
uploaded: dict[str, bytes] = {}
|
||||
deleted: list[str] = []
|
||||
|
||||
def __init__(self, _settings):
|
||||
pass
|
||||
|
||||
def put(self, rel: str, payload: bytes) -> str:
|
||||
self.uploaded[rel] = payload
|
||||
return f"https://dav.example.test/{rel}"
|
||||
|
||||
def get(self, rel: str) -> bytes:
|
||||
return self.uploaded[rel]
|
||||
|
||||
def delete(self, rel: str) -> bool:
|
||||
self.deleted.append(rel)
|
||||
self.uploaded.pop(rel, None)
|
||||
return True
|
||||
|
||||
def test(self) -> dict[str, object]:
|
||||
self.put(".chatgpt2api_webdav_test.txt", b"chatgpt2api webdav test\n")
|
||||
self.delete(".chatgpt2api_webdav_test.txt")
|
||||
return {"ok": True, "status": 200, "error": None}
|
||||
|
||||
|
||||
class ImageStorageServiceTests(unittest.TestCase):
|
||||
def setUp(self):
|
||||
self.tmp = tempfile.TemporaryDirectory()
|
||||
self.addCleanup(self.tmp.cleanup)
|
||||
self.data_dir = Path(self.tmp.name)
|
||||
self.images_dir = self.data_dir / "images"
|
||||
self.settings = {
|
||||
"enabled": False,
|
||||
"mode": "local",
|
||||
"webdav_url": "",
|
||||
"webdav_username": "",
|
||||
"webdav_password": "",
|
||||
"webdav_root_path": "chatgpt2api/images",
|
||||
"public_base_url": "",
|
||||
}
|
||||
self.config_patcher = mock.patch("services.image_storage_service.config")
|
||||
self.mock_config = self.config_patcher.start()
|
||||
self.addCleanup(self.config_patcher.stop)
|
||||
self.mock_config.images_dir = self.images_dir
|
||||
self.mock_config.base_url = "http://app.test"
|
||||
self.mock_config.cleanup_old_images.return_value = 0
|
||||
self.mock_config.get_image_storage_settings.side_effect = lambda: dict(self.settings)
|
||||
FakeWebDAVClient.uploaded = {}
|
||||
FakeWebDAVClient.deleted = []
|
||||
|
||||
def service(self) -> ImageStorageService:
|
||||
return ImageStorageService(self.data_dir / "image_index.json")
|
||||
|
||||
def test_local_mode_saves_to_local_directory(self):
|
||||
stored = self.service().save(png_bytes(), "http://app.test")
|
||||
|
||||
self.assertEqual(stored.storage, "local")
|
||||
self.assertTrue((self.images_dir / stored.rel).is_file())
|
||||
self.assertEqual(stored.url, f"http://app.test/images/{stored.rel}")
|
||||
|
||||
def test_webdav_mode_uploads_without_local_file(self):
|
||||
self.settings.update({
|
||||
"enabled": True,
|
||||
"mode": "webdav",
|
||||
"webdav_url": "https://dav.example.test",
|
||||
"webdav_password": "secret",
|
||||
})
|
||||
with mock.patch("services.image_storage_service.WebDAVClient", FakeWebDAVClient):
|
||||
stored = self.service().save(png_bytes(), "http://app.test")
|
||||
payload = self.service().get_bytes(stored.rel)
|
||||
|
||||
self.assertEqual(stored.storage, "webdav")
|
||||
self.assertFalse((self.images_dir / stored.rel).exists())
|
||||
self.assertIn(stored.rel, FakeWebDAVClient.uploaded)
|
||||
self.assertEqual(payload, FakeWebDAVClient.uploaded[stored.rel])
|
||||
|
||||
def test_list_items_ignores_non_image_files(self):
|
||||
image = png_bytes()
|
||||
image_path = self.images_dir / "2026" / "05" / "07" / "sample.png"
|
||||
image_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
image_path.write_bytes(image)
|
||||
(self.images_dir / ".DS_Store").write_text("not an image", encoding="utf-8")
|
||||
(self.images_dir / "2026" / ".DS_Store").write_text("not an image", encoding="utf-8")
|
||||
|
||||
items = self.service().list_items("http://app.test")
|
||||
|
||||
self.assertEqual([item["rel"] for item in items], ["2026/05/07/sample.png"])
|
||||
self.assertEqual(items[0]["storage"], "local")
|
||||
|
||||
def test_both_mode_saves_to_local_and_webdav(self):
|
||||
self.settings.update({
|
||||
"enabled": True,
|
||||
"mode": "both",
|
||||
"webdav_url": "https://dav.example.test",
|
||||
"webdav_password": "secret",
|
||||
"public_base_url": "https://cdn.example.test/images",
|
||||
})
|
||||
with mock.patch("services.image_storage_service.WebDAVClient", FakeWebDAVClient):
|
||||
stored = self.service().save(png_bytes(), "http://app.test")
|
||||
|
||||
self.assertEqual(stored.storage, "both")
|
||||
self.assertTrue((self.images_dir / stored.rel).is_file())
|
||||
self.assertIn(stored.rel, FakeWebDAVClient.uploaded)
|
||||
self.assertEqual(stored.url, f"https://cdn.example.test/images/{stored.rel}")
|
||||
|
||||
def test_test_webdav_writes_and_deletes_probe_file(self):
|
||||
self.settings.update({
|
||||
"enabled": True,
|
||||
"mode": "webdav",
|
||||
"webdav_url": "https://dav.example.test",
|
||||
"webdav_password": "secret",
|
||||
})
|
||||
with mock.patch("services.image_storage_service.WebDAVClient", FakeWebDAVClient):
|
||||
result = self.service().test_webdav()
|
||||
|
||||
self.assertTrue(result["ok"])
|
||||
self.assertIn(".chatgpt2api_webdav_test.txt", FakeWebDAVClient.deleted)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,181 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import tempfile
|
||||
import time
|
||||
import threading
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
|
||||
from services.image_task_service import ImageTaskService
|
||||
|
||||
|
||||
OWNER = {"id": "owner-1", "name": "Owner", "role": "admin"}
|
||||
OTHER_OWNER = {"id": "owner-2", "name": "Other", "role": "user"}
|
||||
|
||||
|
||||
def wait_for_task(service: ImageTaskService, identity: dict[str, object], task_id: str, status: str, timeout: float = 2.0):
|
||||
deadline = time.time() + timeout
|
||||
last = None
|
||||
while time.time() < deadline:
|
||||
result = service.list_tasks(identity, [task_id])
|
||||
last = (result.get("items") or [None])[0]
|
||||
if last and last.get("status") == status:
|
||||
return last
|
||||
time.sleep(0.02)
|
||||
raise AssertionError(f"task {task_id} did not reach {status}, last={last}")
|
||||
|
||||
|
||||
class ImageTaskServiceTests(unittest.TestCase):
|
||||
def test_elapsed_time_includes_startup_and_stage_timings_survive_reload(self):
|
||||
entered = threading.Event()
|
||||
proceed = threading.Event()
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
path = Path(tmp_dir) / "tasks.json"
|
||||
|
||||
def handler(payload):
|
||||
payload["progress_callback"]("starting_generation")
|
||||
entered.set()
|
||||
if not proceed.wait(timeout=2):
|
||||
raise RuntimeError("test did not release task")
|
||||
payload["progress_callback"]("image_stream_resolve_start")
|
||||
return {"data": [{"url": "http://example.test/image.png"}]}
|
||||
|
||||
service = self.make_service(path, handler)
|
||||
service.submit_generation(OWNER, client_task_id="timed", prompt="cat", model="gpt-image-2", size=None, base_url="http://local.test")
|
||||
try:
|
||||
self.assertTrue(entered.wait(timeout=2))
|
||||
running = service.list_tasks(OWNER, ["timed"])["items"][0]
|
||||
self.assertIn("elapsed_secs", running)
|
||||
self.assertEqual(running["progress"], "starting_generation")
|
||||
started_ts = next(iter(service._tasks.values()))["started_ts"]
|
||||
finally:
|
||||
proceed.set()
|
||||
task = wait_for_task(service, OWNER, "timed", "success")
|
||||
self.assertEqual(next(iter(service._tasks.values()))["started_ts"], started_ts)
|
||||
self.assertIn("starting_generation", task["stage_durations_ms"])
|
||||
self.assertIn("image_stream_resolve_start", task["stage_durations_ms"])
|
||||
reloaded = self.make_service(path).list_tasks(OWNER, ["timed"])["items"][0]
|
||||
self.assertEqual(reloaded["stage_durations_ms"], task["stage_durations_ms"])
|
||||
|
||||
def make_service(self, path: Path, handler=None) -> ImageTaskService:
|
||||
return ImageTaskService(
|
||||
path,
|
||||
generation_handler=handler or (lambda _payload: {"data": [{"url": "http://example.test/image.png"}]}),
|
||||
edit_handler=handler or (lambda _payload: {"data": [{"url": "http://example.test/edit.png"}]}),
|
||||
retention_days_getter=lambda: 30,
|
||||
)
|
||||
|
||||
def test_duplicate_submit_uses_existing_task(self):
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
calls = 0
|
||||
|
||||
def handler(_payload):
|
||||
nonlocal calls
|
||||
calls += 1
|
||||
time.sleep(0.05)
|
||||
return {"data": [{"url": "http://example.test/image.png"}]}
|
||||
|
||||
service = self.make_service(Path(tmp_dir) / "image_tasks.json", handler)
|
||||
first = service.submit_generation(
|
||||
OWNER,
|
||||
client_task_id="task-1",
|
||||
prompt="cat",
|
||||
model="gpt-image-2",
|
||||
size=None,
|
||||
base_url="http://local.test",
|
||||
)
|
||||
second = service.submit_generation(
|
||||
OWNER,
|
||||
client_task_id="task-1",
|
||||
prompt="cat",
|
||||
model="gpt-image-2",
|
||||
size=None,
|
||||
base_url="http://local.test",
|
||||
)
|
||||
|
||||
self.assertEqual(first["id"], "task-1")
|
||||
self.assertEqual(second["id"], "task-1")
|
||||
task = wait_for_task(service, OWNER, "task-1", "success")
|
||||
self.assertEqual(task["data"][0]["url"], "http://example.test/image.png")
|
||||
self.assertEqual(calls, 1)
|
||||
|
||||
def test_different_owner_cannot_query_task(self):
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
service = self.make_service(Path(tmp_dir) / "image_tasks.json")
|
||||
service.submit_generation(
|
||||
OWNER,
|
||||
client_task_id="private-task",
|
||||
prompt="cat",
|
||||
model="gpt-image-2",
|
||||
size=None,
|
||||
base_url="http://local.test",
|
||||
)
|
||||
|
||||
wait_for_task(service, OWNER, "private-task", "success")
|
||||
result = service.list_tasks(OTHER_OWNER, ["private-task"])
|
||||
|
||||
self.assertEqual(result["items"], [])
|
||||
self.assertEqual(result["missing_ids"], ["private-task"])
|
||||
|
||||
def test_success_task_persists_to_new_service_instance(self):
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
path = Path(tmp_dir) / "image_tasks.json"
|
||||
service = self.make_service(path)
|
||||
service.submit_generation(
|
||||
OWNER,
|
||||
client_task_id="persisted-task",
|
||||
prompt="cat",
|
||||
model="gpt-image-2",
|
||||
size=None,
|
||||
base_url="http://local.test",
|
||||
)
|
||||
wait_for_task(service, OWNER, "persisted-task", "success")
|
||||
|
||||
reloaded = self.make_service(path)
|
||||
result = reloaded.list_tasks(OWNER, ["persisted-task"])
|
||||
|
||||
self.assertEqual(result["missing_ids"], [])
|
||||
self.assertEqual(result["items"][0]["status"], "success")
|
||||
self.assertEqual(result["items"][0]["data"][0]["url"], "http://example.test/image.png")
|
||||
|
||||
def test_startup_marks_unfinished_tasks_as_error(self):
|
||||
with tempfile.TemporaryDirectory() as tmp_dir:
|
||||
path = Path(tmp_dir) / "image_tasks.json"
|
||||
path.write_text(
|
||||
json.dumps(
|
||||
{
|
||||
"tasks": [
|
||||
{
|
||||
"id": "queued-task",
|
||||
"owner_id": "owner-1",
|
||||
"status": "queued",
|
||||
"mode": "generate",
|
||||
"model": "gpt-image-2",
|
||||
"created_at": "2099-01-01 00:00:00",
|
||||
"updated_at": "2099-01-01 00:00:00",
|
||||
},
|
||||
{
|
||||
"id": "running-task",
|
||||
"owner_id": "owner-1",
|
||||
"status": "running",
|
||||
"mode": "generate",
|
||||
"model": "gpt-image-2",
|
||||
"created_at": "2099-01-01 00:00:00",
|
||||
"updated_at": "2099-01-01 00:00:00",
|
||||
},
|
||||
]
|
||||
}
|
||||
),
|
||||
encoding="utf-8",
|
||||
)
|
||||
|
||||
service = self.make_service(path)
|
||||
result = service.list_tasks(OWNER, ["queued-task", "running-task"])
|
||||
|
||||
self.assertEqual([item["status"] for item in result["items"]], ["error", "error"])
|
||||
self.assertTrue(all("已中断" in item.get("error", "") for item in result["items"]))
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,131 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import base64
|
||||
import unittest
|
||||
from unittest import mock
|
||||
|
||||
from fastapi import FastAPI
|
||||
from fastapi.testclient import TestClient
|
||||
|
||||
import api.image_tasks as image_tasks_module
|
||||
|
||||
|
||||
AUTH_HEADERS = {"Authorization": "Bearer chatgpt2api"}
|
||||
PNG_BYTES = b"\x89PNG\r\n\x1a\n"
|
||||
DATA_IMAGE_URL = f"data:image/png;base64,{base64.b64encode(PNG_BYTES).decode('ascii')}"
|
||||
|
||||
|
||||
class FakeImageTaskService:
|
||||
def __init__(self):
|
||||
self.generation_calls = []
|
||||
self.edit_calls = []
|
||||
|
||||
def submit_generation(self, identity, **kwargs):
|
||||
self.generation_calls.append((identity, kwargs))
|
||||
return {
|
||||
"id": kwargs["client_task_id"],
|
||||
"status": "success",
|
||||
"mode": "generate",
|
||||
"created_at": "2026-01-01 00:00:00",
|
||||
"updated_at": "2026-01-01 00:00:00",
|
||||
"data": [{"url": f"{kwargs['base_url']}/images/fake.png"}],
|
||||
}
|
||||
|
||||
def submit_edit(self, identity, **kwargs):
|
||||
self.edit_calls.append((identity, kwargs))
|
||||
return {
|
||||
"id": kwargs["client_task_id"],
|
||||
"status": "queued",
|
||||
"mode": "edit",
|
||||
"created_at": "2026-01-01 00:00:00",
|
||||
"updated_at": "2026-01-01 00:00:00",
|
||||
}
|
||||
|
||||
def list_tasks(self, _identity, ids):
|
||||
return {
|
||||
"items": [
|
||||
{
|
||||
"id": task_id,
|
||||
"status": "success",
|
||||
"mode": "generate",
|
||||
"created_at": "2026-01-01 00:00:00",
|
||||
"updated_at": "2026-01-01 00:00:00",
|
||||
"data": [{"url": "http://testserver/images/fake.png"}],
|
||||
}
|
||||
for task_id in ids
|
||||
if task_id != "missing"
|
||||
],
|
||||
"missing_ids": [task_id for task_id in ids if task_id == "missing"],
|
||||
}
|
||||
|
||||
|
||||
class ImageTasksApiTests(unittest.TestCase):
|
||||
def setUp(self):
|
||||
self.fake_service = FakeImageTaskService()
|
||||
self.service_patcher = mock.patch.object(image_tasks_module, "image_task_service", self.fake_service)
|
||||
self.service_patcher.start()
|
||||
self.addCleanup(self.service_patcher.stop)
|
||||
app = FastAPI()
|
||||
app.include_router(image_tasks_module.create_router())
|
||||
self.client = TestClient(app)
|
||||
|
||||
def test_create_generation_task(self):
|
||||
response = self.client.post(
|
||||
"/api/image-tasks/generations",
|
||||
headers=AUTH_HEADERS,
|
||||
json={"client_task_id": "task-1", "prompt": "cat", "model": "gpt-image-2"},
|
||||
)
|
||||
|
||||
self.assertEqual(response.status_code, 200, response.text)
|
||||
payload = response.json()
|
||||
self.assertEqual(payload["id"], "task-1")
|
||||
self.assertEqual(payload["status"], "success")
|
||||
self.assertEqual(len(self.fake_service.generation_calls), 1)
|
||||
|
||||
def test_create_edit_task_accepts_multiple_images(self):
|
||||
"""测试图片编辑任务接口支持多个上传图片。"""
|
||||
response = self.client.post(
|
||||
"/api/image-tasks/edits",
|
||||
headers=AUTH_HEADERS,
|
||||
data={"client_task_id": "edit-1", "prompt": "edit", "model": "gpt-image-2"},
|
||||
files=[
|
||||
("image", ("one.png", b"one", "image/png")),
|
||||
("image", ("two.png", b"two", "image/png")),
|
||||
],
|
||||
)
|
||||
|
||||
self.assertEqual(response.status_code, 200, response.text)
|
||||
self.assertEqual(response.json()["id"], "edit-1")
|
||||
self.assertEqual(len(self.fake_service.edit_calls), 1)
|
||||
images = self.fake_service.edit_calls[0][1]["images"]
|
||||
self.assertEqual(len(images), 2)
|
||||
|
||||
def test_create_edit_task_accepts_image_url(self):
|
||||
"""测试图片编辑任务接口支持表单 image_url 引用。"""
|
||||
response = self.client.post(
|
||||
"/api/image-tasks/edits",
|
||||
headers=AUTH_HEADERS,
|
||||
data={
|
||||
"client_task_id": "edit-url-1",
|
||||
"prompt": "edit",
|
||||
"model": "gpt-image-2",
|
||||
"image_url": DATA_IMAGE_URL,
|
||||
},
|
||||
)
|
||||
|
||||
self.assertEqual(response.status_code, 200, response.text)
|
||||
self.assertEqual(len(self.fake_service.edit_calls), 1)
|
||||
images = self.fake_service.edit_calls[0][1]["images"]
|
||||
self.assertEqual(images, [(PNG_BYTES, "image_url.png", "image/png")])
|
||||
|
||||
def test_list_tasks_reports_missing_ids(self):
|
||||
response = self.client.get("/api/image-tasks?ids=task-1,missing", headers=AUTH_HEADERS)
|
||||
|
||||
self.assertEqual(response.status_code, 200, response.text)
|
||||
payload = response.json()
|
||||
self.assertEqual([item["id"] for item in payload["items"]], ["task-1"])
|
||||
self.assertEqual(payload["missing_ids"], ["missing"])
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,29 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import unittest
|
||||
|
||||
from utils.image_tokens import (
|
||||
count_image_input_tokens,
|
||||
count_image_output_tokens,
|
||||
)
|
||||
|
||||
|
||||
class ImageTokenTests(unittest.TestCase):
|
||||
def test_patch_token_examples_match_openai_docs(self):
|
||||
self.assertEqual(count_image_input_tokens(1024, 1024, "gpt-4.1-mini", "high"), 1659)
|
||||
self.assertEqual(count_image_input_tokens(1800, 2400, "gpt-4.1-mini", "high"), 2353)
|
||||
|
||||
def test_image_input_tokens_force_gpt_54_mini(self):
|
||||
expected = count_image_input_tokens(1024, 1024, "gpt-5.4-mini", "low")
|
||||
self.assertEqual(expected, 415)
|
||||
self.assertEqual(count_image_input_tokens(1024, 1024, "gpt-4o", "low"), expected)
|
||||
self.assertEqual(count_image_input_tokens(1024, 1024, "gpt-image-2", "low"), expected)
|
||||
|
||||
def test_image_output_tokens_scale_by_count_and_size(self):
|
||||
single = count_image_output_tokens("1024x1024", "auto", 1)
|
||||
self.assertGreater(single, 0)
|
||||
self.assertEqual(count_image_output_tokens("1024x1024", "auto", 2), single * 2)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,117 @@
|
||||
import errno
|
||||
import importlib.util
|
||||
import json
|
||||
import os
|
||||
import tempfile
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
from unittest.mock import patch
|
||||
|
||||
|
||||
SCRIPT_PATH = Path(__file__).resolve().parents[1] / "scripts" / "init_proxy_config.py"
|
||||
|
||||
|
||||
def load_script_module():
|
||||
spec = importlib.util.spec_from_file_location("init_proxy_config_under_test", SCRIPT_PATH)
|
||||
module = importlib.util.module_from_spec(spec)
|
||||
assert spec is not None and spec.loader is not None
|
||||
spec.loader.exec_module(module)
|
||||
return module
|
||||
|
||||
|
||||
class InitProxyConfigTests(unittest.TestCase):
|
||||
def test_creates_warp_defaults_when_proxy_runtime_missing(self) -> None:
|
||||
module = load_script_module()
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
path = Path(tmp) / "config.json"
|
||||
path.write_text(json.dumps({"auth-key": "secret", "proxy": ""}), encoding="utf-8")
|
||||
with patch.dict(os.environ, {"CHATGPT2API_CONFIG_FILE": str(path)}, clear=False):
|
||||
self.assertEqual(module.main(), 0)
|
||||
|
||||
data = json.loads(path.read_text(encoding="utf-8"))
|
||||
self.assertEqual(data["auth-key"], "secret")
|
||||
runtime = data["proxy_runtime"]
|
||||
self.assertTrue(runtime["enabled"])
|
||||
self.assertEqual(runtime["egress_mode"], "single_proxy")
|
||||
self.assertEqual(runtime["proxy_url"], "http://privoxy:8118")
|
||||
self.assertTrue(runtime["clearance"]["enabled"])
|
||||
self.assertEqual(runtime["clearance"]["mode"], "flaresolverr")
|
||||
self.assertEqual(runtime["clearance"]["flaresolverr_url"], "http://flaresolverr:8191")
|
||||
|
||||
def test_existing_custom_runtime_is_not_overwritten(self) -> None:
|
||||
module = load_script_module()
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
path = Path(tmp) / "config.json"
|
||||
path.write_text(
|
||||
json.dumps(
|
||||
{
|
||||
"auth-key": "secret",
|
||||
"proxy_runtime": {
|
||||
"enabled": False,
|
||||
"egress_mode": "single_proxy",
|
||||
"proxy_url": "http://custom.proxy:8080",
|
||||
"clearance": {
|
||||
"enabled": True,
|
||||
"mode": "manual",
|
||||
"cf_clearance": "manual-token",
|
||||
},
|
||||
},
|
||||
}
|
||||
),
|
||||
encoding="utf-8",
|
||||
)
|
||||
with patch.dict(os.environ, {"CHATGPT2API_CONFIG_FILE": str(path)}, clear=False):
|
||||
self.assertEqual(module.main(), 0)
|
||||
|
||||
runtime = json.loads(path.read_text(encoding="utf-8"))["proxy_runtime"]
|
||||
self.assertFalse(runtime["enabled"])
|
||||
self.assertEqual(runtime["proxy_url"], "http://custom.proxy:8080")
|
||||
self.assertEqual(runtime["clearance"]["mode"], "manual")
|
||||
self.assertEqual(runtime["clearance"]["cf_clearance"], "manual-token")
|
||||
self.assertIn("timeout_sec", runtime["clearance"])
|
||||
self.assertIn("reset_session_status_codes", runtime)
|
||||
|
||||
def test_env_can_disable_runtime_defaults_for_warp_compose(self) -> None:
|
||||
module = load_script_module()
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
path = Path(tmp) / "config.json"
|
||||
path.write_text(json.dumps({"auth-key": "secret"}), encoding="utf-8")
|
||||
with patch.dict(
|
||||
os.environ,
|
||||
{
|
||||
"CHATGPT2API_CONFIG_FILE": str(path),
|
||||
"CHATGPT2API_PROXY_RUNTIME_ENABLED": "false",
|
||||
"CHATGPT2API_PROXY_RUNTIME_CLEARANCE_ENABLED": "false",
|
||||
},
|
||||
clear=False,
|
||||
):
|
||||
self.assertEqual(module.main(), 0)
|
||||
|
||||
runtime = json.loads(path.read_text(encoding="utf-8"))["proxy_runtime"]
|
||||
self.assertFalse(runtime["enabled"])
|
||||
self.assertFalse(runtime["clearance"]["enabled"])
|
||||
self.assertEqual(runtime["clearance"]["mode"], "none")
|
||||
|
||||
def test_bind_mounted_config_file_falls_back_when_atomic_replace_is_busy(self) -> None:
|
||||
module = load_script_module()
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
path = Path(tmp) / "config.json"
|
||||
path.write_text(json.dumps({"auth-key": "secret", "proxy": ""}), encoding="utf-8")
|
||||
original_replace = Path.replace
|
||||
|
||||
def replace_with_ebusy(self: Path, target: Path) -> Path:
|
||||
if self.name == "config.json.tmp":
|
||||
raise OSError(errno.EBUSY, "Device or resource busy")
|
||||
return original_replace(self, target)
|
||||
|
||||
with patch.dict(os.environ, {"CHATGPT2API_CONFIG_FILE": str(path)}, clear=False):
|
||||
with patch.object(Path, "replace", replace_with_ebusy):
|
||||
self.assertEqual(module.main(), 0)
|
||||
|
||||
data = json.loads(path.read_text(encoding="utf-8"))
|
||||
self.assertTrue(data["proxy_runtime"]["enabled"])
|
||||
self.assertFalse(path.with_suffix(".json.tmp").exists())
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,150 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import tempfile
|
||||
import unittest
|
||||
from concurrent.futures import ThreadPoolExecutor
|
||||
from pathlib import Path
|
||||
|
||||
from services.account_service import AccountService
|
||||
from services.model_service import ModelCatalogService
|
||||
from services.storage.json_storage import JSONStorageBackend
|
||||
|
||||
|
||||
def model_list(*model_ids: str) -> dict:
|
||||
return {
|
||||
"object": "list",
|
||||
"data": [
|
||||
{
|
||||
"id": model_id,
|
||||
"object": "model",
|
||||
"created": 0,
|
||||
"owned_by": "chatgpt",
|
||||
"permission": [],
|
||||
"root": model_id,
|
||||
"parent": None,
|
||||
}
|
||||
for model_id in model_ids
|
||||
],
|
||||
}
|
||||
|
||||
|
||||
class FakeBackend:
|
||||
def __init__(self, access_token: str, outcomes: dict[str, object], calls: list[str], closed: list[str]) -> None:
|
||||
self.access_token = access_token
|
||||
self._outcomes = outcomes
|
||||
self._calls = calls
|
||||
self._closed = closed
|
||||
|
||||
def list_models(self) -> dict:
|
||||
self._calls.append(self.access_token)
|
||||
outcome = self._outcomes[self.access_token]
|
||||
if isinstance(outcome, Exception):
|
||||
raise outcome
|
||||
return outcome
|
||||
|
||||
def close(self) -> None:
|
||||
self._closed.append(self.access_token)
|
||||
|
||||
|
||||
class ModelCatalogServiceTests(unittest.TestCase):
|
||||
def setUp(self) -> None:
|
||||
self.temp_dir = tempfile.TemporaryDirectory()
|
||||
self.addCleanup(self.temp_dir.cleanup)
|
||||
self.accounts = AccountService(
|
||||
JSONStorageBackend(Path(self.temp_dir.name) / "accounts.json")
|
||||
)
|
||||
self.accounts.add_account_items(
|
||||
[
|
||||
{"access_token": "free-bad", "type": "free", "status": "正常"},
|
||||
{"access_token": "free-good", "type": "FREE", "status": "正常"},
|
||||
{"access_token": "plus", "type": "Plus", "status": "正常"},
|
||||
{"access_token": "pro", "type": "pro", "status": "正常"},
|
||||
{"access_token": "team-disabled", "type": "Team", "status": "禁用"},
|
||||
]
|
||||
)
|
||||
self.accounts.refresh_access_token = lambda token, **_kwargs: token
|
||||
self.now = 1000.0
|
||||
self.calls: list[str] = []
|
||||
self.closed: list[str] = []
|
||||
self.outcomes: dict[str, object] = {
|
||||
"": model_list("anon", "shared"),
|
||||
"free-bad": RuntimeError("expired"),
|
||||
"free-good": model_list("free-only", "shared"),
|
||||
"plus": model_list("plus-only", "shared"),
|
||||
"pro": model_list("pro-only"),
|
||||
}
|
||||
self.catalog = ModelCatalogService(
|
||||
self.accounts,
|
||||
backend_factory=lambda access_token="": FakeBackend(
|
||||
access_token, self.outcomes, self.calls, self.closed
|
||||
),
|
||||
cache_ttl_seconds=300,
|
||||
clock=lambda: self.now,
|
||||
)
|
||||
|
||||
def test_catalog_unions_anonymous_and_each_active_account_type(self) -> None:
|
||||
result = self.catalog.list_models()
|
||||
|
||||
self.assertEqual(
|
||||
[item["id"] for item in result["data"]],
|
||||
["anon", "free-only", "plus-only", "pro-only", "shared"],
|
||||
)
|
||||
self.assertCountEqual(self.calls, ["", "free-bad", "free-good", "plus", "pro"])
|
||||
self.assertCountEqual(self.closed, self.calls)
|
||||
self.assertNotIn("team-disabled", self.calls)
|
||||
|
||||
pro_route = self.catalog.route_for_model("pro-only")
|
||||
self.assertEqual(pro_route.account_types, frozenset({"Pro"}))
|
||||
self.assertFalse(pro_route.allow_anonymous)
|
||||
|
||||
shared_route = self.catalog.route_for_model("shared")
|
||||
self.assertEqual(shared_route.account_types, frozenset({"free", "Plus"}))
|
||||
self.assertTrue(shared_route.allow_anonymous)
|
||||
|
||||
def test_catalog_is_cached_until_ttl_expires(self) -> None:
|
||||
self.catalog.list_models()
|
||||
self.catalog.list_models()
|
||||
self.catalog.route_for_model("pro-only")
|
||||
|
||||
self.assertEqual(self.calls.count("pro"), 1)
|
||||
self.assertEqual(self.calls.count(""), 1)
|
||||
|
||||
def test_concurrent_readers_share_one_catalog_refresh(self) -> None:
|
||||
with ThreadPoolExecutor(max_workers=8) as executor:
|
||||
results = list(executor.map(lambda _index: self.catalog.list_models(), range(8)))
|
||||
|
||||
self.assertTrue(all(result == results[0] for result in results))
|
||||
self.assertEqual(self.calls.count(""), 1)
|
||||
self.assertEqual(self.calls.count("free-good"), 1)
|
||||
self.assertEqual(self.calls.count("plus"), 1)
|
||||
self.assertEqual(self.calls.count("pro"), 1)
|
||||
|
||||
def test_failed_refresh_keeps_last_successful_models_for_that_type(self) -> None:
|
||||
self.catalog.list_models()
|
||||
self.outcomes["pro"] = RuntimeError("temporary upstream failure")
|
||||
self.now += 301
|
||||
|
||||
result = self.catalog.list_models()
|
||||
|
||||
self.assertIn("pro-only", {item["id"] for item in result["data"]})
|
||||
self.assertEqual(
|
||||
self.catalog.route_for_model("pro-only").account_types,
|
||||
frozenset({"Pro"}),
|
||||
)
|
||||
self.assertEqual(self.calls.count("pro"), 2)
|
||||
|
||||
def test_removed_account_type_drops_its_stale_capabilities(self) -> None:
|
||||
self.catalog.list_models()
|
||||
self.accounts.delete_accounts(["pro"])
|
||||
|
||||
result = self.catalog.list_models()
|
||||
|
||||
self.assertNotIn("pro-only", {item["id"] for item in result["data"]})
|
||||
self.assertEqual(
|
||||
self.catalog.route_for_model("pro-only").account_types,
|
||||
frozenset(),
|
||||
)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,185 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import base64
|
||||
import unittest
|
||||
from unittest import mock
|
||||
|
||||
from services.config import config
|
||||
from services.openai_backend_api import OpenAIBackendAPI
|
||||
from services.protocol.conversation import ImageOutput, extract_conversation_ids
|
||||
from services.protocol.openai_v1_response import stream_image_response
|
||||
|
||||
|
||||
def _conversation(file_ids: list[str], sediment_ids: list[str] | None = None) -> dict:
|
||||
parts: list[object] = [
|
||||
{"content_type": "image_asset_pointer", "asset_pointer": f"file-service://{file_id}"}
|
||||
for file_id in file_ids
|
||||
]
|
||||
parts.extend(f"sediment://{sediment_id}" for sediment_id in (sediment_ids or []))
|
||||
return {
|
||||
"mapping": {
|
||||
"tool": {
|
||||
"message": {
|
||||
"author": {"role": "tool"},
|
||||
"create_time": 1,
|
||||
"metadata": {"async_task_type": "image_gen"},
|
||||
"content": {"content_type": "multimodal_text", "parts": parts},
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
class FakeBackend(OpenAIBackendAPI):
|
||||
def __init__(self, conversations: list[dict] | None = None) -> None:
|
||||
self.conversations = conversations or []
|
||||
self.calls = 0
|
||||
self.file_urls: dict[str, str] = {}
|
||||
self.sediment_urls: dict[str, str] = {}
|
||||
|
||||
def _get_conversation(self, conversation_id: str) -> dict:
|
||||
self.calls += 1
|
||||
index = min(self.calls - 1, len(self.conversations) - 1)
|
||||
return self.conversations[index]
|
||||
|
||||
def _get_file_download_url(self, file_id: str) -> str:
|
||||
return self.file_urls.get(file_id, "")
|
||||
|
||||
def _get_attachment_download_url(self, conversation_id: str, attachment_id: str) -> str:
|
||||
return self.sediment_urls.get(attachment_id, "")
|
||||
|
||||
|
||||
class MultiImageResultTests(unittest.TestCase):
|
||||
def test_stream_id_extractor_keeps_full_file_ids(self) -> None:
|
||||
payload = (
|
||||
'{"conversation_id":"conv-1"} '
|
||||
'file-service://file-first_123-extra sediment://sed-second_456-extra'
|
||||
)
|
||||
|
||||
conversation_id, file_ids, sediment_ids = extract_conversation_ids(payload)
|
||||
|
||||
self.assertEqual(conversation_id, "conv-1")
|
||||
self.assertEqual(file_ids, ["file-first_123-extra"])
|
||||
self.assertEqual(sediment_ids, ["sed-second_456-extra"])
|
||||
|
||||
def test_conversation_record_extractor_finds_all_generated_assets(self) -> None:
|
||||
backend = FakeBackend()
|
||||
conversation = {
|
||||
"mapping": {
|
||||
"user": {
|
||||
"message": {
|
||||
"author": {"role": "user"},
|
||||
"content": {"parts": ["file-service://file-user-input"]},
|
||||
}
|
||||
},
|
||||
"tool": {
|
||||
"message": {
|
||||
"author": {"role": "tool"},
|
||||
"create_time": 1,
|
||||
"metadata": {
|
||||
"async_task_type": "image_gen",
|
||||
"nested": {"asset": "file-service://file-second"},
|
||||
},
|
||||
"content": {
|
||||
"content_type": "text",
|
||||
"parts": [
|
||||
{"content_type": "image_asset_pointer", "asset_pointer": "file-service://file-first"},
|
||||
"sediment://sed-first",
|
||||
],
|
||||
},
|
||||
}
|
||||
},
|
||||
"assistant": {
|
||||
"message": {
|
||||
"author": {"role": "assistant"},
|
||||
"create_time": 2,
|
||||
"metadata": {},
|
||||
"content": {
|
||||
"parts": [
|
||||
{"content_type": "image_asset_pointer", "asset_pointer": "file-service://file-third"}
|
||||
]
|
||||
},
|
||||
}
|
||||
},
|
||||
}
|
||||
}
|
||||
|
||||
records = backend._extract_image_tool_records(conversation)
|
||||
file_ids = [file_id for record in records for file_id in record["file_ids"]]
|
||||
sediment_ids = [sediment_id for record in records for sediment_id in record["sediment_ids"]]
|
||||
|
||||
self.assertEqual(file_ids, ["file-first", "file-second", "file-third"])
|
||||
self.assertEqual(sediment_ids, ["sed-first"])
|
||||
|
||||
def test_poll_waits_for_generated_asset_ids_to_settle(self) -> None:
|
||||
backend = FakeBackend([
|
||||
_conversation(["file-one"]),
|
||||
_conversation(["file-one", "file-two"], ["sed-one"]),
|
||||
_conversation(["file-one", "file-two"], ["sed-one"]),
|
||||
])
|
||||
|
||||
with (
|
||||
mock.patch.dict(config.data, {
|
||||
"image_poll_initial_wait_secs": 0,
|
||||
"image_poll_interval_secs": 0.5,
|
||||
"image_check_before_hit_enabled": True,
|
||||
"image_settle_enabled": True,
|
||||
}),
|
||||
mock.patch("services.openai_backend_api.time.sleep", lambda _seconds: None),
|
||||
):
|
||||
file_ids, sediment_ids = backend._poll_image_results("conv-1", timeout_secs=10)
|
||||
|
||||
self.assertEqual(file_ids, ["file-one", "file-two"])
|
||||
self.assertEqual(sediment_ids, ["sed-one"])
|
||||
self.assertEqual(backend.calls, 3)
|
||||
|
||||
def test_resolver_uses_file_and_sediment_urls(self) -> None:
|
||||
backend = FakeBackend()
|
||||
backend.file_urls = {"file-one": "https://files.test/one.png"}
|
||||
backend.sediment_urls = {
|
||||
"sed-one": "https://attachments.test/one.png",
|
||||
"sed-two": "https://attachments.test/two.png",
|
||||
}
|
||||
|
||||
urls = backend._resolve_image_urls("conv-1", ["file-one"], ["sed-one", "sed-two"])
|
||||
|
||||
self.assertEqual(urls, [
|
||||
"https://files.test/one.png",
|
||||
"https://attachments.test/one.png",
|
||||
"https://attachments.test/two.png",
|
||||
])
|
||||
|
||||
def test_resolver_keeps_stream_ids_when_poll_extension_fails(self) -> None:
|
||||
backend = FakeBackend()
|
||||
backend.file_urls = {"file-one": "https://files.test/one.png"}
|
||||
backend._get_conversation = mock.Mock(side_effect=RuntimeError("poll failed"))
|
||||
|
||||
with mock.patch("services.openai_backend_api.time.sleep", lambda _seconds: None):
|
||||
urls = backend.resolve_conversation_image_urls("conv-1", ["file-one"], [], poll=True)
|
||||
|
||||
self.assertEqual(urls, ["https://files.test/one.png"])
|
||||
|
||||
def test_responses_stream_emits_all_image_output_items(self) -> None:
|
||||
first = base64.b64encode(b"first").decode("ascii")
|
||||
second = base64.b64encode(b"second").decode("ascii")
|
||||
events = list(stream_image_response(
|
||||
[ImageOutput(
|
||||
kind="result",
|
||||
model="gpt-image-2",
|
||||
index=1,
|
||||
total=1,
|
||||
data=[{"b64_json": first}, {"b64_json": second}],
|
||||
)],
|
||||
"draw two options",
|
||||
"gpt-image-2",
|
||||
))
|
||||
|
||||
done_events = [event for event in events if event.get("type") == "response.output_item.done"]
|
||||
completed = next(event["response"] for event in events if event.get("type") == "response.completed")
|
||||
|
||||
self.assertEqual([event["output_index"] for event in done_events], [0, 1])
|
||||
self.assertEqual([item["result"] for item in completed["output"]], [first, second])
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,180 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import copy
|
||||
import unittest
|
||||
from unittest import mock
|
||||
|
||||
from fastapi import FastAPI
|
||||
from fastapi.testclient import TestClient
|
||||
|
||||
import api.system as system_module
|
||||
from services.config import DEFAULT_PROXY_RUNTIME
|
||||
|
||||
|
||||
AUTH_HEADERS = {"Authorization": "Bearer chatgpt2api"}
|
||||
|
||||
|
||||
class FakeStorage:
|
||||
def get_backend_info(self) -> dict[str, object]:
|
||||
return {"type": "json"}
|
||||
|
||||
def health_check(self) -> dict[str, object]:
|
||||
return {"ok": True}
|
||||
|
||||
|
||||
class FakeConfig:
|
||||
def __init__(self) -> None:
|
||||
self.data: dict[str, object] = {
|
||||
"proxy": "",
|
||||
"proxy_runtime": copy.deepcopy(DEFAULT_PROXY_RUNTIME),
|
||||
}
|
||||
|
||||
def get(self) -> dict[str, object]:
|
||||
return copy.deepcopy(self.data)
|
||||
|
||||
def update(self, updates: dict[str, object]) -> dict[str, object]:
|
||||
self.data.update(copy.deepcopy(updates))
|
||||
return self.get()
|
||||
|
||||
def get_proxy_settings(self) -> str:
|
||||
return str(self.data.get("proxy") or "").strip()
|
||||
|
||||
def get_proxy_runtime_settings(self) -> dict[str, object]:
|
||||
return copy.deepcopy(self.data["proxy_runtime"]) # type: ignore[index]
|
||||
|
||||
def get_public_proxy_runtime_settings(self) -> dict[str, object]:
|
||||
return self.get_proxy_runtime_settings()
|
||||
|
||||
def get_storage_backend(self) -> FakeStorage:
|
||||
return FakeStorage()
|
||||
|
||||
|
||||
class FakeProxySettings:
|
||||
def get_runtime_status(self) -> dict[str, object]:
|
||||
return {
|
||||
"enabled": True,
|
||||
"egress_mode": "single_proxy",
|
||||
"proxy_source": "proxy_runtime",
|
||||
"has_proxy": True,
|
||||
"clearance_enabled": True,
|
||||
"clearance_mode": "flaresolverr",
|
||||
"has_clearance_bundle": False,
|
||||
"cached_clearance_hosts": [],
|
||||
}
|
||||
|
||||
|
||||
class FakeAccountService:
|
||||
def get_stats(self) -> dict[str, object]:
|
||||
return {
|
||||
"total": 1,
|
||||
"cumulative_total": 1,
|
||||
"active": 1,
|
||||
"total_quota": 1,
|
||||
"limited": 0,
|
||||
"abnormal": 0,
|
||||
"disabled": 0,
|
||||
"total_success": 0,
|
||||
"total_fail": 0,
|
||||
"by_type": {"web": 1},
|
||||
}
|
||||
|
||||
|
||||
class ProxyRuntimeApiTests(unittest.TestCase):
|
||||
def setUp(self) -> None:
|
||||
self.fake_config = FakeConfig()
|
||||
self.fake_proxy_settings = FakeProxySettings()
|
||||
self.test_proxy_calls: list[str] = []
|
||||
self.test_clearance_calls: list[str] = []
|
||||
|
||||
def fake_test_proxy(url: str = "") -> dict[str, object]:
|
||||
self.test_proxy_calls.append(url)
|
||||
return {
|
||||
"ok": True,
|
||||
"status": 204,
|
||||
"latency_ms": 12,
|
||||
"error": None,
|
||||
"proxy_source": "proxy_runtime" if not url else "input",
|
||||
"has_proxy": True,
|
||||
}
|
||||
|
||||
def fake_test_clearance(target_url: str = "https://chatgpt.com") -> dict[str, object]:
|
||||
self.test_clearance_calls.append(target_url)
|
||||
return {
|
||||
"ok": True,
|
||||
"status": "ok",
|
||||
"latency_ms": 34,
|
||||
"has_cookies": True,
|
||||
"user_agent": "Flare UA",
|
||||
"error": None,
|
||||
"runtime": self.fake_proxy_settings.get_runtime_status(),
|
||||
}
|
||||
|
||||
self.patchers = [
|
||||
mock.patch.object(system_module, "config", self.fake_config),
|
||||
mock.patch.object(system_module, "require_admin", lambda _authorization: {"role": "admin"}),
|
||||
mock.patch.object(system_module, "test_proxy", fake_test_proxy),
|
||||
mock.patch.object(system_module, "test_clearance", fake_test_clearance, create=True),
|
||||
mock.patch.object(system_module, "proxy_settings", self.fake_proxy_settings, create=True),
|
||||
mock.patch("services.account_service.account_service", FakeAccountService()),
|
||||
]
|
||||
for patcher in self.patchers:
|
||||
patcher.start()
|
||||
self.addCleanup(patcher.stop)
|
||||
app = FastAPI()
|
||||
app.include_router(system_module.create_router("9.9.9-test"))
|
||||
self.client = TestClient(app)
|
||||
|
||||
def test_proxy_test_can_use_active_runtime_when_url_is_empty(self) -> None:
|
||||
response = self.client.post("/api/proxy/test", headers=AUTH_HEADERS, json={})
|
||||
|
||||
self.assertEqual(response.status_code, 200, response.text)
|
||||
payload = response.json()["result"]
|
||||
self.assertTrue(payload["ok"])
|
||||
self.assertEqual(payload["proxy_source"], "proxy_runtime")
|
||||
self.assertEqual(self.test_proxy_calls, [""])
|
||||
|
||||
def test_proxy_runtime_endpoint_reads_and_updates_runtime_config(self) -> None:
|
||||
get_response = self.client.get("/api/proxy/runtime", headers=AUTH_HEADERS)
|
||||
self.assertEqual(get_response.status_code, 200, get_response.text)
|
||||
self.assertEqual(get_response.json()["runtime"]["enabled"], False)
|
||||
self.assertEqual(get_response.json()["status"]["proxy_source"], "proxy_runtime")
|
||||
|
||||
runtime = copy.deepcopy(DEFAULT_PROXY_RUNTIME)
|
||||
runtime["enabled"] = True
|
||||
runtime["egress_mode"] = "single_proxy"
|
||||
runtime["proxy_url"] = "http://privoxy:8118"
|
||||
runtime["clearance"]["enabled"] = True # type: ignore[index]
|
||||
runtime["clearance"]["mode"] = "flaresolverr" # type: ignore[index]
|
||||
runtime["clearance"]["flaresolverr_url"] = "http://flaresolverr:8191" # type: ignore[index]
|
||||
|
||||
post_response = self.client.post("/api/proxy/runtime", headers=AUTH_HEADERS, json=runtime)
|
||||
|
||||
self.assertEqual(post_response.status_code, 200, post_response.text)
|
||||
self.assertTrue(post_response.json()["runtime"]["enabled"])
|
||||
self.assertEqual(self.fake_config.data["proxy_runtime"], runtime)
|
||||
|
||||
def test_clearance_test_endpoint_runs_clearance_refresh_without_returning_cookie_values(self) -> None:
|
||||
response = self.client.post(
|
||||
"/api/proxy/clearance/test",
|
||||
headers=AUTH_HEADERS,
|
||||
json={"target_url": "https://chatgpt.com/backend-api/models"},
|
||||
)
|
||||
|
||||
self.assertEqual(response.status_code, 200, response.text)
|
||||
payload = response.json()["result"]
|
||||
self.assertTrue(payload["ok"])
|
||||
self.assertTrue(payload["has_cookies"])
|
||||
self.assertNotIn("cf_clearance", response.text)
|
||||
self.assertEqual(self.test_clearance_calls, ["https://chatgpt.com/backend-api/models"])
|
||||
|
||||
def test_health_json_includes_proxy_runtime_status(self) -> None:
|
||||
response = self.client.get("/health?format=json")
|
||||
|
||||
self.assertEqual(response.status_code, 200, response.text)
|
||||
payload = response.json()
|
||||
self.assertEqual(payload["version"], "9.9.9-test")
|
||||
self.assertEqual(payload["proxy_runtime"]["clearance_mode"], "flaresolverr")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,220 @@
|
||||
import copy
|
||||
import json
|
||||
import math
|
||||
import tempfile
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
|
||||
from services.config import (
|
||||
DEFAULT_PROXY_RUNTIME,
|
||||
ConfigStore,
|
||||
_normalize_proxy_runtime_settings,
|
||||
)
|
||||
|
||||
|
||||
class ProxyRuntimeConfigTests(unittest.TestCase):
|
||||
def _make_store(self, initial: dict[str, object] | None = None) -> tuple[tempfile.TemporaryDirectory[str], ConfigStore]:
|
||||
tmp_dir = tempfile.TemporaryDirectory()
|
||||
path = Path(tmp_dir.name) / "config.json"
|
||||
data = {"auth-key": "test-auth"}
|
||||
if initial:
|
||||
data.update(initial)
|
||||
path.write_text(json.dumps(data), encoding="utf-8")
|
||||
return tmp_dir, ConfigStore(path)
|
||||
|
||||
def test_defaults_are_safe_and_included_in_public_config(self) -> None:
|
||||
tmp_dir, store = self._make_store({"proxy": " http://legacy.example:8080 "})
|
||||
with tmp_dir:
|
||||
expected_default = copy.deepcopy(DEFAULT_PROXY_RUNTIME)
|
||||
runtime = store.get_proxy_runtime_settings()
|
||||
self.assertEqual(runtime, expected_default)
|
||||
self.assertEqual(store.get_proxy_settings(), "http://legacy.example:8080")
|
||||
|
||||
expected_public = copy.deepcopy(expected_default)
|
||||
expected_public["clearance"]["has_cf_cookies"] = False
|
||||
expected_public["clearance"]["has_cf_clearance"] = False
|
||||
public_config = store.get()
|
||||
self.assertEqual(public_config["proxy"], " http://legacy.example:8080 ")
|
||||
self.assertEqual(public_config["proxy_runtime"], expected_public)
|
||||
self.assertNotIn("auth-key", public_config)
|
||||
|
||||
runtime["enabled"] = True
|
||||
runtime["clearance"]["enabled"] = True
|
||||
self.assertEqual(DEFAULT_PROXY_RUNTIME, expected_default)
|
||||
self.assertEqual(store.get_proxy_runtime_settings(), expected_default)
|
||||
|
||||
def test_normalize_proxy_runtime_sanitizes_invalid_values(self) -> None:
|
||||
normalized = _normalize_proxy_runtime_settings(
|
||||
{
|
||||
"enabled": "yes",
|
||||
"egress_mode": "tor",
|
||||
"proxy_url": " http://proxy.example:8080 ",
|
||||
"resource_proxy_url": " socks5://resource.example:1080 ",
|
||||
"skip_ssl_verify": "on",
|
||||
"reset_session_status_codes": ["403", 429, 99, 600, "bad", None, True],
|
||||
"clearance": {
|
||||
"enabled": "0",
|
||||
"mode": "manual",
|
||||
"cf_cookies": " a=b; c=d ",
|
||||
"cf_clearance": " token ",
|
||||
"user_agent": " Custom UA ",
|
||||
"browser": " firefox ",
|
||||
"flaresolverr_url": " http://flare.example/ ",
|
||||
"timeout_sec": 0,
|
||||
"refresh_interval": 59,
|
||||
"warm_up_on_start": "true",
|
||||
},
|
||||
}
|
||||
)
|
||||
|
||||
self.assertTrue(normalized["enabled"])
|
||||
self.assertEqual(normalized["egress_mode"], "direct")
|
||||
self.assertEqual(normalized["proxy_url"], "http://proxy.example:8080")
|
||||
self.assertEqual(normalized["resource_proxy_url"], "socks5://resource.example:1080")
|
||||
self.assertTrue(normalized["skip_ssl_verify"])
|
||||
self.assertEqual(normalized["reset_session_status_codes"], [403, 429])
|
||||
|
||||
clearance = normalized["clearance"]
|
||||
self.assertFalse(clearance["enabled"])
|
||||
self.assertEqual(clearance["mode"], "manual")
|
||||
self.assertEqual(clearance["cf_cookies"], "a=b; c=d")
|
||||
self.assertEqual(clearance["cf_clearance"], "token")
|
||||
self.assertEqual(clearance["user_agent"], "Custom UA")
|
||||
self.assertEqual(clearance["browser"], "firefox")
|
||||
self.assertEqual(clearance["flaresolverr_url"], "http://flare.example/")
|
||||
self.assertEqual(clearance["timeout_sec"], 1)
|
||||
self.assertEqual(clearance["refresh_interval"], 60)
|
||||
self.assertTrue(clearance["warm_up_on_start"])
|
||||
|
||||
def test_normalize_proxy_runtime_uses_defaults_for_missing_or_empty_values(self) -> None:
|
||||
self.assertEqual(_normalize_proxy_runtime_settings(None), DEFAULT_PROXY_RUNTIME)
|
||||
self.assertEqual(
|
||||
_normalize_proxy_runtime_settings(
|
||||
{
|
||||
"egress_mode": "single_proxy",
|
||||
"reset_session_status_codes": ["bad", 99, 600],
|
||||
"clearance": {
|
||||
"enabled": True,
|
||||
"mode": "invalid",
|
||||
"user_agent": "",
|
||||
"browser": "",
|
||||
"timeout_sec": "bad",
|
||||
"refresh_interval": "bad",
|
||||
},
|
||||
}
|
||||
),
|
||||
{
|
||||
**DEFAULT_PROXY_RUNTIME,
|
||||
"egress_mode": "single_proxy",
|
||||
"reset_session_status_codes": [403],
|
||||
"clearance": {
|
||||
**DEFAULT_PROXY_RUNTIME["clearance"],
|
||||
"enabled": True,
|
||||
"mode": "none",
|
||||
},
|
||||
},
|
||||
)
|
||||
|
||||
def test_malformed_proxy_runtime_values_fall_back_safely(self) -> None:
|
||||
normalized = _normalize_proxy_runtime_settings(
|
||||
{
|
||||
"enabled": "maybe",
|
||||
"skip_ssl_verify": "maybe",
|
||||
"reset_session_status_codes": [math.inf, "NaN", "403"],
|
||||
"clearance": {
|
||||
"enabled": "maybe",
|
||||
"timeout_sec": math.inf,
|
||||
"refresh_interval": -math.inf,
|
||||
"warm_up_on_start": "maybe",
|
||||
},
|
||||
}
|
||||
)
|
||||
|
||||
self.assertFalse(normalized["enabled"])
|
||||
self.assertFalse(normalized["skip_ssl_verify"])
|
||||
self.assertEqual(normalized["reset_session_status_codes"], [403])
|
||||
clearance = normalized["clearance"]
|
||||
self.assertFalse(clearance["enabled"])
|
||||
self.assertEqual(clearance["timeout_sec"], DEFAULT_PROXY_RUNTIME["clearance"]["timeout_sec"])
|
||||
self.assertEqual(clearance["refresh_interval"], DEFAULT_PROXY_RUNTIME["clearance"]["refresh_interval"])
|
||||
self.assertFalse(clearance["warm_up_on_start"])
|
||||
|
||||
def test_update_normalizes_and_persists_proxy_runtime(self) -> None:
|
||||
tmp_dir, store = self._make_store()
|
||||
with tmp_dir:
|
||||
public_config = store.update(
|
||||
{
|
||||
"proxy_runtime": {
|
||||
"enabled": "true",
|
||||
"egress_mode": "single_proxy",
|
||||
"proxy_url": " http://proxy.example ",
|
||||
"reset_session_status_codes": [401, "403", "nope"],
|
||||
"clearance": {
|
||||
"enabled": "yes",
|
||||
"mode": "flaresolverr",
|
||||
"flaresolverr_url": " http://localhost:8191 ",
|
||||
"timeout_sec": "30",
|
||||
"refresh_interval": "120",
|
||||
},
|
||||
}
|
||||
}
|
||||
)
|
||||
|
||||
expected = {
|
||||
**DEFAULT_PROXY_RUNTIME,
|
||||
"enabled": True,
|
||||
"egress_mode": "single_proxy",
|
||||
"proxy_url": "http://proxy.example",
|
||||
"reset_session_status_codes": [401, 403],
|
||||
"clearance": {
|
||||
**DEFAULT_PROXY_RUNTIME["clearance"],
|
||||
"enabled": True,
|
||||
"mode": "flaresolverr",
|
||||
"flaresolverr_url": "http://localhost:8191",
|
||||
"timeout_sec": 30,
|
||||
"refresh_interval": 120,
|
||||
},
|
||||
}
|
||||
expected_public = copy.deepcopy(expected)
|
||||
expected_public["clearance"]["cf_cookies"] = ""
|
||||
expected_public["clearance"]["cf_clearance"] = ""
|
||||
expected_public["clearance"]["has_cf_cookies"] = False
|
||||
expected_public["clearance"]["has_cf_clearance"] = False
|
||||
self.assertEqual(public_config["proxy_runtime"], expected_public)
|
||||
|
||||
raw_saved = json.loads(store.path.read_text(encoding="utf-8"))
|
||||
self.assertEqual(raw_saved["proxy_runtime"], expected)
|
||||
reloaded = ConfigStore(store.path)
|
||||
self.assertEqual(reloaded.get_proxy_runtime_settings(), expected)
|
||||
|
||||
def test_public_proxy_runtime_redacts_and_preserves_existing_clearance_values(self) -> None:
|
||||
existing = copy.deepcopy(DEFAULT_PROXY_RUNTIME)
|
||||
existing["enabled"] = True
|
||||
existing["clearance"]["enabled"] = True
|
||||
existing["clearance"]["mode"] = "manual"
|
||||
existing["clearance"]["cf_cookies"] = "session=secret-cookie"
|
||||
existing["clearance"]["cf_clearance"] = "secret-clearance"
|
||||
tmp_dir, store = self._make_store({"proxy_runtime": existing})
|
||||
with tmp_dir:
|
||||
public_config = store.get()
|
||||
public_runtime = public_config["proxy_runtime"]
|
||||
public_clearance = public_runtime["clearance"]
|
||||
self.assertEqual(public_clearance["cf_cookies"], "")
|
||||
self.assertEqual(public_clearance["cf_clearance"], "")
|
||||
self.assertTrue(public_clearance["has_cf_cookies"])
|
||||
self.assertTrue(public_clearance["has_cf_clearance"])
|
||||
self.assertNotIn("secret-cookie", json.dumps(public_config))
|
||||
self.assertNotIn("secret-clearance", json.dumps(public_config))
|
||||
|
||||
public_clearance["user_agent"] = "Updated UA"
|
||||
updated_public = store.update({"proxy_runtime": public_runtime})
|
||||
updated_raw = json.loads(store.path.read_text(encoding="utf-8"))["proxy_runtime"]
|
||||
self.assertEqual(updated_raw["clearance"]["cf_cookies"], "session=secret-cookie")
|
||||
self.assertEqual(updated_raw["clearance"]["cf_clearance"], "secret-clearance")
|
||||
self.assertEqual(updated_raw["clearance"]["user_agent"], "Updated UA")
|
||||
self.assertEqual(updated_public["proxy_runtime"]["clearance"]["cf_cookies"], "")
|
||||
self.assertEqual(updated_public["proxy_runtime"]["clearance"]["cf_clearance"], "")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user